
Contact Details Scraper & Google Maps Email Extractor
Pricing
from $1.70 / 1,000 website with contacts founds
Contact Details Scraper & Google Maps Email Extractor
Contact details scraper and Google Maps email extractor. Enrich Google Maps Scraper results or any website list with emails, phones, socials and address: one row per place, each with its source page. Pay only for sites with contacts, $2/1k. Most accurate of 4 on a 6-site bench (10-09).
Pricing
from $1.70 / 1,000 website with contacts founds
Rating
0.0
(0)
Developer
hiver
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
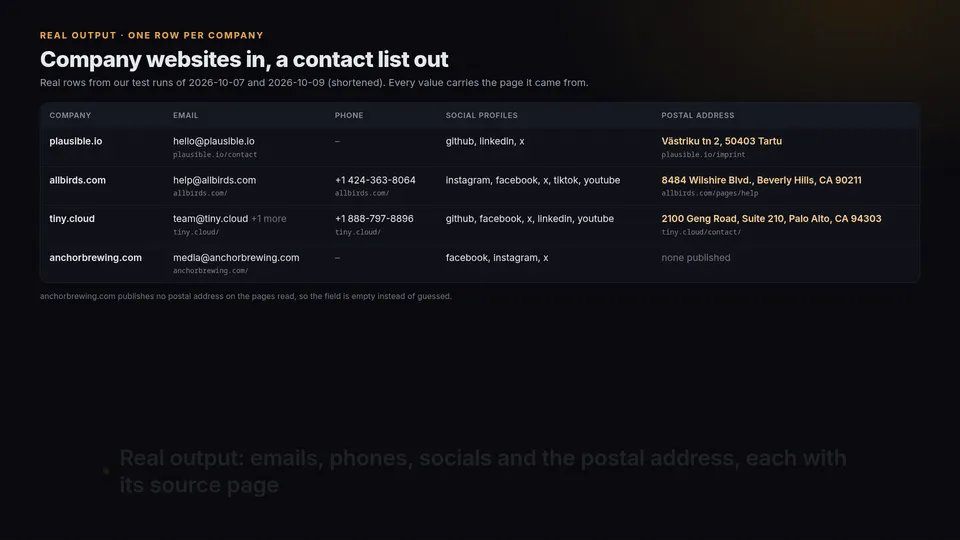
A contact details scraper and Google Maps email extractor. Point it at your Google Maps Scraper dataset or paste company websites, and get one row per place or company: role emails, phone numbers, social profiles and the postal address, each with the page it came from. It reads each business's own website: role emails (info@, sales@, support@, press@), phones, LinkedIn / X / Facebook / Instagram / YouTube / GitHub / TikTok profiles, the contact page and the postal address when one is published. You pay only for websites where it found at least one contact detail.
Built for sales and lead-gen lists, local-business outreach from Google Maps results, CRM enrichment and market research. Company-level data only.
Watch the 1-minute walkthrough (MP4) · Python and Node.js examples on GitHub
Unofficial. Not affiliated with, endorsed by or sponsored by any website or company it reads.
Enrich Google Maps Scraper results with emails
Already ran a Google Maps scraper? Give this Actor the run's dataset ID. It reads the website of every place and returns one row per place, in the dataset's order, and nothing else. The place's own fields stay under place (title, placeId, url, address, phone, categoryName, whichever exist), next to the emails, phones, socials and address found on its website.
Automatic after every Maps run (Apify integration):
- In Apify Console, open your Google Maps scraper and select the Integrations tab (Add integration if it already has some).
- In the Add integration catalog, use the search field to find this Actor (Contact Details Scraper & Google Maps Email Extractor, by hiver) and click its card.
- Set Start when to "run succeeded". This Actor's integration input is preset to the line below, so Apify fills in each Maps run's dataset ID. If your form shows something else, paste it:
- Save, then use Apify's integration test menu on one of your past Maps runs to check the output before the next real run (a test is a real run and is billed like one).
Add "maxItems": 100 (any number) to cap how many places are read from each Maps run, places without a website included. Each run is then charged for at most that many websites.
Manual run, with a dataset you already have: paste its ID into Source dataset ID:
The form's example domains are not added to your dataset run. The input form comes prefilled with two example domains (stripe.com, allbirds.com). When you give a dataset and leave that list exactly as it is, it is ignored: you get only your places and pay only for them. If you edit the list, every domain in it is processed after the dataset rows.
websiteField defaults to website and takes nested paths such as contact.website, so any dataset with a website column works. The dataset input also works in limited-permission runs. A dataset the run cannot read fails with an explicit error; it is never treated as empty.
What a Maps dataset costs: $2 per 1,000 websites where at least one contact detail was found. These rows are free: places with no website (no_website), places whose website is only a Facebook or Instagram page (website_is_social_profile), unreachable sites (failed) and sites that publish nothing (no_contacts_found). Places that share a website, such as chain locations, keep their own rows, but the website is fetched and charged once per run. The first usable URL for a domain is the one read, so these are company-level contacts, not branch-specific ones. If a run reaches your maximum charge it stops, and its status message says so.
Board test run, build 0.2.13 (2026-10-11), with the form's example domains left in: input {"datasetId": "eiFr4LxqWFyfrFoOg", "domains": ["stripe.com", "allbirds.com"], "maxItems": 5}. That public 5-place sample dataset has 2 places sharing plausible.io, 1 place on posthog.com, 1 place with no website and 1 place whose website is a Facebook page. The run returned exactly 5 rows in the dataset's order, no Stripe or Allbirds row and 0 error rows in 7.7 s, and Apify recorded 2 charges: plausible.io once and posthog.com once. The no-website and Facebook rows cost nothing. Try the same sample from the Google Maps example task. One row from that run, shortened (the place block comes from the sample dataset, not a live Maps listing):
The place without a website came back as {"place": {"title": "Example place without a website", ...}, "status": "no_website", "emails": []} and was not charged.
Compared with Apify's dataset enricher (Apify Store, checked 2026-10-11): compass/enrich-google-maps-dataset-with-contacts bills Apify platform usage, so its cost depends on each run; 566 of its 634 public runs in the last 30 days succeeded, and it is rated 3.1 from 9 reviews. Here the price per website is fixed and shown before you start, and only websites with contacts found are charged. Accuracy on Maps datasets has not been benched against other Actors yet; the accuracy table below measures website lists.
Most accurate of four contact scrapers in our bench
Our board's Lab bench ran this Actor and three other contact-details Actors from the Apify Store on the same 6 company websites (3 SaaS companies, 2 small businesses, 1 language school whose site redirects by locale) and checked 17 facts the companies publish: emails, phones, social profiles and postal addresses. Bench run 2026-10-09 20:59 UTC, build 0.2.6 (historical measured build):
| This Actor | jfaro19/website-contact-finder | poidata/contact-details-scraper | solidscrape/contact-details-scraper | |
|---|---|---|---|---|
| Known facts returned correctly | 100% (17 of 17) | 76% (13 of 17) | 65% (11 of 17) | 59% (10 of 17) |
| Fields filled | 59% | 56% | 55% | 44% |
| Bench runs that succeeded | 3 of 3 | 3 of 3 | 3 of 3 | 3 of 3 |
| Average run time per case | 31.9 s | 4.8 s | 44.5 s | 16.4 s |
| What a Store user paid per 1,000 results in these runs | $1.91 | $3.03 | $2.03 | $1.28 |
- Postal address: in the earlier bench run of the same 6 sites (2026-10-09 12:33 UTC, build 0.2.3), only this Actor returned the postal address plausible.io publishes on its imprint page (
Västriku tn 2, 50403 Tartu, withaddressSourceUrlhttps://plausible.io/imprint). solidscrape/contact-details-scraper has no address field. - Read it fairly: six websites are a small sample. Fields filled is 3 points ahead: the most complete in this bench, not a big gap. jfaro19/website-contact-finder is much faster, and solidscrape/contact-details-scraper costs less per result. The bench covers these three Actors only, not every contact scraper on the Store, and it runs again after every new build.
Why use it
- One row per source place, not one row per page. Chain locations sharing a website stay separate; their website is fetched and charged only once per run.
- Postal address with its source:
addressas one line plusaddressSourceUrl, read from the site's schema.org PostalAddress data and its imprint/legal and contact pages.nullwhen none is found (anchorbrewing.com in the bench). - Reads only a few pages: the home page plus the contact, about, imprint/legal and support pages it links to (default 5 pages, 12 max).
- Company channels, not private people. Role mailboxes (info@, sales@, support@, press@, careers@...) are kept. A branded business mailbox published in the site's own Organization/ContactPoint structured data is also accepted, including Gmail-style addresses, with type
published_company. Personal/unclassified addresses, detached contact points and explicitly foreign organizations are excluded. - Every item has its source page (
sourceUrl), so you can check it in one click. - Clear reasons when a site fails:
connection_refused_or_blocked_by_site,robots_txt_disallows_home_page,domain_for_sale_or_parked,dns_not_found,ssl_error,blocked_by_site_http_403,login_required,rate_limited_429... Failed sites are not charged.
Input
domains: company domains or URLs (stripe.com,https://www.example.com/en), deduplicated by registered domain. Supplydomains,datasetId, or both. With adatasetId, the form's unchanged example list (stripe.com,allbirds.com) is ignored.datasetId: an existing Google Maps Scraper (or other) dataset ID; see Enrich Google Maps Scraper results with emails above.websiteFielddefaults towebsite; nested paths such ascontact.websitework. OptionalmaxItemscaps the source dataset items read, including items without websites, not the separate domains list. Dataset rows come first in their original order.maxPagesPerSite(default 5),maxConcurrency(default 5),requestDelayMs(default 600 ms between pages of the same site).defaultCountry: reads local phone numbers written without a country code. Without an override,.cnsites use CN; explicit0086phone numbers are normalized to+86, and international CN tel links supply the region for national footer text. Phones are deduplicated by E.164. Same-site locale redirects such as/jpand/enare followed, and the resulting page URL is retained as the source.allowOtherEmailDomains,allowFreemailAddresses: off by default.retryBlockedWithProxy(default true): retry HTTP 403 once per site through included Apify datacenter Proxy. The User-Agent stayshiver-company-contact-details/0.2 (+https://apify.com/hiver/company-contact-details)on both routes; it never impersonates a browser. Successful retries keep the same route for robots.txt and subsequent pages; there is no IP rotation. Set false for direct-only operation.proxyConfiguration: optional explicit proxy for all requests. Residential groups are not supported in this build and are rejected before requests; no residential usage is silently added to your bill.
Output (real run from the 2026-10-09 bench, shortened)
Fields per company: domain, website, companyName, status (ok, no_contacts_found, failed, no_website, website_is_social_profile), failureReason, emails[], phones[], socials{}, socialSources{}, otherSocialCandidates, contactPageUrl, address, addressSourceUrl, pagesChecked[], redirectedToDomain, scrapedAt, proxyRetry (network, status, and exception type only when unavailable/failed; never proxy credentials).
Each email/phone includes foundVia (structured_data, link, address_tag, decoded_obfuscation, page_text) and pageType (home/contact/imprint/about/support/press/legal, or other); the address uses addressFoundVia / addressPageType (both null without an address). These describe the first retained source, not verification or confidence; check sourceUrl before use.
Price
Pay per event: $2 per 1,000 websites where at least one contact detail was found on the Free plan (company-processed, $0.002), less on paid plans. No website, a social-profile-only website, an unreachable site, an invalid input or nothing found = no charge. Each distinct website is charged once per run, even when several places share it. List prices of the benched rivals, checked 2026-10-09: jfaro19/website-contact-finder $3.00, poidata/contact-details-scraper $2.00 and solidscrape/contact-details-scraper $1.25 per 1,000 results. For comparison, a tool that bills per crawled page at $2 per 1,000 pages costs about $0.01 for a 5-page site (prices checked 2026-10-07; check current pricing before you compare).
Coverage
Not every company publishes an email address or a phone number. Unreachable or refusing sites produce an explicit failure row, not guessed contact details. A business may publish only social profiles or a contact form. Check pagesChecked and the source URL of each returned field.
Good to know
- Reads the HTML a server sends. Sites that build their pages only in the browser with JavaScript return
no_contacts_foundwith the reasonpage_builds_content_with_javascript. - Many large companies publish only contact forms, not emails: you will get their social links and phones, but
emailscan be empty. That is the truth of the site, not an error. - Respects
robots.txt(and Crawl-delay up to 10 s). The one Apify datacenter retry is limited to HTTP 403, not logins (401), rate limits (429), explicit robots disallows or CAPTCHAs. Persistent refusal is reported as failed. - A phone number found on a company's page is the company's published number. International formatting is applied with the
phonenumberslibrary; check numbers before bulk calling and follow your local telemarketing and anti-spam laws. - Use the data lawfully. You are responsible for how you contact the people behind these addresses (GDPR, CAN-SPAM, PECR and similar).
Pricing table & example
Pay per event. Prices per 1,000 events, by Apify plan (higher plans get a discount automatically):
| Event | Free | Starter (Bronze) | Scale (Silver) | Business (Gold) |
|---|---|---|---|---|
Website with contacts found (company-processed) | $2.00 | $1.90 | $1.80 | $1.70 |
Worked example: 5,000 billable company-processed events on the Free plan cost 5,000 × $0.002 = $10.00; on Gold, 5,000 × $0.0017 = $8.50. Rows that the Price section lists as free cost nothing. Apify platform usage is included in these prices.
Input example
FAQ
Does it search Google Maps itself?
No. It reads a dataset your Google Maps scraper already produced (any dataset with a website field). To find places, run a Maps scraper first, then pass its dataset ID or add this Actor as its integration.
Does it find personal emails?
No. It returns role addresses and branded business mailboxes explicitly published by the site's own organization in structured data. Unclassified personal addresses are skipped and counted; a Gmail-style mailbox is not automatically treated as personal or as company-owned.
How many companies get results?
Not every site publishes contact details. See Coverage above; unreachable sites are not charged.
What is not covered?
No login-only pages, no email guessing or verification, no data bought from third parties. It respects robots.txt.
Is this official?
No. Unofficial and not affiliated with, endorsed by or sponsored by any company or site named in the results or this README.
Something looks wrong or you need a field added?
Open an issue from the Actor's Issues tab with the input and run link.


