
Goodreads Scraper — Books, Ratings & Reviews
Pricing
from $1.00 / 1,000 results
Goodreads Scraper — Books, Ratings & Reviews
Scrape public Goodreads book metadata, 1–5 star rating distributions, review-language counts, and linked reader reviews from book URLs, ISBNs, or queries.
Pricing
from $1.00 / 1,000 results
Rating
0.0
(0)
Developer
Hyperbach
Maintained by CommunityActor stats
0
Bookmarked
4
Total users
2
Monthly active users
6 hours ago
Last modified
Categories
Features
Share
Book metadata, rating distributions, language counts, and public reader reviews from Goodreads. Start from exact book URLs, ISBN-10/13 values, or search queries; no Goodreads login or API key is required.
$0.004 per result — pay only for book and review rows the run delivers, with no start fee.
What this Actor covers — and what it does not
- Exact-book detail, not broad catalog crawling. The Actor accepts book URLs and ISBNs, plus the top five matches for each text query. It does not walk Goodreads shelves, lists, author catalogs, or every search page.
- Distribution data in the base book record.
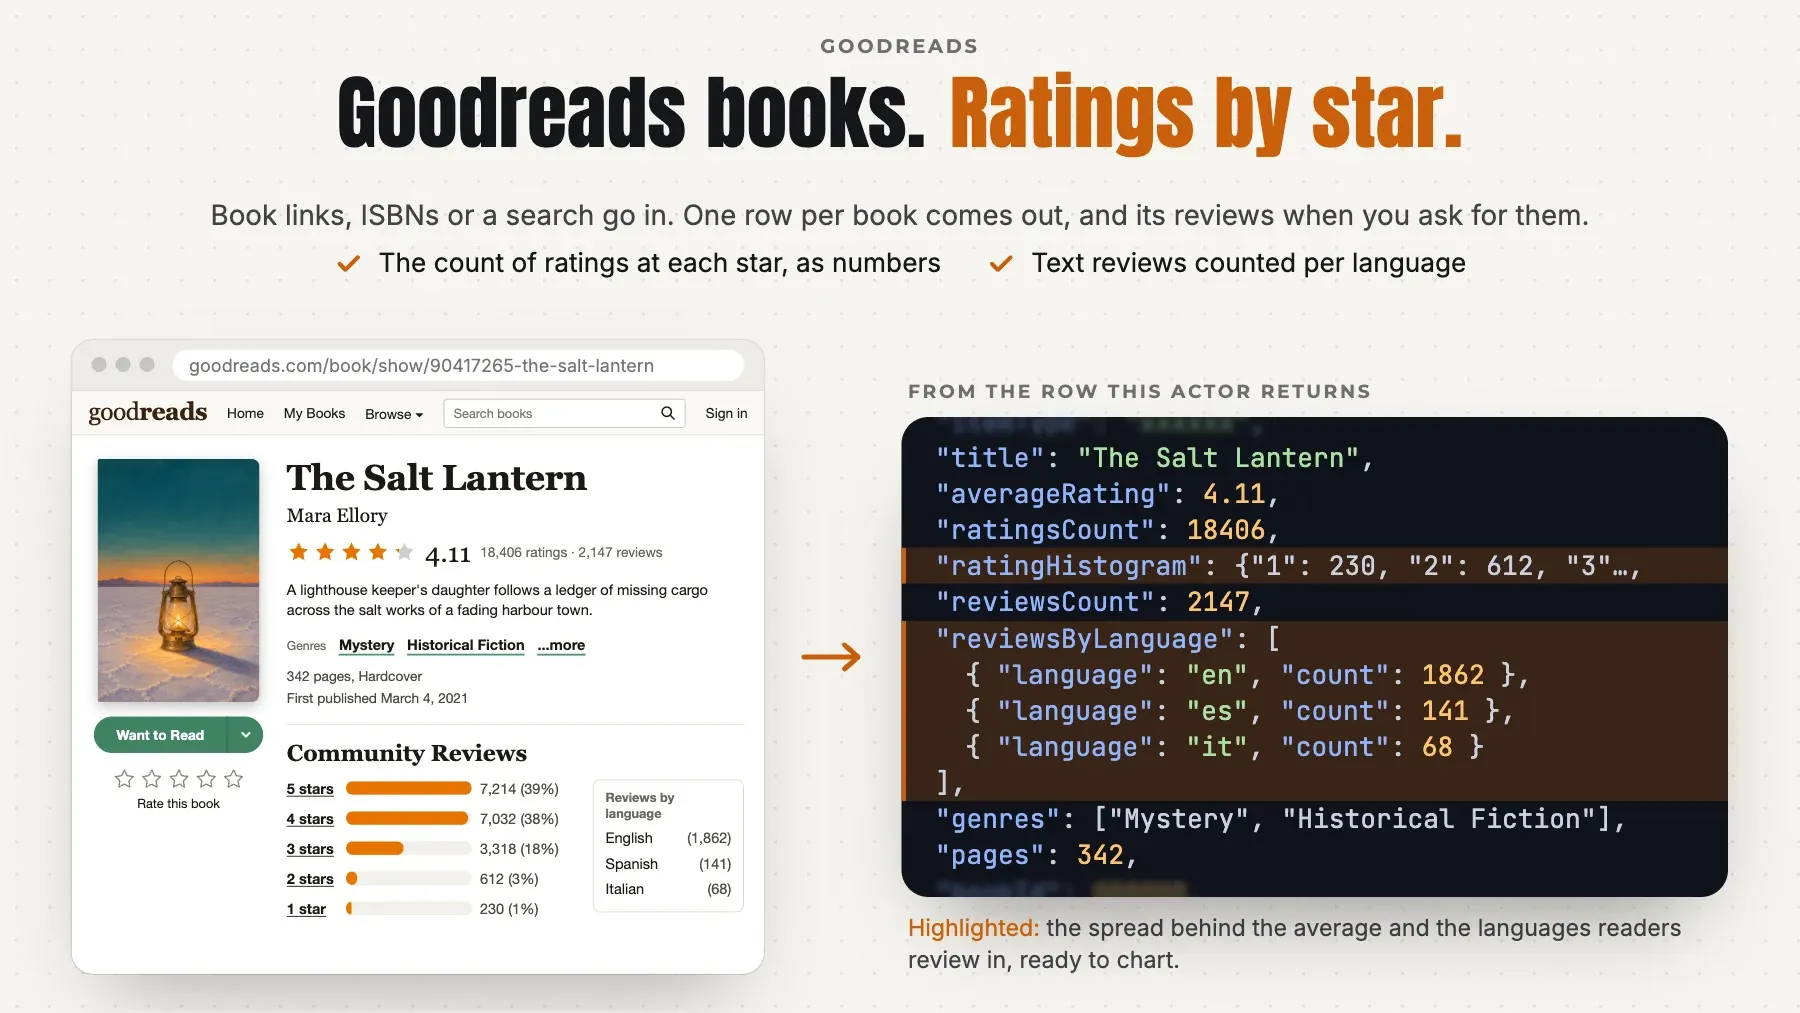
ratingHistogramcarries the 1-to-5-star counts andreviewsByLanguagecarries public text-review counts by language when Goodreads exposes its page state. - Book and review rows in one bounded run. Set
maxItemsfor the combined output cap andmaxReviewsPerBookfor the per-book review cap. Reviews link back throughbookId. - Public pages only. No account, cookies, private shelves, or authenticated reader data. Goodreads can omit fields or temporarily challenge automated requests, so unavailable values remain null or empty and blocked books are logged and skipped.
Who it's for
- Publishers and book marketers — compare ratings, rating distributions, review volume, and public reader responses for exact titles.
- Catalog and recommendation teams — enrich ISBN/title records with Goodreads identifiers, genres, edition metadata, covers, and aggregate ratings.
- Researchers and analysts — collect bounded, reproducible public book and review samples with stable book IDs.
Quick start
One exact book
ISBN with up to ten reviews
Search, filter, and cap
Output
The dataset contains book records and, when requested, linked review records. itemType identifies the shape and bookId joins reviews to books.
| field | meaning |
|---|---|
itemType | Record discriminator: book or review. |
bookId | Goodreads' stable numeric identifier for the book; joins book and review records. |
url | Canonical Goodreads URL for a book record. |
title | Book title. |
titleComplete | Complete edition title, including subtitle when Goodreads exposes it. |
authors | Authors and their public Goodreads profile URLs. |
description | Plain-text book description from the public edition page. |
genres | Genre names associated with the book. |
coverUrl | Book cover image URL published by Goodreads. |
averageRating | Current Goodreads average rating for the book. |
ratingsCount | Current number of Goodreads ratings. |
reviewsCount | Current number of Goodreads text reviews. |
ratingHistogram | Counts for 1-, 2-, 3-, 4-, and 5-star ratings, keyed by star value. |
reviewsByLanguage | Public text-review counts grouped by ISO language code. |
isbn | ISBN-10 for the edition, when available. |
isbn13 | ISBN-13 for the edition, when available. |
asin | Amazon Standard Identification Number for the edition, when available. |
pages | Page count for the displayed edition. |
publisher | Publisher for the displayed edition. |
language | Language of the displayed edition. |
format | Edition format, such as Paperback, Hardcover, or Kindle Edition. |
publishedAt | Publication date of the displayed edition in YYYY-MM-DD form. |
originalPublishedAt | Original work publication date in YYYY-MM-DD form, when available. |
originalTitle | Original title of the work, when available. |
series | Series memberships with title and the book's position. |
awards | Awards recorded for the work, including year, category, and designation when available. |
workId | Goodreads' numeric identifier for the underlying work across editions. |
scrapedAt | UTC timestamp when the record was scraped. |
reviewId | Goodreads' stable numeric identifier for the public review. |
bookTitle | Book title repeated on a review record for export convenience. |
reviewerName | Public display name of the reviewer. |
reviewerUrl | Public Goodreads profile URL for the reviewer. |
rating | Stars assigned by the reviewer, including half-stars where Goodreads exposes them. |
reviewText | Visible public review text with markup removed. |
reviewDate | Review date text as Goodreads displays it. |
reviewUrl | Permalink to the public Goodreads review. |
likesCount | Number of likes displayed for the review. |
hasSpoiler | Whether Goodreads marks the review as containing a spoiler. |
Example record:
Pricing
$0.004 per result — pay only for book and review rows the run delivers, with no start fee. maxItems caps the combined output and the Actor also clamps delivery to the run's pay-per-event budget.
Usage patterns
- Start with exact identifiers — Book URLs and ISBNs avoid search ambiguity. Text queries return at most the top five matches each.
- Bound the first run — Use a small
maxItems; it counts book and review rows together and is also clamped to the run's pay-per-event budget. - Treat reviews as optional fan-out — Keep
maxReviewsPerBooksmall initially. Goodreads' legacy review pagination is best-effort; the Actor falls back to public review cards embedded in the book page. - Handle source blocking — The managed Actor uses a shared cache that fetches direct first and falls back to residential egress after a source challenge. Supplying an Apify proxy configuration explicitly overrides that shared route; datacenter proxy addresses may themselves be challenged.
Input configuration
| field | type | default | what it does |
|---|---|---|---|
bookUrls | array | [] | Goodreads book page URLs, e.g. https://www.goodreads.com/book/show/3735293-clean-code |
queries | array | [] | Free-text searches (title, author, keyword). The top matching books are scraped. |
isbns | array | [] | ISBN-10 or ISBN-13 codes. Each is resolved to the matching book page. |
includeReviews | boolean | true | Collect public reader reviews for each book. |
maxReviewsPerBook | integer | 10 | Cap on collected reviews per book. 0 disables review collection entirely. |
minRating | number | 0 | Skip books with an average rating below this value (0 = no filtering). |
maxItems | integer | 200 | Total dataset records cap (books + reviews). Default 200; set 0 for an unlimited run. |
delaySeconds | integer | 2 | Politeness delay between HTTP requests. Higher values reduce the risk of rate-limiting. |
maxRequestsPerMinute | integer | 20 | Hard rate limit across all requests. Lower values reduce the risk of IP blocking. |
proxyConfiguration | object | Optional, and off by default: requests come directly from the run's IP, which works for typical volumes. If Goodreads starts refusing the run (HTTP 202 or 403), turn on Apify Proxy. | |
feedback | string | A note to the people who maintain this Actor: what you needed and did not get. For example a missing field, a wrong or empty result, or the Actor you switch from or to, and why. The run does not read it: the rows and the charges stay the same. A person reads every note. |
Errors
A run does not fail because of your input. When an input cannot be used — a date that is not a date, an id in the wrong form, two settings that contradict each other — the run ends Succeeded, charges nothing, and says what to change:
- the status message starts with
INPUT REJECTED; - the dataset stays empty: a row would be billed as a result, so none is written;
- the key-value store record
ERRORholds{"error": true, "code": "…", "message": "…"}.
From code, read the ERROR record when the dataset comes back empty.
A search that matches nothing is not an error: the dataset is empty and nothing is charged. A run that ends Failed is a fault on our side, never your input; it charges nothing, and we are alerted.
FAQ
Does this crawl shelves, lists, authors, or all Goodreads search pages?
No. This Actor focuses on exact book detail and bounded discovery: direct book URLs, ISBNs, and the top five matches per text query. Use a broader catalog crawler when you need shelves, lists, author catalogs, or deep search pagination.
How many reviews can it return?
Up to maxReviewsPerBook for each accepted book, subject to the total maxItems cap. Deep review pagination uses a legacy Goodreads endpoint and is best-effort; when unavailable, the Actor falls back to visible public review cards from the book page.
Why are some fields null or empty?
Goodreads does not expose every field for every edition, and the richer histogram/language/series fields depend on page state that may be absent. The Actor returns observed values and does not invent missing data.
What happens when Goodreads blocks a request?
The managed Actor's shared fetch layer detects source challenges and retries through residential egress; cache hits avoid the source request altogether. If that service is unavailable, the Actor falls back to its own egress. An explicit proxy input always takes precedence. The client still rate-limits requests and backs off on 429/5xx responses.
What if a run returns nothing?
The run's status message says which case it was: an empty input, an input that matched no book (a URL that is not a /book/show/ page, an ISBN or query Goodreads answered with no book), a book Goodreads has no page for (HTTP 404), everything filtered out by minRating, or books and searches that Goodreads refused to serve. Only the last case is counted as a failed run — that one is worth a retry or a residential proxy.
Is maxItems a book limit?
No. It is the combined dataset-row limit: book rows plus review rows. With maxItems: 1, the Actor fetches and returns one book and does not make review requests.
Do I need Apify Proxy or my own proxy?
No. The Actor uses its own connections, at no extra cost to you.
Integration
JavaScript
Python
CLI
REST
AI agents and MCP
Apify's MCP server offers this Actor as a tool to Claude, Cursor, VS Code and any other MCP client. Connect https://mcp.apify.com?tools=hyperbach/goodreads-scraper and ask, for example: "Get the Goodreads rating, review count and details of the book Clean Code". The agent fills the input from the table above and reads the rows from the run's dataset. The input names are the ones in the table above. An agent or a person can add feedback to any run and say what was needed and not delivered: a missing field, a wrong or empty result, the Actor switched from or to, and why. The run returns the same rows at the same price, and a person reads every note.
n8n, Make and Zapier
The Apify node in n8n, the Apify app in Make and the Apify integration in Zapier run this Actor on a schedule or from a trigger and read its dataset. A webhook on the run's end (Integrations on the Actor page) sends the rows on to your own endpoint. Nothing to install on our side.
Support
Disagree with a charge? Write to apify@hyperbach.com with the run ID. We will ask Apify to compensate you, and the charge comes back to your Apify account as platform credit.
Did it do the job? A short review on the Store, at any rating, helps the next buyer choose.
See also
- Trustpilot Reviews Scraper — every review of a business on Trustpilot, past the 200-review cap.
- App Store Reviews Scraper — Apple App Store reviews by app and country, with the app version each reviewer used.
- Google Play Reviews Scraper — Google Play reviews by app, language and country, with the app version each reviewer used.
- Yelp Reviews Scraper — every review of a Yelp business, with the owner's reply, the photos and the reviewer's public counts, without an API key.
- Yandex Maps Reviews Scraper — the reviews of a Yandex Maps organization, with the rating, the owner's reply and the organization's own rating.
- Google Maps Reviews Scraper — Google Maps reviews by place link, place ID, search or reviewer: the text and its translation, the stars, the exact date, the reviewer, photos, the owner's reply and sub-ratings.
This page is generated from the Actor's schemas and a live sample — it cannot describe a field the Actor does not have.


