
Internshala Scraper: Internships & Fresher Jobs
Pricing
from $0.20 / 1,000 results
Internshala Scraper: Internships & Fresher Jobs
Internshala scraper and API for Internshala internships and jobs in India: fresher jobs and work from home internships by keyword, category, city or link. Each posting's own page: stipend parsed, applicants (1000+ kept), openings, apply-by, exact post time, skills, perks. No login. Misses free.
Pricing
from $0.20 / 1,000 results
Rating
0.0
(0)
Developer
Hyperbach
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
6 hours ago
Last modified
Categories
Features
Share
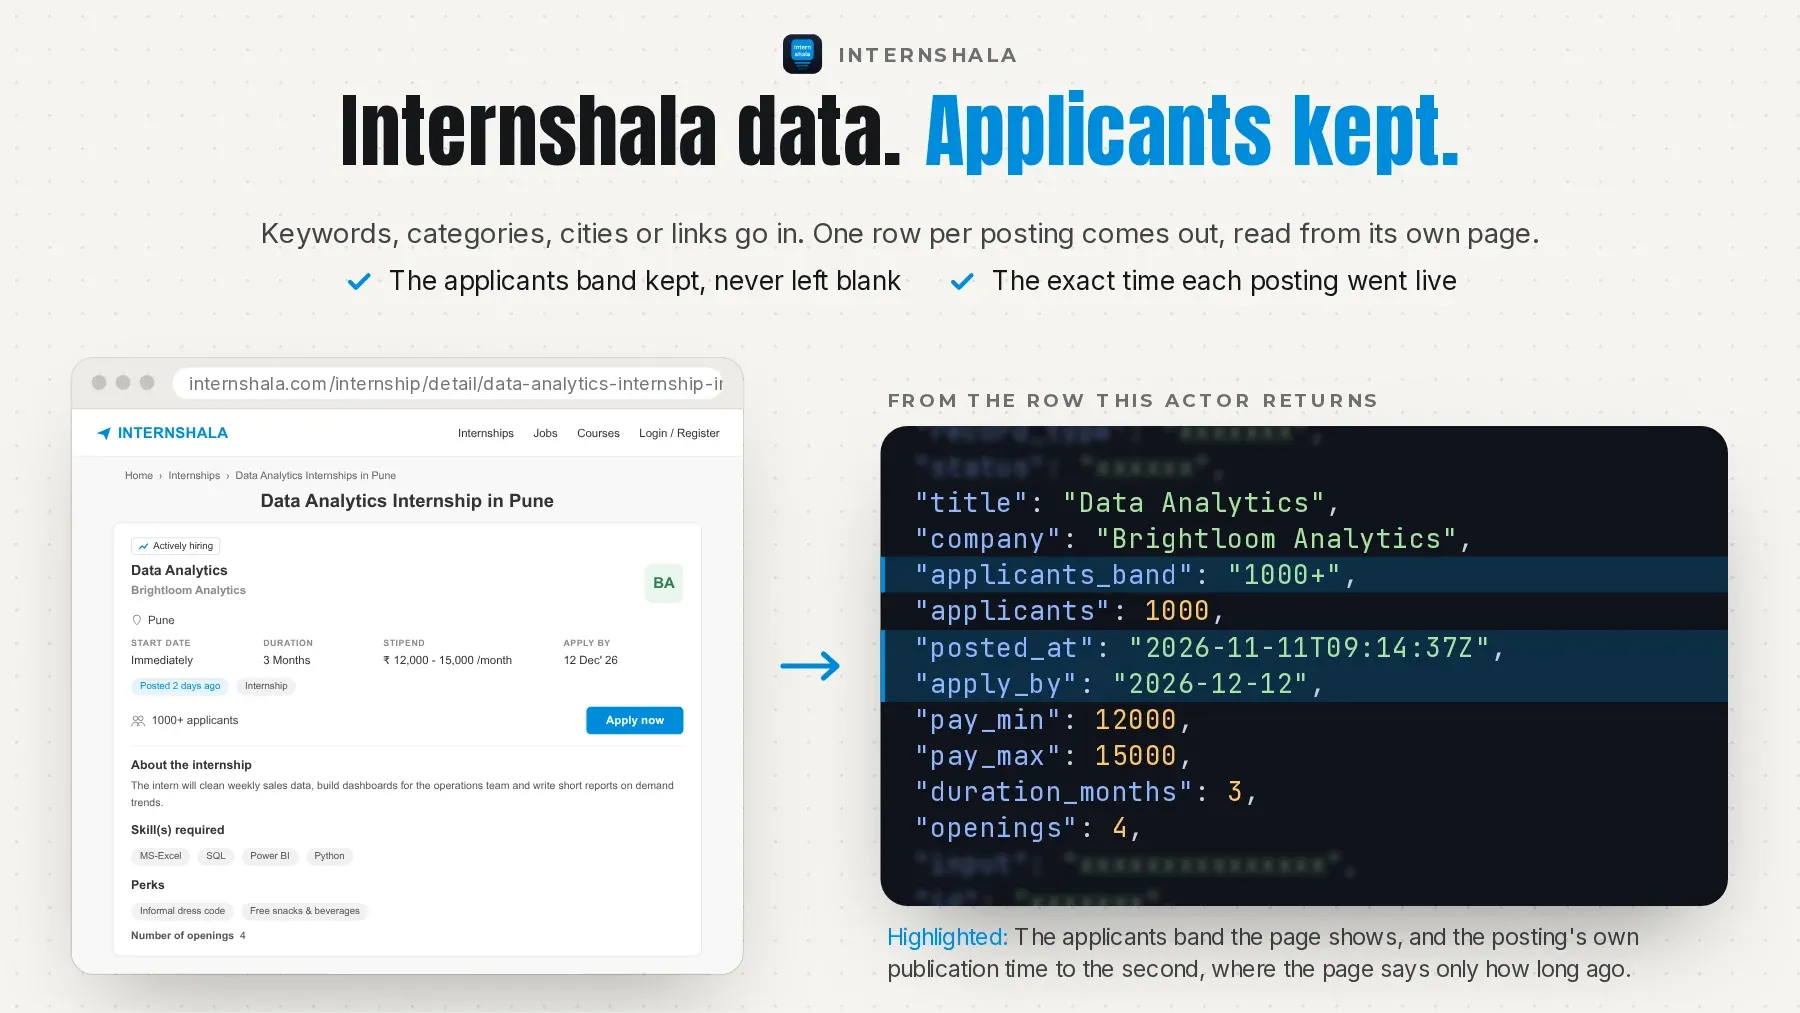
Internshala internships and fresher jobs as data, logged out. Give keywords, categories, cities or any internshala.com link, and get one row per posting with its own page read: the full description, applicants (the 1000+ band kept, never blank), openings, perks, who can apply, the apply-by date, the exact publication time, the stipend or salary as shown and parsed (min, max, currency, period, unpaid, the fixed and variable parts), duration, start date, skills, the job-offer label and the employer's hiring history. Internships, jobs or both in one run, each posting split by its own type; the source's own filters (work from home, part time, stipend, duration, job offer, salary, experience, start date, for women, international) and newest first or posted-within over the whole list. Every input ends with a free row that says what was found. No login, no cookies, no browser, proxies handled for you.
$0.40 per 1,000 result rows on the Free plan, $0.34 on Starter. A run start is $0.0017. The default input returns about 51 rows for about $0.0217. A keyword with no match, a removed posting, an unknown company or a value that names nothing is a free row that says why: you never pay for an input that gave no posting.
How it compares
- 2 times cheaper than getascraper's Internshala Scraper, with more data: $0.31 per 1,000 internships, against $0.63; 64 fields per internship, against 45. It is faster: 50 internships in 29 s, against our 46 s.
- Faster and cheaper than blackfalcondata's Internshala Scraper, with more data: 50 internships in 46 s, against 64 s; $0.31 per 1,000 internships, against $0.44; 64 fields per internship, against 53.
Measured on 2026-11-13. Each line compares one job, run by both scrapers at the same time. Prices are per 1,000 internships: Apify Actors at the Scale plan's prices.
Tested head-to-head on 2026-11-13
The job: the first 50 web development internships of Internshala's keyword search, each with its own posting page read (the input schema's example input and the leader's default job, lane/CLAIMS.md row 1). Every Actor ran on it the same day from the same harness; every run's cost is at the Scale plan's prices: a rival's charged events at its price for that plan, this Actor's at its list price. Fields counts the filled fields of a typical row. Every row here is a posting of the same keyword search with its own page read; the leader bills Apify platform usage on top of its per-row price, getascraper charges two per-row add-ons by default, and our price is the whole charge. Re-measured monthly.
| Actor | Rows | First row | Run time | Cost | Fields | Failures |
|---|---|---|---|---|---|---|
| this Actor | 50 | 11 s | 46 s | $0.016 | 64 | none |
blackfalcondata/internshala-scraper | 50 | 9.0 s | 64 s | $0.022 | 53 | none |
getascraper/internshala-scraper | 50 | 5.5 s | 29 s | $0.032 | 45 | none |
Why this Internshala scraper
- Every row is the posting's own page, read in the run, at the card readers' speed. The leader's default job (50 web development internships with their pages) ran 8 to 46 s here on builds 0.1.4 and 0.1.5 (most runs 8 to 16 s; the slowest waited about 30 s on one Apify dataset write) and 50 to 64 s on the leader, and 200 such rows took 23 s (the first row at 4.4 s), with the description, applicants, openings, perks, who can apply and apply-by on every row: the pages are read side by side over 16 connections.
- The fields the leaders drop, kept. "1000+ applicants" is
applicants1000 withapplicants_band"1000+" (the leader writes null); an unpaid internship is 0 withunpaidtrue (the leader writes 0 with no flag); "Be an early applicant" is no number withearly_applicanttrue, never a made-up count. - The exact publication time, and newest first that is really newest. Internshala's lists are not in time order (the 10 newest "web development" internships sat on pages 1 to 47 of 48), and its cards say only "3 weeks ago" for anything from 21 days to 5 months. Every posting's link carries its publication time to the second (equal to the page's own date on 435 of 437 pages), so
posted_atis exact andsortBynewest reads the whole list first. - Internships and jobs split by their own type. A jobs list on Internshala also holds internships (486 of 2,396 "web development" jobs); each posting carries its own type, so a job row is always a job, and
listingTypeboth reads both boards in one run. - Honest billing. One charge a delivered posting, however many inputs list it; no charge for a page of results, a summary row, a filtered posting or a removed one.
Who it's for
- Students and career services — every internship for a skill and a city, with the stipend, the duration, the applicants and the apply-by date, newest first.
- Recruiters and HR teams — which companies hire interns and freshers for a role now, what they pay, how many apply, and how often they have hired on Internshala.
- Researchers and edtech teams — the internship market by category, city, stipend and work mode: a weekly read of a whole list with each posting's publication time.
Quick start
The leader's default job: 50 web development internships with their pages
Fresher jobs and internships for Python in Bangalore, both boards
Work-from-home marketing internships posted in the last 3 days, paying 10,000 a month or more
One posting and one company page
Switching from blackfalcondata/internshala-scraper?
Your input works as it is. Each name in the left column is read as this Actor's own field and the run log says so (read <theirs> as <ours>); a name marked not read is ignored with a note. A value in the other Actor's shape, an object list or its own date form, is read too.
| blackfalcondata/internshala-scraper | this Actor | what to know |
|---|---|---|
query | queries | Read as one keyword of queries; give several in queries. |
listingType | listingType | The same name and values (internship, job), and both for one run over both boards. |
category | categories | Read as one category; give several in categories. |
location | locations | Read as one city; give several in locations (one search each). |
workFromHome | workFromHome | The same name. |
partTime | partTime | The same name. |
durationMonths | maxDurationMonths | The leader's list of months is read as its largest: internships of at most that many months (the source's own filter). |
withJobOffer | withJobOffer | The same name. |
fastResponse | fastResponse | The same name. |
earlyApplicant | earlyApplicant | The same name. |
forWomen | forWomen | The same name. |
minStipend | minStipend | The same name; the source's meaning: the top of the stipend range reaches it. |
minSalary | minSalary | The same name (INR a year); the source filters by whole lakhs and the rest is checked on each row. |
startUrls | startUrls | The same name: any internshala.com list, posting or company link. |
country | not read | Not read: Internshala has one view (India); the leader's only value is IN. |
maxResults | maxItems | Read as maxItems; 0 here reads the whole list. |
maxPages | maxPagesPerSearch | Read as maxPagesPerSearch (40 postings a page); 0 here reads to the list's end. |
includeDetails | includeDetails | The same name and default (on). |
descriptionMaxLength | not read | Not read: the description is whole; compact leaves the long texts out. |
compact | compact | The same name: the long texts are left out. |
incrementalMode | not read | Not read: no memory of earlier runs is kept for you; postedWithinDays reads the recent postings only. |
stateKey | not read | Not read: no memory of earlier runs (see incrementalMode). |
emitUnchanged | not read | Not read: no memory of earlier runs (see incrementalMode). |
emitExpired | not read | Not read: give a posting's link to read its status (active or closed). |
skipReposts | not read | Not read: a refreshed posting keeps its id here, so it is one row; posted_at says when it was refreshed. |
telegramToken | not read | Not read: no notification channel holds your token here; send the rows with Apify's own integrations. |
telegramChatId | not read | Not read: see telegramToken. |
discordWebhookUrl | not read | Not read: use Apify's webhooks and integrations. |
slackWebhookUrl | not read | Not read: use Apify's Slack integration. |
notificationLimit | not read | Not read: no notification channel. |
notifyOnlyChanges | not read | Not read: no notification channel and no memory of earlier runs. |
whatsappAccessToken | not read | Not read: no notification channel holds your token here. |
whatsappPhoneNumberId | not read | Not read: see whatsappAccessToken. |
whatsappTo | not read | Not read: see whatsappAccessToken. |
webhookUrl | not read | Not read: use Apify's own webhooks. |
webhookHeaders | not read | Not read: use Apify's own webhooks. |
appConnector | not read | Not read: use Apify's own integrations. |
mcpIssueTeam | not read | Not read: the leader's issue-tracker add-on. |
descriptionFormat | not read | Not read: the description is plain text with its line breaks. |
excludeEmptyFields | not read | Not read: every row carries every column, null where it does not apply, so the typed schema holds. |
What differs:
- The leader's
queryis one keyword; herequeriestakes many (one search each), andqueryis read as the first. maxItems0 (or unset) reads the whole list here; the leader's default is 100 rows and itsmaxPages5.- The output columns are snake_case:
pay_min,pay_max,pay_currency,pay_periodfor itssalaryMin,salaryMax,salaryCurrency,salaryPeriod;applicantsfor itsapplicantCount(here 1000 withapplicants_band"1000+", where the leader writes null);openingsfornumberOfOpenings;posted_atis the exact UTC time where the leader'spostedAtis a date. - Each input gets a free summary row (
record_type=target) beside its posting rows; filter onrecord_type=postingfor the postings alone. - There is no repeat-delivery memory and no notification channel: give
postedWithinDaysto read only the recent postings, and send the rows with Apify's own integrations.
Output
One row per posting (and one free summary row for every search or link you give):
| field | meaning |
|---|---|
record_type | posting on a posting row (charged), company on a company page row (charged), target on an input's free summary row. |
status | ok, or why an input gave no row: no_results, not_found, invalid_input, failed, not_read, duplicate. |
input | The keyword, category, city or link you gave that this row answers. |
id | The posting's id on Internshala (a company row: the company's slug). The leader's jobKey. |
url | The posting's page on internshala.com (a company row: the company page). The leader's sourceUrl. |
listing_type | internship or job: the posting's own type, whatever list gave it. The leader's listingType. |
title | The posting's title as Internshala shows it. |
company | The company's name (an NGO tag is moved to company_is_ngo). |
company_url | The company's page on internshala.com, when the posting links one. The leader's companyUrl. |
company_logo | The company's logo, from the list card. The leader's companyLogo. |
company_is_ngo | True when Internshala tags the company as an NGO. |
locations | The posting's places as Internshala lists them (Work from home, or one or more cities, one item a city). |
location_text | The places as one text, with (Hybrid) when the posting is hybrid. The leader's location. |
work_mode | wfh, hybrid or onsite. The leader's workMode. |
office_days_per_week | For a hybrid posting: the days a week in the office. The leader's inOfficeDaysPerWeek. |
part_time | True when Internshala labels the posting part time. The leader's isPartTime. |
international | True when Internshala labels the posting international (an employer outside India). The leader's isInternational. |
fresher_job | True when Internshala labels the job a fresher job (no experience required). |
pay_text | The stipend or salary as Internshala shows it (₹ 15,000 - 22,000 /month, Unpaid, Performance Based). The leader's stipendText. |
pay_type | range, fixed, unpaid, performance_based, lump_sum, competitive or other. |
pay_min | The lowest amount of the pay shown, in pay_currency per pay_period; 0 when unpaid. The leader's salaryMin. |
pay_max | The highest amount of the pay shown; equal to pay_min for one amount. The leader's salaryMax. |
pay_currency | The currency of the pay shown (INR, USD, GBP, EUR, JPY …). A job's salary block shows INR where the employer posted another currency; source_salary_currency keeps the posting's own. The leader's salaryCurrency. |
pay_period | month, year, week or lump_sum. The leader's salaryPeriod. |
unpaid | True for an unpaid internship (pay_min and pay_max are then 0). |
fixed_pay_min | With the posting's page read: the fixed part's lowest amount, when the page splits the pay into fixed and incentive (internships) or fixed and variable (jobs). |
fixed_pay_max | The fixed part's highest amount. |
variable_pay_min | The incentive or variable part's lowest amount. |
variable_pay_max | The incentive or variable part's highest amount. |
fixed_pay_stated | With the posting's page read: true when the page splits the pay into a fixed and a variable part. |
source_salary_min | The page's structured salary minimum, in the posting's own currency (empty when the page carries none). |
source_salary_max | The page's structured salary maximum, in the posting's own currency. |
source_salary_currency | The currency of the page's structured salary (the posting's own). |
source_salary_unit | The period of the page's structured salary (month, year, week). |
duration_text | An internship's duration as shown (3 Months, 6 Weeks). The leader's duration. |
duration_months | The duration in months (weeks ÷ 4.345). The leader's durationMonths. |
start_date_text | With the posting's page read: the start date as shown (Immediately, 15 Dec - 14 Jan' 27). The leader's startDate. |
experience_text | A job's experience as shown (No experience required, 1 year(s)). The leader's experienceText. |
experience_min_years | The experience's lowest years (0 for no experience required). |
posted_at | The posting's publication time (UTC, to the second), from the number its link ends with; Internshala's own page date agrees on 435 of 437 pages. The leader's postedAt (a date there). |
posted_text | The card's age text (3 weeks ago, Today). The leader's publishedAge. |
apply_by_text | With the posting's page read: the apply-by date as shown (12 Dec' 26). The leader's applyBy. |
apply_by | The apply-by date as YYYY-MM-DD. |
valid_through | The page's structured closing time (2026-12-12 23:59:59), when the page carries it. The leader's validThrough. |
applicants | With the posting's page read: the applicants Internshala shows; 1000 for "1000+ applicants" (see applicants_band); empty for "Be an early applicant". The leader's applicantCount (null there for 1000+). |
applicants_band | "1000+" when Internshala shows the band instead of a number. |
applicants_text | The applicants text as shown (106 applicants, 1000+ applicants, Be an early applicant). |
early_applicant | True when Internshala shows "Be an early applicant" (few applicants yet; it shows no number then). The leader's earlyApplicant. |
openings | With the posting's page read: the number of openings. The leader's numberOfOpenings. |
applicants_per_opening | applicants ÷ openings, when both are numbers. |
skills | The skills asked for: the page's whole list when it was read, else the card's (up to 7, see more_skills). The leader's skills. |
more_skills | On a card-only row: the skills the card did not show (+3 more). |
perks | With the posting's page read: the perks (Certificate, Letter of recommendation, Flexible work hours …). The leader's perks. |
who_can_apply | With the posting's page read: who can apply, as the page writes it. The leader's whoCanApply. |
other_requirements | With the posting's page read: the other requirements. The leader's otherRequirements. |
description | With the posting's page read: the full description as plain text with its line breaks; on a card-only row, the card's summary. The leader's description. |
additional_information | With the posting's page read: the page's additional information, when it has one. |
job_offer | True when the internship comes with a job offer (the card's label, or the page's perk). The leader's hasJobOffer. |
job_offer_text | The job-offer label as shown (Job offer upto ₹ 4 LPA post internship). The leader's jobOfferText. |
actively_hiring | True when the posting carries Internshala's "Actively hiring" badge. The leader's activelyHiring. |
pro_exclusive | True for an Internshala PRO-exclusive posting (read whole logged out all the same). |
labels | The posting's labels as shown (Internship, Part time, Fresher Job, International, Job). |
categories | The card's categories (Information Technology, Web Development …), when the card shows them. |
category | With the posting's page read: the page's structured category (Web Development). The leader's occupationalCategory. |
industry | With the posting's page read: the page's structured industry, when given. The leader's category. |
job_locations | With the posting's page read: the page's structured places, each with its locality, region and country (the page's own value). |
direct_apply | With the posting's page read: the page's structured direct-apply flag. |
posting_status | With the posting's page read: active, or closed (applications closed: the page says so). |
red_flags | With the posting's page read: rules over the row's own fields: unpaid, mostly_variable_pay, low_fixed_pay (a fixed part under ₹2,000 a month, or the whole stipend's top when the page states no split), no_hires_yet (20 or more postings and no hire shown). No model. |
company_about | The company's about text (from the posting's page, or the company page). The leader's aboutCompany. |
company_website | The company's website, when shown. The leader's companyWebsite. |
company_hiring_since | Since when the company hires on Internshala (August 2026; a company row: the year). |
company_opportunities_posted | The opportunities the company has posted on Internshala. |
company_candidates_hired | The candidates the company has hired on Internshala, when shown. |
company_location | On a company row: the company's location as its page shows it. |
company_industries | On a company row: the company's industries. |
company_employees | On a company row: the employee count band as its page shows it (11-50). |
company_open_count | On a company row: the openings its page shows. |
company_openings | On a company row: the openings its page shows, each with its id, type, title, link, publication time, place, pay, duration, applicants, and the actively-hiring and PRO flags. |
detail_status | On a posting row: served (its page was read in this run), not_asked (includeDetails off: the card's fields), failed (no connection served the page: the page's fields are empty), cut (the run's time limit came while its page was read). |
search_url | On a posting row from a search: the Internshala list page it came from. |
verdict | On an input's row: COMPLETE, CAPPED, TRUNCATED or PARTIAL (the FAQ says which is which). |
rows_delivered | On an input's row: the charged rows it delivered. |
source_count | On a search's row: Internshala's own count of the list (empty when the source shows none). |
pages_read | On a search's row: the list pages read. |
note | Why an input's row has the status or the verdict it has, with the counts. |
scraped_at | When this row was read (UTC). |
Example record:
Pricing
Pay for the postings a run delivers, plus one run start; no platform usage is billed to you. The row price falls with your Apify plan.
| event | unit | Free | Starter | Scale | Business |
|---|---|---|---|---|---|
Result (result) | per 1,000 | $0.40 | $0.34 | $0.28 | $0.20 |
Run start (start) | per run | $0.0017 | $0.0017 | $0.0017 | $0.0017 |
A posting is $0.40 per 1,000 on the Free plan ($0.0004 a posting) and $0.34 on Starter, with everything it carries, its own page included: the description, applicants, openings, perks, who can apply, apply-by, the pay parsed and the employer's history. A posting read from its list card alone (includeDetails off) and a company page row cost the same. Each run that delivers a charged row also pays the run start, $0.0017 once; a run that delivers none pays nothing at all. So the leader's default job, 50 web development internships with their pages, costs $0.0217 on the Free plan and $0.0187 on Starter; 1,000 postings cost $0.4017 and $0.3417; every input of a run shares one start. Free: every input's summary row, a keyword with no match, a removed posting, an unknown company, a posting a filter leaves out, a posting another input of the run already delivered (one row, one charge), a value that names nothing, and an input left unread at maxItems, your charge limit or the time limit. A run that stops early (a timeout, an abort) is charged for the rows it delivered.
Before the first request the log names the prices at your plan and the most the run can cost: maxItems over the whole run, or maxItemsPerSearch for each search or list link and one row for each posting or company link, and never more than your charge limit. A search with no cap is read to its end and the log says so: Internshala's count on the input's summary row is its size ("content writing" internships: 1,640 postings with their pages on 2026-11-13, $0.6577 on the Free plan). Set maxItems, maxItemsPerSearch or a charge limit for a lower maximum. Enterprise plans have their own rates — the Actor's Pricing tab shows the price for your plan.
Usage patterns
- What a search reads — Each keyword is one search of Internshala's own keyword search (it matches titles, skills and categories). A category and a city narrow every keyword's search, or stand alone as their own search; a city is its region on Internshala (Delhi includes Noida and Gurgaon), and each city is its own search. The source's filters (work from home, part time, minimum stipend, maximum duration, job offer, fast response, early applicant, for women, international, start date; for jobs the minimum salary in whole lakhs, the experience and the fresher board) are applied by Internshala itself, and the run checks each posting against the ones Internshala applies loosely: a stipend floor between its steps (2,000 to 10,000) is checked on the range's top, international keeps the postings Internshala labels international, the salary floor is checked where the range starts. Work from home with a city reads the work-from-home internships without the city (Internshala does not narrow them by city) and the input's row says so; international takes no city or category.
listingTypeboth reads the two boards side by side, internships from the internships list and jobs from the jobs list, so a capped run carries both. The list is read 40 postings a call to its end, and each posting's own page is read for the rows the run can still deliver. One walk of a long list delivers about 99 % of the postings it holds: Internshala's paging repeats about 1 % of its cards and leaves about as many out (two reads of the 1,911 "web development" internships, 2026-11-13). - Newest first and posted within — Internshala shows no sort and its lists are not in time order. With
sortBynewest orpostedWithinDays, the run reads every card of the list first (40 a call, side by side), orders or filters them by the exact publication time each posting carries, and then reads the pages of the rows it delivers only. A list of 1,900 postings is about 48 list calls. - Links —
startUrlstakes any internshala.com link: a list or search page (its own filters are kept; a page number and a query string are dropped), a posting (/internship/detail/…or/job/detail/…: one row, its status active or closed), or a company page (/company/…: one company row with the company's about text, industries, employee count, hiring history and the openings its page shows, each with its applicant count). A removed posting answers HTTP 404 on two connections and is a freenot_foundrow. - What a row is —
record_type=posting: one posting, charged once a run however many inputs list it;detail_statussays whether its own page was read (served), not asked (includeDetailsoff: the card's fields), not served (failed: the card's fields, the page's are empty) or cut by the run's time limit (cut).record_type=company: one company page.record_type=target: one free row per keyword, category, city or link, with itsstatus,verdict, the rows it delivered, the source's count (source_count), the list pages read and anote. Filter onrecord_type=postingfor the postings alone.
Input configuration
| field | type | default | what it does |
|---|---|---|---|
queries | array | [] | Keyword searches, one search each (web development, data science, python). The source's own keyword search: it matches the title, the skills and the category. A keyword with no match gives a free row that says so. |
listingType | internship / job / both | "internship" | Internships, fresher jobs, or both in one run. A jobs list also holds internships: each posting is split by its own type, so a job row is always a job. Both reads the two boards side by side (internships from the internships list, jobs from the jobs list), so a capped run carries both. |
categories | array | [] | Internshala's categories by name (Web Development, Marketing, Data Science). Beside keywords, each narrows every keyword's search; alone, each is its own search. |
locations | array | [] | Cities by name (Delhi, Bangalore, Navi Mumbai), one search each. A city is its region on Internshala (Delhi includes Noida and Gurgaon). Beside keywords, each narrows every keyword's search. |
startUrls | array | [] | Any internshala.com link: a list or search page (its filters are kept), a posting (/internship/detail/…, /job/detail/…), or a company page (/company/…: one company row with the openings its page shows and their applicant counts). A removed posting is a free row that says so. |
includeDetails | boolean | true | On: every row carries the posting's own page (full description, applicants with the 1000+ band, openings, perks, who can apply, apply-by, the stipend structure, the employer's hiring history). Off: the list card's fields only, faster. |
workFromHome | boolean | false | Only work-from-home postings. Internshala does not narrow its work-from-home internships by city, so a city beside it is not applied to the internships list (the input's row says so). |
partTime | boolean | false | Only part-time postings. |
minStipend | integer | 0 | Internships whose stipend reaches this amount a month. The source's meaning: the top of the stipend range reaches it (₹ 5,000 - 12,000 passes 10,000). The source takes 2,000, 4,000, 6,000, 8,000 and 10,000; any other amount is checked on every posting, and an unpaid posting never passes. Each row carries the parsed minimum and maximum. 0 = any. |
maxDurationMonths | integer | 0 | Internships of at most this many months. 0 = any. |
withJobOffer | boolean | false | Internships with a pre-placement job offer. |
fastResponse | boolean | false | Internships whose employer answers fast (the source's own label). |
earlyApplicant | boolean | false | Internships with few applicants yet (the source's own filter). |
forWomen | boolean | false | The source's internships and jobs for women. |
international | boolean | false | Internships with employers outside India: the source's international list, of which the run keeps the postings Internshala labels international (the list also holds Indian postings). Internships only; it takes no city or category, and with work from home each posting is checked for it. |
startDateFrom | string | Internships a candidate can start on this date (the source's own start-date filter: its start window reaches the date, so "Immediately" postings pass). | |
fresherOnly | boolean | false | Jobs from the source's fresher board (no experience required). |
minSalary | integer | 0 | Jobs whose salary starts at this amount a year or more (₹ 3,00,000 - 4,00,000 does not pass 3,50,000). The source filters by whole lakhs and passes jobs with an undisclosed salary; the rest is checked on each row. 0 = any. |
experienceYears | integer | 0 | Jobs open to this many years of experience: the job's minimum is this many years or less (1 to 5; 6 or more = 5 years and more). 0 = any. |
sortBy | source / newest | "source" | The source's own order, or newest first. Internshala's lists are not in time order, so newest first reads every card of the list first (fast: 40 cards a call), then the pages of the rows it delivers. |
postedWithinDays | integer | 0 | Only postings published in the last N days, by the exact publication time each posting carries. Reads every card of the list first. 0 = any age. |
includeKeywords | array | [] | Keep a posting only when its title or summary holds one of these words (any case). |
excludeKeywords | array | [] | Leave out a posting whose title or teaser (with its page read, its description) holds one of these words (any case). |
skills | array | [] | Keep a posting that asks for these skills (Python, React; any case). The posting's page lists every skill; the card shows up to 7. |
skillsMatch | any / all | "any" | Any of the skills, or all of them. |
activelyHiringOnly | boolean | false | Only postings with the source's 'Actively hiring' badge. |
maxApplicants | integer | 0 | Leave out postings with more applicants than this ('1000+' counts as 1,000; 'Be an early applicant' passes). Read on the posting's page. 0 = any. |
minOpenings | integer | 0 | Only postings with at least this many openings (read on the posting's page). 0 = any. |
applyByFrom | string | Only postings whose apply-by date is on or after this date (read on the posting's page). | |
excludeRedFlagged | boolean | false | Leave out postings with a red flag read from their own fields: unpaid, mostly variable pay, a fixed part under ₹2,000 a month, or 20+ postings and no hire shown. Read on the posting's page. |
compact | boolean | false | Leave the long texts out of each row (description, who can apply, other requirements, additional information, about the company). |
maxItems | integer | 0 | The most charged rows of the whole run; 0 = no cap beyond your charge limit. |
maxItemsPerSearch | integer | 0 | The most rows one keyword, category, city or link gives; 0 = no cap. |
maxPagesPerSearch | integer | 0 | The most list pages (40 postings each) one search reads; 0 = to the list's end. |
feedback | string | A note to the people who maintain this Actor: what you needed and did not get. For example a missing field, a wrong or empty result, or the Actor you switch from or to, and why. The run does not read it: the rows and the charges stay the same. A person reads every note. |
Errors
A run does not fail because of your input. When an input cannot be used — a date that is not a date, an id in the wrong form, two settings that contradict each other — the run ends Succeeded, charges nothing, and says what to change:
- the status message starts with
INPUT REJECTED; - the dataset holds one row,
{"error": true, "code": "…", "message": "…"}, and no results; - the key-value store record
ERRORholds the same object.
From code, check error on the first row before reading results.
A keyword with no match, a removed posting, an unknown company page or a value that is not an Internshala search or link is not an error: it gets one free row with its status and the reason, and the run goes on with the others. A run that ends Failed is a fault on our side, never your input; it charges nothing, and we are alerted.
FAQ
Which status and verdict is which?
A posting or company row is ok. An input's row: ok with a verdict (COMPLETE: the list was read to its end, at 90 % of the source's count or more; CAPPED: maxItems, maxItemsPerSearch or maxPagesPerSearch stopped it; TRUNCATED: the list ended under the source's count, or a page filter read 100 pages and then 15 a delivered row without enough matches; PARTIAL: stopped early, the note says why), or free: no_results (no posting for the search, or none passed the filters), not_found (a removed posting, an unknown company or a category, city or path the source does not know, on two connections), invalid_input (a value that is not a search or an internshala.com link), failed (the source refused every connection tried; run it again later), not_read (maxItems, your charge limit or the time limit came first), duplicate (an input that names what an earlier input reads, or a posting link another input delivered: the note names it). A posting link that the run's filters leave out is a free no_results row whose note names the filter.
What does the stipend filter mean?
Internshala's own: a posting passes minStipend when the top of its stipend range reaches the amount a month (₹ 5,000 - 12,000 /month passes 10,000). Internshala takes five floors (2,000, 4,000, 6,000, 8,000, 10,000); any other floor is sent as the step under it and checked on every posting, so an unpaid posting or a top under the floor is never delivered. Every row carries the parsed pay_min and pay_max, so you can keep the floor you mean. maxDurationMonths keeps internships of at most that many months; minSalary for jobs is whole lakhs at the source and is checked on each row where its range starts (₹ 3,00,000 - 4,00,000 does not pass 3,50,000; a job with an undisclosed salary passes).
How fresh is it, and how exact is the date?
Every list and every posting page is read during the run, and nothing is cached between runs. posted_at is the posting's publication time to the second (UTC), from the number every posting's link ends with; posted_text is the card's own words ("3 weeks ago").
Can it get the employer's e-mail or phone?
No. Internshala shows no recruiter and no contact logged out; the company's website, about text and Internshala company page are on the row.
Does it need an Internshala account, cookies or an API key?
No. Everything is read from Internshala's public, logged-out pages, PRO-only postings included: no login, no cookie of yours, no token. The connections are included in the price.
Do I need Apify Proxy or my own proxy?
No. The Actor uses its own connections, at no extra cost to you.
Integration
JavaScript
Python
CLI
REST
AI agents and MCP
Apify's MCP server offers this Actor as a tool to Claude, Cursor, VS Code and any other MCP client. Connect https://mcp.apify.com?tools=hyperbach/internshala-scraper and ask, for example: "Find the newest web development internships on Internshala with the stipend, the number of applicants and the apply-by date". The agent fills the input from the table above and reads the rows from the run's dataset. A field under the name another Actor gives it is read as this Actor's own: query, keyword, keywords, search as queries; category, profile, profiles as categories; location, city, cities as locations; urls, url, links, listUrls as startUrls (and more). An agent or a person can add feedback to any run and say what was needed and not delivered: a missing field, a wrong or empty result, the Actor switched from or to, and why. The run returns the same rows at the same price, and a person reads every note.
n8n, Make and Zapier
The Apify node in n8n, the Apify app in Make and the Apify integration in Zapier run this Actor on a schedule or from a trigger and read its dataset. A webhook on the run's end (Integrations on the Actor page) sends the rows on to your own endpoint. Nothing to install on our side.
Support
Disagree with a charge? Write to apify@hyperbach.com with the run ID. We will ask Apify to compensate you, and the charge comes back to your Apify account as platform credit.
Did it do the job? A short review on the Store, at any rating, helps the next buyer choose.
See also
- Upwork Jobs History — every Upwork job posting since November 2024 by period, category and skill, with the client's record as it stood on the day of posting.
- LinkedIn Jobs Scraper — LinkedIn job listings for keywords and a location, with the applicants count, the salary block and the company's facts.
- Greenhouse Jobs Scraper — the hiring of major tech companies from their own Greenhouse boards, kept as roles open and close.
- Remote Jobs Scraper — every remote job from seven boards and ATSs in one deduplicated feed, kept after the postings close.
- Y Combinator Jobs Scraper — every open job of every YC company on Work at a Startup, newest first, by keyword, company or link: the description, salary and equity, the role, posting age, remote, visa, the batch and the founders.
- Arbeitsagentur Jobs Scraper — jobs of Germany's Federal Employment Agency (Jobsuche) by keyword, search link or job link: employer, place, working time, contract and the stated salary as numbers, with the description on request.
This page is generated from the Actor's schemas and a live sample — it cannot describe a field the Actor does not have.


