

SoundCloud Scraper — Tracks, Plays, Artists & Contact Links
Pricing
Pay per event
SoundCloud Scraper — Tracks, Plays, Artists & Contact Links
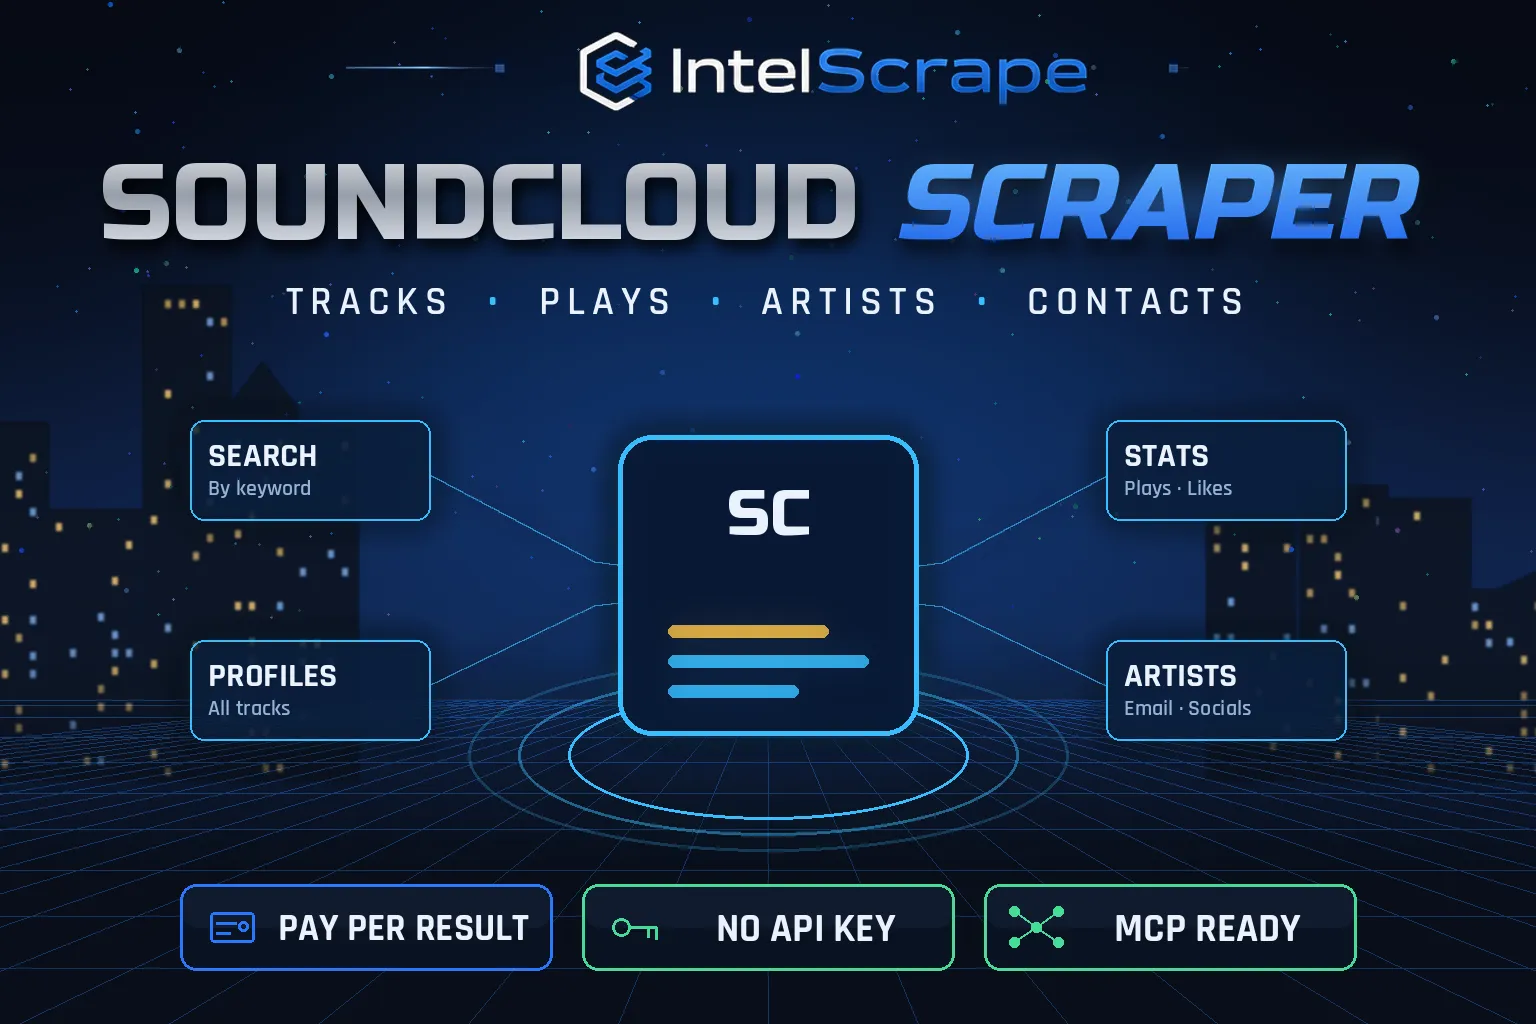
SoundCloud Scraper: search SoundCloud tracks by keyword, pull every track from an artist profile, or look up track URLs. Plays, likes, reposts, comments, genre, tags, artwork, plus artist followers, bio, email in bio, website, Instagram, Spotify and YouTube links. No API key.
Pricing
Pay per event
Rating
0.0
(0)
Developer
IntelScrape
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
9 hours ago
Last modified
Categories
Share
🇨🇳 SoundCloud 抓取器:按关键词搜索 SoundCloud 曲目、抓取艺人主页的全部曲目或查询曲目链接。返回播放量、点赞、转发、评论、流派、标签、封面,以及艺人粉丝数、简介、简介中的邮箱、网站、Instagram、Spotify 和 YouTube 链接。无需 API 密钥。
🇸🇬 Pengikis SoundCloud: cari lagu SoundCloud mengikut kata kunci, ambil semua lagu artis atau URL lagu. Main, suka, kongsi semula, genre, serta pengikut artis, bio, e-mel, laman web dan media sosial. Tiada kunci API.
🤖 NEW: Connect This To Your AI!
Use this actor from Claude, ChatGPT, Cursor or any MCP client through the IntelScrape MCP Server, or call it directly over the Apify API.
🏆 Featured Bots by IntelScrape
- Skip Trace Pro
- TruePeopleSearch Scraper
- TikTok Email Scraper
- Amazon Product Reviews Scraper
- Website Contact Scraper
- Skip Trace MCP Server
⚡ Works with n8n, Make, Zapier, Google Sheets and the Apify API.

SoundCloud tracks with plays and engagement, plus artist followers, bio emails and social links for A&R and outreach.
Honest coverage & billing: SoundCloud search results are limited to what its public search returns. You pay only for results actually delivered, and a built-in cost guard stops the run at your max-charge limit.
🌍 Built for teams in the US, China and Singapore, and anyone who needs this data in a spreadsheet or pipeline.
⭐ Found it useful? Please leave a review; it helps others find it.
⚖️ Lawful business use only. Collect public data only, and comply with the source site's terms, copyright and data-protection laws (GDPR, CCPA, China PIPL, Singapore PDPA).
Examples below are illustrative; names and values may be fictional or out of date.
What is SoundCloud Scraper?
SoundCloud is where independent artists, producers and DJs publish first, which makes it the best place to find emerging talent, track what is blowing up in a genre and build outreach lists. SoundCloud Scraper searches tracks by keyword, pulls an artist's full catalogue or looks up track links, and returns plays, likes, reposts and comments with the artist's followers, bio, any email in the bio and their website, Instagram, YouTube and Spotify links.
What does it do?
- Keyword search across all public SoundCloud tracks
- Artist catalogues: every public track from a profile URL or username
- Track lookup by URL
- Track data: title, URL, plays, likes, reposts, comments, duration, genre, tags, created and release date, artwork, license, label, downloadable flag, description
- Artist basics on every row: username, profile URL, followers, verified, city, country
- Artist links (on by default): full name, bio, emails found in bio, website, Instagram, X, YouTube, TikTok, Spotify, follower and track counts
Why choose us over cheaper scrapers?
- Honest output: limits are documented, missing data is labeled, never invented
- Clean, consistent schema ready for Excel, Sheets, BI tools or an LLM
- No account risk: no logins, no cookies, no API keys
- Pay per result with a built-in cost guard; no subscription, failed items are never charged
- Fast and light: no residential proxy, so runs finish in seconds and stay cheap
- Maintained by IntelScrape and fixed fast when the source changes
Who is it for?
- A&R and talent scouting: emerging artists in a genre ranked by plays and followers
- Music marketing & playlist outreach: artists with emails and socials
- Sync licensing: tracks by mood/genre with license info
- Trend tracking: what is gaining plays in a niche each week
- Label & promoter research: map an artist's catalogue and engagement
- Datasets of music metadata for analysis
How to use it
In Apify Console (no code)
- Click Try for free / Start. The form is prefilled with a working example.
- Change the inputs (see examples below).
- Click Start, then export the results as JSON, CSV, Excel, XML or HTML, or open them in Google Sheets.
- Optional: Schedule the actor to run hourly, daily or weekly.
Via API
Or use the official Apify JavaScript and Python clients:
With AI agents (MCP)
Add Apify's MCP server (https://mcp.apify.com) or the IntelScrape MCP Server to Claude Desktop, Cursor, ChatGPT or any MCP client, then ask in plain language, e.g. "Run intelscrape/soundcloud-scraper with the default input and summarise the results."
Input examples
Keyword search (default)
An artist's catalogue
Bulk genres, no artist links
Output fields
| Field | Description |
|---|---|
trackId / title / url / source | Identity and which keyword/profile found it |
plays / likes / reposts / comments / durationSecs | Stats |
genre / tags / license / label / downloadable | Classification |
createdAt / releaseDate | Dates |
artwork / description | Media |
artistId / artist / artistUrl / artistFollowers / artistVerified / artistCity / artistCountry | Artist basics |
artistEmail / artistDetails{name, bio, emails, website, instagram, twitter, youtube, tiktok, spotify, links[]} | Artist links (when on) |
Sample output
Pricing (pay per event)
| Event | When it is charged | Price |
|---|---|---|
| Actor start | once per run | $0.005 |
| Track | per track row | $0.001 |
| Artist links | per track with artist bio and links (on by default; turn off to skip) | $0.001 |
Cost examples
| Run | Cost |
|---|---|
| Default run: 30 tracks with artist links | $0.065 |
| 1,000 tracks with artist links | $2.005 |
| 5,000 tracks only | $5.005 |
Platform usage is included in these prices. Set Max charge per run in the run options to cap spend; the actor stops cleanly when the limit is reached and keeps everything collected so far.
Tips for best results
- Search a genre plus a city (e.g. "drill london") for local talent lists.
- Turn artist links off for the cheapest bulk export.
- Schedule weekly runs to track plays growth.
- Emails appear only when the artist put one in their bio.
FAQ
Do I need a SoundCloud account or API key?
No. It uses the same public endpoints the SoundCloud website uses.
Where do emails come from?
Only from text the artist published in their public bio.
Can I get private tracks?
No, only public tracks.
Are playlists supported?
Not in this version; use the artist profile input.
How many tracks per search?
Up to 2,000 per keyword or profile.
Are Go+ preview tracks included?
Yes, with their public metadata.
Honest limits
- SoundCloud search results are limited to what its public search returns.
- Emails appear only when present in an artist's bio.
- Private, deleted or geo-blocked tracks are skipped.
- Artist links add requests per new artist, so very large runs take longer.
Related IntelScrape bots
- Linktree Scraper: bio-link pages to emails & socials
- Username Checker: find a username on 600+ sites
- Skip Trace MCP Server: IntelScrape tools for AI agents
Legal
This actor collects publicly available data only. You are responsible for using the results lawfully and in line with the source's terms and applicable privacy laws (GDPR, CCPA, PIPL, PDPA). Process personal data only with a legitimate purpose. IntelScrape is not affiliated with, endorsed by or sponsored by the data source; all trademarks belong to their owners.


