

SoundCloud Scraper | Track Data & Direct Stream Links
Pricing
from $1.50 / 1,000 results
SoundCloud Scraper | Track Data & Direct Stream Links
Extract track and artist data from SoundCloud — titles, play counts, genres, stream links and engagement metrics for music analytics and discovery.
Pricing
from $1.50 / 1,000 results
Rating
0.0
(0)
Developer
Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
23
Total users
3
Monthly active users
8 days ago
Last modified
Categories
Share
SoundCloud Scraper - Track Data, Artist Metrics and Stream Links
The SoundCloud Scraper resolves public SoundCloud tracks, user profiles, sets and search pages into structured records. It returns the raw public track or user object plus useful fields such as title, artist, genre, duration, play count, likes, reposts, comment count, creation date, artwork and a short-lived direct stream URL for tracks.
Use it for music discovery, artist research, playlist and label analysis, engagement benchmarking and audio metadata pipelines. The Actor obtains a public client ID, resolves each submitted URL through the SoundCloud API, and writes one row per returned object. No SoundCloud login is required.
Main Use Cases for SoundCloud Music Data
- Music discovery - resolve search results into tracks and artist profiles for genre or keyword research.
- Artist benchmarking - compare play counts, likes, reposts and comment counts across tracks and artists.
- Label and catalog research - inspect release metadata, label names, ISRC, UPC and release dates.
- Playlist and set analysis - collect the tracks returned by a public set or search URL.
- Audio metadata pipelines - obtain track durations, artwork, waveforms and temporary stream URLs for downstream processing.
- Trend monitoring - schedule runs to track engagement growth on a defined track or artist list.
- AI music research - provide an LLM compact track rows with stable IDs and public metrics.
How It Works
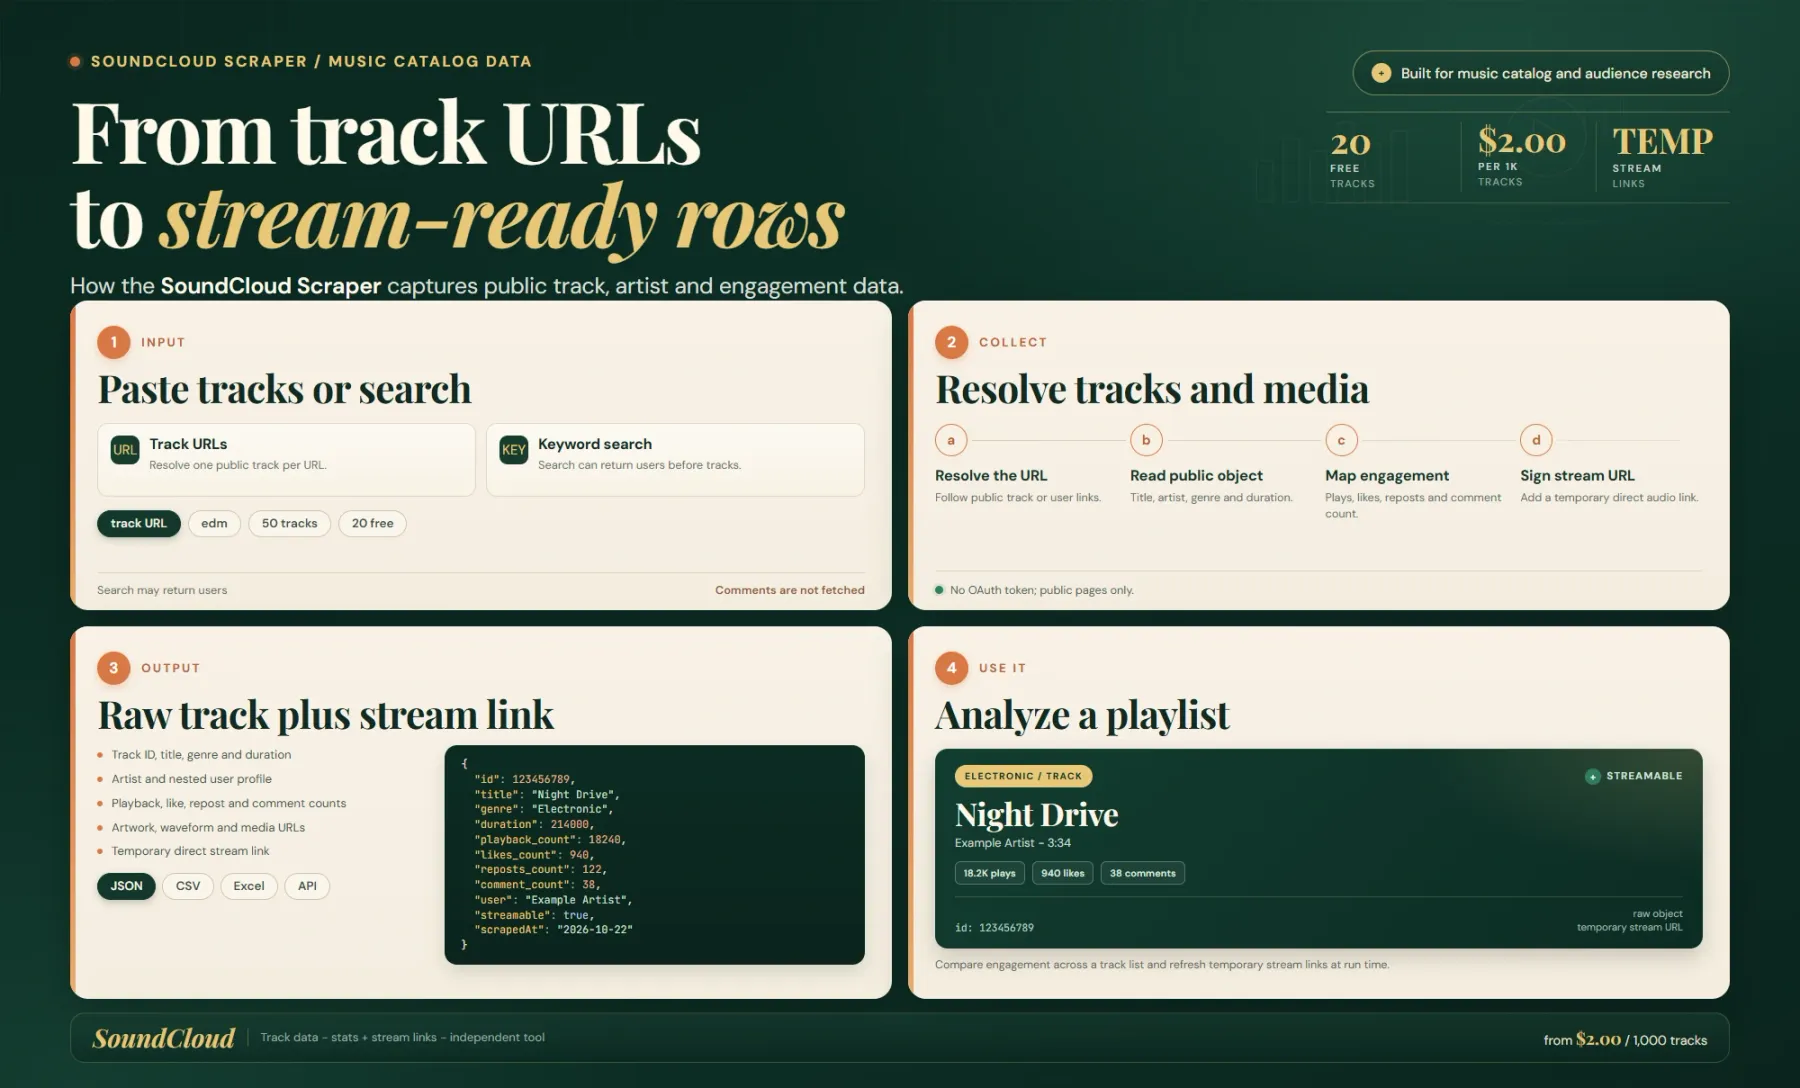
Provide track, user, set or search URLs in startUrls. For a search URL, the Actor reads the q parameter and calls the public SoundCloud search endpoint. For any other URL, it resolves the page through the SoundCloud resolve endpoint. Search results can contain a mix of tracks, users and playlists, so always inspect kind before processing a row.
For tracks, the Actor keeps the public track object and adds direct_stream_url by resolving the first media transcoding through the public API. The URL is temporary and can expire, so resolve it again for a later download or playback job rather than storing it as a permanent asset link.
The output is intentionally close to the SoundCloud object rather than a heavily normalized schema. Track rows expose title, permalink_url, genre, duration in milliseconds, playback_count, likes_count, reposts_count, comment_count, download_count, created_at, release_date, label_name, license, streamable, user, media and waveform_url. User rows expose follower and track counts, verification, avatar, description and profile URL.
maxItems is shared across all submitted URLs and is checked after each batch. The free tier is capped at 20 saved objects. includeComments is present in the input form but is not applied by the current build; comment data is limited to the public comment_count field. The Actor does not download audio files, private tracks or account data.
Input
The input is a list of public SoundCloud URLs plus an item budget and proxy setting. Search, track, user and set URLs can be mixed in one run.
| Field | Type | Required | Default | What it does |
|---|---|---|---|---|
startUrls | string[] | Yes | SoundCloud search example | Public track, user, set or search URLs. Search URLs use their q parameter. |
maxItems | integer | No | 20 | Maximum objects saved across all URLs. The free tier is capped at 20. |
includeComments | boolean | No | false | Present in the form for compatibility. The current build does not fetch comment threads. |
proxy | object | No | Apify Proxy | Proxy configuration. A proxy is strongly recommended for larger runs and repeated client ID resolution. |
Start with a single track or user URL to see the raw object shape, then add search URLs. Because search can return users before tracks, filter locally on kind: track when you need audio metrics. maxItems applies across the entire run, not per URL.
Output
The row shape depends on the object kind. Track rows carry audio and engagement fields; user rows carry profile and follower fields; playlist or set rows carry their own public collection metadata.
| Field group | Fields | What you get |
|---|---|---|
| Track identity | id, kind, title, permalink_url, genre, duration | Stable track ID, object kind, title, public URL, genre and duration in milliseconds. |
| Engagement | playback_count, likes_count, reposts_count, comment_count, download_count | Public play, like, repost, comment and download counts. |
| Release metadata | created_at, release_date, label_name, license, publisher_metadata | Upload and release dates, label, license and nested publisher identifiers such as ISRC and UPC. |
| Artist | user | Nested public user object with username, profile URL, avatar, followers, track count and verification. |
| Media | artwork_url, waveform_url, media, direct_stream_url | Artwork, waveform, transcoding metadata and a temporary direct stream URL for tracks. |
| Playback state | streamable, downloadable, state, sharing | Whether the track can be streamed or downloaded and whether it is public. |
| Source | scrapedAt | Observation timestamp added to each resolved object. |
direct_stream_url can be null when SoundCloud does not expose a usable transcoding, and it can expire after a short period. likes_count, reposts_count, download_count and some publisher fields can be null. A user result has no track metrics; a playlist result is not a track. Check kind rather than assuming every row is audio.
Pricing
Pricing is pay-per-event. A start event is charged per run and each saved SoundCloud object is charged as a result.
| Event | FREE | BRONZE | SILVER | GOLD+ |
|---|---|---|---|---|
| Actor start, per run | $0.00005 | $0.00005 | $0.00005 | $0.00005 |
| SoundCloud result | $0.002 | $0.002 | $0.0015 | $0.0015 |
That is $2.00 per 1,000 objects on FREE and BRONZE, falling to $1.50 per 1,000 on SILVER and higher tiers. A 1,000-track run costs about $2.00 before the start fee. The free preview is capped at 20 objects, which is enough to validate a search or track URL.
Example Input
This resolves one public track and exposes its metrics, nested artist object and a temporary stream URL. Use a search URL such as https://soundcloud.com/search?q=techno when you want a batch.
Example Output
This is a trimmed real sample. duration is in milliseconds, not seconds. The real row also contains the full nested media transcoding list, publisher metadata and waveform URL. Stream URLs are temporary.
Integrations and Automation
Call the Actor through the Apify API, Apify MCP, a scheduled task, Zapier, Make or n8n. Export JSON, CSV or Excel, or push rows to Google Sheets, Airtable, a database, a music analytics tool or a webhook.
For artist research, explode the nested user object into an artist table and key tracks on id. Store playback_count and likes_count with scrapedAt so you can calculate growth instead of treating a single snapshot as a trend.
For audio pipelines, treat direct_stream_url as a short-lived signed URL. Download promptly, record the resolution time, and re-resolve the track if the URL expires. Do not assume the same URL will work in a later run.
Related Actors
- SeatGeek Scraper - concert and sports ticket prices for live-event research.
- Ticketmaster Scraper - event and ticket data for live music and venue analysis.
- Reddit Scraper Pro - music community discussions, comments and sentiment.
FAQ
Does the Actor download audio files?
No. It resolves metadata and a temporary direct stream URL. You are responsible for complying with copyright, licensing and SoundCloud terms if you use that URL.
Why does a search return users instead of tracks?
SoundCloud search can mix tracks, users and playlists. Filter on kind: track when you need audio metrics, or search by a more specific track title.
Why is direct_stream_url null or expired?
The track may not expose a usable transcoding, may be region-restricted or may have changed. The URL is short-lived by design, so re-resolve the track for a later job.
Does includeComments fetch comment threads?
Not in the current build. The field is present for compatibility, but only the public comment_count is returned.
Can I scrape private tracks or user emails?
No. The Actor reads public objects only. It does not log in, access private tracks or expose account emails.
What does maxItems count?
It counts saved objects across all start URLs, including users and playlists. A run with a search URL can therefore produce fewer tracks than maxItems.
For AI Agents and LLM Apps
The Actor provides raw public SoundCloud objects with stable IDs, artist relationships and engagement metrics. It is suitable for music discovery, catalog analysis and metadata enrichment through the Apify API or Apify MCP.
- Always branch on
kind; a result can be a track, user or playlist, and the fields differ. - Track durations and playback counts are numeric, but
durationis in milliseconds. direct_stream_urlis temporary. Use it promptly and never present it as a permanent asset URL.- The nested
userobject is the artist profile; do not flatten it without preserving the user ID or permalink. - The free tier is capped at 20 saved objects across all start URLs.
Legal and Compliance
This Actor is an independent tool and is not affiliated with, endorsed by or sponsored by SoundCloud. It reads publicly available metadata and does not bypass private tracks or access controls. SoundCloud terms, copyright law and the rights of artists and labels still apply.
Do not redistribute audio, artwork or other copyrighted media without permission. Stream URLs are temporary and may be subject to licensing restrictions. If you process personal data from artist or listener profiles, keep a lawful basis and honor platform and privacy obligations.
SEO Keywords
SoundCloud scraper, SoundCloud track data, SoundCloud API alternative, SoundCloud stream URL, SoundCloud music data, SoundCloud artist data, SoundCloud play counts, SoundCloud likes, SoundCloud metadata, music data scraper, SoundCloud search scraper, SoundCloud dataset, artist analytics, track metadata, music discovery data, SoundCloud waveform, SoundCloud label data, audio metadata extraction, music catalog research, SoundCloud profile scraper


