
Domain to Company Data Lookup (Logo, Socials, Role Emails)
Pricing
from $0.83 / 1,000 company profiles
Domain to Company Data Lookup (Logo, Socials, Role Emails)
Get company data from a domain: name, description, logo, founding year, HQ country, social profiles and role contact emails, taken from the company's own website, never a third-party database. Careers page, ATS and tech hints too. Dead or blocked sites cost nothing. $1.50 per 1,000 companies.
Pricing
from $0.83 / 1,000 company profiles
Rating
0.0
(0)
Developer
locaihost data
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
14 days ago
Last modified
Categories
Share
Turn a list of company domains into one structured profile per company, read straight from each company's own website: name, description, logo, founding year, address and country, social accounts, role contact emails, phone, careers and pricing pages, hiring platform and tech hints. No login, no API key, no third-party database.
- Enrich a lead list: turn a column of domains into names, descriptions, LinkedIn pages, generic contact inboxes and HQ country.
- Clean up a CRM: fill missing logos, social links and countries, and spot dead or redirected domains.
- Map a market: compare founding years, locations, tech stacks, hiring activity and pricing pages across hundreds of companies.
- Answer questions from an agent: "what does this company do, where is it, how do I reach it?" as structured JSON.
Quick start
Paste this into the JSON tab of the input and click Start:
You get 5 company profiles, usually in about 20 seconds. Domains and any URL on a company's site both work; duplicates are merged.
What data can I get?
| Group | Fields |
|---|---|
| Company | name, legalName, description, aboutSummary (1-3 sentences quoted from the About page), organizationType, foundingYear, keywords |
| Brand | logoUrl, faviconUrl |
| Location | address (street, city, region, postalCode, country, full), countryCode |
| Social accounts | socialProfiles: linkedin, x, facebook, instagram, youtube, github, tiktok (company pages only) |
| Contact | contact.emails (role mailboxes only), contact.phone, contact.contactPageUrl |
| Signals | signals: hasCareersPage, careersUrl, careersPlatform, hasPricingPage, pricingUrl, hasBlog, blogUrl, languages, techHints, hasLlmsTxt, schemaTypes |
| Run detail | input, domain, status (ok, failed, blocked), finalUrl, pagesFetched, errors, scrapedAt |
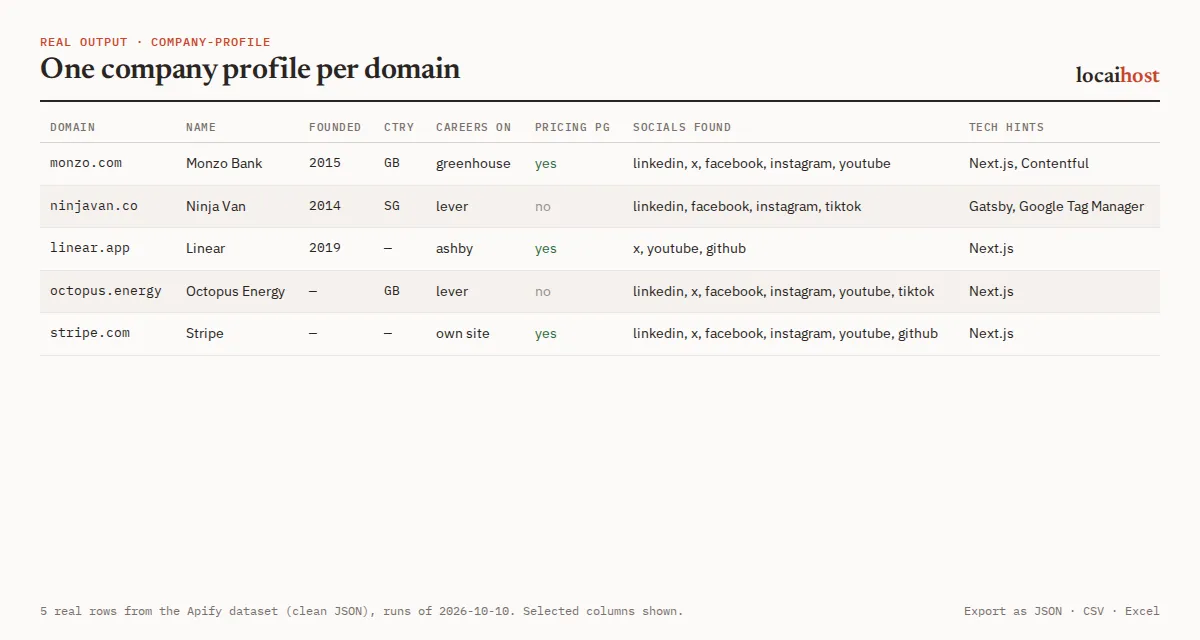
One real row (run on 2026-10-18 with the quick-start input, shortened):
The Companies view shows the main columns side by side; every run exports to JSON, CSV, Excel or HTML. A per-site report is saved as the run's SUMMARY record.
Where each field comes from
Facts come from the site's schema.org markup, meta tags and its About, Contact and Careers pages, and nothing is guessed: a field the site doesn't publish is null.
name: the schema.org Organization name, elseog:site_name, else the cleaned-up page title.description: the site's meta description (falls back to the About summary).aboutSummaryquotes the site's own sentences, or isnullrather than an off-topic quote.foundingYear: schema.orgfoundingDate, or an explicit "founded in 2014" or "Est. 1932" on the About page. Ambiguous text givesnull.addressandcountryCode: only the Organization's schema.org address or a clearly labelled "Registered office:" line. Country from the address, else from a country-code domain (.sg, .co.uk).contact.phone: only from the schema.org Organization or LocalBusiness markup.signals.careersPlatform: greenhouse, lever, ashby, workable, workday, smartrecruiters, bamboohr, teamtailor, recruitee, personio and others.signals.techHints: Shopify, WordPress, WooCommerce, Webflow, Squarespace, Wix, Framer, Next.js, Gatsby, HubSpot, Magento and more, from platform-specific markup only.
Typical fill rates across 21 readable sites in our test (SaaS, e-commerce, banks, SG and UK local businesses): name 100%, favicon 100%, logo 95%, tech hints 95%, description 90%, any social profile 86%, careers page 81%, About summary 67%, LinkedIn 57%, founding year 48%, country 48%, role emails 48%, address 38%, phone 14%, keywords 10%.
Privacy built in
Emails are kept only if they are role mailboxes on the company's own domain (info@, sales@, press@, careers@ and similar). Anything that looks like a person (jane@, j.smith@, jsmith@, initials like jd.sales@) is dropped. Social links are company pages only: personal linkedin.com/in/… profiles, posts and share buttons are rejected. Founders' names in schema.org are never copied. If a company lists only personal addresses, contact.emails is empty, by design.
How much does it cost?
You pay per company profile returned with status: "ok". There is no charge for Apify platform usage on top.
| Row | Free and Starter | Scale | Business |
|---|---|---|---|
| Company profiled | $1.50 per 1,000 | $1.125 per 1,000 | $0.825 per 1,000 |
Plus $0.00005 per run start. Apify's free $5 monthly credit covers about 3,300 companies. Free-plan runs stop at 100 company profiles each; any paid Apify plan removes the cap.
What's free: sites that can't be read (dead domain, bot wall, timeout, queue page) and sites whose robots.txt blocks us come back as a record with the reason and are not charged; duplicates are merged; sites not reached before the run's time limit are listed in SUMMARY and not charged. For example, a 500-row list where 450 sites are readable costs 450 profiles. Set Max results to stop after a number of profiles, or Maximum cost per run in the run options to cap a run's spend.
Limits, stated up front
- Own website only: the homepage plus at most 4 more pages (About, Contact, Careers). No LinkedIn scraping and no third-party databases, so the data is only as complete as the company's own site.
- Respects robots.txt (user agent
locaihost-company-profile), reads one page at a time per site with 10 to 15 second timeouts, and identifies itself honestly. Sites that block automated visitors are reported asfailed, not bypassed. - JavaScript-only sites that render nothing without a browser may come back with few fields: the Actor reads the HTML as served.
- Up to 2,000 domains per run; extra ones are left out with a warning. About 15 seconds for 25 companies.
- If a long list would outlast the run's time limit, the run stops starting new sites shortly before it, still succeeds, and lists the sites it didn't reach (not charged).
Schedules
Each run reads the websites live, so data is as fresh as the run. Save a list as a task and add a monthly schedule under Schedules in Apify Console to keep CRM records current and catch dead or redirected domains.
Integrations: API, n8n, Make and AI agents
API. Run it and get the rows back in one call (synchronous runs wait up to 5 minutes; use the asynchronous run endpoint for long lists):
Python, with pip install apify-client:
n8n, Make, Zapier, Google Sheets, Slack, webhooks. Apify's built-in integrations send each run's dataset wherever you need it, or into your CRM through Zapier or Make.
AI agents (MCP). Add this Actor to Claude, Cursor or any MCP client with https://mcp.apify.com/?tools=locaihost/company-profile, then ask something like "What do Monzo and Ninja Van do, when were they founded, which job board do they hire through, and what are their LinkedIn pages?" One input, one record per company, null instead of guesses.
FAQ
How much does company enrichment by domain cost?
$1.50 per 1,000 company profiles on the Free and Starter plans, less on Scale and Business. Sites that can't be read are free. Apify's free $5 monthly credit covers about 3,300 companies.
Can I use it through the API or from Python?
Yes. Use the run-sync-get-dataset-items call or the Python example above, or Apify's JavaScript client. Every run's data is also available as JSON, CSV or Excel from its dataset.
Can I use it from an AI agent?
Yes. Through the Apify MCP server (https://mcp.apify.com/?tools=locaihost/company-profile) any MCP client can pass a list of domains and read the profiles back.
Is it legal to collect company data this way?
The Actor reads only each company's own public website, as any visitor sees it, and respects robots.txt. It never logs in and uses no third-party databases. It returns company information: role mailboxes, company social accounts and the phone number from the company's own markup, never personal email addresses, personal profiles or founders' names. You are responsible for using the results lawfully, including data-protection and marketing rules where you are.
Why are some fields empty?
A field is filled only when the site publishes it. In our test of 21 readable sites, founding year and country were found on about half, and a phone number on 14%. Empty means "not published", never a guess.
Why did a site come back as failed or blocked?
failed means the domain doesn't resolve, the server timed out or refused the request, or it showed a bot wall (Cloudflare, Imperva, Sucuri and others) or a queue page; the record's errors say which. A bot wall or a 403 usually means the site is fine for people but blocks automated visitors. blocked means the site's robots.txt disallows our crawler, and we respect that. Neither is charged. Try again later, or give the exact homepage URL.
Does it use AI to write the summary?
No. aboutSummary quotes the site's own sentences, so nothing is made up.
More from locaihost data
- LinkedIn Company Scraper: industry, size band, headquarters and followers from each company's LinkedIn page, found from the same domains.
- Tech Stack & Domain Lookup: email provider, DMARC, DNS, hosting and a deeper tech stack for each domain.
- Website Traffic Checker: monthly visits and traffic sources for each company's website.
- Company KYB Check: legal entity identifiers, company registry records and sanctions screening for the companies you enrich.
Did it help?
If this saved you time, a quick rating on the Store helps other people find it.
Support
Something not working, or a field you need? Open an issue on the Issues tab: we answer issues within 24 hours.


