
Facebook Reels Scraper
Pricing
from $2.50 / 1,000 results
Facebook Reels Scraper
Extract the reels of public Facebook Pages and profiles without logging in: caption, hashtags, publish time, play count, reactions, comments, shares, duration, video and thumbnail URLs, subtitle tracks and the Page's details on every reel.
Pricing
from $2.50 / 1,000 results
Rating
0.0
(0)
Developer
Goldmine
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 hours ago
Last modified
Categories
Share
🎬 Facebook Reels Scraper — Extract Reels from Public Facebook Pages
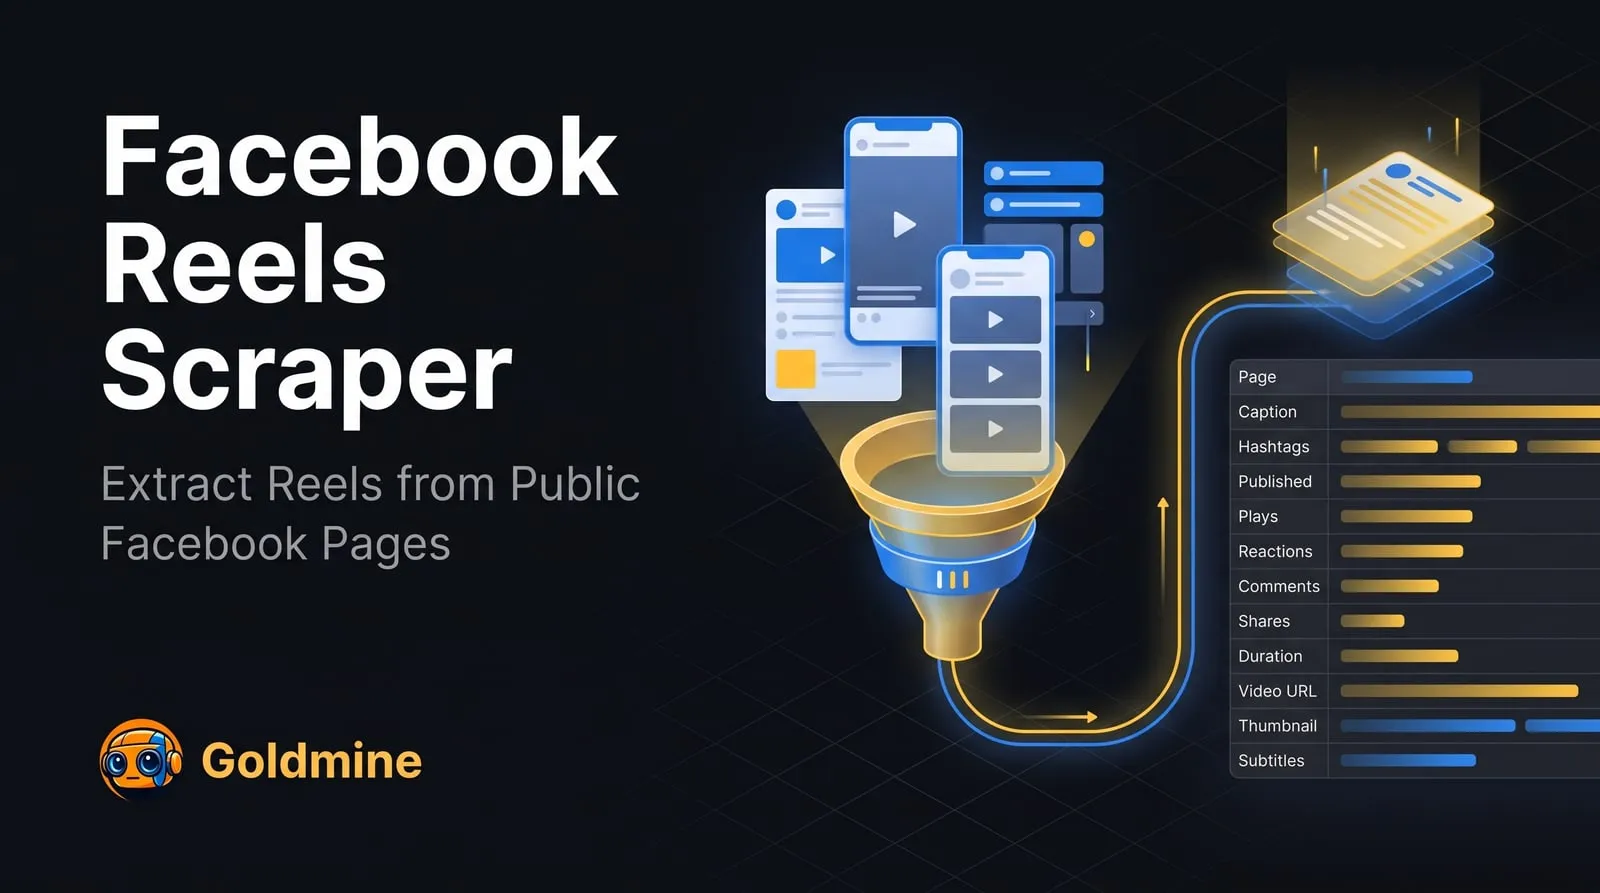
This Facebook reels scraper turns the reels tab of any public page or profile on Facebook into structured data. Give it page URLs or usernames and it returns the page's Facebook reels, newest first, each with its caption and hashtags, publish time, play count, reactions, comments and shares, duration, video and thumbnail URLs, subtitle files, and the page's name and follower count. Teams use it to track what a brand or a competitor publishes as short video, compare how reels perform, and build datasets of short-form video for research.
Paste as many pages as you like, choose how many reels you want from each and how far back to go, and get one dataset item per reel, ready to export to JSON, CSV or Excel. No Facebook account, cookies, API key or proxy is needed.
🚀 Key Features
- 🔎 Page URLs or usernames —
natgeo,https://www.facebook.com/natgeo, its/reelstab, or aprofile.php?id=…link - 🎞️ Reel data — caption, hashtags, publish time, duration, width and height, video URLs in HD and SD, thumbnail
- 📈 Engagement on every reel — play count, reactions, comments and shares
- 💬 Subtitle files — the subtitle tracks Facebook offers for a reel, with their language, when it has any
- 🏷️ Page details on every reel — page name, username, id, URL, verified badge, follower count and profile picture
- 📑 Newest first, per page —
maxItemslimits reels per page, anduntilDatestops at reels older than a date - 🛡️ No login and no proxy — reads only what Facebook shows logged-out visitors; a proxy is optional
- 📤 Multiple export formats — JSON, CSV, Excel, XML via the Apify dataset
- 🔁 Schedulable runs — run it daily with
untilDateto collect each new reel as it is posted
👥 Who Is This Actor For?
- 📣 Social media and marketing teams — seeing which of a brand's reels get the most plays, reactions and shares
- 🕵️ Competitive analysts — tracking what competitors publish as short video and how often
- 🎥 Creators and agencies — finding the formats, lengths and hashtags that perform on a page
- 🧠 Researchers — building datasets of short-form video captions, subtitles and engagement
- 🤖 AI builders — feeding reel captions, subtitle files and engagement into an agent or analysis pipeline
💡 Common Use Cases
- Scrape Facebook reels from a brand page with their play counts
- Export a competitor's last 100 Facebook reels to a spreadsheet
- Track reactions, comments and shares on a page's new reels every day
- Download the video and subtitle file of each reel a page published this month
- Compare reel length and hashtags against engagement across several pages
🔗 Supported URL Types
| URL Type | Example |
|---|---|
| Page URL | https://www.facebook.com/natgeo |
| Reels tab | https://www.facebook.com/natgeo/reels/ |
| Username | natgeo |
| Profile by id | https://www.facebook.com/profile.php?id=100044623170418 |
📥 Input
| Field | Type | Description | Default |
|---|---|---|---|
startUrls | Array | Facebook Pages or public profiles whose reels to scrape: a page URL, its reels tab, a username, or a profile.php?id=… link. One entry per page. | Required |
maxItems | Integer | Maximum number of reels to extract per page (start URL), newest first. | 10 |
untilDate | String | Stop scraping a page when its reels get older than this date (YYYY-MM-DD). Leave empty to scrape until maxItems is reached. | — |
proxyConfiguration | Object | Proxy settings. Facebook serves reels without a proxy, so none is used by default. | { "useApifyProxy": false } |
Example Input
📤 Output
Each dataset item is one reel:
| Field | Type | Description |
|---|---|---|
reelId | String | The reel's video id |
postId | String | The id of the post that carries the reel |
url | String | Link to the reel |
caption | String | The reel's caption, or null when it has none |
hashtags | Array | Hashtags in the caption, without # |
publishedAt | String | Publish time (ISO 8601, UTC) |
durationSeconds | Number | Length of the video in seconds |
width, height | Number | Video dimensions in pixels |
playCount | Number | Plays, from the rounded figure Facebook shows (for example 165K = 165000) |
playCountText | String | Plays exactly as Facebook shows them, e.g. 165K |
reactionCount | Number | Reactions (likes and other reactions) |
commentCount | Number | Comments |
shareCount | Number | Shares, from the figure Facebook shows (rounded above 1,000) |
shareCountText | String | Shares exactly as Facebook shows them, e.g. 22K |
thumbnailUrl | String | Thumbnail image URL |
videoUrl | String | Video file URL, HD when available |
videoSdUrl | String | Video file URL in SD |
subtitles | Array | Subtitle files (.srt) Facebook offers for the reel: locale, language and url. Often empty; when present these are usually automatic translations |
audioTitle | String | Title of the reel's soundtrack, or null for original audio |
isOriginalAudio | Boolean | Whether the reel uses its own audio |
isReshare | Boolean | Whether the reel is a reshare of another creator's reel |
pageName | String | Name of the page that posted the reel |
pageUsername | String | The page's username |
pageId | String | The page's id |
pageUserId | String | The page's profile id |
pageUrl | String | Link to the page |
pageIsVerified | Boolean | Whether the page has a verified badge |
pageFollowers | Number | The page's follower count |
pageProfilePictureUrl | String | The page's profile picture URL |
inputUrl | String | The start URL or username this reel was found from |
Video, thumbnail and subtitle URLs are signed by Facebook and stop working after a few days, so download the files you need soon after the run.
Example Output
A real item from a run on natgeo, with URL query strings removed and the subtitle list shortened to two of its nine tracks:
You can export the dataset as JSON, CSV, Excel, XML, RSS, or HTML from the Apify Console or via the Apify API.
💰 Pricing
This Actor is pay per event (you pay per result): each reel saved costs $0.0035 on the free plan, so 1,000 reels cost $3.50, falling to $0.0025 per reel ($2.50 per 1,000) on Gold and higher Apify plans. Each run also has a $0.00005 start fee per GB of memory. It runs without a proxy by default, so there is no proxy traffic to pay for. A free Apify account is enough to try it.
❓ FAQ
What is the Facebook Reels Scraper?
It is a Facebook reels scraper that takes public page URLs or usernames and returns each page's reels as structured data, with engagement counts and the page's details on every reel. You can run it from the Apify Console, the API, or on a schedule.
Do I need an account, cookies or an API key?
No. The Actor reads only what Facebook shows to visitors who are not logged in.
Do I need a proxy?
No. Facebook serves reels without one, so the default runs with no proxy. If a page comes back blocked, switch the proxy setting to Apify datacenter or residential proxies.
How many reels can I get per page?
Up to maxItems per page, newest first, until the page has no older reels. A single run on National Geographic's page returned 200 reels going back six months.
Does it handle pagination automatically?
Yes. It keeps loading older reels until it reaches maxItems, the untilDate, or the end of the page's reels.
Why is playCount a round number?
Facebook shows plays and shares to logged-out visitors rounded, for example 165K. The Actor returns that figure as a number in playCount, and exactly as shown in playCountText. Reactions and comments are exact.
Why did a page return no reels?
Pages that have never posted a reel have no reels tab, and the run status names how many such pages it found. Pages that are private, age-restricted or removed cannot be read logged-out.
Can I scrape a single reel, or a page's posts and comments?
This Actor reads a page's reels tab. For a page's feed posts and for the comments on a reel, use the other Actors in the Facebook Scraper Suite listed below.
Can I schedule it or integrate it with my app?
Yes. Every Apify Actor exposes a REST API, webhooks, and integrations with Zapier, Make, Google Sheets and Slack, and can be called from an AI agent via the Apify MCP server.
Is it legal to scrape Facebook?
This Actor accesses only publicly available pages. You are responsible for making sure your use complies with Facebook's terms of service and the laws in your jurisdiction.
What if Facebook changes and the Actor breaks?
Open an issue on the Actor's Issues tab with a page URL that fails, so the problem can be reproduced.
🧩 Part of the Facebook Scraper Suite
Goldmine's Actors for public Facebook data. Also try:
- Facebook Posts Scraper — posts, reactions, comments and shares from public Facebook pages
- Facebook Comments Scraper — comments and replies on public posts, videos, reels and photos
- Facebook Page Details Scraper — followers, category, contact details and about text for a page, one row per page
- Facebook Group Scraper — posts, authors, reactions and photos from public Facebook groups
- Facebook Ads Library Scraper — ad copy, creatives, CTAs and run dates from the public Facebook Ad Library
See every Goldmine Actor at apify.com/logical_scrapers.
📬 Contact & Support
- Issues & feature requests: use the Issues tab on this Actor's page. Include a page URL that fails so it can be reproduced.
- Email:
coredev.dan@gmail.com - If this Actor saved you time, please leave a ⭐ rating on the Apify Store. It helps us keep it maintained.


