
Bing Search Scraper
Pricing
from $1.00 / 1,000 serp pages
Bing Search Scraper
Scrape Bing search results — organic results, paid ads, related queries, People Also Ask, news, videos, and the entity/knowledge card. Filter by market, country, language, safe search, and freshness. Decodes Bing /ck/a tracking redirects to canonical URLs.
Pricing
from $1.00 / 1,000 serp pages
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
4
Total users
3
Monthly active users
a day ago
Last modified
Categories
Share
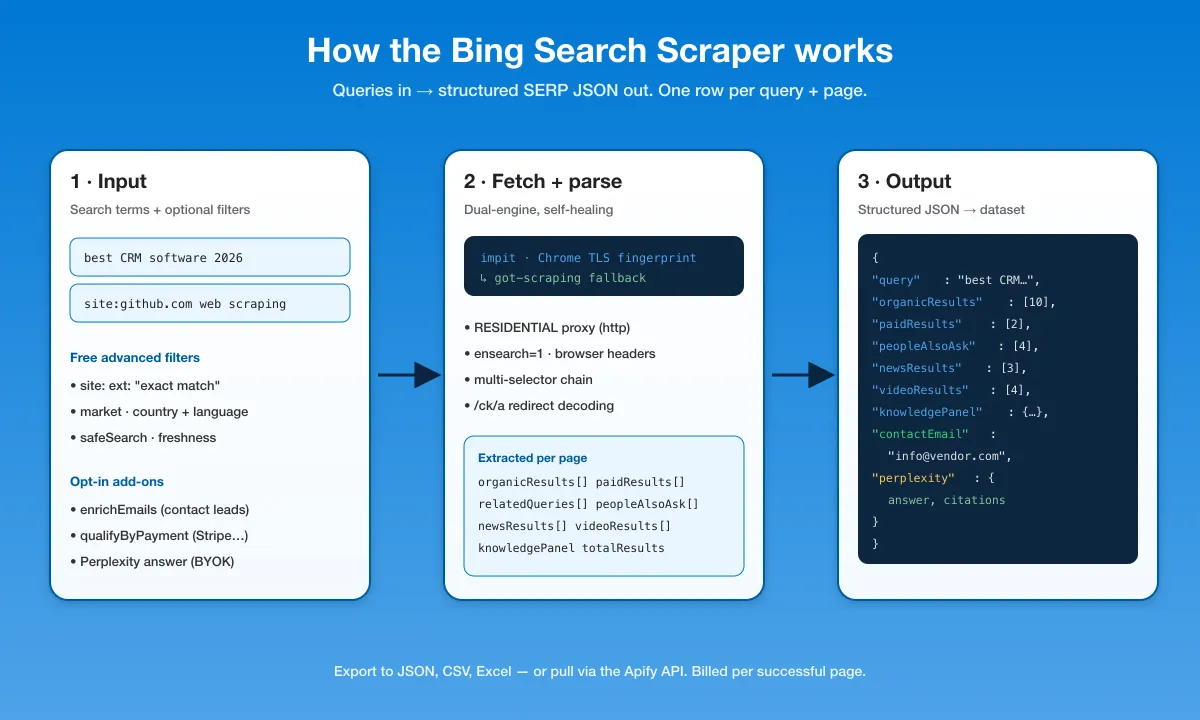
Scrape Bing search results pages (SERPs) and get clean, structured JSON — organic results, related searches, People Also Ask, news, videos, paid ads, and the entity/knowledge card — for any query, market, country, and language.
Two fetch modes: a fast HTTP mode (default) for organic results at scale,
and a browser mode (Camoufox, hardened Firefox) that loads related searches
via client-side AJAX. Bing's /ck/a tracking redirects are decoded to canonical
URLs, a multi-selector parser chain survives Bing's layout rotations, and
structural soft-block detection won't false-reject a valid SERP.
What it extracts
- Organic results — position, title, URL, displayed URL, description, date, emphasized keywords, and sitelinks (HTTP + browser mode)
- Related searches — the "Related searches" box at the bottom of the SERP (browser mode only; loaded via client-side AJAX)
- Paid ads — sponsored results with title, URL, displayed URL, description, and sitelinks (parser ready; Bing rarely serves ads to automated requests)
- People Also Ask — the expandable Q&A questions with answer text when present (parser ready; Bing rarely serves PAA to automated requests)
- News results — the in-SERP news block (parser ready; query-dependent)
- Video results — the in-SERP videos block (parser ready; query-dependent)
- Knowledge / entity card — title, subtitle, description, fact attributes, source link, and image (parser ready; query-dependent)
- Total results — the "1-10 of N results" count (HTTP + browser mode)
- Contact emails (opt-in) — turn a SERP into leads: scrape each result's own site for a contact email + people. See Lead enrichment below.
- Perplexity AI answer (opt-in, BYOK) — a grounded AI answer with citations per query, via Perplexity's official API with your key. See Perplexity AI answer.
Input
| Field | Type | Default | Notes |
|---|---|---|---|
queries | string[] | — | One or more search terms. Required. |
maxPagesPerQuery | integer | 1 | Pages to fetch per query (~10 results each). |
resultsPerPage | integer | 10 | Bing's count parameter (Bing honors up to ~50, caps near 10–30 in practice). |
market | string | — | Bing market code, e.g. en-US, en-GB, de-DE. Cleanest geo+language selector. Wins over countryCode/languageCode. |
countryCode | string | US | Two-letter country (cc). Used when no market is set. |
languageCode | string | en-US | UI language (setLang), BCP-47 tag. Used when no market is set. |
safeSearch | off/moderate/strict | off | Bing SafeSearch level. |
freshness | Day/Week/Month | — | Recency filter (filters=ex1:"ezN"). |
includeAds | boolean | true | Extract paid ad results. |
includeRelated | boolean | true | Extract the "Related searches" box. |
includePeopleAlsoAsk | boolean | true | Extract the "People also ask" box. |
includeNews | boolean | true | Extract the in-SERP news block. |
includeVideos | boolean | true | Extract the in-SERP videos block. |
includeKnowledgePanel | boolean | true | Extract the entity/knowledge card. |
maxConcurrency | integer | 5 | Parallel query-pages. |
maxRequestRetries | integer | 5 | Retries per page before giving up (rotates proxy exit). |
useBrowser | boolean | false | Browser mode — use Camoufox (hardened Firefox) to load client-side AJAX features like related searches. Slower but richer. See Browser mode below. |
proxy | object | RESIDENTIAL | Proxy config. Leave default — see Limitations. |
Advanced search filters
Bing search operators exposed as structured fields (all folded into the query
string — you can also type the operators directly inside a queries entry):
| Field | Type | Operator | Notes |
|---|---|---|---|
site | string | site: | Restrict to one site. |
fileTypes | string[] | ext: | OR-combined (pdf, docx, …). |
forceExactMatch | boolean | "…" | Wrap the query in quotes. |
saveHtml | boolean | — | Attach raw SERP HTML to each row under html (large). |
saveHtmlToKeyValueStore | boolean | — | Save HTML to the KV store; add htmlSnapshotUrl to each row. |
Lead enrichment (opt-in)
Turn search results into leads. When enrichEmails: true, the top business domains
in each SERP get their own site scraped for a contact email + people; the hits
are attached to those organic results as contactEmail and emailEnrichment.
| Field | Type | Default | Notes |
|---|---|---|---|
enrichEmails | boolean | false | Enable contact-email enrichment. |
qualifyByPayment | boolean | false | Also flag businesses that take money online (Stripe, Shopify, …). |
maxEnrichedDomainsPerPage | integer | 3 | Cap unique business domains enriched per page. |
- Best on business-intent queries (
"commercial plumbers chicago","B2B SaaS vendors"). - Non-business domains (search engines, social, Wikipedia, big marketplaces) are skipped; domains are de-duped per page.
- Best-effort and free (direct site scrape) — enrichment never fails a scrape.
Perplexity AI answer (opt-in, bring-your-own-key)
Attach a Perplexity (Sonar) AI answer to each query — grounded, with citations.
This calls Perplexity's official API with your own key, so you are billed by
Perplexity per request (it is not scraping). The answer lands on the page-1 row
under perplexity { answer, model, citations, searchResults?, relatedQuestions? }.
| Field | Type | Default | Notes |
|---|---|---|---|
perplexitySearch | boolean | false | Enable the Perplexity answer. |
perplexityApiKey | string (secret) | — | Your key from docs.perplexity.ai. Required. |
perplexitySearchRecency | day/week/month/year | — | Restrict grounding to recent content. |
perplexityRelatedQuestions | boolean | false | Also return follow-up questions. |
Inert unless both the toggle is on and a key is supplied; a Perplexity error never breaks the SERP scrape.
Example input
Output
One dataset item per (query, page):
selectorUsed tells you which parser variant matched — handy for spotting future
Bing layout drift.
How it works
- Dual-engine fetch — tries
impit(Rust, real Chrome TLS + HTTP/2 fingerprint) first, falling back togot-scraping. Two independent fingerprints = two chances against bot detection. - Browser-like headers — Bing's bot detection is header-sensitive: a request
missing the
sec-ch-ua/sec-fetchfamily is far more likely to be served an empty "no results" page. The actor sends a full Chrome header set. ensearch=1— forces the US/English SERP from outside-US proxy exits, somarket/countryCode/languageCodeare honored instead of silently localised to the exit IP's geography.- Self-healing selectors — organic results run through a multi-selector chain
(the stable
li.b_algofirst, then a class-agnostica:has(h2)structural net), so a single Bing class rename won't zero out a run. - Redirect decoding — Bing wraps every destination URL in a
/ck/atracking redirect. The real URL is recovered from the base64url-encodeduparameter, so you get canonical URLs, not Bing tracking links. - Structural soft-block detection — a page is only treated as blocked if it
doesn't structurally look like a Bing SERP (no
#b_results), so a genuineb_no"no results" page is returned as a legitimate zero-results row, not a block.
Browser mode
Set useBrowser: true to switch from the fast HTTP fetcher to Camoufox
(hardened Firefox with fingerprint spoofing). Browser mode loads client-side
AJAX features that Bing doesn't server-render:
| Feature | HTTP mode | Browser mode |
|---|---|---|
| Organic results | ✅ 10/page, every SERP | ✅ 10/page, every SERP |
| Total result count | ✅ | ✅ |
| Related searches | ❌ (client-side only) | ✅ 6–8 per query (~40% of proxy exits) |
| Paid ads | ❌ | ❌ (Bing blocks via rdr=1) |
| People Also Ask | ❌ | ❌ (Bing blocks via rdr=1) |
| News / Videos / Knowledge | ❌ | ❌ (Bing blocks via rdr=1) |
Why not all features? Bing detects browser automation and marks the
request with rdr=1, serving a stripped SERP that includes organic results
and related searches but omits ads, PAA, news, videos, and knowledge panels.
This holds across Chromium, Camoufox, stealth scripts, and residential proxies.
The parsers for those features are implemented and will fire if Bing changes
its rendering, but they're rarely populated today.
When to use browser mode: when you need related searches alongside organic
results. It's ~3× slower per page (browser launch + render + AJAX settle) and
uses more memory, so keep maxConcurrency low (1–2).
When to use HTTP mode (default): for organic-only results at scale — faster, cheaper, and more reliable. Related searches are the main trade-off.
Limitations & notes
-
Use the default RESIDENTIAL proxy. Bing soft-blocks datacenter IPs by returning an empty "no results" (
b_no) page instead of a CAPTCHA. This actor is built around Apify's RESIDENTIAL proxy group, which is applied automatically. Overridingproxyto a datacenter group will fail with soft-blocks for most queries — leave the proxy at its default. -
Ads, PAA, news, videos, and knowledge panels are client-side only. Bing does not server-render these features over HTTP, and its
rdr=1anti-automation detection strips them from browser-rendered SERPs too. The parsers are implemented against Bing's stable selectors and will fire if Bing changes its rendering, but they're rarely populated today. Organic results, total counts, and related searches (browser mode) are the reliably available features. -
Related searches need browser mode. Set
useBrowser: trueto load the "Related searches" box via client-side AJAX. About 40% of residential proxy exits serve them; the rest get organic-only. HTTP mode never gets related searches. -
resultsPerPageis effectively ~10–30. Bing honors thecountparameter up to ~50, but caps the rendered page near 10–30 in practice. To collect more, raisemaxPagesPerQueryrather thanresultsPerPage. Pagination always steps by the real page size, so no results are skipped if you set a larger value. -
Knowledge-card images are sometimes lazy-loaded by Bing's JS, so
imageUrlmay be absent even when the card is otherwise fully populated. -
People Also Ask answers are only present when Bing pre-expands the card; for most queries you'll get the question and destination URL but no answer text.
-
News / video blocks appear only for queries that trigger them (e.g. a current-events query surfaces news; a "how to" query may surface videos). Their absence for a given query is normal, not a parser failure.
Tips
- Use
market(e.g.en-GB,de-DE) for the cleanest localized results — it sets both geography and language in one parameter. - For deep coverage, set
maxPagesPerQuery(e.g. 5) instead ofresultsPerPage. - Bing search operators work inside
queries(site:,ext:,"exact",OR). - Use
freshness: "Week"for recent-content queries (news, launches, releases).
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/bing-search-scraper).
Purpose: Scrape structured Bing SERPs for any query, market, country and language — organic results, paid ads, related searches, People Also Ask, news, videos, knowledge card and total counts — with a self-healing selector chain that survives Bing's layout rotations, and /ck/a redirect decoding to canonical URLs.
Minimal input:
Output: one row per (query, page) — query, page, searchUrl, organicResults {type, position, title, url, displayedUrl, description, date, siteLinks}, paidResults, relatedQueries {title, url}, peopleAlsoAsk {question, answer, url}, newsResults {title, url, source, date}, videoResults {title, url, source, duration}, knowledgePanel {title, description, attributes}, totalResults, selectorUsed, scrapedAt.
Behaviors an agent should know:
queriesis the only required field; one row per query × page. To collect more results, raisemaxPagesPerQuery(default 1) — Bing capsresultsPerPagenear 10–30 regardless of the value set.- Leave
proxyat its default RESIDENTIAL group; overriding to datacenter groups fails with soft-blocks (Bing returns an empty "no results" page to datacenter IPs). - Use
market(e.g.en-US,de-DE) for the cleanest localized results — it sets geography + language in one parameter and wins overcountryCode/languageCode. freshness(Day/Week/Month) filters by recency;safeSearch(off/moderate/strict) controls explicit-content filtering.- Bing wraps destination URLs in
/ck/atracking redirects; the actor decodes them to canonical URLs, soorganicResults[].urlis the real destination, not a Bing tracking link. enrichEmails(opt-in, best-effort, free) scrapes top business domains' own sites forcontactEmail;perplexitySearch(opt-in, bring-your-own-key) attaches a Perplexity answer and is billed by Perplexity, not this actor.useBrowser: trueswitches to Camoufox (hardened Firefox) to load related searches via client-side AJAX. ~3× slower; organic results and total counts are available in both modes. Ads/PAA/news/videos/knowledge are parser-ready but Bing'srdr=1anti-automation detection strips them from both HTTP and browser responses.- Pay-per-event billing — see the Pricing tab on the actor page.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Microsoft Corporation or any of its subsidiaries. All trademarks mentioned, including Bing and Microsoft, are the property of their respective owners.
The scraper accesses only publicly available Bing search results pages — no authenticated endpoints, paid features, or content behind any bing.com login wall. Users are responsible for ensuring their use complies with bing.com's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organization.
SEO Keywords
bing search scraper, scrape bing, bing serp scraper, bing search api, bing.com scraper, apify bing, serp scraper, search results scraper, organic results scraper, seo rank tracking, keyword research data, competitor serp analysis, people also ask data, search engine intelligence, serp data export, marketing analytics data, bing ads scraper, bing news scraper, bing video scraper


