

Facebook Profile Scraper | No Login | Bulk | $4/1K
Pricing
from $4.00 / 1,000 profiles
Facebook Profile Scraper | No Login | Bulk | $4/1K
Scrape public Facebook profiles and Pages without logging in. Paste profile URLs, usernames or numeric IDs and get name, bio, work, education, city, hometown, relationship, websites, followers, verified badge and photos. One row per profile. No cookies. $4 per 1,000 profiles.
Pricing
from $4.00 / 1,000 profiles
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 hours ago
Last modified
Categories
Share
Facebook Profile Scraper — Public Profiles & Pages, No Login
Turn Facebook profile links, usernames or numeric IDs into clean, structured profile rows without logging in. Get the name, category, bio, work, education, city, hometown, relationship, websites, exact follower counts, verified badge, and profile and cover photos of public profiles and Pages. One row per profile, ready for JSON, CSV or Excel.
Why Use This Scraper?
- ✅ No login, cookies or Facebook account. Paste the profiles and run.
- ✅ Exact follower counts such as
121350061, not just the rounded "121M" label. - ✅ Profiles and Pages in the same run. Every row says which one it is and gives its category.
- ✅ The full public intro card: work, education, current city, hometown, relationship, websites, emails and phones.
- ✅ Every common link format works: vanity URLs,
profile.php?id=links,/people/permalinks, mobile hosts,fb.com, plain usernames and numeric IDs. - ✅ Pay only for delivered profiles. Anything that isn't delivered is listed with its reason and never billed.
- ✅ Duplicate-safe. The same profile given twice, by username and by ID, is delivered once.
Overview
Facebook Profile Scraper is built for sales and marketing teams, influencer researchers, recruiters and data teams who already have a list of Facebook profiles or Pages and need structured data about them.
You give it a list of profiles. It returns one dataset row per profile with what Facebook shows a logged-out visitor on the profile's header and intro card: identity, category, bio, work, education, places, links, audience counts and photos.
Personal profiles and Pages come back in the same row shape. The accountType field tells them apart. The actor reads profiles, not their content: posts, photos, comments, friends lists and follower lists are not scraped.
Supported Inputs
Input types
| Input type | Pattern | Example |
|---|---|---|
| Profile or Page URL | facebook.com/<name> | https://www.facebook.com/zuck |
| Numeric-ID link | facebook.com/profile.php?id=<id> | https://www.facebook.com/profile.php?id=4 |
| People permalink | facebook.com/people/<Name>/<id>/ | https://www.facebook.com/people/<Name>/<id>/ |
| Legacy Page URL | facebook.com/pg/<name>/ | https://www.facebook.com/pg/NASA/ |
| Mobile and short hosts | m., mbasic., web., touch. or fb.com | https://m.facebook.com/BillGates |
| Username | letters, digits, dots, - and _; a leading @ is fine | zuck or @zuck |
| Numeric ID | digits only | 4 |
Links are normalized before fetching, so https://m.facebook.com/NASA/?ref=bookmarks and NASA are the same input.
Copy-pasteable startUrls
Unsupported inputs
- ❌ Groups, events, posts, photos, videos, reels, Marketplace, search and hashtag links (
/groups/,/events/,/posts/,/watch/,/marketplace/,/search/,/hashtag/and similar). They are rejected before any fetch and listed inNOT_DELIVEREDwith the reason. - ❌ Links that are not on facebook.com or fb.com, including shortened links such as bit.ly.
- ❌ Anything behind the Facebook login: friends-only details, private profiles, friends lists.
- ❌ Keyword or name search. This actor reads a list of profiles you already have. To find profiles by keyword, run Facebook Search Scraper first and feed its URLs in here.
Use Cases
| Audience | Use case |
|---|---|
| Sales & lead generation | Enrich a list of business Pages with category, website, email and phone before outreach |
| Influencer marketing | Compare creators and public figures by exact follower count and verified status |
| Brand & competitor monitoring | Schedule a run over competitor Pages and track their follower counts over time |
| Recruiting & research | Read the public work and education lines of profiles you already have links for |
| Data teams & agencies | Turn a column of Facebook links in a CRM or spreadsheet into clean, typed fields |
How It Works
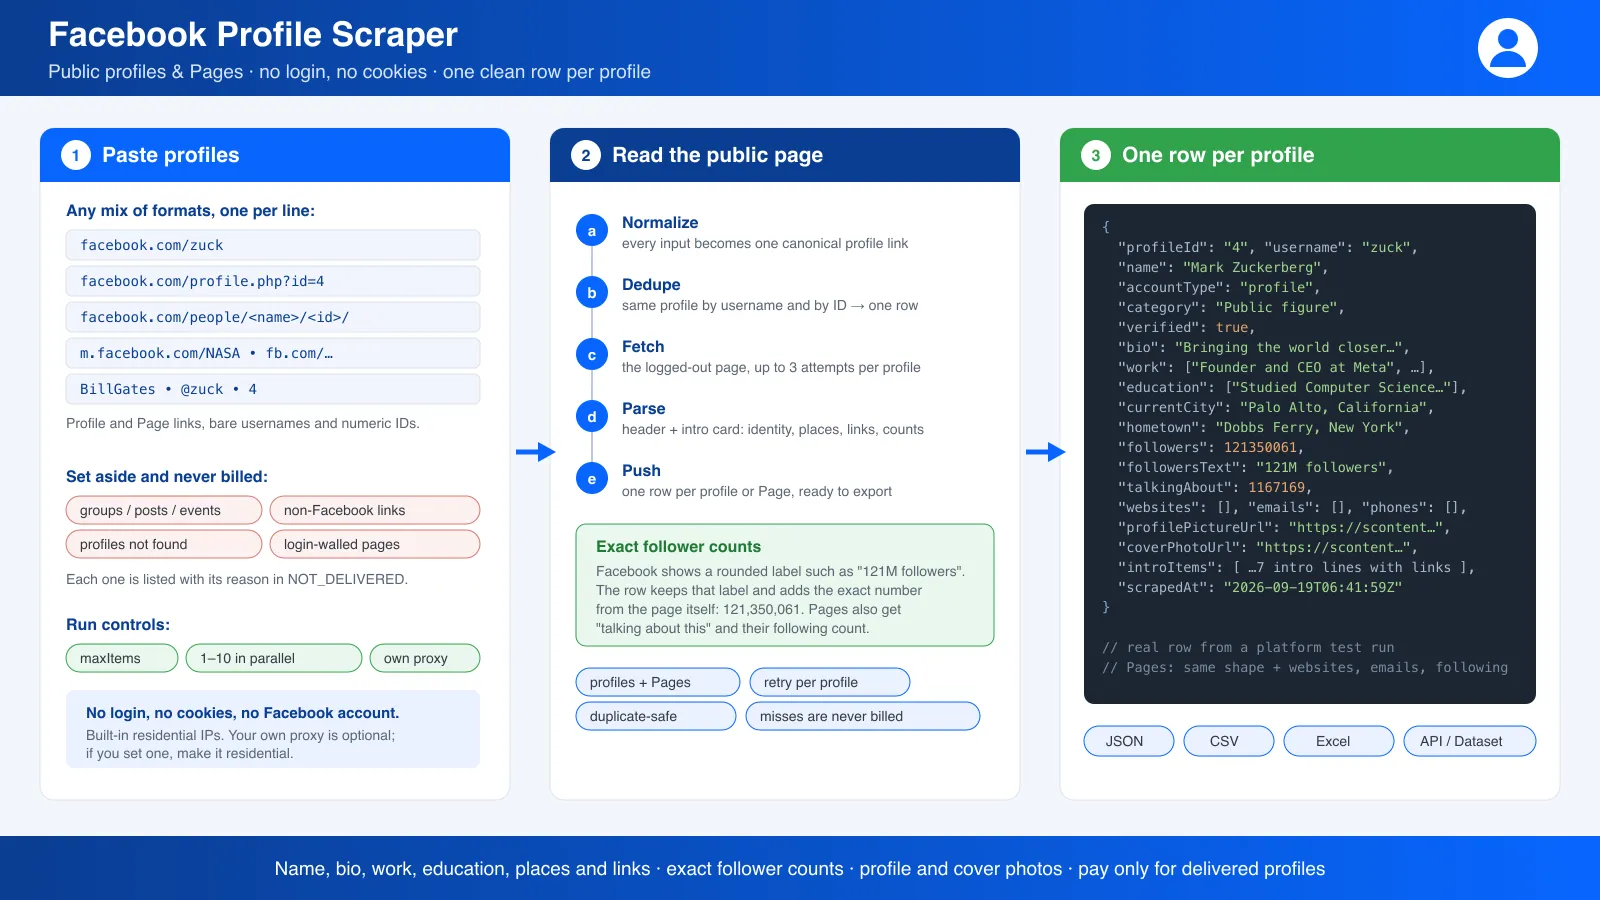
- Paste profiles. URLs, usernames or numeric IDs, in any mix.
- Normalize and dedupe. Every input becomes one canonical profile link. Duplicates are fetched once, and links that are not profiles are set aside.
- Fetch the public page. Each profile is loaded as a logged-out visitor through residential IPs, with up to three attempts.
- Parse the header and intro card. Name, category, bio, work, education, places, links, audience counts and photos.
- Export. One row per profile in JSON, CSV or Excel. Every input that gets no row, other than a duplicate of a delivered profile, is listed in the
NOT_DELIVEREDrecord with its reason.
Input Configuration
Input fields
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
startUrls | array of strings | yes | – | Profile or Page URLs, usernames or numeric IDs, one per line. Objects of the form {"url": "..."} are accepted too. Duplicates are fetched once. |
maxItems | integer | no | 1000 | Stop after this many profile rows. |
maxConcurrency | integer (1–10) | no | 4 | How many profiles are fetched at the same time. |
proxy | object | no | built-in residential pool | Leave empty for most runs. Facebook shows a login page to datacenter IPs, so if you set your own proxy, make it residential. |
Common scenarios
1. A few profiles
2. A mixed column from a spreadsheet
3. Your own residential proxy
Output Overview
Each dataset item is one profile or Page:
- Identity: profile ID, username, name, canonical URL, account type (
profileorpage), category, verified badge, memorialized flag - About: bio, work, education, current city, hometown, relationship
- Contact and links: websites, emails and phones, when the intro card shows them publicly
- Audience: exact follower count with Facebook's rounded label, following, friends, "talking about this", likes
- Media: profile picture and cover photo URLs
- Raw intro:
introItems, every intro line with its link, for anything the named fields don't cover - Run metadata: the input you gave (
inputUrl) andscrapedAt
Profiles and Pages share one shape. A field the profile doesn't show is null, and an empty list is []. Pages usually have a category, websites and a "talking about this" count but no work or education. Personal profiles are often the other way round.
Output Samples
Personal profile, input https://www.facebook.com/zuck (trimmed)
Page, input https://www.facebook.com/NASA (trimmed)
Both rows come from a test run on the Apify platform on 2026-09-19.
Key Output Fields
| Group | Fields |
|---|---|
| Identity | profileId, username, name, alternateName, url, accountType, category, verified, isMemorialized, linkedPageId |
| About | bio, work[], education[], currentCity, hometown, relationship |
| Contact & links | websites[], emails[], phones[] |
| Audience | followers, followersText, following, followingText, friends, talkingAbout, likes |
| Media | profilePictureUrl, coverPhotoUrl |
| Raw intro | introItems[] with text and url |
| Run | inputUrl, scrapedAt |
FAQ
Do I need a Facebook account, cookies or a login?
No. The actor reads each profile the way a logged-out visitor sees it. You never share credentials, and no account is at risk.
Which links work?
Profile and Page URLs on www, m, mbasic, web, touch and fb.com hosts, profile.php?id= links, /people/<Name>/<id>/ permalinks, legacy /pg/<name>/ links, bare usernames (with or without @) and numeric IDs. Group, event, post, photo, video, Marketplace and search links are rejected and listed in NOT_DELIVERED.
How exact are the follower counts?
followers is the exact number Facebook puts in the page's own metadata, for example 121350061. followersText keeps the rounded label shown on screen, such as "121M followers". If a page carries no exact figure, followers falls back to the rounded label, so "121M" becomes 121000000.
Why are some fields empty?
The actor only returns what a logged-out visitor can see. Many personal profiles hide their work, education, city or relationship, and Pages rarely list work or education. Hidden fields are null or []. friends and likes are filled only when Facebook shows those counts publicly, which is rare today.
Can it scrape private profiles, friends lists or posts?
No. Private and friends-only details, friends lists, follower lists, posts, photos and comments are out of scope. For posts, use Facebook Posts Scraper.
What happens to profiles that can't be scraped?
They are listed in the run's NOT_DELIVERED record (Storage → Key-value store) with the input and a reason, such as "Facebook says this profile or Page is not available", an invalid link, or "not attempted: maxItems reached". They are never pushed to the dataset, so they are never billed.
Do the photo links expire?
Yes. profilePictureUrl and coverPhotoUrl are signed Facebook CDN links that stop working after a few days. If you need the images, download them soon after the run.
Do I need a proxy?
No. Runs use a built-in residential pool by default. If you set your own proxy, use a residential one, because Facebook shows a login page to datacenter IPs.
How fast is it?
A test run of three profiles took about 9 seconds. Up to 10 profiles are fetched in parallel (maxConcurrency), and each one gets up to three attempts before it is set aside.
Can I find profiles by name or keyword?
Not with this actor. Use Facebook Search Scraper to find profiles and Pages by keyword, then paste their URLs here.
Support
- Issues and feature requests: the Issues tab on this actor in Apify Console.
- Custom work:
- Website: https://muhamed-didovic.github.io/
- Email: muhamed.didovic@gmail.com
Additional Services
- Custom fields, bulk profile lists or scheduled monitoring: muhamed.didovic@gmail.com
- API access (no Apify platform fee, usage fee only): muhamed.didovic@gmail.com
Explore More Scrapers
- Facebook Search Scraper: find people, Pages and posts by keyword
- Facebook Page Contact Details: emails, phones and opening hours of business Pages
- Facebook Posts Scraper: posts from Pages and post URLs, no login
- Facebook URL to ID: numeric IDs for Page, profile, group and post links
- Facebook Public Group Posts & Comments: posts and comments from public groups
Full list at apify.com/memo23.
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/facebook-profile-scraper).
Purpose: Scrape public Facebook profiles and Pages without a login: one row per profile with identity, intro card, exact follower count and photos.
Minimal input:
Output: one dataset row per profile or Page with profileId, username, name, alternateName, url, accountType (profile or page), category, verified, bio, work[], education[], currentCity, hometown, relationship, websites[], emails[], phones[], followers, followersText, following, followingText, friends, talkingAbout, likes, profilePictureUrl, coverPhotoUrl, linkedPageId, isMemorialized, introItems[] {text, url}, inputUrl and scrapedAt.
Behaviors an agent should know:
startUrlstakes URLs, usernames (zuck) or numeric IDs (4). SetmaxItemsto cap rows.- Inputs are deduplicated by link and by profile ID, so a profile never appears twice.
- Every input that gets no row (duplicates aside) is listed in the key-value record
NOT_DELIVEREDas{input, url, reason}. - Billing is pay per event: a start event per run plus one event per profile row. Rejected, not-found, blocked and skipped inputs are never billed.
- Only data visible to a logged-out visitor is returned. There are no posts, friends lists or private fields, and no keyword search.
- Photo URLs are signed CDN links that expire after a few days.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Meta Platforms, Inc. or any of its subsidiaries. Facebook is a trademark of Meta Platforms, Inc. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly available Facebook profile and Page information shown to logged-out visitors: no login, cookies, authenticated endpoints, or content behind the facebook.com login wall. Profile data can be personal data. Users are responsible for ensuring their use complies with Facebook's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organization.
SEO Keywords
facebook profile scraper, scrape facebook profiles, facebook page scraper, facebook scraper no login, facebook profile API, Apify facebook scraper, fb profile scraper, public profile scraper, social media profile scraper, follower count scraper, verified badge checker, profile bio extractor, lead enrichment data, influencer research data, competitor audience tracking, page contact details, social media intelligence, creator analytics data, B2B lead generation, Meta profile data


