
Instahyre Jobs Scraper — India Tech Jobs & Hiring Monitor
Pricing
from $1.50 / 1,000 jobs
Instahyre Jobs Scraper — India Tech Jobs & Hiring Monitor
Search and monitor India tech jobs on Instahyre — title, skills, city, apply URL and the full hiring-company profile (headcount, founded year, tagline) on every row. Track only-new postings, filter by skill, city, company or size, and add employer emails. JSON, CSV or Excel.
Pricing
from $1.50 / 1,000 jobs
Rating
5.0
(1)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
86
Total users
63
Monthly active users
16 hours ago
Last modified
Categories
Share
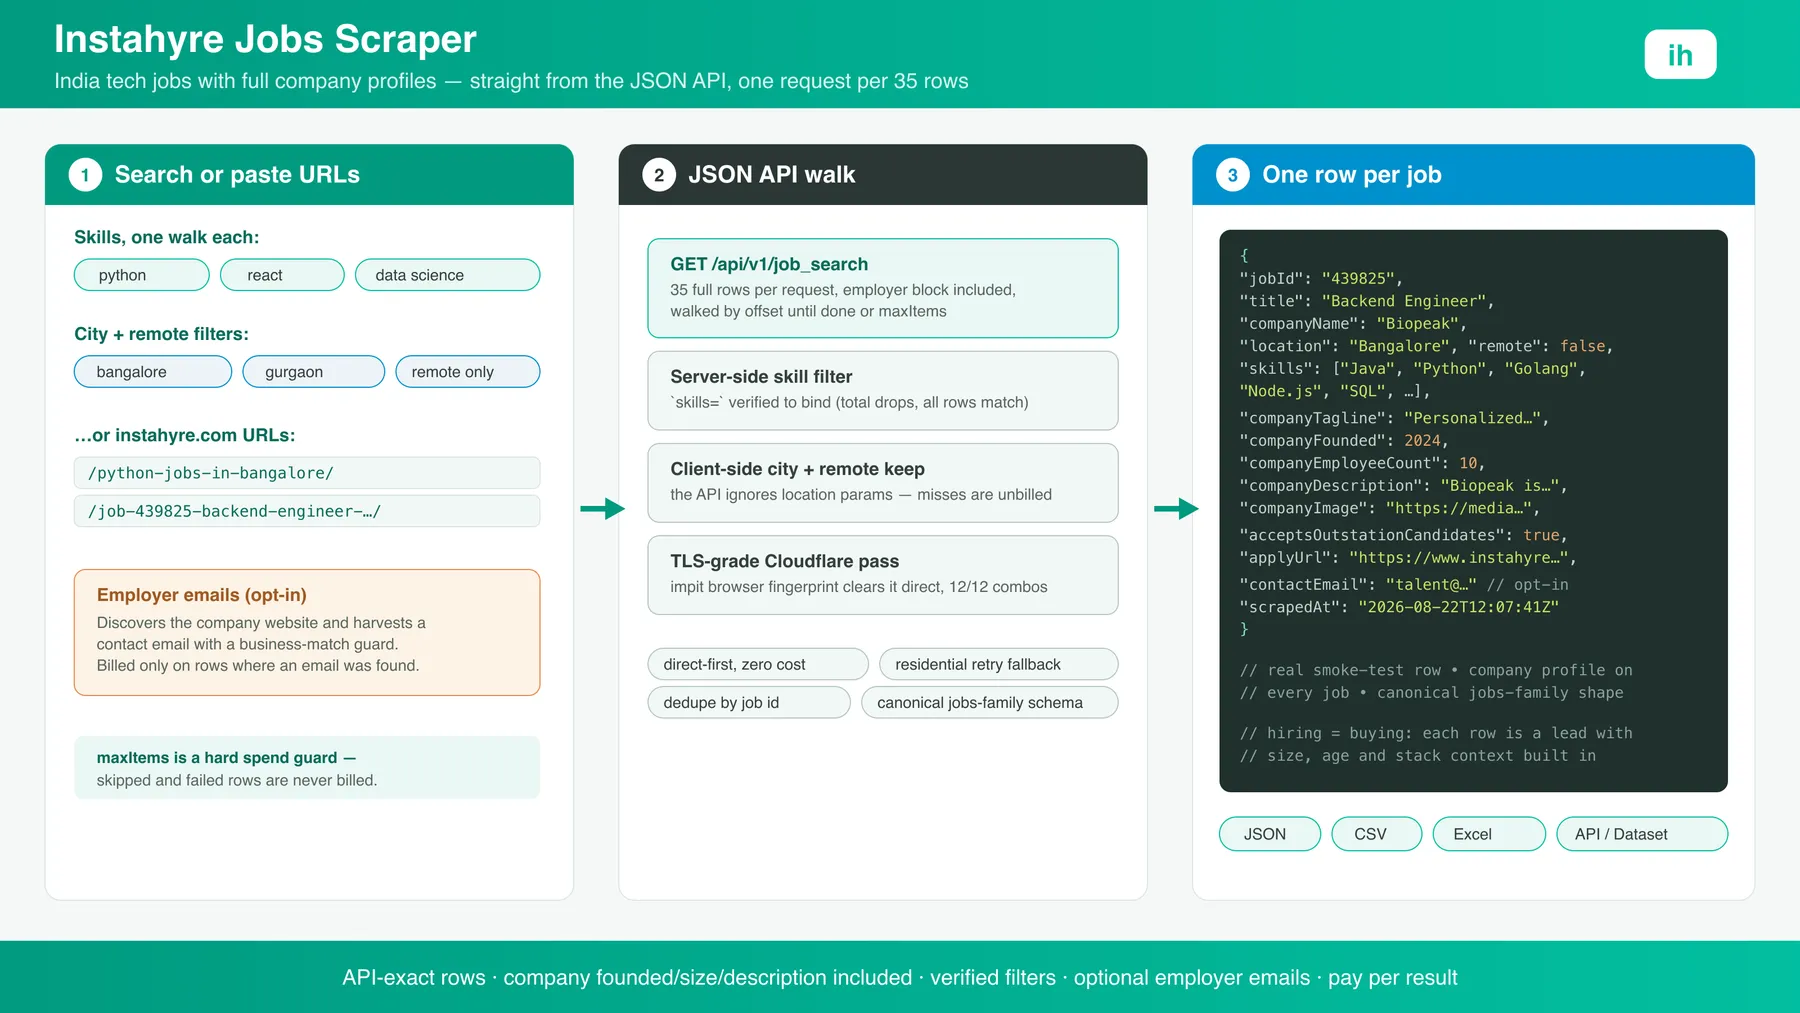
Search India's tech job market on Instahyre and watch it change over time. Every row carries the job (title, skills, locations, apply URL) plus the hiring company's full profile — name, tagline, founding year, employee count and description. Run it once for a clean dataset, or turn on monitor mode to get only the postings that are new since your last run, so you catch companies the moment they start hiring. Powered by Instahyre's own JSON API, so runs are fast and rows are exact — no HTML guesswork.
Search by skill and city, paste listing or job URLs, and optionally add employer contact emails to turn each hiring company into an outreach-ready lead.
How it works
✨ Why use this scraper?
- API-exact data — rows come from Instahyre's JSON API, one request per 35 jobs. Fast, cheap, and immune to layout changes.
- Company intelligence included — founding year, headcount, tagline and company description ride along on every job row, which most job scrapers skip.
- Skill search that actually filters — the
skillsfilter binds server-side (verified against row content, since Instahyre ignores several of its own documented parameters). - Honest city filtering — Instahyre's API ignores location parameters, so the city and remote filters are applied to row content on our side; rows that miss the filter are skipped and never billed.
- Employer emails on demand — opt-in enrichment discovers the company's website and harvests a contact email, billed only per row where one is found.
- Bulk-friendly and fail-safe — paste many URLs or skills; failed requests retry direct then through residential, and produce no billed placeholder rows.
🔁 Hiring monitor — track only what's new
Companies that just started hiring are the freshest lead of all. Turn on monitoringMode and the scraper remembers which jobs it has already seen, then on every later run emits only the postings that appeared since — new roles, new companies, new stacks. Point it at a skill (react) or a city (bangalore), put it on an Apify schedule, and you get a daily feed of who's newly hiring for what, with the company profile and optional email already attached.
Running more than one watch? Give each its own monitorStateName (e.g. bangalore-eng on one schedule, remote-sales on another) and their "already seen" histories stay separate, so neither hides the other's new jobs.
- First run emits a baseline of current postings (or skip the baseline and start clean).
- Later runs emit only changes, so you pay for signal, not for re-scraping the same board.
- State is per-actor, and
resetMonitoringStateclears it when you want a fresh baseline.
This is the difference between a one-off export and a standing hiring-signal feed.
🎯 Use cases
| Who | What they do with it |
|---|---|
| Recruiters & sourcing teams | Monitor which companies hire for which stacks across India's tech hubs. |
| Lead generation | Companies actively hiring are companies actively buying — enriched with emails, each row is an outreach-ready lead. |
| Job boards & aggregators | Clean structured rows with stable ids for deduplicated ingestion. |
| Market & salary researchers | Skill demand by city and company size over time. |
| Founders & analysts | Track competitor hiring as a growth signal, with founding year and headcount context built in. |
📥 Supported inputs
| Input | Example |
|---|---|
| Skills / keywords / job function | python, react, data science, product manager, sales |
| City (one or many) | bangalore; or several at once: ["bangalore", "pune", "gurgaon"] |
| Remote only | roles listed under Work From Home |
| Listing URLs | https://www.instahyre.com/python-jobs-in-bangalore/ |
| Job detail URLs | https://www.instahyre.com/job-439825-backend-engineer-at-biopeak-bangalore/ |
Not supported: candidate-side pages behind login, applying to jobs, and non-instahyre.com domains.
⚙️ Input parameters
| Field | Type | Default | Notes |
|---|---|---|---|
searchQueries | array | ["python"] | One search walk per skill or keyword |
jobFunctions | array | [] | Free-text function search (product manager, sales, devops); merged with searchQueries |
jobFunctionSlugs | array | [] | Instahyre slugs bound server-side (backend-development, data-science-machine-learning). Unknown slugs are skipped, not guessed |
city | string | — | Single city; applied to row content (see FAQ) |
cities | array | [] | Several cities at once — a job in ANY of them passes. API alias: locations |
remoteOnly | boolean | false | Work From Home roles only |
monitoringMode | boolean | false | Only return jobs not seen on previous runs |
emitBaseline | boolean | true | First monitor run: true returns all current matches; false seeds silently and emits only later-new jobs |
includeUnchanged | boolean | false | Monitoring: also re-emit already-seen jobs whose fields did not change, tagged unchanged |
includeRemoved | boolean | false | Monitoring: after a completed uncapped scan, emit billed removed stubs for ids missing since the last complete scan |
diversityEmployersOnly | boolean | false | Keep only employers Instahyre flags with a diversity-hiring badge |
companyNames | array | [] | Exact Instahyre name first (companies=), then partial scan on a miss |
trackCompanies | array | [] | Hiring-tracker mode: one row per exact company, not a job list |
monitorStateName | string | — | Name a watch to run several independent monitors from one account. API alias: stateName |
maxPages | integer | — | Cap the crawl at N pages per search term (~35 jobs each); maxItems still caps billed rows |
startUrls | array | [] | Listing or job URLs; override the search fields |
enrichEmails | boolean | false | Employer email discovery, billed per found email |
maxItems | integer | 1000 | Hard cap on billed rows |
proxy | object | direct | Direct works; residential fallback kicks in on retries automatically |
📦 Output sample
Real row from a live run:
Rows follow the portfolio-wide canonical job shape (same field names as the CutShort, Naukri and RemoteOK scrapers), so multi-source pipelines map one column layout across all of them.
🔑 Output fields
Every job row carries these fields (missing values come back null, never guessed):
| Field | What it is |
|---|---|
jobId | Stable Instahyre job id — use it as the dedup key |
title | Job title |
jobUrl / applyUrl | Listing URL and where to apply |
applyType | internal (apply on Instahyre) or external |
companyName | Hiring company |
location / remote | City, and whether the role is Work From Home |
skills | Array of the stack the role asks for |
companyTagline | One-line company positioning |
companyFounded | Founding year — a maturity signal |
companyEmployeeCount | Headcount — segment startups vs enterprises |
companyDescription | Full company blurb |
companyImage | Logo URL |
acceptsOutstationCandidates | Whether non-local applicants are considered |
candidateTitle | Instahyre's candidate-facing title when it differs from title |
isDiversityEmployer | Employer carries Instahyre's diversity-hiring badge |
isFeaturedEmployer | Employer carries Instahyre's featured badge |
contentHash | Fingerprint of title / skills / location / company used for updated detection |
contactEmail | Employer email (only when enrichEmails is on and one is found) |
changeType | In monitoring mode: new, updated (public fields changed), unchanged (only with includeUnchanged), or removed (only with includeRemoved after a complete scan) |
scrapedAt | ISO timestamp of the run |
Every search run also writes MARKET_SNAPSHOT to the run's key-value store: live facet counts (total jobs, top companies, top locations, function mix, company-size and job-type splits) for the filters you used. That record is not a dataset row and is not billed.
Coming from another Instahyre scraper?
| You asked for | getascraper / themineworks | This actor |
|---|---|---|
| Server-side function slugs | jobFunctionSlugs | Same key, resolved against Instahyre's live catalog |
| Diversity-employer filter | diversityEmployersOnly | Same, from the list payload badge |
| New / updated / removed | monitorMode: changes_only | monitoringMode + updated always; includeRemoved opt-in so existing schedules are not surprise-billed |
| Market facet snapshot | KV MARKET_SNAPSHOT | Same key, not billed |
| Company hiring tracker | trackCompanies | Same key — one billed row per exact employer (open-role count, location/skill mix, deltas). Other search filters are ignored |
| Exact company-name lookup | companyNames hits companies= first | Same: recognised names bind server-side; unrecognised names fall back to a partial scan |
| Recruiter / agency / experience | includeDetails / excludeAgencyPosted | Public list, job JSON and JSON-LD do not publish those fields; we do not invent them |
locations / stateName / maxJobs / proxyConfiguration | Their key names | Accepted as aliases; cities, monitorStateName, maxItems, proxy stay the published keys |
The company fields are what most job scrapers drop — they turn a job feed into a company-intelligence feed you can segment by size, age and stack.
❓ FAQ
Can I get a daily feed of only new jobs?
Yes — that's monitor mode. Turn on monitoringMode, put the actor on an Apify schedule, and each run returns only postings that appeared since the last one. See the Hiring Monitor section above.
How do I watch one company's hiring instead of a job list?
Pass exact Instahyre names in trackCompanies (the spelling from a MARKET_SNAPSHOT topCompanies row). The run returns one billed row per company: open-role count, location mix, skill mix, and new/closed job ids versus the last run. Unknown names are skipped and not billed.
What if I type a company name Instahyre does not recognise?
companyNames tries Instahyre's exact companies= token first. A miss ({"companies":["Invalid company"]}) falls back to a partial match on the scanned pages. trackCompanies does not fall back — it skips the unknown name.
How does the city filter work if the API ignores location parameters?
The skill filter narrows the walk server-side; the city/remote filters then keep only rows whose location matches, on our side. Skipped rows are never billed. The trade-off: a very narrow city in a broad skill can take a few extra unbilled pages to fill your maxItems. Pass several cities in cities to widen the net — a job in any of them passes.
Can I search by job function, not just a skill?
Two ways. jobFunctions / searchQueries are free text (product manager, sales) and walk the skill index. jobFunctionSlugs uses Instahyre's own ids (backend-development) and is the filter the API actually applies server-side — verified: job_functions=1 drops the board from ~13.6k to the matching function. Unknown slugs are skipped with a warning.
Can I run more than one saved monitor?
Yes — give each watch its own monitorStateName. Each name keeps an independent "already seen" history, so a bangalore-eng schedule and a remote-sales schedule never mask each other's new jobs.
Does it include salary? Instahyre's public API does not expose salary on listings, so there is no salary column pretending otherwise.
What does enrichEmails cost?
It is billed as an additional-data event only on rows where an email was actually found — see the pricing tab. Discovery uses the company name plus a business-match guard, so unrelated domains are rejected rather than guessed.
Do I need a proxy? No. Instahyre's Cloudflare passes browser-grade TLS from a direct connection; the retry ladder adds residential automatically if a request struggles.
💬 Support
Open an issue on the actor's Issues tab in Apify Console — answered within 1–2 business days.
🛠 Additional services
Scheduled hiring-signal feeds, multi-board merges (Instahyre + CutShort + Naukri), or delivery straight to your CRM — custom builds available, contact me through the actor page.
🔎 Explore more scrapers
Same developer, same canonical row shape: CutShort Jobs, Naukri, RemoteOK, Remote Jobs Aggregator — full portfolio at memo23 on Apify Store.
🤖 For AI Agents & LLM Apps
Stable, typed JSON with a type discriminator and canonical field names shared across the whole jobs family — an agent that learns one scraper's shape can drive them all. Skill search maps cleanly to tool calls; keep maxItems low per call for cost control.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Instahyre or its operators. All trademarks are the property of their respective owners. The scraper accesses only publicly available listing data — no login, no candidate profiles, no private information. Users are responsible for compliance with Instahyre's Terms of Service, applicable data-protection law (GDPR, DPDP Act, CCPA), and their own organisation's obligations, particularly when using contact enrichment for outreach.
SEO Keywords
instahyre scraper, instahyre jobs scraper, india tech jobs scraper, india hiring monitor, hiring signals india, new job postings tracker india, instahyre jobs api, scrape instahyre, bangalore startup jobs data, india hiring data, instahyre company data, tech recruitment leads india, jobs api india, startup hiring signals india, who is hiring india, apify instahyre, india jobs by function, product manager jobs india, data science jobs india, multi city job search india, bangalore pune hyderabad jobs, engineering jobs india scraper, sales jobs india data


