
Ouest-France Scraper
Pricing
from $1.00 / 1,000 results
Ouest-France Scraper
Scrape news articles from ouest-france.fr — title, lead, full body, author, dates, categories, photos, paywall status, and reading time. Accepts search URLs, article URLs, or free-text queries. Mobile JSON API, no proxy needed. JSON or CSV out.
Pricing
from $1.00 / 1,000 results
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Share
Scrape news articles from ouest-france.fr — France's largest regional newspaper — and export them as structured JSON. Paste a search URL, a direct article URL, or a free-text query, and get titles, leads, full body text, authors, dates, categories, photos, and paywall status for every article. No headless browser, no proxy, no anti-bot to fight: the actor talks to Ouest-France's own mobile JSON API directly.
How it works
✨ Why use this scraper?
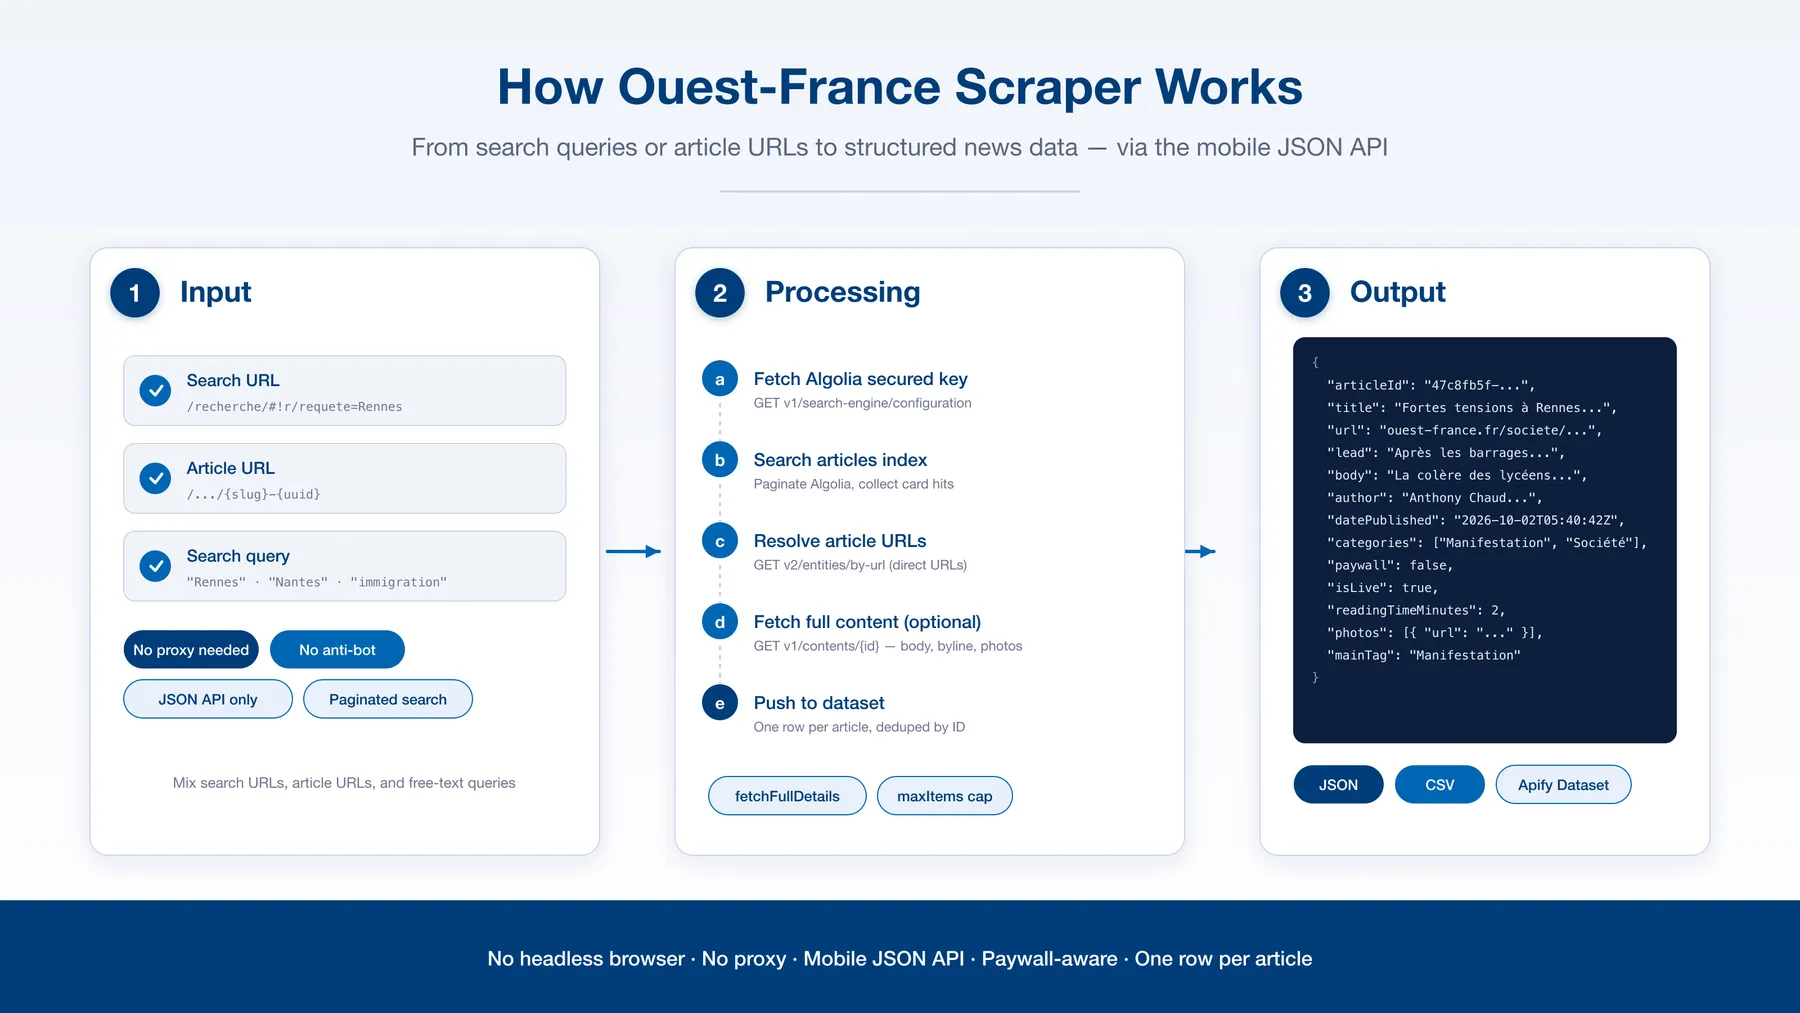
- Mobile JSON API, not a headless browser. The ouest-france.fr website sits behind Akamai bot protection (returns 403 to plain HTTP). The Android app's API has no such wall — the actor fetches a short-lived Algolia key, searches the articles index, and pulls full content in three clean JSON calls. Faster, cheaper, and more reliable than rendering pages.
- Search or direct URLs. Run a free-text query ("Rennes", "immigration", "Nantes"), paste a recherche URL, or drop in individual article URLs. All three work and can be mixed in one run.
- Full article body, not just cards. Toggle
fetchFullDetailsto pull the complete article text (assembled from the content API's structured body blocks), byline, reading time, and all photos — or leave it off for fast card-only harvests. - Paywall-aware. Each row carries a
paywallflag andarticleType. Paywalled articles (CONTENU_PAYANT) return their lead only; free articles return the full body. No pretending paywalled content is free. - One row per article, deduped. No padding rows. If the same article shows up in two search queries, it appears once.
- No proxy required. The mobile API returns 200 with a plain User-Agent. Run direct and save the proxy budget.
🎯 Use cases
| Audience | What they do with it |
|---|---|
| News monitors | Track coverage of a topic, region, or event across Ouest-France's archive (1.4M+ articles searchable) |
| Media analysts | Build datasets of headlines, leads, and publication dates for trend analysis |
| Data journalists | Harvest regional news (Bretagne, Rennes, Nantes) for investigation or archive |
| NLP / LLM pipelines | Feed structured article text (title, lead, body, categories) into models for summarization or classification |
| Content archivists | Snapshot articles with full body, author, and photo metadata before they change |
📥 Supported inputs
| Input type | Example | What happens |
|---|---|---|
| Search URL | https://www.ouest-france.fr/recherche/#!r/requete=Rennes&onglet=actualites | Query extracted from the hash fragment, run against the articles index |
| Article URL | https://www.ouest-france.fr/bretagne/rennes-35000/...-48996954-bdb4-11f1-81a4-4fea3020cab7 | Resolved to full content via the by-url endpoint |
| Free-text query | searchQueries: ["Rennes", "immigration"] | Each query paginated through the Algolia articles index |
Not supported: Ouest-France e-paper editions (feuilleteur), real estate listings (ouest-france.immo), funeral notices (avis-de-deces), and content behind a subscriber login.
🔄 How it works
- The actor fetches a short-lived Algolia secured key from the search-engine configuration endpoint.
- For each search query, it paginates the
articlesAlgolia index (50 hits per page), collecting card metadata. - Direct article URLs are resolved via the
v2/entities/by-urlendpoint to full content. - If
fetchFullDetailsis on, each card is enriched with av1/contents/{id}call for the full body, byline, photos, and paywall status. - Results are deduped by article ID and pushed to the dataset, one row per article.
⚙️ Input parameters
| Field | Type | Default | Description |
|---|---|---|---|
startUrls | array | ["https://www.ouest-france.fr/recherche/#!r/requete=Rennes&onglet=actualites"] | Ouest-France search URLs and/or direct article URLs. Auto-classified. |
searchQueries | array | [] | Free-text queries to run against the articles index. Alternative to search URLs. |
fetchFullDetails | boolean | false | Open each article for the full body, byline, photos, and paywall status. |
maxItems | integer | 100 | Hard cap on articles. Free-plan users are capped at 5. |
maxConcurrency | integer | 10 | Parallel article-detail fetches (only when fetchFullDetails is on). |
proxy | object | { "useApifyProxy": false } | The mobile API has no anti-bot, so a proxy is usually unnecessary. |
📊 Output overview
Each dataset row is one Ouest-France article. Card-only runs (the default) return title, lead, url, date, categories, source, paywall flag, type, and photo counts. With fetchFullDetails on, each row also carries the full body text (plain + HTML), author, all publication dates, reading time, main tag, geo zones, and photo URLs.
📦 Output sample
🗂 Key output fields
| Field | Description |
|---|---|
articleId | Ouest-France article UUID (the Algolia objectID) |
title | Article headline |
url | Full ouest-france.fr article URL |
lead | Article lead paragraph (chapeau) |
body | Full article text, HTML stripped (only with fetchFullDetails) |
bodyHtml | Full article body as HTML (only with fetchFullDetails) |
author | Byline / signature (only with fetchFullDetails) |
datePublished | Publication date (ISO 8601) |
firstPublicationDate | First publication timestamp (only with fetchFullDetails) |
lastPublicationDate | Last publication timestamp (only with fetchFullDetails) |
lastUpdatedDate | Last update timestamp (only with fetchFullDetails) |
categories | Topic categories (e.g. Société, Éducation) |
source | Content source (usually of for Ouest-France) |
paywall | true if the article is behind a paywall (CONTENU_PAYANT) |
articleType | Article type (GENERAL, LOCAL, CONTENU_PAYANT, live, etc.) |
isLive | true for live-blog articles |
photos | Array of photo objects with url, credit, caption |
nbPhotos / nbVideos | Media counts |
readingTimeMinutes | Estimated reading time (only with fetchFullDetails) |
mainTag | Primary tag (only with fetchFullDetails) |
zonesGeo | Geographic zones the article covers |
fetchedFullDetails | Whether full content was fetched for this row |
❓ FAQ
Why does the actor use the mobile API instead of scraping the website? The ouest-france.fr website is behind Akamai bot protection and returns 403 to non-browser HTTP clients. The Android app's JSON API has no such protection and returns the same data in a cleaner, structured format. This makes the actor faster, cheaper, and more reliable than a headless-browser approach.
Why are some article bodies short?
Articles marked CONTENU_PAYANT (paywall: true) are behind Ouest-France's subscriber paywall. The API returns only the lead paragraph for these, not the full body. Free articles return the complete text. The paywall and articleType fields tell you which is which.
Do I need a proxy? No. The mobile JSON API returns 200 with a plain User-Agent. A proxy is only useful if you need to mask your IP for volume reasons, not for access.
How many articles can I scrape?
The Algolia articles index holds over 1.4 million articles. maxItems caps each run. Free-plan users are capped at 5 articles per run.
Can I search for articles by date or region?
The free-text query supports whatever Algolia search syntax Ouest-France exposes. Geographic filtering comes through the zonesGeo field on each result. For date filtering, sort by datePublished in post-processing.
💬 Support
Found a bug or want a feature? Open an issue on the Apify Console and we'll take a look.
🛠 Additional services
Need a custom integration, a specific filter, or a larger volume? Reach out via the Apify Console — we build tailored scraping pipelines on request.
🔎 Explore more scrapers
Looking for other news or directory scrapers? Check the full portfolio on Apify.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Ouest-France, SIPA Ouest-France, or any of their subsidiaries or affiliates. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly available article data via Ouest-France's mobile API — no authenticated endpoints, subscriber-only content, or content behind a login. Paywalled articles return only their publicly visible lead paragraph. Users are responsible for ensuring their use complies with Ouest-France's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organisation.
SEO Keywords
ouest-france scraper, scrape ouest-france, ouest-france api, apify ouest-france, ouest-france news scraper, french news scraper, ouest-france article extractor, ouest-france search scraper, regional press scraper, bretagne news scraper, rennes news scraper, nantes news scraper, ouest-france algolia, ouest-france json api, news article archive scraper, french regional news data, ouest-france headlines scraper, ouest-france content scraper, ouest-france data extraction, ouest-france crawler


