
SimplyHired Jobs Scraper [$0.9/1K 💰] Salaries & Companies
Pricing
from $0.70 / 1,000 result (one job)s
SimplyHired Jobs Scraper [$0.9/1K 💰] Salaries & Companies
Turn SimplyHired into structured US hiring data. Structured salaries, real map coordinates, employer ratings, and full descriptions from any search URL — job type, min-pay, and recency filters included. Expired listings skipped automatically. JSON or CSV out, billed per result.
Pricing
from $0.70 / 1,000 result (one job)s
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
63
Total users
16
Monthly active users
5 days ago
Last modified
Share
SimplyHired Jobs Scraper
Turn SimplyHired into structured US hiring data — with salary numbers and map coordinates on every row. Scrape every job from any SimplyHired search URL — title, employer (with star rating and logo), location with real lat/lng, structured salary (min/max/unit/currency), qualifications, benefits, job types, posted date, and the full HTML description — pulled from SimplyHired's own JSON data routes. JSON or CSV out, billed per result.
How it works
✨ Why use this scraper?
- Structured salary on most rows —
min/max/unit/currencyparsed by SimplyHired itself, not regexed from text. - Real map coordinates — latitude/longitude on every located job, ready for radius filters and mapping.
- Employer ratings — each job carries the company's SimplyHired star rating, logo, and company-page URL.
- JSON data routes, not HTML scraping — fields come from the site's own framework payloads, so they don't break when the layout changes.
- No proxy cost — the scraper's TLS fingerprinting passes SimplyHired's Cloudflare gate without residential proxies (a fallback is built in).
- Expired listings skipped automatically — you're never billed for dead jobs; stale search results are detected at the detail step and dropped.
🎯 Use cases
| Who | What they do with it |
|---|---|
| Recruitment agencies | Monitor open roles by metro, title, and pay band across the US |
| HR / comp & ben teams | Benchmark real posted salary ranges by title and city |
| Job aggregators | Ingest deduplicated structured postings with stable job keys |
| Market researchers | Track hiring volume and wage trends over time (date-added filters built in) |
| Sales / lead-gen teams | Find companies actively hiring — with optional contact-email enrichment |
| Data scientists | Geo-coded, salary-labelled job records for modelling |
📥 Supported inputs
| Input | Example | What happens |
|---|---|---|
| Search URL | https://www.simplyhired.com/search?q=nurse&l=Chicago%2C+IL | Walks the full result set via cursor pagination |
| Search with filters | /search?q=driver&l=Dallas%2C+TX&t=7&jt=CF3CP&mip=50000 | All filter params pass through (days since added, job type, min pay, sort). Old links are translated: fdb=N to t=N, and a job-type word such as t=fulltime to its jt= code |
| Canadian search URL | https://www.simplyhired.ca/search?q=nurse&l=Toronto%2C+ON | simplyhired.ca works the same way, and one run can mix .com and .ca URLs |
| Remote search | /search?q=developer&l=Remote | Location accepts "Remote" like the site does |
| Direct job URL | /job/{jobKey} | Scraped as a single job |
| Keyword + location fields | keyword: "accountant", location: "New York, NY" | Used when Start URLs is empty |
Not supported: company browse pages (/browse-jobs/companies/…) as start URLs, and features behind a SimplyHired/Indeed login.
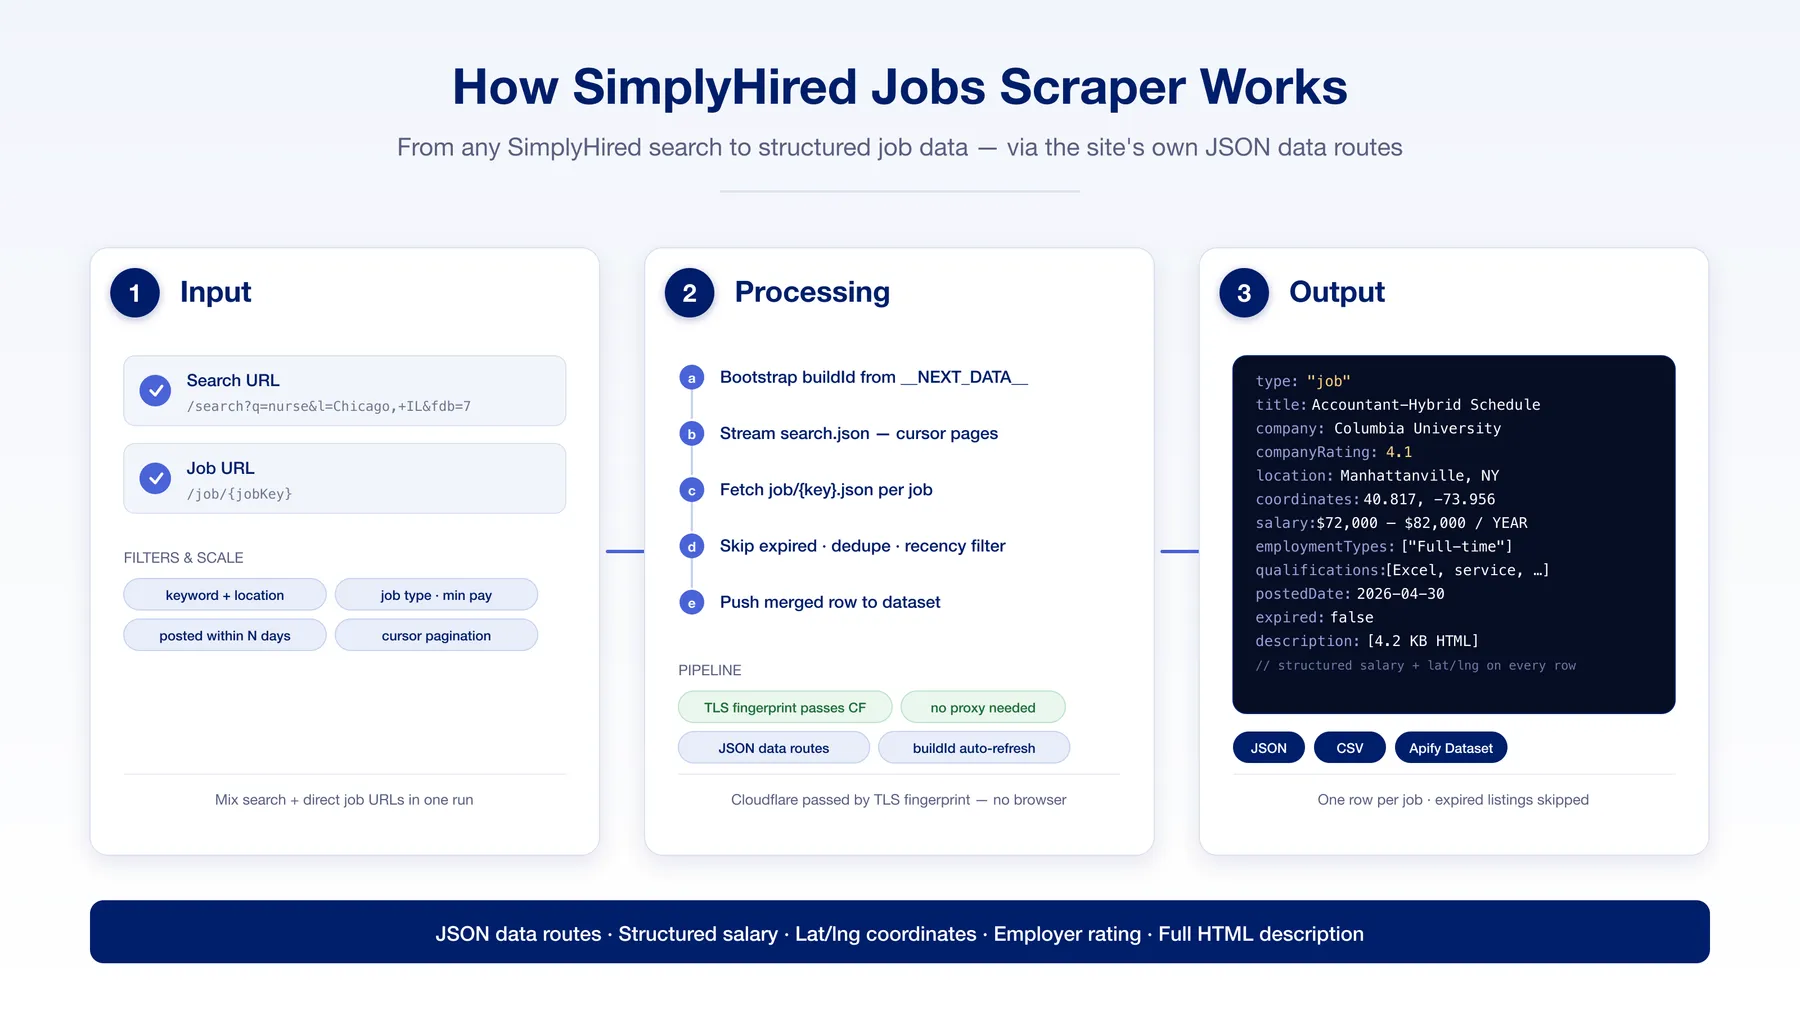
🔄 How it works
- Bootstrap — one page fetch reads SimplyHired's
__NEXT_DATA__blob: the currentbuildId, locale, and page 1 of results come free. - Stream the search data route — 20 jobs per page, cursor-based pagination; details start processing while later pages are still being fetched.
- Fetch each job's detail JSON — description HTML, structured salary, coordinates, qualifications, employer rating, dates, flags.
- Skip expired listings and duplicates, apply the optional recency filter.
- Push one merged row per job — capped exactly at
maxItems. If the site deploys mid-run, thebuildIdis refreshed automatically.
⚙️ Input parameters
| Field | Type | Default | Description |
|---|---|---|---|
startUrls | array | ["https://www.simplyhired.com/search?q=accountant&l=New+York%2C+NY"] | Search and/or direct job URLs |
keyword | string | — | Keyword search; used when startUrls is empty |
location | string | — | Location (city/state, zip, or "Remote"); used when startUrls is empty |
postedWithinDays | integer | — | SimplyHired's own date-added filter, any 1–30 days; used when startUrls is empty |
jobType | string | — | Full-time, part-time, contract, temporary, internship and more; used when startUrls is empty |
country | string | auto | us searches simplyhired.com, ca searches simplyhired.ca; auto picks Canada when the location is Canadian ("Toronto", "Guelph, ON", "Canada"); used when startUrls is empty |
fetchJobDetails | boolean | true | Fetch full detail per job (description, salary, coordinates, rating) |
enrichEmails | boolean | false | Experimental employer contact-email discovery |
postedWithinHours | integer | — | Finer-grained filter on when each job was added to SimplyHired (dateOnIndeed) |
maxItems | integer | 1000 | Hard cap on jobs collected |
maxConcurrency | integer | 10 | Parallel detail requests |
proxy | object | none | Usually not needed — honoured as an explicit override only |
📊 Output overview
Each dataset row is one job with everything merged inline: stable jobId (SimplyHired's job key), employer block (name, rating, logo, company-page URL), location with coordinates, structured + raw salary, qualifications and benefits chips, both description formats, ISO dates, and status flags (expired, sponsored, isIndeedApply). Fields the source doesn't provide are null — columns never disappear between rows.
📦 Output sample
🗂 Key output fields
| Group | Fields |
|---|---|
| Identity | jobId (stable job key), jobUrl, title, normalizedTitle |
| Employer | companyName, companyRating, companyProfileUrl, logoUrl |
| Location | location, addressLocality, addressRegion, coordinates.{latitude,longitude}, remote |
| Compensation | salary.{currency,min,max,unit,raw} (structured), salaryRaw |
| Classification | employmentTypes, workSettings, qualifications[], benefits[], requirements[] (search-card chips), skillTags[] |
| Dates | postedDate, dateOnIndeed, closingDate (ISO-8601) |
| Content | description (HTML), descriptionText (plain), snippet |
| Flags | expired, sponsored, isIndeedApply |
❓ FAQ
Do I need a proxy? Usually not. The scraper's browser-grade TLS fingerprinting passes SimplyHired's Cloudflare check directly, and a residential fallback engages automatically on retries. A user-supplied proxy is honoured as an override.
Does it return the employer's direct apply link?
No — SimplyHired routes applications through a session-bound redirect that can't be reliably resolved server-side. applyUrl is the canonical SimplyHired job page (one click from the real form), and isIndeedApply tells you when the job uses Indeed's apply flow. If a resolved ATS URL matters to you, check the eFinancialCareers actor pattern or email for a custom build.
Why did I get slightly fewer rows than maxItems?
Search results can include listings that expired minutes ago. Those are detected at the detail step and skipped (logged as skipped in the run stats) rather than pushed as junk rows.
Can I filter by job type, minimum pay, or recency?
Yes — either set the filters on simplyhired.com and paste the resulting URL (t=7 for days since added, mip=50000 for minimum pay, jt=… for job type), or use the postedWithinDays, postedWithinHours and jobType inputs.
What happens when SimplyHired deploys a new site version mid-run?
The data routes briefly 404; the scraper detects this, re-reads the new buildId, and continues — you'll see buildIdRefreshes in the stats.
💬 Support
- For issues or feature requests, please use the Issues tab on the actor's Apify Console page.
- Author's website: https://muhamed-didovic.github.io/
- Email: muhamed.didovic@gmail.com
🛠 Additional services
- Custom output shape, additional fields, or one-off datasets: muhamed.didovic@gmail.com
- Need a similar scraper for other job boards (eFinancialCareers, TotalJobs, CharityJob, s1jobs, etc.)? Drop an email.
- For API access (no Apify fee, just a usage fee for the API): muhamed.didovic@gmail.com
🔎 Explore more scrapers
If this SimplyHired Scraper was useful, see other scrapers and actors at memo23's Apify profile — covering job boards, real estate, social media, and more.
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/simplyhired-jobs-scraper).
Purpose: Scrapes US job postings from SimplyHired search or job URLs — one row per job with structured salary (min/max/unit/currency), map coordinates, employer rating, and full HTML description pulled from SimplyHired's own JSON data routes.
Minimal input:
Keyword mode (used when startUrls is empty): { "keyword": "accountant", "location": "New York, NY", "maxItems": 50 }
Output: one row per job — type, source, jobId, jobUrl, title, normalizedTitle, companyName, companyRating, companyProfileUrl, logoUrl, location, addressLocality, addressRegion, coordinates {latitude, longitude}, remote, salary {currency, min, max, unit, raw}, salaryRaw, employmentTypes, workSettings, qualifications[], benefits[], requirements[], skillTags[], postedDate, dateOnIndeed, closingDate, description (HTML), descriptionText, snippet, expired, sponsored, isIndeedApply, applyType, applyUrl, scrapedAt. With enrichEmails on: contactEmail, contactWebsite, emailEnrichment.
Behaviors an agent should know:
- startUrls takes priority; keyword/location/postedWithinDays/jobType/country only apply when startUrls is empty. postedWithinDays accepts any 1–30 days.
- Canada: simplyhired.com lists almost no Canadian jobs, so a Canadian location (or country "ca") searches simplyhired.ca. simplyhired.ca start URLs work too.
- Always set maxItems — the default cap is 1000 jobs.
- fetchJobDetails (default true) fetches description, structured salary, coordinates and employer rating per job; set false for search-card fields only.
- postedWithinHours filters on when each job was added to SimplyHired (dateOnIndeed); it works with or without fetchJobDetails.
- No proxy needed — TLS fingerprinting clears SimplyHired's Cloudflare gate, with a residential fallback built in. Company browse pages and login-gated fields are unsupported; expired listings are skipped and never billed.
- Pay-per-event billing (per result) — see the Pricing tab on the actor page.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by SimplyHired, Indeed, Recruit Holdings, or any of their subsidiaries or affiliates. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly available job listings and the public JSON payloads that power the SimplyHired website — no authenticated endpoints, candidate data, or content behind a SimplyHired or Indeed login. Users are responsible for ensuring their use complies with SimplyHired's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organisation.
SEO Keywords
simplyhired scraper, scrape simplyhired, simplyhired api, simplyhired jobs scraper, Apify simplyhired, us jobs scraper, job postings api, job listings scraper, salary data scraper, posted salary benchmark, jobs with coordinates api, geo-coded jobs data, employer rating data, us hiring trends, recruitment data scraper, job market research data, indeed alternative scraper, ziprecruiter alternative scraper, glassdoor alternative scraper, job board scraper, job aggregator data feed


