
Zhihu Scraper 知乎 [Only $3] Answers, Comments, Search 回答 评论 搜索
Pricing
from $3.00 / 1,000 rows
Zhihu Scraper 知乎 [Only $3] Answers, Comments, Search 回答 评论 搜索
[Only $3 per 1000 rows] Zhihu (知乎) scraper, no login: 搜索 search sorted by newest or most upvoted with date and type filters, search suggestions, questions with 回答 answers and 评论 comments, user profiles, 热榜 hot list, columns and articles.
Pricing
from $3.00 / 1,000 rows
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
17
Total users
17
Monthly active users
7 hours ago
Last modified
Categories
Share
Zhihu Scraper: Questions, Answers, Search, Columns & Articles
Question threads with answers and comments, keyword search, people, the hot list, and public columns and articles, as JSON or CSV. No Zhihu login.
Zhihu shows questions, answers and search only to logged-in visitors. This actor returns them without a login or a cookie, alongside the public column and article pages it has always read.
$3 per 1,000 rows, plus a $0.005 start fee.
Why Use This Scraper?
- No login. Questions, answers, comments, search and profiles come back without a cookie.
- Whole threads. A question returns its detail and its answers, 20 a page, each with upvotes, comments and the author; comments and replies on request.
- Four searches. Content (answers, articles, questions), people, topics and columns.
- Search filters like on Zhihu itself. Sort by newest (最新发布) or most upvoted (最多赞同), keep to the last day, week, month, 3 or 6 months or year, and pick answers, articles or videos only.
- Search suggestions. Zhihu's own suggestions for each keyword, for keyword research.
- People. A profile with follower and post counts, plus that person's answers, articles, pins, followers or following.
- Hot list. The 30 questions on 热榜 with their heat.
- Columns and articles with the HTML body. A column list carries the longer HTML of each article.
- One price. Every row costs the same, and
maxItemscaps the whole run.
Overview
Rows are told apart by type: question, answer, comment, reply, user, topic, column, pin, hot-question, and the article rows the actor has always returned.
A column URL such as https://zhuanlan.zhihu.com/xuehy pages through that column's public item list. An article URL such as https://zhuanlan.zhihu.com/p/2084570146228664180 fetches that article on its own; that path also returns topics, with a shorter HTML body than the same article inside a column list.
Supported Inputs
| Input | What you get |
|---|---|
https://zhuanlan.zhihu.com/{slug} | Every article in that column, up to maxItems |
https://www.zhihu.com/column/{slug} | Same column list |
Column slug, e.g. xuehy | Same column list |
https://zhuanlan.zhihu.com/p/{id} | One article |
| Numeric article id | One article |
Copy-paste column run:
Question, answer and profile links work in startUrls too:
| Input | What you get |
|---|---|
https://www.zhihu.com/question/{id} | The question and its answers |
https://www.zhihu.com/question/{id}/answer/{id} | One answer |
https://www.zhihu.com/people/{token} | The profile, plus the lists chosen in userContent |
Keywords in searchKeywords, peopleKeywords, topicKeywords, columnKeywords | Search results, 20 a page |
Question thread with comments:
Not supported: https://www.zhihu.com/search?q=... links. Put the keyword in searchKeywords instead.
Use Cases
| Who | What they do with the rows |
|---|---|
| Research | Read a columnist's public essays without clicking through each post |
| Media monitoring | Track a named column for new titles, votes and comment counts |
| Market notes | Pull Chinese-language commentary on a topic a column already covers |
| Archives | Save the public HTML of articles you can already open in a browser |
| Agents | Hand a column URL to an Apify call and read a flat article list |
How It Works
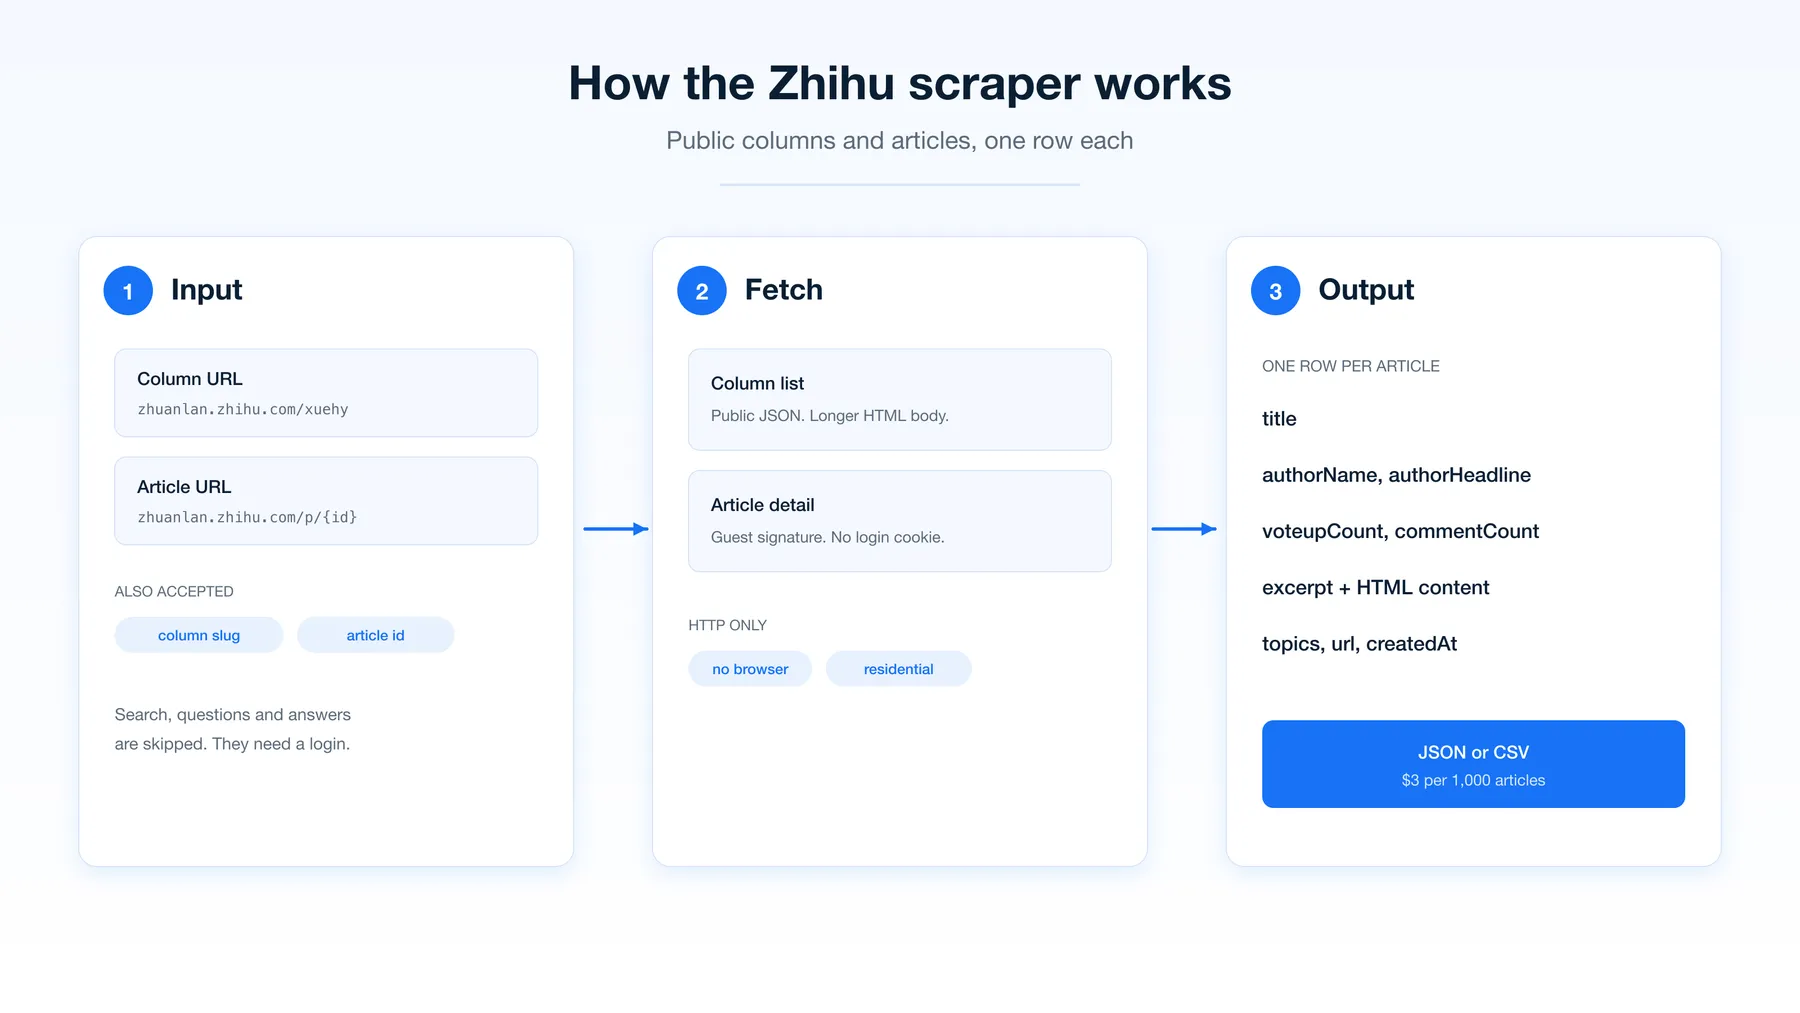
- You pass column URLs, article URLs, slugs or numeric ids.
- Each value is classified: column, article, question, answer or profile.
- A column is read from Zhihu's public column-items API, page by page, until
maxItemsor the last page. - An article id that did not already come from a column is fetched from the public article API.
- Questions, answers, comments, search, people and the hot list are read from a data source that needs no login.
- Each result is pushed as one dataset row. On Apify, that row is the billed result.
Pure HTTP. No browser.
Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
startUrls | string[] | no | Column and article URLs. Prefill: https://zhuanlan.zhihu.com/xuehy. If every list is empty, that column is used. |
columnIds | string[] | no | Slugs such as xuehy. |
articleIds | string[] | no | Numeric ids such as 2084570146228664180. |
questionUrls | string[] | no | Question links or ids. Each returns the question and its answers. |
maxAnswersPerQuestion / answerOrder | integer / string | no | Default 20; default ranking or updated (newest first). |
answerUrls | string[] | no | Single answers by link or id. They carry text and author; vote counts come with question threads and search. |
includeComments / maxCommentsPerAnswer | boolean / integer | no | Comment rows for every answer in the run. Default 20 per answer. |
includeReplies | boolean | no | Reply rows under each comment, up to 20 per comment. |
searchKeywords | string[] | no | Content search: answers, articles and questions. |
peopleKeywords / topicKeywords / columnKeywords | string[] | no | People, topic and column search. |
searchSort | relevance | upvoted | newest | no | Order of content search results. Default relevance. |
searchTimeRange | all | day | week | month | three_months | half_year | year | no | Publishing window for content search. |
searchContentType | all | answer | article | video | no | Content search: only this type. |
includeSearchSuggestions | boolean | no | One search-suggestion row per Zhihu suggestion for each searchKeywords entry. |
maxResultsPerKeyword | integer | no | Default 20. |
users | string[] | no | Profile links or url tokens. |
userContent / maxItemsPerUser | string[] / integer | no | answers, articles, pins, followers, following; default 20 rows per list. |
includeHotList | boolean | no | The 30 questions on the hot list. |
maxItems | integer | no | Default 20. Cap on all rows of the run. Free plans cap at 100. |
maxConcurrency | integer | no | Default 5. Range 1–20. Applies to article-detail calls. Column pages stay sequential. |
Column, 5 articles
One article
Column plus one extra article
The column list is collected first. An article id already present in that list is not fetched a second time.
Output Overview
Rows are told apart by type. Article rows from columns and article links are as before: there is no separate column row and no padding row, and the column name is the slug on each article (columnSlug).
An answer row has answerId, url, questionId, questionTitle, text, html, upvotes, comments, favorites, createdAt and the author. A question row has title, detail, answerCount, followerCount, viewCount. A comment or reply row has text, likes, replyCount, ipLocation, parentCommentId. A user row has urlToken, name, headline, followers, answers, articles, ipLocation. A hot-question row adds rank, heat and heatValue.
source is column when the row came from a column list, and article when it came from the article endpoint. Column rows carry the longer HTML. Article rows add topics when Zhihu sends them. contentTruncated follows Zhihu's own guest flag.
Output Samples
Column list, https://zhuanlan.zhihu.com/xuehy, first article. HTML below is cut for the README. The live row's content was 3,015 characters.
The same id fetched as an article (not via the column list) returned content of 769 characters, excerpt of 128 characters, and topics A股(人民币普通股票) and 股票交易策略. Author, votes and comment count matched.
Key Output Fields
Identity
articleId,url,entityType(article),source(columnorarticle)columnSlugwhen the article belongs to a column
Text
title,excerpt,content(HTML)contentTruncated— Zhihu's guest flag. Atruevalue can still sit on a multi-thousand-character column body.
Author
authorName,authorHeadline,authorId,authorUrl
Engagement
voteupCount,commentCounttopics— filled on article-detail rows when Zhihu sends them. Column-list rows in the sample above had an empty list.
Media and time
imageUrlcreatedAt,updatedAt— ISO timestamps
FAQ
Does it search Zhihu?
Yes. Put keywords in searchKeywords (content), peopleKeywords, topicKeywords or columnKeywords. Questions, answers and comments are returned too, all without a login.
Why do answers given by link have no vote counts? Zhihu's single-answer response carries the text and the author only. Read the question thread, or search, to get upvotes, comments and favorites.
What does a column run actually request?
GET https://www.zhihu.com/api/v4/columns/{slug}/items?limit=10&offset=0, then the next offset, until maxItems or Zhihu says the list is finished. Ten articles per page. Pages run one after another.
What does an article run request?
GET https://www.zhihu.com/api/v4/articles/{id} with the public fields content, excerpt, voteup_count, comment_count, author, topics and column. The request is signed as a guest. No d_c0 cookie is sent. Sending that cookie is what flips Zhihu into its click-challenge, so the actor leaves it off.
Can I mix a column and an article id? Yes. The column is walked first. If that article id already appeared in the column, it is not fetched again.
What if the slug or id is wrong? A failed column page or article is logged and counted as a failure. The rest of the run continues. A bad id does not produce a billed row, because a row is only pushed after a title comes back.
Is there a free-plan cap? On Apify, accounts that are not on a paid plan are limited to 100 articles per run. The Store's automated tester is limited to 1.
How many retries?
Each URL is tried up to 4 times, with a new proxy address each time. A login wall (40353) or an abnormal-request block (40362) stops that URL immediately. Those are not transient proxy errors.
Why is the article HTML shorter than the column HTML?
They are different Zhihu endpoints. For article 2084570146228664180 the column list returned 3,015 characters and the article endpoint returned 769. Use a column URL when you want the longer public HTML.
What does contentTruncated: true mean?
Zhihu sets that flag on guest responses. It does not mean the field is empty. Paid 盐选 bodies that Zhihu does not show to guests stay on the excerpt.
Will a question id work if I paste the number? A long numeric id is treated as an article id. Question URLs are rejected before any request.
How much does a run cost? $0.005 when the run starts, then $0.003 for each article row. Five articles cost about $0.02.
Support
- Bugs and field requests: the actor's Issues tab at memo23/zhihu-scraper.
- More actors from the same developer: apify.com/memo23.
Additional Services
Need a scheduled column feed, a different field set, or a push into a sheet or warehouse? Custom work is available through the Issues tab.
Explore More Scrapers
Same developer, same pay-per-result model:
- Quora Scraper — public Quora questions and answers
- Douyin Scraper — public Douyin posts
- The rest of the catalogue is on the memo23 Store page
🤖 For AI Agents & LLM Apps
Compact reference for agents calling this actor via the Apify MCP server or the Apify API (memo23/zhihu-scraper).
Purpose: Zhihu questions, answers, comments, search, people, hot list, and public column articles. No login.
Minimal input:
Output fields: entityType, articleId, title, excerpt, content, contentTruncated, voteupCount, commentCount, authorName, authorHeadline, authorId, authorUrl, columnSlug, imageUrl, url, createdAt, updatedAt, topics, source.
Other inputs: questionUrls, answerUrls, searchKeywords, peopleKeywords, topicKeywords, columnKeywords, users (+ userContent), includeComments, includeReplies, includeHotList. Rows carry type: question, answer, comment, reply, user, topic, column, pin, hot-question, search-suggestion. Content search takes searchSort, searchTimeRange, searchContentType.
Billing: $0.005 actor start + $0.003 per dataset row of any type.
Behavior: Column rows have the longer HTML and often empty topics. Article-detail rows are shorter and may include topics. contentTruncated can be true on a full-looking column body. maxItems caps all rows together, comments included.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Zhihu Inc. or any of its subsidiaries. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly available Zhihu column and article pages. It does not log in, and it does not collect search results, questions, answers, or content Zhihu only shows to a signed-in member. Users are responsible for ensuring their use complies with Zhihu's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organization.
SEO Keywords
Zhihu scraper, scrape Zhihu, 知乎 scraper, Zhihu question scraper, Zhihu answers scraper, Zhihu comments, Zhihu search scraper, Zhihu hot list 热榜, Zhihu user scraper, Zhihu no login, Apify Zhihu, zhuanlan articles, zhuanlan.zhihu.com scraper, column article export, Chinese essay archive, author monitoring, public HTML export, media monitoring, China commentary data, guest article body, column feed, article JSON, upvote export, research export, column archive, comment count export


