
Website Email & Contact Details Scraper: Phones, Socials
Pricing
from $7.50 / 1,000 website with contacts
Website Email & Contact Details Scraper: Phones, Socials
Email scraper and contact details extractor for company websites. One clean row per site: emails (junk filtered, MX-checked), phones, LinkedIn, Facebook, Instagram, X, YouTube, TikTok and contact page. No proxy needed. Pay only for sites with contacts.
Pricing
from $7.50 / 1,000 website with contacts
Rating
0.0
(0)
Developer

Jason
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
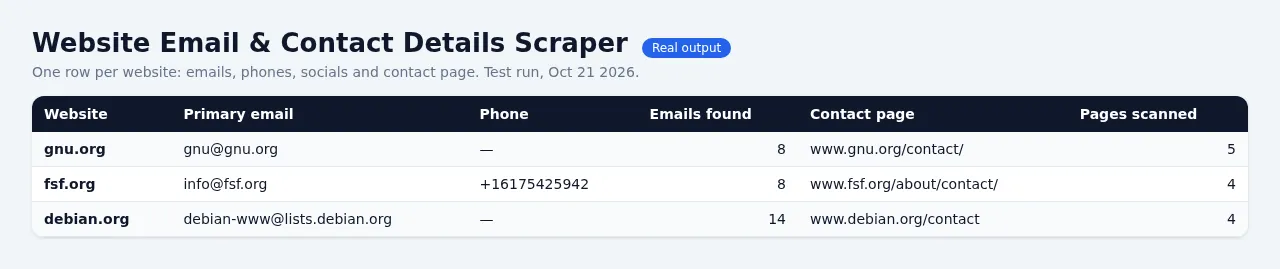
Give it a list of company websites. Get back one clean row per website, in the same order as your list, with the best email, all emails, phone numbers in international format, social profiles, contact page, company name and address. Ready for your CRM, spreadsheet or outreach tool.
- $7.50 per 1,000 websites with contacts. Priced per website, not per page. However many pages it reads on a site, you pay once for that website. No per-page, per-email or proxy add-on fees.
- Websites with nothing on them are free. Dead domains, blocked sites, empty sites, duplicates and invalid lines cost $0.
- Finds the emails other tools miss. Reads
mailto:links, visible text, schema.org data, Cloudflare-protected emails, TYPO3-encrypted links, JavaScript-assembled addresses, reversed text andname [at] domain [dot] com/info(at)firma.de/hello AT shop DOT comstyles. - Junk filtered out before you pay. No
example@,you@domain.com,logo@2x.png,bootstrap@5.2.3, Sentry/Wix tracking addresses or no-reply. Every email domain gets a free mail-server (MX) check. - Phones you can dial. E.164 format (
+12122542246) plus country, line type (mobile, landline, toll-free) and the national format. Dates, prices, order numbers and IDs are rejected, so there is no "uncertain phones" junk list to clean up. - The source page for every email and phone, so you can see exactly where it came from.
- Fast and predictable. It reads only the pages likely to hold contacts (contact, impressum, about, team, legal, locations, in 7 languages), up to 5 per site by default, with a hard time limit per site. 1,000 websites usually take a few minutes. No endless crawls.
Why switch from a per-page scraper
| Typical per-page contact scraper | This Actor | |
|---|---|---|
| What you pay for | Every page crawled (often 5 to 20 per website, plus retries) | One price per website that has contacts |
| Real cost for 1,000 websites | $10 to $40 at $2 per 1,000 pages, and more if the crawler wanders | $7.50 at most, usually less (e.g. $5.25 when 700 of them have contacts) |
| Websites with no contacts, dead or blocked | Still charged for the pages it tried | Free |
| Rows per website | One row per page, or merged rows you have to dedupe | Exactly one row per input line, in your order, with inputIndex and your exact inputUrl |
| Phones | Mixed with dates and IDs ("phonesUncertain") | E.164 only, with country and line type |
| Email checks | Paid add-on per email | Free MX check for every email |
| Hidden emails | Plain text only | Cloudflare, TYPO3, JavaScript, [at]/(at)/AT/DOT, reversed text |
| Best contact picked for you | No | primaryEmail (own domain, info@/sales@/hello@ or a named person before privacy@/jobs@) and primaryPhone |
| Memory / proxy needed | 4 GB, proxy on by default | 512 MB, no proxy needed |
Cost examples
| Your list | Websites with contacts | You pay |
|---|---|---|
| 100 websites | 70 | $0.53 |
| 1,000 websites | 700 | $5.25 |
| 10,000 websites from a Google Maps export | 6,500 | $48.75 |
| 1,000 websites, all dead or empty | 0 | $0.00 (only Apify's $0.00005 start fee) |
The same 1,000 websites at $2 per 1,000 pages with 10 pages read per site would be $20, contacts or not. Set Maximum cost per run in the run options and the Actor stops cleanly when it is reached; anything not delivered is not charged.
What you get for each website
| Field | Example |
|---|---|
inputIndex, inputUrl | 0, Katz's Deli - katzsdelicatessen.com (exactly what you entered, so rows join back to your sheet) |
website, domain, status | https://katzsdelicatessen.com/, katzsdelicatessen.com, ok |
companyName | Katz's Delicatessen |
primaryEmail, allEmails, emails | cs@katzsdelicatessen.com, cs@...; press@...; events@... |
primaryPhone, allPhones, phones | +12122542246 |
linkedin, facebook, instagram, twitter, youtube, tiktok | canonical profile URLs (company LinkedIn first; share links and website-builder accounts removed) |
socialProfiles | every profile found, including Pinterest, GitHub, Threads, Telegram and WhatsApp |
contactPageUrl, contactFormUrl | the contact page and the page with a contact form |
address | postal address from schema.org, microdata or the page's <address> block |
emailDetails | per email: type (role or personal), sameDomain, freeMail, mxValid, foundOn pages, method (mailto, cloudflare, obfuscated, text...) |
phoneDetails | per phone: country, lineType, national, fromTelLink, fromStructuredData, legalPageOnly (seen only on terms/privacy pages, e.g. a regulator; never picked as primaryPhone), foundOn pages |
redirectedToDomain | set when the website now redirects to a different domain (moved brand, or an expired domain) |
pagesScanned, pagesScannedUrls, durationSecs, error | what was checked, and a plain-English reason when nothing could be collected |
Statuses: ok, no_contacts, blocked, dns_error, timeout, connection_error, ssl_error, http_error, robots_disallowed, duplicate, invalid_input. Only ok rows are charged.
Flat columns export cleanly to CSV and Excel. Prefer one row per email or phone (for mail merge)? Set Output layout to One row per contact: each email, phone and social profile gets its own row with its type, primary flag and source page. You still pay per website, not per contact.
Input
Paste domains, URLs or even messy cells, one per line:
- Pasted emails are turned into their domain. Company names around a domain are ignored.
www.and non-www.duplicates are scanned and charged once; the duplicate line gets a freeduplicaterow pointing to the first one. - Big lists: put a link to a public TXT or CSV file, or a Google Sheet shared as "Anyone with the link can view", in websitesFileUrl. The website (or email) is picked from any column.
- emailScope:
all,sameDomain(only @their-domain), orsameDomainOrFreeMail(plus Gmail/Outlook-style addresses, common for small local businesses). - onlyWebsitesWithContacts: hide the free rows; their counts stay in the run summary.
FAQ
Do I pay for websites where nothing is found? No. Only rows with at least one email, phone number or social profile are charged ($0.0075 each). Everything else is free.
Why is it priced per website? Because that is what you are buying. Per-page pricing makes the bill depend on how a site is built and how far a crawler wanders, which is where "it said $2 per 1,000 and charged me $71" comes from.
How many pages does it read per website? The homepage plus up to 4 likely contact pages by default (contact, impressum/imprint, about, team, legal, locations; it also follows a Contact link found on the About page). Raise Max pages per website to 20 for deeper coverage; your price does not change.
Does it verify emails? It checks that every email domain has a working mail server (MX), free, and drops emails on domains that cannot receive mail. It does not send any email or probe individual mailboxes. Pair it with an email verifier if you need mailbox-level checks.
Some websites show blocked. Why? A few sites refuse all automated visitors or require JavaScript to show anything. They are free. If you think a site blocks by IP address, turn on the optional Proxy for blocked websites (Apify datacenter proxy or your own proxy URLs): it is used only to retry websites that blocked or timed out.
Does it use a browser? No. It uses a fast HTTP client, which is why it is cheap and quick. Sites that render all content with JavaScript may return no_contacts with an explanation (free).
Is the output in the same order as my list? Yes. Rows come out in input order, each with inputIndex (0-based) and your exact inputUrl, even when sites are scanned in parallel.
Can it run from n8n, Make, Zapier or the API? Yes. There is no large start fee, so even one-website runs cost $0.0075 at most. One row per website maps straight onto a CRM record.
Where is the run summary? In the key-value store record OUTPUT: counts per status, hit rates, billable websites and any note (for example if the maximum cost per run was reached).
Is this legal? It collects only public business contact details that a website shows to every visitor, respects robots.txt, sends at most 2 requests at a time to a site and pauses between them. You are responsible for using the data lawfully, including GDPR, CAN-SPAM and your outreach tool's rules. Prefer role addresses (info@, sales@) for cold outreach in the EU.
Works well with
Google Maps and directory scrapers (paste their website column here), email verifiers, n8n, Make and Zapier, and the Apify API.


