
X (Twitter) Profile Tweet Scraper
Pricing
from $2.00 / 1,000 tweet scrapeds
X (Twitter) Profile Tweet Scraper
Scrape any public X/Twitter account's tweet timeline - text, engagement stats, media, and author info. Give it a handle, @handle, or profile URL. No login, cookies, or session tokens required.
Pricing
from $2.00 / 1,000 tweet scrapeds
Rating
0.0
(0)
Developer
MrDoe
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
X (Twitter) Profile Tweet Scraper
Scrape any public X/Twitter account's tweet timeline — full text, likes, retweets, replies, quotes, view counts, media, and author details. Give it a handle, an @handle, or a profile URL and get one clean row per tweet. No login, no cookies, no session tokens, no account needed.
This Actor is a Twitter/X scraper, a tweet exporter, and a profile timeline downloader rolled into one.
At a glance
- Input: one or more X/Twitter usernames,
@handles, or profile URLs. - Output: one row per tweet — text, engagement stats, media links, posted date, and author info.
- Retweets: automatically resolved to the original tweet's own content, flagged
isRetweet. - Login: none required — no account, no cookies, no session tokens.
- Runs on: the Apify platform — schedule it, call it via API, or wire it into Make/Zapier/Google Sheets.
What does the X (Twitter) Profile Tweet Scraper do?
Give it a username (or several) and it returns that account's public tweet timeline — original tweets, retweets, replies, and quote tweets — paginated back through the account's history up to your maxResults. Every tweet is returned as one clean, spreadsheet-ready row.
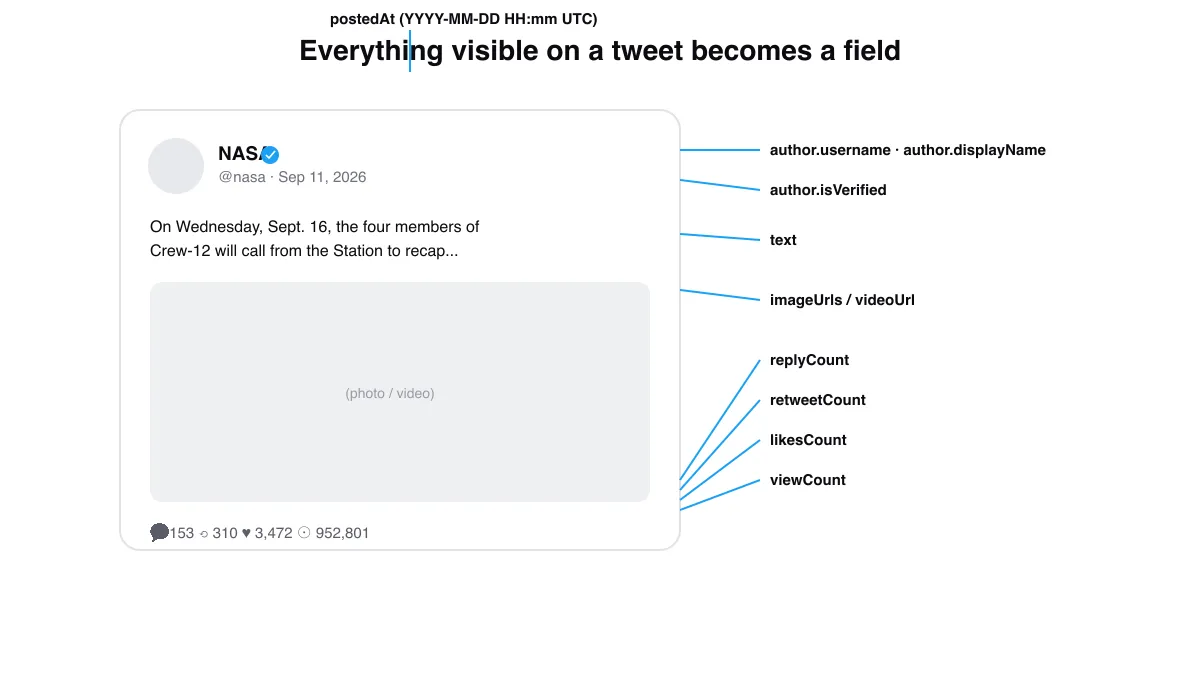
Everything visible on a tweet becomes a dataset field:
| On the tweet | Dataset field |
|---|---|
NASA · verified badge | author.username, author.displayName, author.isVerified |
| The tweet text | text |
| Photo / video | imageUrls, videoUrl |
| 153 replies · 310 retweets · 3,472 likes · 952,801 views | replyCount, retweetCount, likesCount, viewCount |
| "Sep 11, 2026" | postedAt (YYYY-MM-DD HH:mm, UTC) |
| The permalink | url, id |
Why use this X/Twitter scraper?
- Scrape any public account's timeline — one username in, that account's tweets out, fully paginated.
- Real engagement numbers — likes, retweets, replies, quotes, and view counts as actual numbers, not placeholders.
- Retweets handled correctly — a retweet is returned as the original tweet's real text, media, and counts, with
isRetweet: trueandretweetedBytelling you who shared it. No garbled "RT @..." text with empty stats. - Media links included — image URLs and the direct video file link for tweets that have them.
- No login — no account, no cookies, nothing to connect and nothing to get banned.
- Standard exports — JSON, CSV, Excel, XML, or the Apify API.
What makes this Actor different?
Most Twitter/X scrapers either need your own login cookies (risky, and against X's rules, and your account can get suspended for it) or return raw, jargon-named fields straight off the wire. This one runs fully logged-out, resolves retweets to their original content automatically, and returns clean, consistently-typed fields — real numbers for counts, a readable UTC timestamp, and working media URLs — ready to drop into a spreadsheet or database.
How it works
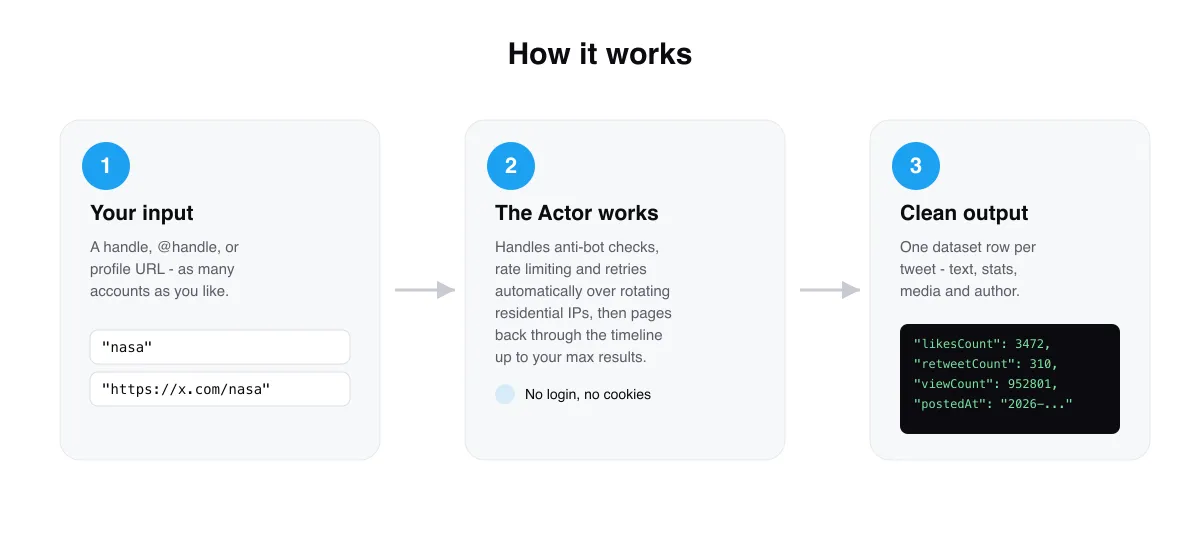
- Your input — one or more usernames,
@handles, or profile URLs. - The Actor collects the data — it handles everything between your input and clean results: no login, anti-bot handling, rate limiting, rotating identities over residential IPs, retries, and paging through to your
maxResults. - Output — a dataset row per tweet with full text, engagement stats, media, and author info.
What data you get
| Field | Description |
|---|---|
url / id | Tweet permalink and numeric id |
text | Full tweet text |
postedAt | Publish time, YYYY-MM-DD HH:mm (UTC) |
likesCount | Likes |
retweetCount | Retweets |
replyCount | Replies |
quoteCount | Quote tweets |
viewCount | View count, when the platform exposes one for that tweet |
bookmarkCount | Bookmarks, when exposed |
isRetweet | true if this row is a retweet - text/media/counts are the original tweet's |
retweetedBy | The scraped account's username, when isRetweet is true |
isReply | true if this tweet is a reply |
inReplyToUsername | The account being replied to, when isReply is true |
isQuote | true if this tweet quotes another tweet |
language | Detected tweet language code (e.g. en) |
imageUrls | Array of image URLs attached to the tweet |
videoUrl | Direct link to the tweet's video, at the highest available quality - null if there is no video |
author | username, displayName, isVerified, avatarUrl |
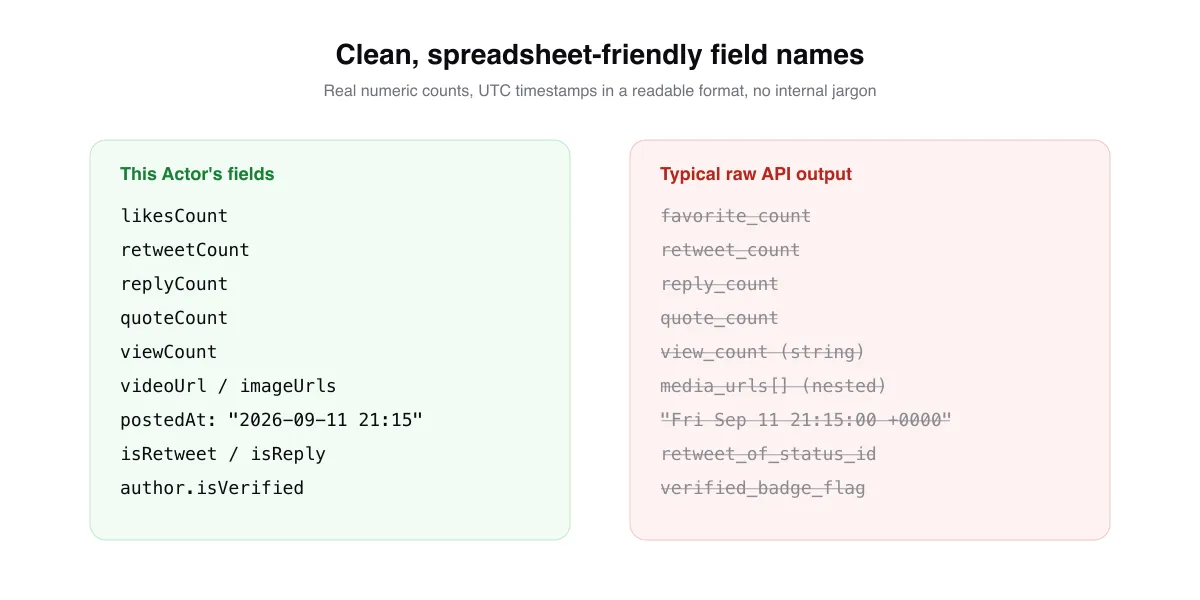
Input parameters
| Parameter | Type | Required | Default | Description |
|---|---|---|---|---|
usernames | Array | Yes | – | Bare handle (nasa), @handle, or full profile URL (https://x.com/nasa). One or more accounts. |
maxResults | Integer | No | 20 | Stop after this many tweets per account. Raise it for a fuller export. |
proxyConfiguration | Object | Yes | Apify Residential | A residential proxy is strongly recommended - X rate-limits and flags datacenter IPs. |
notificationWebhookUrl | String | No | – | Optional Discord/Slack/Zapier/Make webhook URL, pinged with a summary when the run finishes. |
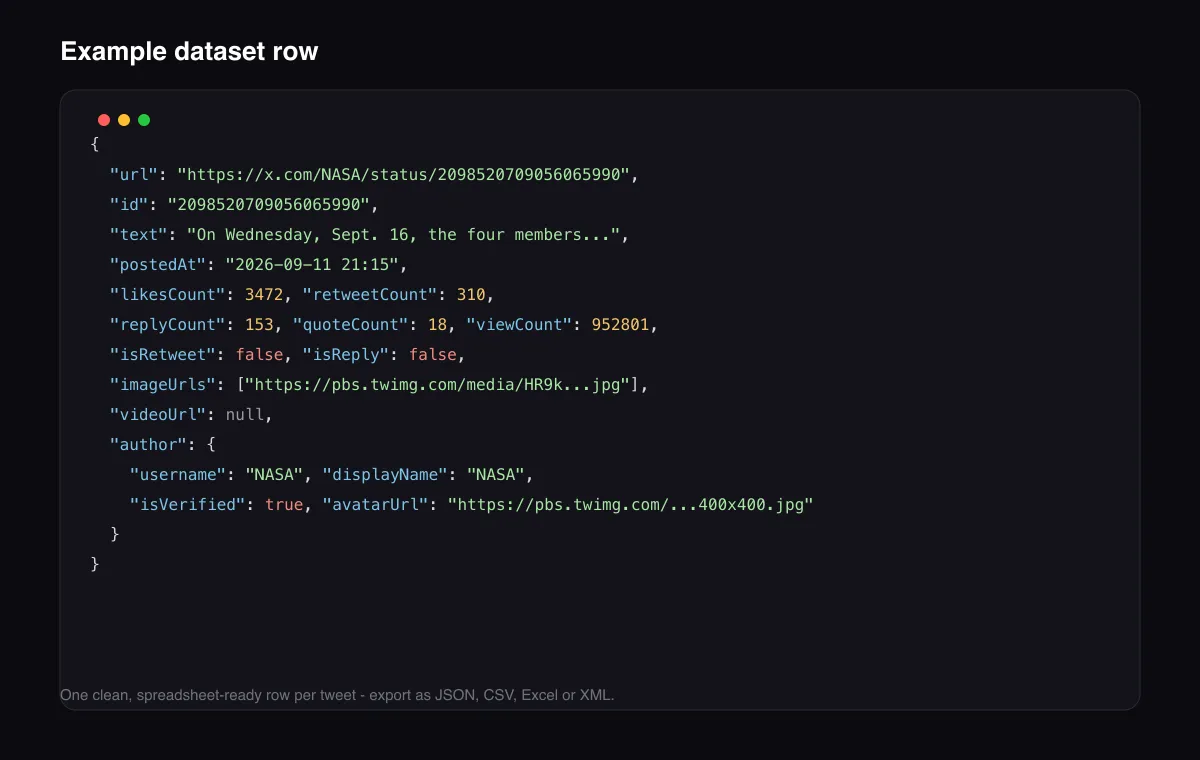
Example output
How to use the X (Twitter) Profile Tweet Scraper
- Open the Actor.
- Add one or more
usernames(bare handle,@handle, or profile URL). - Set
maxResults(per account). - Press Start.
- Read the rows in the Dataset tab (export JSON / CSV / Excel / XML).
Usage examples
Scrape one account's recent tweets
Scrape several accounts in one run
A larger export for analysis
Tips for best results
- Use a residential proxy. A good residential proxy pool is the single biggest reliability factor. Datacenter IPs get rate-limited fast.
maxResultsis per username, not per run — 3 usernames atmaxResults: 20can return up to 60 rows.- A retweet row is the original tweet. If you only want an account's own tweets, filter out rows where
isRetweetistrue. - For a tweet-history archive, schedule the Actor on the same
usernamesand append new runs' output over time. - Protected/private accounts return no data — their tweets aren't publicly readable, by design.
Limitations
- Public accounts only. Protected, suspended, or nonexistent accounts return no data for that username.
- X rate-limits aggressively; the Actor retries and rotates identities automatically, but very large exports go faster with a bigger residential proxy pool.
viewCountisnullfor tweets where the platform doesn't expose a view count (this varies by tweet age and type).- A row is a snapshot at collection time; like/retweet/reply counts keep moving after that.
- This Actor reads public tweet timelines only — it doesn't access DMs, private lists, or protected accounts.
Export formats & integrations
Export the dataset as JSON, CSV, Excel, or XML from the Dataset tab or the Apify API. Connect results to Google Sheets, Make, Zapier, Slack, or your own systems via the API and webhooks, and schedule runs to build a tweet-history archive or a brand-mention monitor.
Frequently asked questions
Do I need an X/Twitter account or login?
No. It works fully logged out — no account, no cookies, no session tokens.
Can I scrape more than one account in a single run?
Yes. Add as many usernames as you like to the usernames array; each gets its own maxResults.
Does it include retweets?
Yes, and they're resolved to the original tweet's real text, media, and engagement counts rather than the empty-stats retweet action itself. Look at isRetweet and retweetedBy to identify and, if you want, filter them out.
Can I download the video from a tweet?
The dataset row includes videoUrl, a direct link to the video file, for tweets that have one. Download it separately with any HTTP client.
Why did a run return nothing for an account?
Usually a datacenter proxy IP being rate-limited, a private/protected account, or a typo'd handle. Switch to a residential proxy and double-check the handle.
What does viewCount: null mean?
The platform doesn't expose a view count for every tweet - it's most consistently available on more recent tweets. null isn't an error.
How many tweets can it collect per account?
As many as maxResults. It pages back through the account's public timeline automatically.
Is this against X's rules?
The Actor only reads publicly available data and doesn't log in or use anyone's account. You are responsible for how you use the data — see below.
Related scrapers
Building a social-media data pipeline? These pair well with this Actor:
- Instagram Reel & Audio Scraper — Reels by trending audio or by username, with video/audio download.
- TikTok Scraper — profile videos with views, likes, comments and audio/video download.
- Facebook Marketplace Scraper — listings, prices and locations, no login.
- YouTube Video Downloader — videos, Shorts, playlists and whole channels as MP4/MP3.
Support
Found a bug or need another field exposed? Open an issue on the Actor's Issues tab in the Apify Console.
Legal / responsible use
This Actor collects publicly available X (Twitter) data. It does not log in, access private content, or touch any account. You are responsible for how you use the Actor and its output, including compliance with X's Terms of Service, applicable copyright in any media you collect, and the data-protection laws that apply to you (GDPR, CCPA, and others).


