
Australia Exchange Rates - RBA
Pricing
from $33.50 / 1,000 fx observations
Australia Exchange Rates - RBA
The RBA's official Australian-dollar exchange rates (F11.1, RBA-sourced series only): pick currencies (EUR, JPY, CNY, TWI...), a date range and newest first - or take the whole table. Daily, from 2023 in the current file. Pay per record.
Pricing
from $33.50 / 1,000 fx observations
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
10 days ago
Last modified
Categories
Share
Australia's official exchange rates - the RBA's own 4pm fixings for the Australian dollar against 20+ currencies and the Trade-weighted Index - from the Reserve Bank of Australia (RBA), as clean per-observation records. Only RBA-sourced columns are emitted.
Who buys this and for what job
- Treasury, finance and accounting teams pulling RBA exchange rates to revalue Australian-dollar balances and invoices.
- Importers, exporters and FX analysts tracking Australian dollar exchange rate history against the euro, yen, yuan and the trade-weighted index.
- Analysts and dashboards that need the RBA's official daily rates as clean records.
Buyers usually search for this as "rba exchange rates" or "australian dollar exchange rate history".
Choose the series
Question: What were the RBA's official Australian-dollar rates against the euro, yen and yuan in the last few days?
Run on 30 Sep 2026 this returned the newest 10 values (10 × $0.05 = $0.50 on Apify's Free plan):
| Date | Series | Title | Value |
|---|---|---|---|
| 30-Sep-2026 | FXRCR | A$1=CNY | 4.6768 |
| 30-Sep-2026 | FXRJY | A$1=JPY | 109.47 |
| 30-Sep-2026 | FXREUR | A$1=EUR | 0.615 |
| 29-Sep-2026 | FXRCR | A$1=CNY | 4.6857 |
| 29-Sep-2026 | FXRJY | A$1=JPY | 109.95 |
Search options (all optional; a record must match every option you set, and several values in one option match any of them):
- Currencies / series (
series) — Series ids or words from the series title, e.g.EUR,JPY,CNY,FXRTWI(trade-weighted index). Only RBA-sourced series exist here (USD is not one of them). - From / to date (
fromDate,toDate) — e.g.2026-01-01or a year. - Newest first (
newestFirst) — latest dates first; the table itself runs oldest first.
Only the chosen series and dates are delivered and billed, tested before the record limit. A series name that matches nothing stops the run with the list of available series, nothing charged. With no option set the actor returns the table exactly as before.
What one record represents
The source is the RBA F11.1 Exchange Rates table at www.rba.gov.au, a keyless CSV. Each record is one RBA-sourced currency series x date - the RBA series id (e.g. FXRCR = A$1=CNY, FXREUR = A$1=EUR, FXRTWI = Trade-weighted Index) and title, the units, frequency and type, the observation date and the value.
Sample output
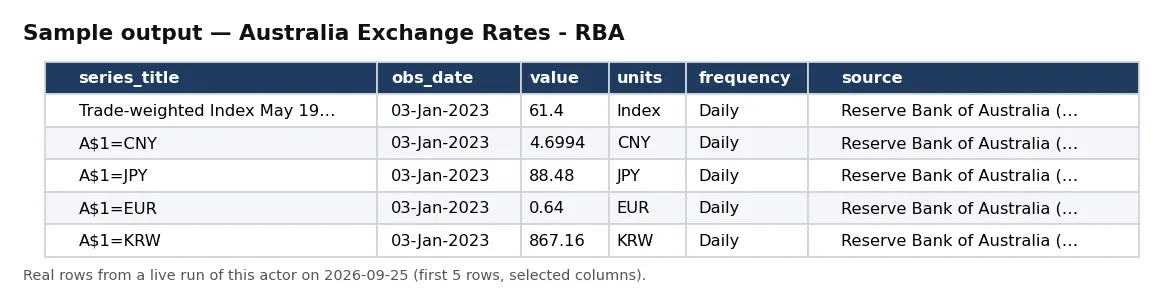
Real rows from a live run of this actor (first 5 rows, selected columns).
One full record from the same run, exactly as delivered:
The licence-driven column filter
The F11.1 table carries a published Source header row naming who supplies each column. This cell emits only columns whose Source is exactly 'RBA' - 21 series - and never the WM/Reuters USD or IMF SDR columns. The filter is read live from the Source row on every run and enforced structurally: a non-RBA column can never enter the output. Across 923 dated rows the 21 RBA series hold 16,273 non-blank observations; blank cells are skipped.
Licence
Reserve Bank of Australia (RBA) statistical tables. RBA copyright material may be used commercially with attribution to the Reserve Bank of Australia and without any suggestion of RBA endorsement. This cell emits ONLY columns whose published Source is exactly 'RBA'; series sourced to WM/Reuters, ASX, FENICS or the IMF are never selected, honouring the RBA's terms on third-party material.
Sibling Actors
This is the RBA's own official AUD fixing table (RBA series ids, the RBA 4pm method). The fleet's ecb-bank-interest-rate-records cell is a euro-area rate series from the ECB - a different publisher, no dataset-row overlap.
Fields, scheduling and integration
Every field in the record is either a source-native identifier, a source-native attribute, or one of the six
provenance fields (source, source_dataset, licence, attribution, caveat, observed_at) the fleet attaches to
every record. Nothing is derived or inferred beyond the small, documented transforms noted above, and nothing is
dropped silently - the handling section spells out exactly what is excluded and why. The grain is one record per the
natural unit of the source, which keeps each row independently meaningful, keeps the key stable across runs so
re-running is a cheap upsert rather than a re-import, and lets you aggregate up to whatever unit you need without
unpicking a pre-joined table.
Because the source republishes on its own cadence, a scheduled run keeps a downstream table current: new and changed
records upsert over the old ones on the stable key, and the observed_at stamp tells you when each was last seen live.
Set Maximum records low to sample the shape of the data cheaply, then raise it once the cell fits your use; the
Actor streams or partitions its source, so memory stays flat regardless of how many records you request, and you are
billed only for what is delivered. The output is a flat table of typed records, so it drops straight into whatever you
already use: load the run's dataset over the API or an export, key on the record id, and upsert. Because identifiers
are preserved exactly as the source publishes them, joins across the fleet's cells - and onto your own systems - work
without a mapping layer. There is no subscription and no minimum: the per-record price and the record cap together
mean the spend on any run is known in advance and matched exactly to the data you receive.
Reconciling counts honestly
Where the live count differs from any previously published figure, the live measure is the honest one and is what this listing quotes; sources re-issue and re-version their data over time. The run receipt always states what was actually delivered and charged and confirms the two agree, so every run is auditable against itself regardless of what any external index expected.
Scaling, scheduling and support
A common pattern is a light scheduled run that pulls the newest slice into a staging table, then a merge on the stable key into the table your product reads, so you never re-pay for rows you already hold and your history grows cleanly over time. Because the record shape assumes no particular warehouse, language or tool, the integration work is a load and a merge, not a cleaning project: the same code path handles a 40-row sample and a full pull, and the only thing that changes between them is the record cap. If you only need a slice, the cap and any partition or filter inputs bound the run precisely, so a targeted pull costs cents rather than the price of the whole set, and a broad pull is simply a higher cap left to run. Nothing about the delivery is subscription-gated: each run stands alone, priced at exactly the records it returns, so you can dial spend up or down run by run as your needs change, and a scheduled cadence keeps a downstream table current without any standing commitment. When the source publishes a correction or a new period, the next run picks it up and upserts it over the stale row on the same key, so the table you maintain stays both complete and current with no manual reconciliation.
Provenance and compliance
Every run reads the door host's robots.txt at runtime and records the result (URL, status, byte length and, where
a policy is served, its SHA-256) in the run's RUN_RECEIPT. Where the host serves no applicable policy - a 404, a
403, or a homepage redirect - the gate records that as a flag and proceeds on the licence, which grants re-use; a flag
is never treated as permission in itself. The endpoint is keyless and the Actor reads only the public data door -
never a mirror, and it never bypasses a block.
Data quality and freshness
Numbers arrive as real numbers, booleans as real booleans, and every other value as a string or null, so the dataset
loads without a cleaning pass. Each record is keyed on a stable composite of the source's own identifiers, so it is
safe to diff, deduplicate or upsert. Every run re-reads the live door, so the data is as fresh as the source
publishes, and each record's observed_at stamp dates the snapshot. The receipt records how many rows were delivered
and charged and confirms charge_equals_delivered.
Billing, delivery and joins
Default changed on 30 Sep 2026: if you leave maxRecords out, a run now returns up to 10 records (it was 1,000). Set maxRecords yourself to get more — the maximum is unchanged.
Pricing is per record: you are billed only for records the Actor actually delivers, and the charge is raised after each record is pushed (push-then-charge), so a failed or empty run costs nothing. The Maximum records cap bounds every run, so spend is known before you start - sample cheaply, then raise it. Every record is a flat, typed object keyed on a stable id, so it loads without a cleaning pass, diffs cleanly between runs, and upserts into a table you keep over time; re-running keeps that table current without re-paying for rows you already hold, and each receipt reconciles delivered against charged. Because the source's own identifiers are preserved verbatim, the dataset joins onto other sources keyed on the same identifier.
Who buys this, and how they use it
This cell is bought by teams that need the source's published set as a typed, keyed table they can hold and refresh rather than a page they scrape: market- and macro-intelligence teams sizing and tracking a market, data engineers wiring a clean upstream feed into a warehouse, and compliance and research teams building on a stable identifier. The grain and the key are chosen so the output is a building block, not a one-off export - you run it on a schedule, keep the delta, and join it to your other sources on the identifiers it preserves verbatim. The spend on any run is the per-record price times the records delivered, matched exactly to what you receive.


