
Broken Link Checker — Find Dead Links on Any Website
Pricing
from $33.50 / 1,000 link checkeds
Broken Link Checker — Find Dead Links on Any Website
Check every link on a website, its sitemap or a plain URL list: one row per link with status, broken / blocked / redirect result, redirect chain, link text and linking pages. Images and scripts too, or only the problems. Part of NexGen Signal — data tools and official-source data products
Pricing
from $33.50 / 1,000 link checkeds
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
🔗 Broken Link Checker — Find Dead Links on Any Website
Give one or more websites and get every link on them checked, one row per unique link: whether it works, is redirected, is broken (4xx or 5xx) or is unreachable, its status code and redirect chain, the link text, and up to 20 pages that link to it.
The actor reads your site's pages (staying on your site, within the click depth you set, with the sitemap's pages too if you want), collects every link, and checks each unique link once, whether it appears on one page or on a thousand. Links to other sites are checked too, and you can also check images, scripts, stylesheets, icons and embedded media. You can also hand it a plain list of links to check as they are. Turn on onlyBroken to receive only the problems.
Results are ok, redirect, blocked (the server answered 401, 403, 429 or 999 to an automated check; the page may work in a browser), broken (any other 4xx or 5xx) or unreachable (no answer). Slow links are flagged.
The unit of output is one unique link delivered. With onlyBroken, every link is still checked but only broken and unreachable ones (and redirects, if you ask) are delivered and billed.
Who buys this and for what job
- SEO and content teams fixing 404s and redirect chains that waste crawl budget.
- Web agencies checking a client site before and after a launch or migration.
- Documentation teams finding dead references in docs and help centres.
- Site owners running a scheduled weekly link check.
Buyers usually search for this as "broken link checker", "dead link finder" or "404 checker".
📊 Sample Output
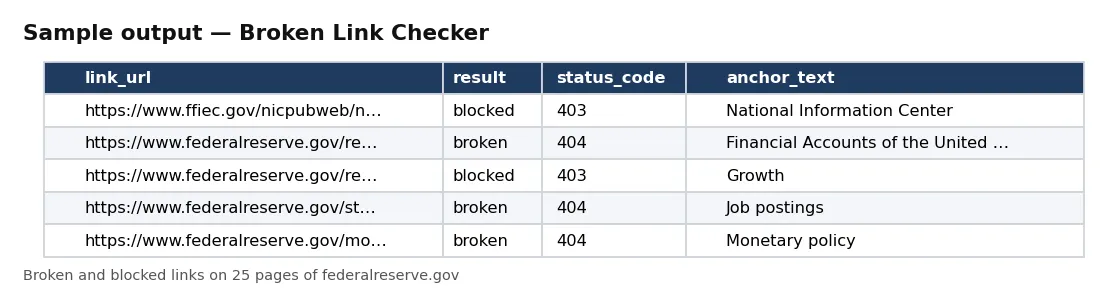
| link_url | result | status_code | anchor_text | first_found_on |
|---|---|---|---|---|
| https://www.bankdirectorsdesktop.org/ | unreachable | — | Bank Director's Desktop | https://www.federalreserve.gov/sitemap.htm |
| https://www.ffiec.gov/nicpubweb/nicweb/nichome.aspx | blocked | 403 | National Information Center | https://www.federalreserve.gov/sitemap.htm |
| https://www.federalreserve.gov/releases/z1/current/default.… | broken | 404 | Financial Accounts of the United States - Z.1 | https://www.federalreserve.gov/sitemap.htm |
| https://www.federalreserve.gov/releases/z1/current/ | blocked | 403 | Growth | https://www.federalreserve.gov/azindex.htm |
| https://www.federalreserve.gov/start-job-search.htm | broken | 404 | Job postings | https://www.federalreserve.gov/azindex.htm |
Rows from live run 9zVb837zf1R5Lcneo on Apify (25 pages of federalreserve.gov with onlyBroken and includeRedirects on). Notice the blocked rows: those servers refused an automated check, and the error field says to confirm them in a browser.
✅ What you get
Every field of each record:
record_id,link_url— the link (absolute, without its #fragment).result— ok, redirect, blocked, broken or unreachable.slow— true when the answer took longer than slowThresholdMs (default 5 s).status_code,final_url,redirect_count,redirect_chain— final status, where it ends up, and every redirect hop.error— why nothing answered (timeout, host does not resolve, redirect loop), or a note when a server refuses automated checks.link_type,element— internal or external; a, area, img, script, link, iframe, source, video, audio, embed.first_found_on,anchor_text,nofollow— first page it was seen on, its link text there, and rel=nofollow.occurrences,found_on_pages— how often it appears, and up to 20 pages that link to it with their link text.content_type,response_ms,checked_at— type and time of the answer, and when it was checked (UTC).
⚙️ Sample inputs
Three pages of a site (the Store example)
Every link, working or not, up to 10.
Only the problems on a whole site
Broken, unreachable and redirected links only.
Images, scripts and stylesheets too
Checks the page's own files as well as its links.
A plain list of links
Each link is checked as it is; nothing is opened for more links.
Input fields:
| Field | Meaning |
|---|---|
startUrls | start pages (up to 100); the same site is read for more links. |
linkUrls | a plain list of links to check as they are (up to 50,000); can be combined with startUrls. |
useSitemaps | also read the pages in each site's sitemap (default off). |
requestTimeoutSecs, slowThresholdMs | how long to wait for an answer (default 25 s) and what counts as slow (default 5,000 ms). |
maxPages | pages of your site opened and read for links (default 100). |
maxDepth | clicks from the start page (default 10). |
checkExternalLinks | check links to other sites (default on). |
checkResources | also check images, scripts, stylesheets, icons, iframes, video and audio (default off). |
onlyBroken, includeRedirects | deliver only broken and unreachable links (optionally redirects too). |
includeSubdomains, includeUrlPatterns, excludeUrlPatterns | which pages are read for links. |
maxLinks | stop after this many links are delivered (default 10,000). Each delivered link is billed once. |
🧾 JSON sample record
🔧 How it works
Pages of your site are read 4 at a time while links are checked 8 at a time, with at most 2 requests at once to any one host and its robots.txt crawl-delay respected. A page of your site that is read counts as its own check. Other links get a HEAD request; when that answers with an error, a GET confirms it, because some servers answer HEAD wrongly.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
Rows are delivered when checking finishes, so each row lists every page that links to it. If the run nears its time limit it stops reading pages and delivers what it checked. The run receipt (RUN_RECEIPT) has the counts by result, the links that were skipped and why, the pages with the most broken links, and the delivered and charged counts.
💰 Pricing example
Per link delivered, no start fee, no monthly charge:
| Apify plan | Price per link |
|---|---|
| Free | $0.05 |
| Bronze | $0.045 |
| Silver | $0.04 |
| Gold, Platinum, Diamond | $0.0335 |
- 10 links: $0.50 on the Free plan, $0.34 on Gold.
- 1,000 links: $50.00 on the Free plan, $33.50 on Gold.
- 10,000 links: $500.00 on the Free plan, $335.00 on Gold.
Coverage and size. Proof runs on 17 Oct 2026: 25 pages of federalreserve.gov in about 90 seconds; 809 unique links checked, 6 broken or unreachable, 2 blocked and 95 redirected (103 rows delivered with onlyBroken and includeRedirects); 4 NASA sitemap pages, 46 links, in 4 seconds; a plain list of 4 links in 2 seconds. Pages are read as the server sends them; links added only by JavaScript are not seen.
⚖️ Legal & ToS
You choose the sites. Check sites you own or have the right to check; every link is requested once per run, politely.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
❓ FAQ
What does blocked mean?
The server answered 401, 403, 429 or 999 to an automated check. Some servers do that even when the page works in a browser, so these are reported apart from broken links; open them in a browser to confirm.
Are #anchors checked? No. The page is checked; the fragment after # is not.
Is a link on 50 pages billed 50 times? No. Each unique link is one row, with up to 20 linking pages listed in it.
🆘 Troubleshooting
- Too few links checked — Raise maxPages and maxDepth; RUN_RECEIPT shows pages read and links left unchecked.
- Links skipped by robots.txt — The target site's robots.txt disallows them; they are listed in RUN_RECEIPT and not billed.
- SOURCE UNAVAILABLE — None of your start pages could be reached after retries. Nothing was charged.
🔗 Related Actors
- Website Performance Audit — Lighthouse scores and web vitals per page
- Website Tech Stack Detector — what a site is built with
- Website Contact Scraper — contact details from website lists
🏢 About NexGen Signal — data tools and official-source data products. Browse the catalog: apify.com/nexgensignal
⭐ Found this useful?
If this actor saved you time, a rating on its Apify Store page helps other buyers find it.
Part of NexGen Signal — data tools and official-source data products.


