
Bulk Image Downloader — Save Images from Pages
Pricing
from $33.50 / 1,000 image downloadeds
Bulk Image Downloader — Save Images from Pages
Download every image from a list of web pages or image links: JPEG, PNG, WebP, GIF, SVG and more. Filter by size and type, skip duplicates, and get each file saved with a download link plus width, height and hash. Part of NexGen Signal — data tools and official-source data products
Pricing
from $33.50 / 1,000 image downloadeds
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
🖼️ Bulk Image Downloader — Save Images from Pages
Give a list of web pages or direct image links and get every image downloaded, checked and saved, one row per image: where it was found, the alt text, format, width and height, file size, SHA-256, and a download link to the stored file.
The actor reads each page's <img> tags (including srcset, lazy-load data-src attributes and <picture> sources), its og:image and twitter:image tags, and links that point straight at image files. It picks the largest srcset candidate, skips data: URIs, de-duplicates by file hash across the whole run, and filters by type, minimum size and minimum dimensions.
The unit of output is one image delivered. Images that are skipped (wrong type, too small, duplicate, blocked by robots.txt, unreachable) are not billed.
Who buys this and for what job
- E-commerce teams pulling product photos from supplier or catalogue pages.
- Designers and researchers collecting reference images from a list of articles.
- ML teams building image datasets with hashes for de-duplication.
- Archivists and site owners backing up the images on their own pages.
Buyers usually search for this as "bulk image downloader", "download all images from URL" or "image scraper".
📊 Sample Output
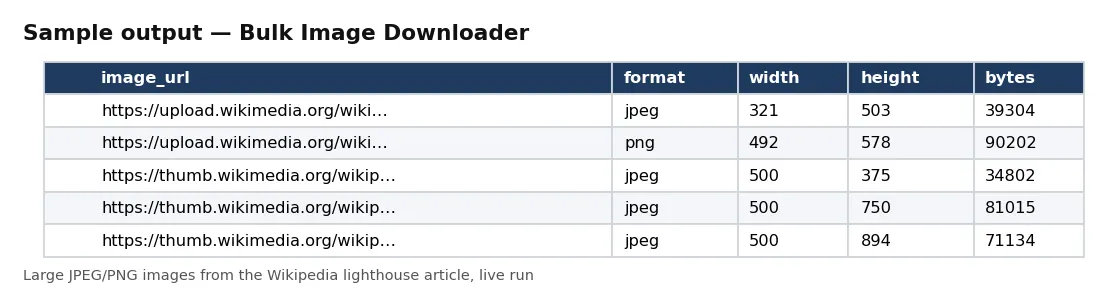
Rows from live run 5dVND5wPhxqehWR2b on Apify (JPEG and PNG only, at least 200 px wide and 5,000 bytes, from the Wikipedia article on lighthouses). Notice that where a page offers several sizes in srcset, only the largest is downloaded.
✅ What you get
Every field of each record:
record_id,sha256— file hash (record_id is its first 24 characters): the same file always gets the same id.source_page,image_url,final_url— the page it was found on, the image link as found, and where it was served from after redirects.alt_text,found_in— the alt text or title the page gives it, and where it was found (img src, img srcset, picture source, meta og:image, link to image, direct link).content_type,format,bytes,width,height— type, format (jpeg, png, gif, webp, svg, avif, bmp, ico, tiff), size and pixel dimensions (empty for SVG).file_key,file_url— key and link of the saved file in the run's key-value store (empty when saveImages is off).downloaded_at— when it was downloaded (UTC).
⚙️ Sample inputs
Images from one article (the Store example)
The first 10 images in page order.
Large photos only, details without files
Skips icons and logos; gives size, dimensions and hash for each image.
Direct image links
Each link is downloaded as it is.
Input fields:
| Field | Meaning |
|---|---|
urls | pages or direct image links (up to 5,000). |
imageTypes | jpeg, png, gif, webp, svg, avif, bmp, ico, tiff. Empty = all. |
saveImages | store each file with a link (default true). |
minWidth, minHeight, minBytes | skip smaller images (0 = no limit). |
maxImageMb | skip files bigger than this (default 25). |
maxImagesPerPage | image links tried per page, in page order (default 100). |
maxImages | stop after this many delivered images (default 1,000). Each delivered image is billed. |
🧾 JSON sample record
🔧 How it works
Each page is downloaded once and parsed; each image is then downloaded (8 at a time) to measure it and hash it. Pillow reads the dimensions. A file already delivered in the run (same SHA-256) is skipped, so the same logo on 50 pages is billed once.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
Saved files go to the run's own key-value store. If your Apify account keeps storages private, add your API token to the link (?token=…) or open the store from the run in Apify Console.
Delivery is pushed first and charged after. The run receipt (key-value store record RUN_RECEIPT) lists every page with its outcome and number of images found and delivered, the robots.txt result per host, the reasons images were skipped with counts, and the delivered and charged counts.
💰 Pricing example
Per image delivered, no start fee, no monthly charge:
| Apify plan | Price per image |
|---|---|
| Free | $0.05 |
| Bronze | $0.045 |
| Silver | $0.04 |
| Gold, Platinum, Diamond | $0.0335 |
- 10 images: $0.50 on the Free plan, $0.335 on Gold.
- 1,000 images: $50.00 on Free, $33.50 on Gold.
- 10,000 images: $500.00 on Free, $335.00 on Gold.
Coverage and size. Proof runs on 17 Oct 2026: the Wikipedia article on lighthouses gave 94 image links; a 40-image run over two articles finished in about 6 seconds. Works on any public page that puts its images in the HTML; images added only by JavaScript after load are not seen.
⚖️ Legal & ToS
Images belong to their owners. You choose the links. Make sure you have the right to download and use the content you point it at; the actor fetches only what you give it (and, where you turn it on, what those pages link to).
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
❓ FAQ
Does it run JavaScript? No. It reads the HTML the server sends, including srcset and lazy-load attributes. Images inserted later by scripts are not found.
Can I download only the files, not the details? Every delivered image has a row; the file itself is in the key-value store.
Why was an image skipped? RUN_RECEIPT counts the reasons: type not selected, smaller than your limits, duplicate, over maxImageMb, blocked by robots.txt, or the link was not an image.
🆘 Troubleshooting
- file_url answers 403 — Your account keeps storages private: add
?token=YOUR_TOKENto the link or open the store from the run. - Fewer images than on the page — Check maxImagesPerPage and the skipped counts in RUN_RECEIPT.
- SOURCE UNAVAILABLE — None of your links could be reached after retries. Nothing was charged.
🔗 Related Actors
- Brand Logo & Favicon Lookup — a company's logo from its domain
- Website Tech Stack Detector — what a site is built with
- Website Performance Audit — Lighthouse scores and web vitals per page
🏢 About NexGen Signal — data tools and official-source data products on Apify. Browse the catalog: apify.com/nexgensignal
⭐ Found this useful?
If this actor saved you time, a rating on its Apify Store page helps other buyers find it.
Part of NexGen Signal — data tools and official-source data products.


