
CMS Part D Drug Spending — by Drug & Maker
Pricing
from $33.50 / 1,000 drug spending records
CMS Part D Drug Spending — by Drug & Maker
Medicare Part D spending by drug and manufacturer, 2020-2024: search by generic, brand or maker, keep one row per drug, set a 2024 spending floor and rank by 2024 spending, claims, beneficiaries or unit-cost growth. Aggregate only. Pay per record.
Pricing
from $33.50 / 1,000 drug spending records
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 days ago
Last modified
Categories
Share
Turn CMS's Medicare Part D Spending by Drug dataset into clean, per-record drug-economics benchmarks - one row per drug (brand/generic) and manufacturer with multi-year spending, dosage units, claims and beneficiary counts, ready for market-access teams to benchmark drug economics.
Each row from the CMS data API becomes one clean, flat record with numeric fields coerced to real
numbers, CMS's *-suppressed cells delivered as null (not zero), a stable record_id, and provenance
stamped on every row: source, dataset UUID, the public-domain notice, attribution, a UTC retrieval
timestamp and an interpretation caveat.
What one record represents
The source is the U.S. Centers for Medicare & Medicaid Services (CMS) open data API — dataset
7e0b4365-fd63-4a29-8f5e-e0ac9f66a81b, Medicare Part D Spending by Drug. Each record is one drug (brand and generic) for one manufacturer, carrying five years (2020-2024) of Medicare Part D metrics: total spending, dosage units, claims, beneficiaries, average spend per dosage unit / claim / beneficiary, an outlier flag per year, and the recent change and compound annual growth rate in average spend per dosage unit. The manufacturer 'Overall' denotes the all-manufacturer aggregate row for a drug.
For each record you get the analytic columns listed below (reproduced verbatim, numbers as numbers) plus
a composite record_id and the provenance block. Columns include brand_name, generic_name, manufacturer_name, total_manufacturers, and per-year total_spending_YYYY, total_claims_YYYY, total_beneficiaries_YYYY, avg_spend_per_dosage_unit_YYYY and outlier_flag_YYYY, plus chg_avg_spend_per_dosage_unit_23_24 and cagr_avg_spend_per_dosage_unit_20_24.
Search and rank drugs
Question: What did Medicare Part D spend on the GLP-1 drugs semaglutide and tirzepatide (Ozempic, Wegovy, Rybelsus, Mounjaro) in 2024, largest first?
Run on 30 Sep 2026 this matched 5 Overall rows and returned all 5, ranked by 2024 spending (5 × $0.05 = $0.25 on Apify's Free plan):
| Brand | Generic | Spending 2024 | Claims 2024 | Beneficiaries 2024 |
|---|---|---|---|---|
| Ozempic | Semaglutide | $12,970,296,347 | 10,417,182 | 1,952,637 |
| Mounjaro | Tirzepatide | $6,336,942,641 | 5,105,397 | 894,581 |
| Rybelsus | Semaglutide | $1,890,082,026 | 1,251,733 | 309,993 |
| Wegovy | Semaglutide | $301,283,291 | 211,575 | 52,961 |
| Zepbound | Tirzepatide | $387,343 | 353 | 245 |
Search options (all optional; a record must match every option you set, and several values in one option match any of them):
- Generic name / brand name / manufacturer (contains) (
generics,brands,manufacturers) — words in the name; several values = any of them. - One row per drug (
overallOnly) — CMS gives each drug anOverallrow plus one row per manufacturer; keep only the Overall row so totals are not double-counted. - Minimum total spending 2024 (
minSpending2024) — in US dollars, e.g.1000000000. - Rank by (
sortBy) —spending2024,claims2024,beneficiaries2024,unitCostChange(2023-24 change in spend per dosage unit) orunitCostGrowth(2020-24 yearly growth). The actor reads every matching row and keeps the top ones; blank (suppressed) values rank last.
Name and spending filters are sent to the CMS data API, so filtering happens before Maximum records; ranking is done over every matching row (at most the 14,536 rows in the dataset). The status message gives CMS's match count. "No records match" (nothing charged) is a successful run. With no search option the actor reads the dataset in the source's order exactly as before.
Coverage and volume
The live dataset holds 14,536 drug-manufacturer records across the Medicare Part D formulary - that is the record capacity of a full pull.
Live count: 14,536 records - matches the Wave-3 index figure exactly.
The Actor pages the CMS data API (size/offset) and stops as soon as your Maximum records cap is met. The whole dataset fits comfortably in a single run.
Licence and attribution
CMS open data is a public-domain U.S. Government work (17 U.S.C. §105) — free to use, redistribute and build on. The developer FAQ that governs the API is published by CMS; the full notice travels on every record:
U.S. CMS (Centers for Medicare & Medicaid Services). Public-domain U.S. Government work (17 U.S.C. 105). Reproduced verbatim; no third-party content. Aggregate drug-level spending only - no beneficiary, provider, or NPI data.
The required attribution — U.S. Centers for Medicare & Medicaid Services (CMS) — is present on every record.
Interpretation caveat
Aggregate Medicare Part D spending per drug by manufacturer and year. Spending is gross Part D spending (not net of rebates). No beneficiary-level, provider, or NPI data.
Values are reproduced verbatim from the API. CMS suppresses small cells with an asterisk (*) for
privacy; those are delivered as null so you can tell "suppressed" apart from a real zero. The per-year outlier_flag_YYYY fields are normalized to real booleans (true/false/null).
Person-data policy
There is no beneficiary, provider, or NPI data in this dataset - only drug names, manufacturer organisations and aggregate spend metrics. The field list this Actor emits is a fixed allow-list, and a per-record assertion rejects any row that would introduce an NPI, provider-name, or contact field (verified with a planted- field test). This is aggregate benchmark data about drugs, procedures, manufacturers and localities — never about individual patients or providers.
Data quality and freshness
Numeric fields are coerced to real numbers and booleans to real booleans; suppressed cells become
null. Every run re-reads the live API, so the data is as fresh as CMS publishes, and each record's
observed_at stamp records when it was retrieved. Delivery is in the API's order and keyed on the
source-native composite, so the dataset is safe to diff, deduplicate or upsert. The run's RUN_RECEIPT
records the API's reported total row count alongside how many records were delivered and charged.
Provenance and compliance
Every run reads data.cms.gov/robots.txt at runtime; the gate result (URL, status, byte length, SHA-256
of the policy) is written to the run's RUN_RECEIPT. The API is keyless. The Actor never bypasses a
block or fetches through a mirror.
Inputs
Default changed on 30 Sep 2026: if you leave maxRecords out, a run now returns up to 10 records (it was 500). Set maxRecords yourself to get more — the maximum is unchanged.
- (No partition input - the whole dataset is pulled directly.)
- Maximum records (
maxRecords) — hard cap on records delivered and billed. - Search options - see Search and rank drugs above; all optional.
Output
Records land in the Actor's default dataset and export as JSON, CSV, Excel or via the Apify API. A tabular overview view surfaces the most useful columns for quick inspection.
Fields in detail
The record leads with the drug and manufacturer identifiers, then the multi-year metric block, then the change/CAGR fields. The provenance block — source, source_dataset, licence, attribution,
caveat, observed_at — closes every record, so a single row is self-describing and audit-ready.
Working with CMS suppression
CMS suppresses small cells with an asterisk (*) to protect privacy. This Actor maps every suppressed
numeric cell to null rather than to zero or the literal string *, so your downstream aggregations do
not silently treat a suppressed value as a real number. A null in a count or amount column therefore
means "CMS suppressed this cell", not "reported zero" — an important distinction when you sum or average
across rows. Text and code columns are always passed through verbatim, so codes such as HCPCS, BETOS,
carrier and locality remain exactly as CMS publishes them and join cleanly against CMS reference tables.
Scaling and limits
Set Maximum records low to sample cheaply or high to pull the full set (or, for the partitioned
dataset, the full slice for your chosen code). The Actor pages the API server-side and delivers
incrementally, so memory stays flat regardless of how many records you request, and you are billed only
for what is delivered. Because CMS refreshes these datasets on its own publication calendar, re-running
the Actor picks up new periods automatically, and each record's observed_at stamp dates the snapshot —
schedule a run to keep a downstream benchmark table current.
Sibling Actors
This Actor benchmarks drug economics under Medicare Part D — spending at drug level, not regulatory approvals and not provider-level data. This Actor also shares its engineering — the runtime robots gate, push-then-charge billing and verbatim-value discipline — with the fleet's other public-data records Actors.
Sample output
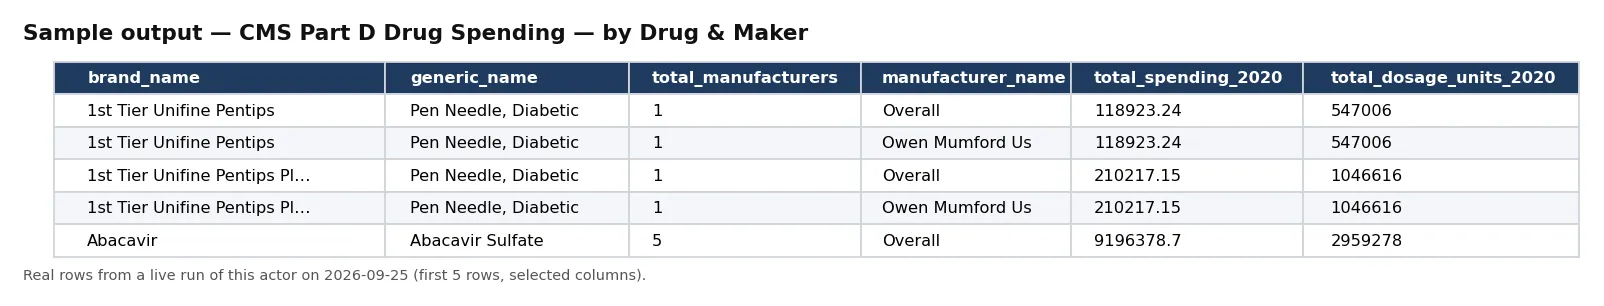
Real rows from a live run of this actor (first 5 rows, selected columns).
One full record from the same run, exactly as delivered:
Pricing
This Actor uses Apify's pay-per-event model: a flat $0.05 per record actually delivered to the dataset, and nothing else — no monthly rental, no per-run base fee, no compute charge. Deliver 40 records and you pay $2.00; deliver 10,000 and you pay $500.00. Billing is wired after delivery — each record is pushed first and only then does the per-record event fire — so a mid-run failure can only ever under-charge you, never over-charge. Use Maximum records to cap spend precisely.
Typical uses
Benchmark drug spending and price growth under Medicare Part D; rank drugs or manufacturers by spend, claims or beneficiaries; track multi-year cost trends and flag outliers; screen for high-growth drug costs; or feed a market-access, pricing or payer-strategy model with clean drug-economics records.
What this Actor does not do
It does not deliver provider-level, NPI-level, or beneficiary-level data — it is an aggregate benchmark
table; it does not forecast or model; and it does not alter any published value beyond coercing types and
mapping CMS's * suppression to null. It gives you faithful, public-domain, analysis-ready records with
a provenance trail you can audit on every run.


