

LinkedIn Job Postings API — Public Hiring Data
Pricing
from $33.50 / 1,000 public job postings
LinkedIn Job Postings API — Public Hiring Data
Query public LinkedIn job postings by role, location, employment type, and posting age. Receive normalized records through an Apify dataset or API. Public job postings only; no accounts, profiles, or people data. Pay per delivered record.
Pricing
from $33.50 / 1,000 public job postings
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
🧑💻 LinkedIn Job Postings API — Public Hiring Data
Query public LinkedIn job postings and receive normalized hiring records through an Apify dataset or API response. This actor is for recruiting, hiring-intelligence, and labour-market workflows that need repeatable structured records rather than manual browsing.
Output is one None row per result; billing is pay-per-event, the value event being one public job posting (a $0.02 start fee per run, then $0.05 per public job posting). Source: www.linkedin.com.
Use with
linkedin-job-postings-api → company/domain enrichment → hiring-intensity analysis → scheduled delta runs. Keep downstream enrichment on company-level public facts; this actor supplies no personal profiles or applicant data.
📊 Sample Output
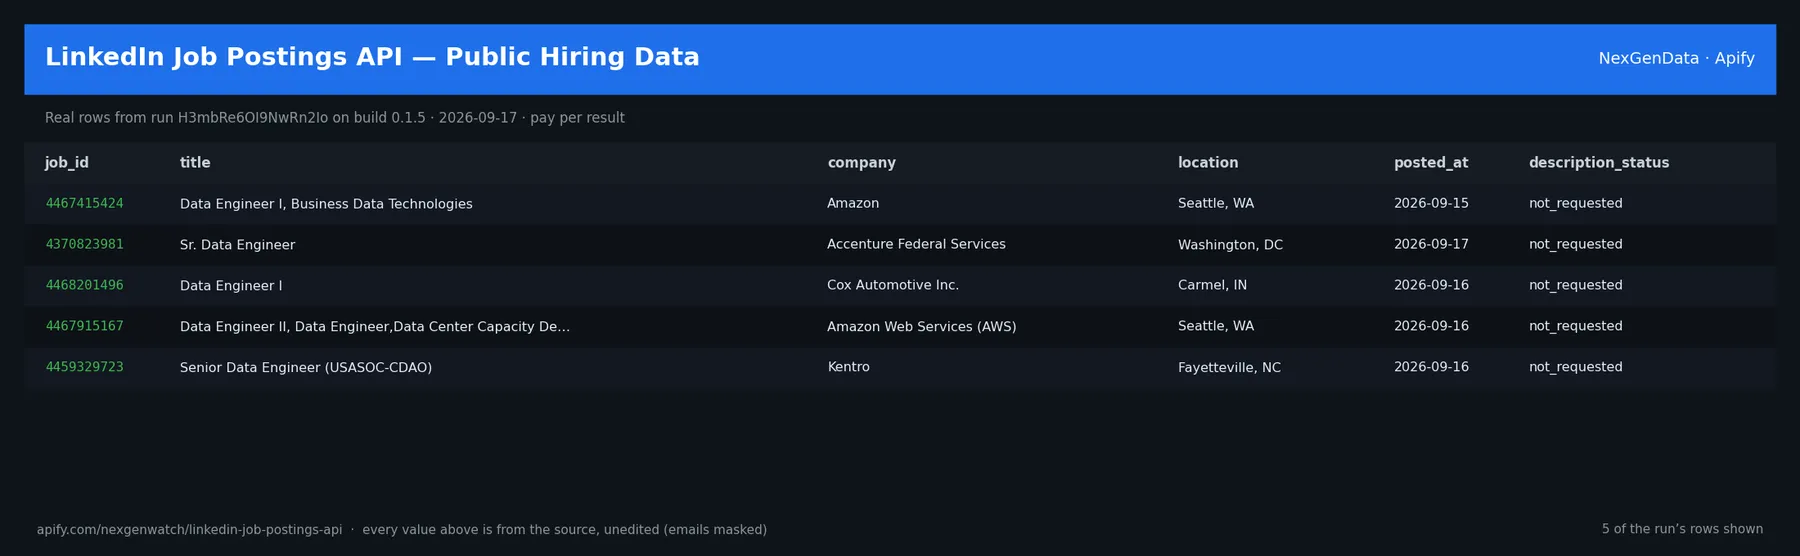
Real rows from run H3mbRe6OI9NwRn2Io on build 0.1.5 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| job_id | title | company | location | posted_at | description_status |
|---|---|---|---|---|---|
| 4467415424 | Data Engineer I, Business Data Technologies | Amazon | Seattle, WA | 2026-09-15 | not_requested |
| 4370823981 | Sr. Data Engineer | Accenture Federal Services | Washington, DC | 2026-09-17 | not_requested |
| 4468201496 | Data Engineer I | Cox Automotive Inc. | Carmel, IN | 2026-09-16 | not_requested |
| 4467915167 | Data Engineer II, Data Engineer,Data Center Capacity Delivery | Amazon Web Services (AWS) | Seattle, WA | 2026-09-16 | not_requested |
| 4459329723 | Senior Data Engineer (USASOC-CDAO) | Kentro | Fayetteville, NC | 2026-09-16 | not_requested |
The run finished with the status message: Delivered 5 public job_record(s).
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
job_id(string) — Source-native numeric posting identifier.title(string) — Published role title.company(string) — Published hiring-organisation name.location(string/null) — Published job location.posted_at(string/null) — Source-published posting date or timestamp.job_url(string) — Canonical public posting URL.salary_text(string/null) — Salary text when the public card supplies it.employment_type(string/null) — Buyer-selected employment type or null when unfiltered.description(string/null) — Public description text when requested and available.description_status(string) — not_requested, ok, empty, gone, or block.change_type(string/null) — new_job, updated_job, or removed_from_public_search in delta mode.changed_fields(array) — Fields changed since the preceding saved baseline.first_seen(string/null) — First observation timestamp in delta mode.detected_at(string/null) — Delta detection timestamp.source_url(string) — Exact public source URL for this record.observed_at(string) — UTC observation timestamp.query(string) — Role or skill query used for this record.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 5 × $0.05 job_record = $0.27 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
Caps the run at 2 rows — about $0.12 on the Free tier ($0.02 start + 2 × $0.05). keywords narrows what the source is asked for.
3. Watch mode on a schedule
The first run seeds a private baseline and emits zero deltas; every later run emits one row per change, billed at $0.05 each.
🧾 JSON sample record
One real record from run H3mbRe6OI9NwRn2Io, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Source. The actor reads www.linkedin.com — endpoints: https://www.linkedin.com/jobs-guest/jobs/api/jobPosting/, https://www.linkedin.com/jobs-guest/jobs/api/seeMoreJobPostings/search, https://www.linkedin.com/robots.txt. Public pages and feeds only; nothing behind a login.
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent.
Watch semantics. Snapshot mode (watch_mode: false) returns a preview. Watch mode keys every record on a source-native id, stores a private baseline in a named key-value store, and on each later run emits one delta row per change (new / changed / removed). A blocked fetch is never diffed, so a source outage cannot show up as a mass removal.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each public job posting is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
What it delivers
- One structured record per public posting, keyed by LinkedIn's numeric
job_id. - Role title, hiring organisation, place, posting date, salary text when published, and the public posting URL.
- Optional public description retrieval with an explicit
description_status. - Source URL and UTC
observed_atprovenance on every record. - A bounded 500-record maximum and fail-loud handling for blocks, throttling, source-shape loss, and time-budget exhaustion.
This actor reads public logged-out job-posting pages only. It does not use accounts, cookies, profiles, people records, applicant data, or authenticated LinkedIn surfaces.
Delta mode
Set watchMode to true and schedule stateless runs. The first run writes a KV baseline and emits zero alerts. Later runs deliver only newly seen postings, changed postings, and postings absent from the public result window on two consecutive eligible runs. The source-native composite key is job_id; a maximum of 500 deltas can be delivered in one run.
Delta mode stores only its bounded baseline in a named KV store. It does not run an always-on process. A partial source read never commits a new baseline.
Honest limits
- LinkedIn can throttle, block, or change its public guest-posting HTML without notice. A blocked first page fails loudly and bills no
job_record; a later block retains delivered rows and labels the runPARTIAL. - Public result windows are not a complete census of all jobs. Ranking and availability can vary by place, query, and time.
- Salary, description, and employment type can be absent because the source did not publish them.
removed_from_public_searchmeans a posting disappeared from this public query twice; it is not proof that the employer closed the requisition.- The exact-host robots policy is re-read every run. This actor proceeds under Steve's recorded one-actor source ruling dated 2026-08-12; it never defeats a login, CAPTCHA, WAF, or paywall.
Compliance
Public logged-out job postings only; transparent NexGenWatchBot/1.0 user agent; no authentication, profiles, people data, CAPTCHA solving, browser spoofing, paywall circumvention, or anti-bot defeat. Comply on objection.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
⏰ Set it on a schedule
A single run is a snapshot. The value is the feed: open the actor in Apify Console → Schedules → Create new, add this actor with input 3 above (watch_mode: true), and pick a cadence:
- Daily —
0 7 * * *(07:00 UTC): catch changes within a day. - Weekly —
0 7 * * 1: a Monday digest.
Each run is independent; keep the same input on the schedule so the results stay comparable. Schedules can also POST results to a webhook (Console → Integrations).
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Public job posting (job_record) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price (watch mode, one delta per change):
- 5 public job postings: $0.02 start + 5 × $0.05 = $0.27
- 25 public job postings: $0.02 start + 25 × $0.05 = $1.27
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 512 MB.
Yield on the sample run: Delivered 5 public job_record(s).. maxResults is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public, logged-out pages and feeds published by www.linkedin.com. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. The source (www.linkedin.com) is read logged-out; the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input (in watch mode the first run always seeds the baseline and returns zero deltas); BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxResults (default 5). Raise the cap for a bigger run; you pay per delivered row.
Q: What does watch mode remember between runs?
A: A private baseline of source-native record ids in a named key-value store. Each later run diffs the live source against it and emits only changes.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs except the watch baseline. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job feeds actors?
A: Same output shape and billing model; this one covers www.linkedin.com. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxResults) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
- First watch run shows no deltas → expected: it seeds the baseline; changes appear from the second run.
🔗 Related Actors
- JazzHR Job Feed — Any Employer Board — Scrape jobs from any JazzHR employer careers board. One structured record per public posting — title, location, link. No API key; pay per job
- Jobvite Job Feed — Any Employer Board — One structured jobrecord per public posting on a Jobvite employer board. You supply a tenant (or list of tenants); the actor reads that board's publi…
- Keka Careers Jobs Exporter — One structured job record per active opening from employer career portals powered by Keka Hire — title, company, location, apply link. Keyless, logge…
- Manatal (careers-page.com) Job Feed — Any Employer Board — Manatal (careers-page.com) Job Feed — Any Employer Board
- Oracle Recruiting Jobs Exporter — One structured job record per open requisition across Oracle Recruiting Cloud career sites, read from the keyless candidate-experience contract — tit…
- PageUp Careers Jobs Exporter — One structured job record per publicly listed opening from employer career sites hosted by PageUp — title, employer, location, closing date, apply li…
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


