
Reddit Scraper: Posts, Comments, Users, Search & Explore
Pricing
from $1.00 / 1,000 posts
Reddit Scraper: Posts, Comments, Users, Search & Explore
Scrape Reddit posts, full comment threads, users, communities and comment search by keyword, plus the Explore tab's recommended communities. API-grade JSON with no login or browser, unaffected by Reddit's 2026 .json shutdown. Monitor brands and keywords with only-new runs.
Pricing
from $1.00 / 1,000 posts
Rating
0.0
(0)
Developer

Tauqeer Abbas
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
Scrape Reddit posts, full comment threads, user profiles and histories, communities and their rules, and search comments by keyword, plus the communities Reddit's Explore tab recommends. Clean JSON straight from Reddit's API, with no login, no API key and no browser.
Still works after Reddit's 2026 shutdown. In May 2026 Reddit closed
its public .json endpoints to anonymous requests (they now answer 403
whatever the IP). This actor doesn't use them: it reads Reddit's
authenticated API the way Reddit's own app does. You get the same
structured data, with exact scores, upvote ratios, flairs, media and
comment trees, and no fragile page parsing.
What it scrapes
| Source | Rows |
|---|---|
Subreddits (hot, new, top, rising, controversial; any time range), r/popular, r/all, the front page | posts, optionally with their comments and the subreddit's info and rules |
| Posts (any post URL) | the post and its comment thread: text, score, depth and parent of every comment |
| Users | profile (karma, account age, verified, moderator), posts and comments |
| Search by keyword, site-wide or inside one subreddit | posts, comments (full text, with the post and subreddit), communities or users |
| Explore | the communities Reddit recommends (popular near you, hidden gems, topic picks) with subscribers and rules |
Paste any Reddit URL (subreddit, post, user, search, /explore/) or use
the name and keyword fields. Mix as many sources as you like in one run.
Why this one
- Comment search with full text. Find every comment that mentions your brand, product or competitor. Each row has the comment's full text, author, score and date, plus the post's title, score and comment count.
- Deeper comment threads. Reddit shows logged-out readers 500 comments of a thread at a time. Above that, this actor merges several comment orders (top, new, controversial, old) and reaches about 3 times more of a big thread (1,605 of a 5,050-comment thread instead of 499).
- Real monitoring. Turn on Only new rows and schedule the run: each run delivers only the posts and comments the earlier runs didn't, and you never pay twice for the same row. Monitors are remembered for 60 days, and you can keep one per brand.
- No duplicates in a run. A post found by two searches is delivered and charged once.
- Built for Reddit's rate limit. Reddit allows each IP 100 requests per 10 minutes. The actor switches to a fresh IP before that runs out, so it doesn't stall or fail on 429 errors.
- Light and cheap. Pure HTTP at 256 MB, on datacenter proxies by default. If Reddit refuses them, the run moves to residential by itself.
- Explore, the recommended communities, which no other Reddit actor offers.
Input examples
A subreddit's top posts of the week, with comments:
Monitor a brand: new comments and posts every day:
Every comment of a big thread (up to 2,000):
Users' recent comments:
Communities about a topic, with their rules:
Output
One row per post, comment, community or user. The dataType field says
which. Every row also carries source (what found it), sourceUrl,
created_at (ISO date) and scrapedAt.
Post (dataType: "post", 45 fields):
| Field | Example |
|---|---|
title, selftext | the post's title and body |
subreddit, author | espresso, KiloBrewer |
score, upvote_ratio, num_comments | 1202, 0.78, 386 |
permalink, url | the Reddit link and the linked page / image / video |
flair, flair_background_color | "[SUNDAY ONLY] Self-Promotion", #014980 |
post_hint, is_video, is_gallery, media, preview, gallery | media details and image URLs |
over_18, spoiler, stickied, locked, archived, edited | flags |
created_utc, created_at | 1792368908, 2026-10-17T22:15:08+00:00 |
Comment (dataType: "comment", 34 fields): body, author, score,
depth, parent_id, post_id, post_title, post_permalink,
subreddit, is_submitter (the post's author), controversiality,
edited, distinguished, permalink, created_at. Comment search rows
add post_score and post_num_comments.
Community (dataType: "community"): name, title, subscribers,
public_description, description, subreddit_type, over18,
created_utc, icon, banner, url, and rules (name, description,
kind) when Include community rules is on.
User (dataType: "user"): name, link_karma, comment_karma,
total_karma, created_utc, verified, is_mod, is_employee,
is_gold, is_suspended, description, icon, url.
Pricing
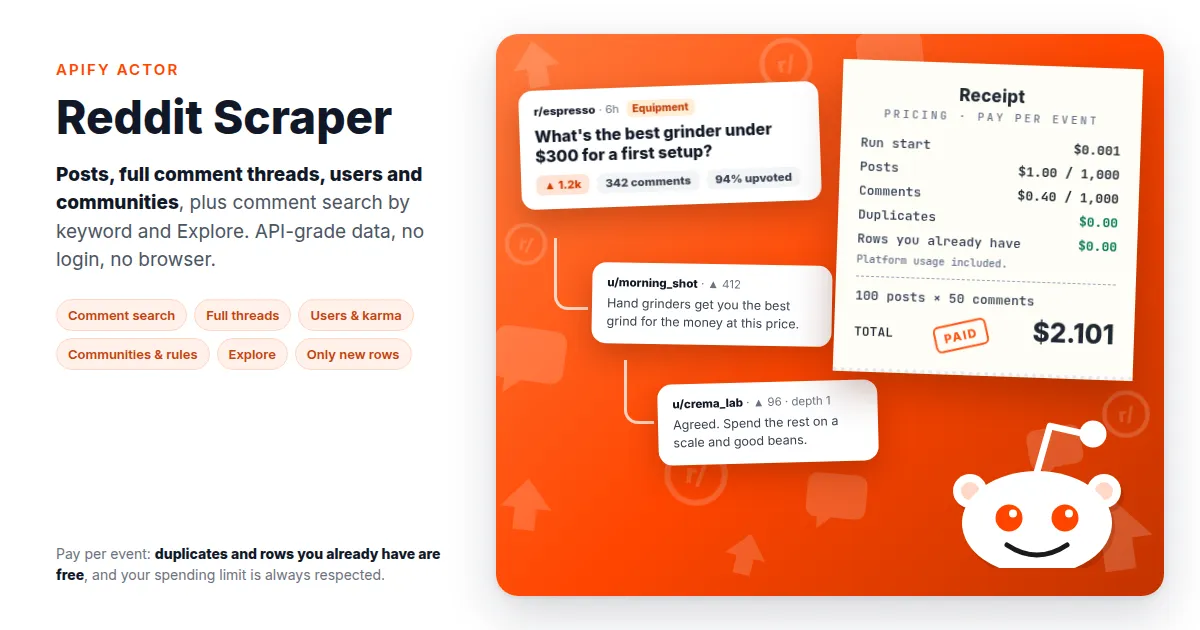
Pay per row: platform usage is included, so you never pay Apify compute or proxy traffic on top.
| Event | Price |
|---|---|
| Run start | $0.001 |
post | $1.00 / 1,000 |
comment | $0.40 / 1,000 |
community | $1.00 / 1,000 |
user | $1.00 / 1,000 |
Example: 100 posts with 50 comments each = $0.001 + 100 × $0.001 + 5,000 × $0.0004 = $2.10 for 5,100 rows.
Duplicates, filtered rows and rows a monitor already delivered are never charged. Your spending limit is always respected: the actor stops before exceeding it.
Good to know
- About 1,000 per listing. Reddit ends every listing and search at
roughly 1,000 results. For more, combine sorts (
new,topby time range) or keywords. - NSFW, private and quarantined communities aren't readable without a Reddit account. They're skipped with a note in the log and aren't charged.
- Comment search reads about 10 comments per page, so it's slower per row than post search. Use the New sort with Comments after for monitoring: the search stops at the first older comment.
- Deleted content shows as
[deleted]/[removed], as on Reddit.removed_by_categorysays who removed a post. - Dates: Posted after and the other date filters take a date
(
2026-10-01) or a relative time (7 days,24 hours,1 month).
Use it from your tools
Run it from the Apify API, Make, Zapier, n8n or Google Sheets, or call it from AI agents through the Apify MCP server. Export to JSON, CSV, Excel or HTML.


