

Global Job Postings — live ATS index
Pricing
from $3.00 / 1,000 results
Global Job Postings — live ATS index
Live job postings and enriched employer records, read directly from the career systems of tens of thousands of companies. Filter by country, technology, seniority, workplace. Every field carries its source.
Pricing
from $3.00 / 1,000 results
Rating
0.0
(0)
Developer
Nivult
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
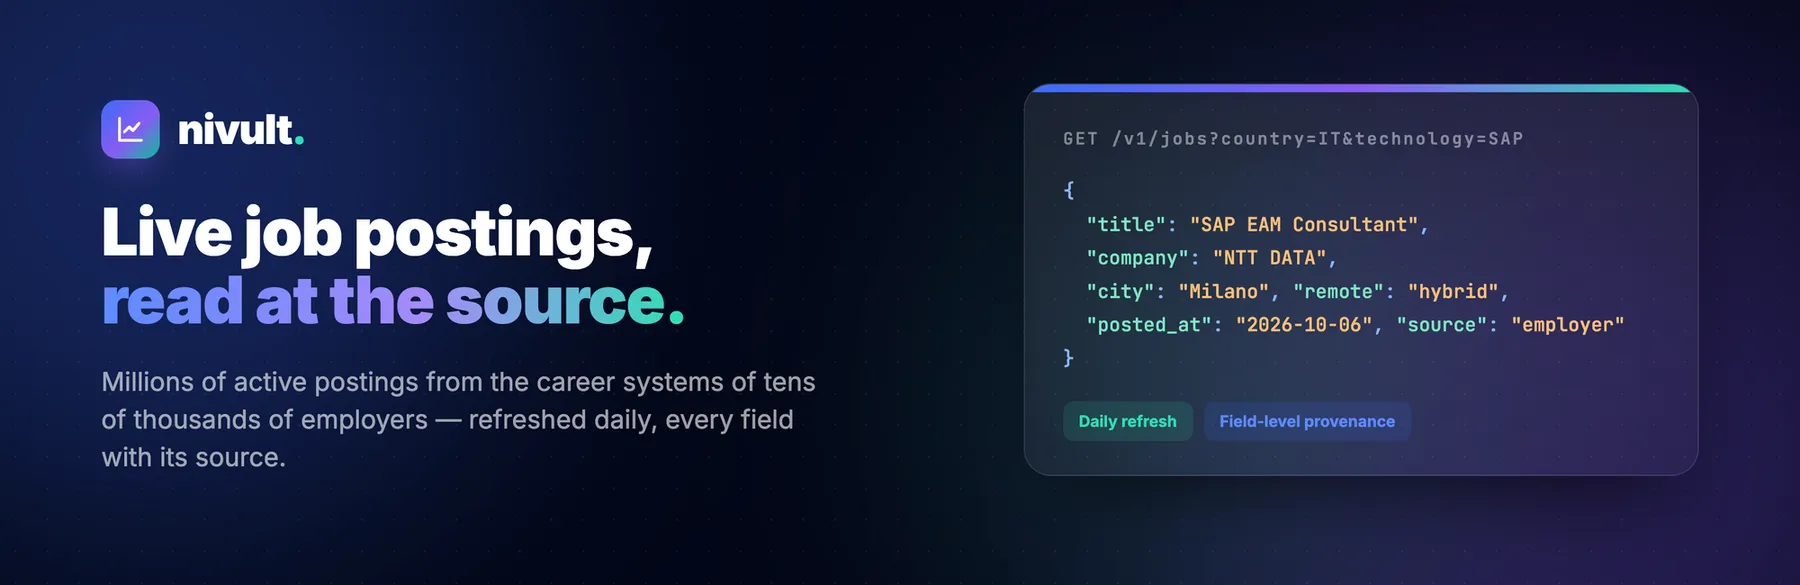
Not another scraper. A maintained index.
Most job actors ask you for career-site URLs, then spend minutes scraping them, then hand you raw rows. This Actor asks for nothing but filters — and answers in seconds, because the work is already done: we read the career systems of tens of thousands of employers every day, whether you run us or not.
| Scrape-on-demand actors | Nivult Dataset API | |
|---|---|---|
| You supply | career-site URLs you must know | nothing — just filters |
| Answer in | minutes of scraping | seconds |
| Closed postings | stay in your data forever | verified closed, daily |
| Enrichment | raw title + link | seniority, workplace, language, skills, salary signal |
| Company layer | a name string | spine record: industry, size, legal identity, tech stack |
| Provenance | none | field-level, on every row |
What does the Nivult Job Index do?
We read job postings directly from the career systems of tens of thousands of employers — Workday, Greenhouse, Lever, SmartRecruiters, SuccessFactors and dozens more — across 240+ countries and territories. Refreshed daily; closed when the posting leaves the employer's own page.
Filter by what matters:
- 🌍 Country — 240+ countries and territories, ISO-2
- 🧩 Technology — postings that mention SAP, Snowflake, Kubernetes… in the text
- 🎯 Seniority & workplace — intern to head, remote / hybrid / on site
- 🗓️ Posted-after date — only what is fresh
- 🏢 Company mode — industry, size band, legal identity from public registries, measured technology stack
How to use it
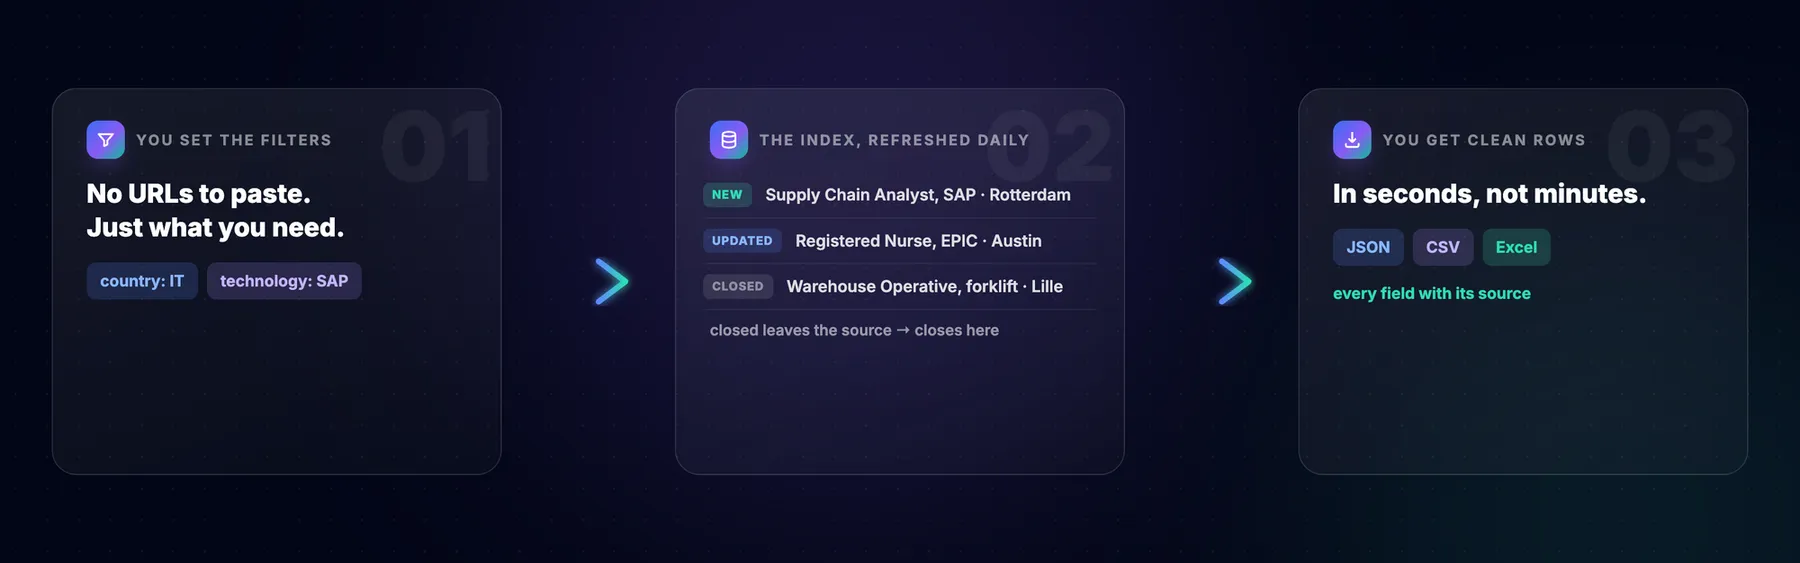
- Choose Job postings or Companies.
- Set your filters — country, technology, keyword, seniority, workplace, posted-after.
- Run, and download the dataset as JSON, CSV, or Excel — or read it through the Apify API.
Every result set is a slice of the same index we sell as a full daily feed.
How much does it cost — and why is a row worth more here?
$3 per 1,000 rows received — nothing for empty filters, nothing upfront. On Apify's free plan, your monthly free usage covers your first hundreds of rows.
A fair question: raw-scrape actors charge cents per thousand. A raw row is a title and a link that may be dead by tonight. Our row is an enriched, verified record: classified seniority and workplace, measured skills and language, salary signal, a link to the company's spine record, and the source of every field — closed out of the index the day it leaves the source. You are not paying for a scrape; you are paying for the maintenance.
For the full daily export or a custom feed (millions of rows, JSONL, daily deltas), write to us — the Actor page links to the contact.
What does the output look like?
A real row from the index, verbatim (the posting went live the same day):
And company mode is a different league — one record per employer, with every enrichment carrying its own source:
Company mode returns one record per employer: name, domain, industry, size band, legal form from public registries, technology stack, and the count of live postings.
Explore the Nivult family
- Job Postings Dataset — the full index — every ATS, every filter, company mode
- Workday Jobs Dataset — every Workday career site, daily
- Greenhouse Jobs Dataset — every Greenhouse board, daily
- Jobs by Technology — postings matched by the stack in the text
FAQ
Where does the data come from? From the employers' own career systems — the page where the company itself publishes the opening. A closure is verified: the posting left the source.
How fresh is it? The index refreshes every day; new postings land within 24 hours of appearing at the source.
Is this legal? We read public pages that employers publish for candidates, respect robots directives and rate limits, and honor removal requests. The company records enrich public postings with public registries.
Can I get the data through an API instead of the UI? Yes — the dataset of every run is readable through the Apify API, and the full index has its own REST API with daily JSONL exports. Ask us through the store page.
Something looks off — who do I tell? Write to us from the store page. We read everything, and we fix fast.


