
Google Jobs Scraper - Job Postings API
Pricing
$2.00 / 1,000 jobs
Google Jobs Scraper - Job Postings API
Google Jobs and job postings scraper: get job title, company, location, posted date, salary, full description and every apply link for any search. Deduped with a stable job id. US, UK, Canada, India, Singapore, Brazil, Mexico.
Pricing
$2.00 / 1,000 jobs
Rating
0.0
(0)
Developer

Redomic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 hours ago
Last modified
Categories
Security
Limited permissionsShare
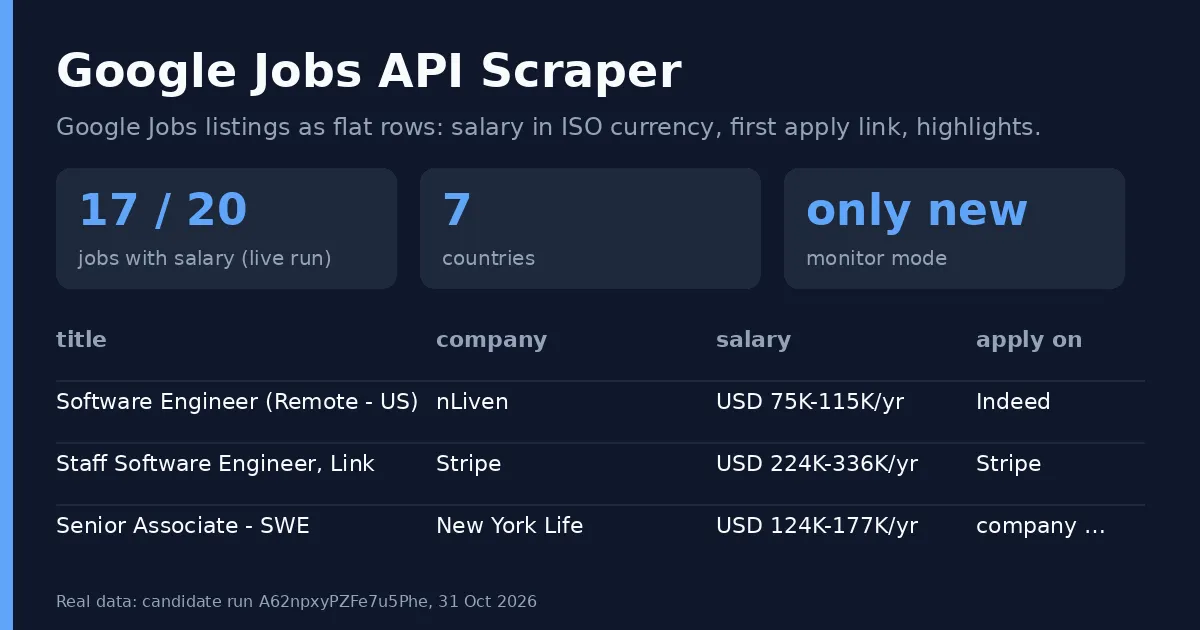
For recruiters, job boards and labour-market analysts who need fresh postings as data: enter one job search or up to ten at once, plus a location, and get the matching Google Jobs listings as flat rows (title, company, location, workplace type (Remote/Hybrid/Onsite), posting date, salary as numbers with an ISO currency, job type, full description and the first apply link in its own column, plus every other apply link), with a stable job id for dedupe across runs and across the searches in one run.
Reliability: 0 of 4 runs failed/timed out/aborted in the last 30 days (0.0%). See ./CHANGELOG.md#06.
Why this one
- Bounded run time: Each run has a time budget (120 seconds by default) and every request has a timeout. When the budget runs out you keep what was found, and a status row says
partial. - Salary as numbers:
salaryMin,salaryMax, an ISO 4217salaryCurrency(USD,CAD,GBP...) andsalaryPeriod. When Google shows no salary chip, a pay range written in the title or description ("Day Rate: £400-£495 per day") is read instead, andsalarySourcesays where it came from. - Pay per job, nothing else: You are charged only for job rows delivered. Searches, retries, duplicates and status rows cost nothing. There is no start fee and no per-page fee.
- No bill shock:
maxJobscaps the rows (and the price) of every search, and your run's maximum cost is respected: the run stops cleanly at it. - Real apply links: Apply links point at the employer or job board page (Indeed, LinkedIn, Lever, Workday and so on), not at Google redirects, and duplicates are removed.
- Personal data left out: By default, recruiter and contact person names, personal email addresses, and phone numbers next to them are removed from descriptions. Company names and role mailboxes such as careers@ or hr@ stay.
- No wasted pages: Extra Google searches only run while they keep finding new jobs (see below).
Countries
United States, United Kingdom, Canada, India, Singapore, Brazil and Mexico, each checked with a real jobs page. Google has turned the jobs view off in the EU and EEA, so EU countries cannot be searched. Australia and Japan are not offered: when checked on 2026-10-30, Google did not serve the jobs view there.
Output
One row per job, then one status row per search. Example values come from Google pages captured on 2026-10-30 (the default input's first page). When queries holds several searches, each job row's query says which search found it, and the status rows at the end say how each search went.
| Field | Example | Meaning |
|---|---|---|
jobId | AIPUj2dXDu-T_aYiAAAAAA== | Google's job id. The same posting keeps it across runs |
fingerprint | cc5f99e723c63129 | Hash of title, company and location, for matching across sources |
title | Forward Deployed Software Engineer (Recent Graduate) - New York | Job title |
company | CrossCountry Consulting | Employer |
location | New York, NY | The job's location as Google shows it (Anywhere for remote) |
workplaceType | Onsite | Remote, Hybrid, Onsite, or null (derived from location and title) |
via | Indeed | Site Google took the listing from |
postedText | 3 days ago | Posting age as shown (missing on some listings) |
postedAt | 2026-10-27 | Posting date worked out from postedText |
ageDays | 3 | Days since posting |
salaryText | $110K–$140K a year | Salary as shown by Google, or the range read from the title or description |
salaryMin, salaryMax | 110000, 140000 | Parsed salary range |
salaryCurrency, salaryPeriod | USD, year | ISO 4217 currency code (a bare $ follows the country: CAD on Canada, SGD on Singapore) and period (hour, day, week, month, year; null when not stated) |
salarySource | chip | chip (Google's salary chip), title or description (read from the text); null when no pay is shown |
jobType | Full-time | Employment type |
qualification | No degree mentioned | Degree chip, when shown |
benefits | ["Health insurance"] | Benefit chips |
description | By joining our team as a Forward Deployed Engineer (FDE), you will serve as... | Full job description, line breaks kept |
highlights | {"qualifications": ["Ability to learn continuously, ..."], "benefits": [...], "responsibilities": [...]} | Google's job highlights |
applyUrl | https://www.indeed.com/viewjob?jk=635bc04355b2a209&... | The first apply link, flat, for spreadsheets |
applySource | Indeed | Site of the first apply link |
qualificationsText, responsibilitiesText, benefitsText | Ability to learn continuously, ... | Google's job highlights as plain text, one item per line |
applyLinks | [{"source": "Indeed", "url": "https://www.indeed.com/viewjob?jk=635bc04355b2a209&..."}, {"source": "Lever", "url": "https://jobs.lever.co/crosscountry-consulting/..."}] | Deduped apply links |
sourceSites | ["Indeed", "Built In NYC", "ZipRecruiter", "Lever", "LinkedIn"] | Every site the job is listed on |
googleUrl | https://www.google.com/search?ibp=htl;jobs&q=software+engineer+New+York&htidocid=AIPUj2dXDu-T_aYiAAAAAA%3D%3D&hl=en-US | The job on Google |
query | software engineer | Your query |
searchLocation | New York | Your location input (null when empty) |
country | US | Your country preset |
searchQuery | software engineer New York | Exact text sent to Google for the page the job came from |
searchVariant | null | Refinement that found the job (since yesterday, full time, senior...); null for the plain search |
scrapedAt | 2026-10-30T10:00:00+00:00 | When the row was scraped (UTC) |
firstSeenAt | 2026-10-30T10:00:00+00:00 | Monitor mode only (onlyNewJobs: true): when this job was first seen by this search (UTC, ISO 8601); the same stamp is kept in the monitor history for later runs |
The status row has these fields (filter on _status to separate it from the jobs):
| Field | Example | Meaning |
|---|---|---|
_status | ok | ok; partial (stopped by the time budget or spend limit, some pages failed, or the page layout looked wrong); empty (Google has no jobs for this search); blocked (Google refused every attempt); error (Google returned a jobs page the parser could not read; the run fails so it gets fixed) |
query, searchLocation, country | software engineer, New York, US | Your input |
rows | 20 | Job rows returned |
pagesFetched | 3 | Google pages requested |
pagesFailed | 0 | Pages that failed after retries |
stopReason | maxJobs | Why the search stopped: maxJobs (reached your limit), time budget, spend limit, no jobs for this search (page one was empty), first page not full (page one had under 9 jobs), first page failed, low yield (refined searches stopped paying off), no new jobs (4 refined searches in a row found nothing new), blocked (most pages failed), all refinements tried, or parser found no jobs on a jobs page. It starts with degraded parse; when most jobs on a page missed company, location or apply links, and ends with ; last error: ... when pages failed |
Input
| Field | Type | Default | Meaning |
|---|---|---|---|
query | string | software engineer | The job search, as you would type it into Google Jobs, for example software engineer. Used when queries is empty |
queries | array of strings | [] | Up to 10 job searches run in order in one run, for example ["software engineer", "data analyst"]. Leave empty to use query. All searches share location, country and the filters below and one time budget; a job found by an earlier search is not returned again under a later one. maxJobs applies per search, and one status row is written per search |
location | string | "" | City, region or remote, as plain text. Empty searches the whole country (outside the US the country name is added to the search, since Google returns nothing for a bare query there) |
country | enum | US | Google edition: US, GB, CA, IN, SG, BR, MX |
datePosted | enum | any | any, today (since yesterday), 3days, week, month |
jobType | enum | any | any, fulltime, parttime, contract, internship |
maxJobs | integer | 50 | Upper limit on job rows per search, 1 to 200. See below for how many a search can really reach |
timeBudgetSecs | integer | 120 | Total budget for the whole run (60 or more), shared by every search in queries; stop at this time and keep what was found |
includeContactNames | boolean | false | Keep recruiter and contact names in descriptions |
onlyNewJobs | boolean | false | Monitor mode: return (and charge) only jobs that earlier runs of the same search have not delivered; each delivered row carries firstSeenAt, when it was first seen |
remoteOnly | boolean | false | Return only remote jobs (workplaceType is Remote: location "Anywhere" or "Remote" in the title or location) |
jobIds | array of strings | [] | Detail lookup instead of a search: Google job ids or Google Jobs URLs from an earlier run; returns only those jobs (see below). Leave empty for search mode |
Example:
Several titles in one run:
Each search runs in turn, rows are tagged with the search that found them in query, and a posting that matches two searches is returned once, under the first one. You pay only for rows delivered.
How it gets more than 10 jobs
Google shows about 10 jobs per search. To reach maxJobs the Actor runs refined versions of your search, the same ones Google's own filter chips use (posted since yesterday, last 3 days, full time, contract, senior, remote and so on), and keeps only jobs it has not seen yet. Every refinement still matches your query, location and filters. The first search plus its refinements make at most 23 Google searches when datePosted and jobType are both any (4 date windows, 4 job types, 8 seniority/remote words, 6 job type and date pairs), 13 when exactly one of them is set (the refinements of the filter you set are skipped, and so are the pairs), and 9 when both are set (the 8 seniority/remote words only). At about 10 jobs a page that is at most about 230 jobs before overlap; after duplicates are removed a search usually reaches far fewer, and maxJobs stops at 200.
Refinements only narrow your search, so the Actor does not run them when the first page has fewer than 9 jobs, and stops them as soon as a group of refined searches averages fewer than 2 new jobs each, or 4 in a row find nothing new. It also stops at maxJobs, at the time budget and at your spend limit. A narrow search (a rare role in a small town, or datePosted: today) often ends after the first page; the status row then says ok with the number found.
Duplicates are removed by jobId and by fingerprint (same title, company and location), including across the searches in one run. Two separate postings that look identical (same title, company and location under two Google ids, for example the same role advertised twice) come back once.
Job details lookup
For pipelines that already hold Google job ids (saved from an earlier run, or in a CRM): pass them in jobIds and get back only those jobs, with the full description and every apply link, instead of re-running a search. Each entry can be a bare jobId or a full Google Jobs URL (the googleUrl of an earlier row); the id is read from its htidocid parameter. One Google page is fetched per id, in the order given, and capped by maxJobs like a search. query, location, datePosted, jobType and remoteOnly are ignored in this mode; country picks the Google edition. You pay per job row delivered, as usual; an id Google no longer serves gives no row and costs nothing (a run where none of the ids are found ends empty).
Example input:
Real output for that id, from the page captured on 2026-10-30 (the same row shown in the Output table above):
| Field | Value |
|---|---|
jobId | AIPUj2dXDu-T_aYiAAAAAA== |
title | Forward Deployed Software Engineer (Recent Graduate) - New York |
company | CrossCountry Consulting |
location | New York, NY |
postedText | 3 days ago |
salaryText | $110K–$140K a year |
description | 3,671 characters, starting By joining our team as a Forward Deployed Engineer (FDE), you will serve as... |
applyLinks | 8 links, first {"source": "Indeed", "url": "https://www.indeed.com/viewjob?jk=635bc04355b2a209&..."} |
The status row ends ok with stopReason: "all job ids tried", rows: 1, pagesFetched: 1 and jobIds: ["AIPUj2dXDu-T_aYiAAAAAA=="].
Pricing
job: $0.002 per job row delivered. No start fee. 1,000 jobs ≈ $2.00; a daily 50-job watch ≈ $3 a month.
Tips
- Phrase the query like a person would:
senior react developer fintech,warehouse jobs no experience. - Daily monitoring recipe: save a task with
onlyNewJobs: true(anddatePosted: "week"to keep each run small), schedule it every morning in Apify Console, and add a "run succeeded" webhook to Slack, Make or n8n, or export the dataset to Google Sheets. Each run returns only jobs you have not received before, each stamped withfirstSeenAt, and you pay only for those; the status row says how many were already delivered. - Do not use the data to build a competing search engine. Respect the terms of the sites you apply through.
FAQ
- Why only about 10 jobs on some searches? Google shows about 10 jobs per search; the Actor widens with refinements only while they keep finding new jobs (see above). A narrow search can end after the first page.
- Is salary always filled? No. Google shows a salary chip on some listings; otherwise the Actor reads a range written in the title or description. When neither has one, the salary fields are
null: nothing is estimated. - Can I search the EU? No. Google has switched the jobs view off in the EU and EEA.
What this does not do
It does not log in anywhere, open LinkedIn or Indeed pages, or collect applicant data; it reads Google's public jobs view only. It does not search EU/EEA countries, Australia or Japan. It does not estimate missing salaries.
Sibling Actors: Greenhouse Jobs Scraper with Salaries (every open job on a company's Greenhouse careers board, with published pay ranges) and Google Trends.
Other languages
Español
Escribe una búsqueda de empleo y una ubicación y obtén los anuncios de Google Jobs como filas: puesto, empresa, ubicación, fecha de publicación, salario, tipo de empleo, descripción completa y todos los enlaces para postularse, con un id estable para quitar duplicados entre ejecuciones. Para usarlo, indica query (por ejemplo software engineer), location (por ejemplo New York) y country, y pulsa Start. Pagas solo por cada empleo entregado.
Deutsch
Gib eine Jobsuche und einen Ort ein und erhalte die passenden Google-Jobs-Anzeigen als Zeilen: Titel, Firma, Ort, Veröffentlichungsdatum, Gehalt, Anstellungsart, vollständige Beschreibung und alle Bewerbungslinks, mit einer stabilen Job-ID zum Entfernen von Duplikaten über mehrere Läufe. So startest du es: query (zum Beispiel software engineer), location (zum Beispiel New York) und country ausfüllen und auf Start klicken. Du zahlst nur pro gelieferter Stelle.
Français
Saisissez une recherche d'emploi et un lieu et recevez les offres Google Jobs correspondantes sous forme de lignes : intitulé, entreprise, lieu, date de publication, salaire, type de contrat, description complète et tous les liens de candidature, avec un identifiant stable pour dédoublonner d'une exécution à l'autre. Pour le lancer, remplissez query (par exemple software engineer), location (par exemple New York) et country, puis cliquez sur Start. Vous ne payez que pour chaque offre livrée.
Português
Digite uma busca de vaga e um local e receba os anúncios do Google Jobs como linhas: título, empresa, local, data de publicação, salário, tipo de contrato, descrição completa e todos os links de candidatura, com um id estável para remover duplicatas entre execuções. Para rodar, preencha query (por exemplo software engineer), location (por exemplo São Paulo) e country (por exemplo BR) e clique em Start. Você paga apenas por vaga entregue.
Use it from AI agents (MCP) and Python
AI agents. Add this Actor as a tool in Claude, Cursor, VS Code or any MCP client through the Apify MCP server. The agent reads the input schema, so a plain request is enough.
Python. pip install apify-client, then:
More from us
- Ashby Jobs Scraper with Salaries: Ashby jobs scraper for any startup careers board (OpenAI, Ramp, Notion and thousands more), with salary ranges as numbers: min, max, currency, period, plus equity and bonus flags
- ATS Jobs Search: Greenhouse, Lever & Ashby Jobs API: Search 328,000+ open jobs from 11,000+ companies on Greenhouse, Lever and Ashby in one run
- Google Trends API: Trending Now & Interest Over Time: Trending-now searches and new-trends alerts/monitoring per country with the news behind them, plus interest over time, interest by region, and related and rising queries for any keyword
- Greenhouse Jobs Monitor & Scraper: Monitor Greenhouse jobs from any company careers board (Airbnb, Stripe, Discord and thousands more)
- Lever Jobs Scraper with Salaries: Lever jobs scraper for any company's careers page (Palantir, Spotify, Zoox, Shield AI and thousands more): flat rows with title, team, location, workplace, commitment, apply link, salary as numbers and the full description merged


