
Facebook Posts & Pages Scraper
Pricing
from $4.00 / 1,000 results
Facebook Posts & Pages Scraper
Public Facebook page metadata and posts in one run. HTTP-first, tokenless by default, optional Graph API token mode for comments and deep pagination.
Pricing
from $4.00 / 1,000 results
Rating
0.0
(0)
Developer
REXREUS D.O
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
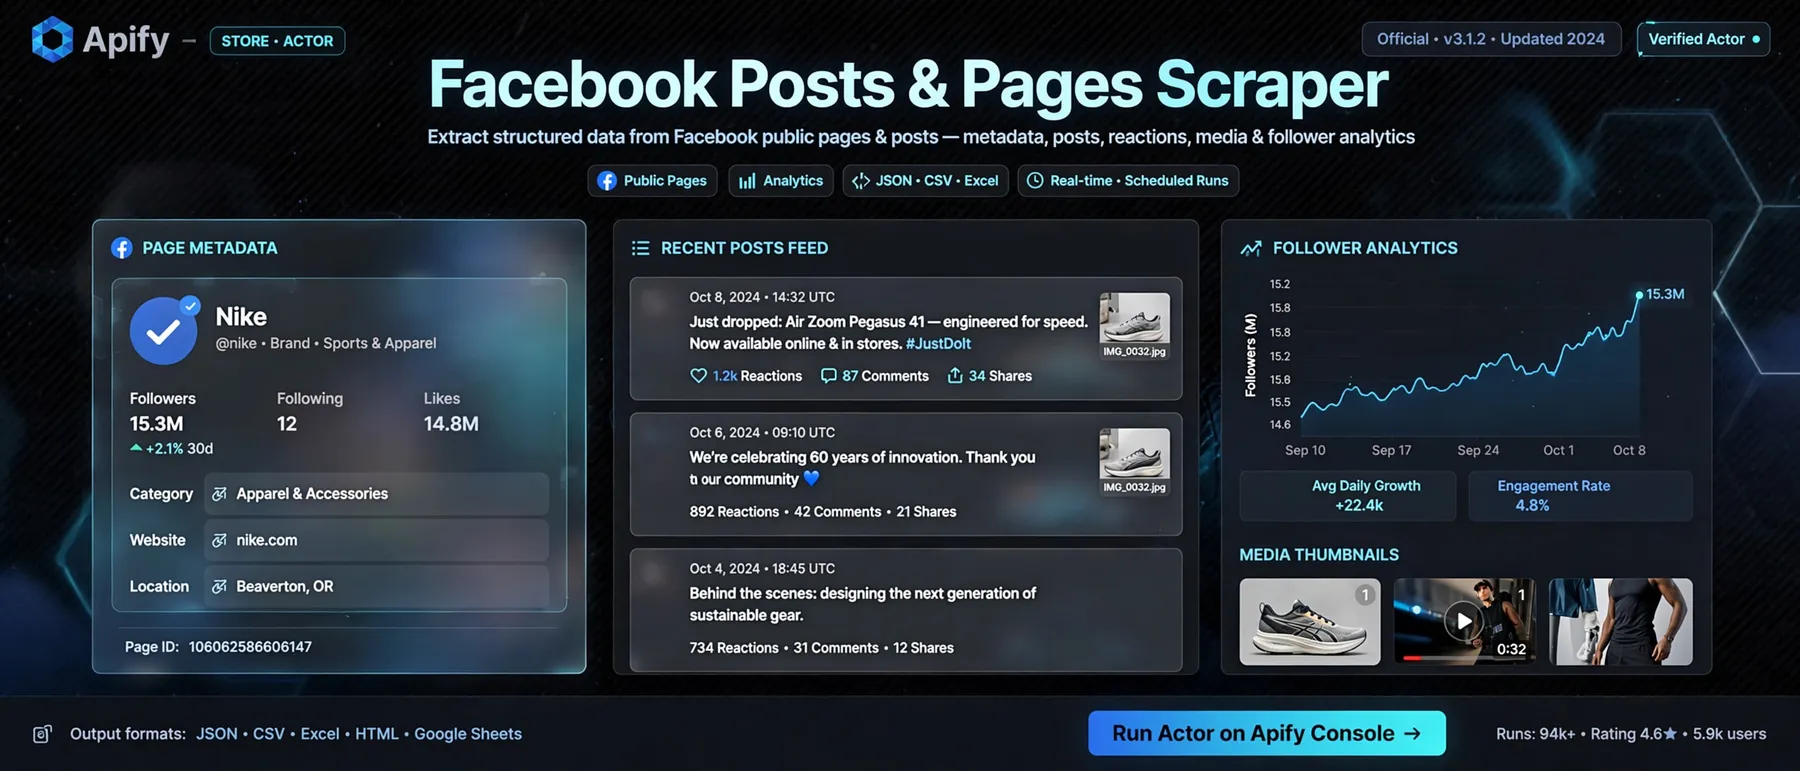
Public Facebook page metadata and posts in one run. HTTP-first, tokenless by default, optional Graph API token mode for comments and deep pagination.
Features
- 🏢 Page info — name, followers, likes, category, about, website, verified flag
- 📝 Recent posts — text, timestamp, reactions, comment count, shares, media
- 🔓 Tokenless mode — no login, no access token, pure HTTP requests
- 🔑 Graph token mode (optional) — per-emoji reaction breakdown, comments, deep pagination
- 📇 Contact extraction — email, phone, website, address from page/about (always on) and post text (opt-in)
- ⚡ Cheap — HTTP-only (no headless browser): ~0.01–0.05 CU per page
- 🔄 Incremental mode — skip posts already scraped, only emit new ones
What it does
Give it Facebook page URLs (or bare usernames like NASA). For each URL the Actor:
- Fetches the public page over HTTP (no browser, no login) and emits a page item: name, followers, likes, category, about, and publicly listed contact details.
- Collects ~1–6 recent posts per URL from the page HTML, then optionally fetches permalinks to extend coverage up to
maxPostsper page. Each post is emitted with text, timestamp, engagement counts, and media URLs. - Optionally regex-extracts emails and phone numbers from post text (off by default for PII minimization).
Optionally, provide a Graph API access token to unlock comments per post, per-emoji reaction breakdowns, and deep pagination beyond what the HTML yields.
Tokenless vs Graph token mode
| Capability | Tokenless (default) | Graph token |
|---|---|---|
| Page info & about | ✅ | ✅ |
| Recent posts (~1–6 per URL) | ✅ | ✅ |
Extended posts via permalinks (up to maxPosts) | ✅ | ✅ |
| Post reactions total | ✅ | ✅ |
| Per-emoji reaction breakdown | ❌ | ✅ |
| Comments + comment counts | ❌ | ✅ (capped by maxCommentsPerPost) |
| Deep pagination | ❌ | ✅ |
| Setup | None | Facebook Graph API access token |
| Cost per page | ~0.01–0.05 CU | Slightly higher (per-comment fetching) |
Input parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
startUrls | array (required) | — | Facebook page URLs or usernames (e.g. https://www.facebook.com/NASA or NASA). Max 100. |
maxPosts | integer | 20 | Max posts per page (1–500). Tokenless: HTML yields ~4–6; permalink fetches extend up to this cap. |
since | string | — | ISO 8601 date. Posts older than this are skipped. |
until | string | — | ISO 8601 date. Posts newer than this are skipped. |
keyword | string | — | Only keep posts whose text contains this keyword (case-insensitive). Max 200 chars. |
includePageInfo | boolean | true | Emit a page dataset item per start URL. |
extractContactsFromPosts | boolean | false | Regex-extract emails/phones from post text (not comments). Page/about contact extraction is always on. Off by default for PII minimization. |
incremental | boolean | false | Skip posts already emitted by a previous run (key-value store state). Only new posts are pushed. |
graphAccessToken | string (secret) | — | Optional Graph API token. Unlocks comments, reaction breakdown, deep pagination. Leave empty for tokenless HTTP mode. |
maxCommentsPerPost | integer | 50 | Cap on comments fetched per post in Graph mode (1–200). Prevents runaway cost on viral posts. |
proxyConfiguration | object | — | Residential proxy recommended for Apify datacenter IPs. Facebook blocks datacenter ASNs aggressively. |
Example input
Output
Each dataset item carries a type field (page or post) plus a status / httpStatus result indicator.
Page item
Post item (tokenless)
Field notes
reactions(per-emoji breakdown) andcomments(comment objects) are only populated in Graph token mode; they stay empty{}in tokenless mode.extractedContactsapplies to post items only: extracted from post text whenextractContactsFromPosts=true(defaultfalse). Page/about contact fields (email,phone,address,messenger) come from the page's own published info.httpStatusreflects the last HTTP response for the item;statusis one ofSUCCESS,PARTIAL,NOT_FOUND,BLOCKED,ERROR.
Use cases
- Brand monitoring — track followers, engagement, and recent posts on your own and partner pages; keyword-filter for mentions.
- Competitor analysis — compare categories, follower counts, posting cadence, and top-performing posts across rival pages.
- Market research — profile public pages in a niche (categories, contact info, audience size) in bulk.
- Lead extraction — harvest publicly listed emails, phones, and websites from business pages; opt into post-text contact extraction when relevant.
FAQ
Do I need to log in? No. Tokenless mode never logs in and never handles cookies. All data comes from publicly served page HTML. A Graph API token is optional and unlocks extra fields — you obtain it from Facebook yourself; the Actor never stores it.
What are the tokenless limits?
Tokenless HTML yields roughly 1–6 recent posts per URL (typically ~4–6), extendable toward maxPosts via permalink fetches. No comments, no per-emoji reaction breakdown, no deep pagination in this mode.
Does incremental mode work?
Yes — set incremental: true and the Actor records emitted post IDs in its key-value store. Subsequent runs push only new posts.
How does contact extraction work?
Emails/phones/websites/addresses found on the page and its about information are always extracted. Post text is only scanned when extractContactsFromPosts is enabled (default false, for PII minimization).
Do I need a proxy?
Strongly recommended. Facebook blocks datacenter IP ranges aggressively. Configure proxyConfiguration (residential recommended) for reliable runs — Apify's default residential proxy works out of the box.
Cost & performance
- HTTP-first — every request is plain HTTP via
got-scrapingwith browser-like headers. No headless browser, no CDP, no page rendering. - Cost: ~0.01–0.05 CU per page in tokenless mode (page fetch + up to
maxPostscheap permalink fetches). - Runtime: tens of seconds for a handful of pages; scales linearly with URLs and
maxPosts. - To keep costs down: reduce
maxPosts, usesince/untilwindows, and enableincrementalfor repeated monitoring runs.
Personal data & lawful basis
[!IMPORTANT] This Actor extracts publicly available Facebook data, which may include personal data (names of page admins implied by page names, contact details listed on pages, usernames in post text).
- PII disclosure: Page-level contact fields (
email,phone,address,messenger) are published by page owners voluntarily.extractedContactsfrom post text may contain personal contact details of commenters/authors — that is why it is off by default. - Buyer responsibility: You, the buyer, are the data controller for whatever you scrape. Under GDPR and similar laws you need a lawful basis (e.g. legitimate interest assessment) before processing personal data. Do not scrape private profiles, do not build contact lists for spam, and honor data-subject rights (deletion requests) for data you store.
- This Actor only accesses content Facebook serves without authentication. If you cannot articulate a lawful basis for your use case, do not run it.
Limitations
- Tokenless mode cannot read posts older than what the public page serves.
- Private pages, groups, and login-gated content are never accessed.
- Facebook markup changes can intermittently affect extraction — the
status/httpStatusfields on each item let you monitor success rates.
License
LICENSED — all rights reserved. © 2026 REXREUS


