Facebook Page Posts Scraper
Pricing
from $1.79 / 1,000 results
Facebook Page Posts Scraper
Facebook Page Posts Scraper — Extract Facebook Page posts including text, captions, reactions, comments, shares, timestamps, media URLs, engagement metrics, and post links. Useful for content research, competitor analysis, audience insights, and social media monitoring.
Pricing
from $1.79 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
21 hours ago
Last modified
Categories
Share
Facebook Page Posts Scraper — Post Text, Reactions and Media
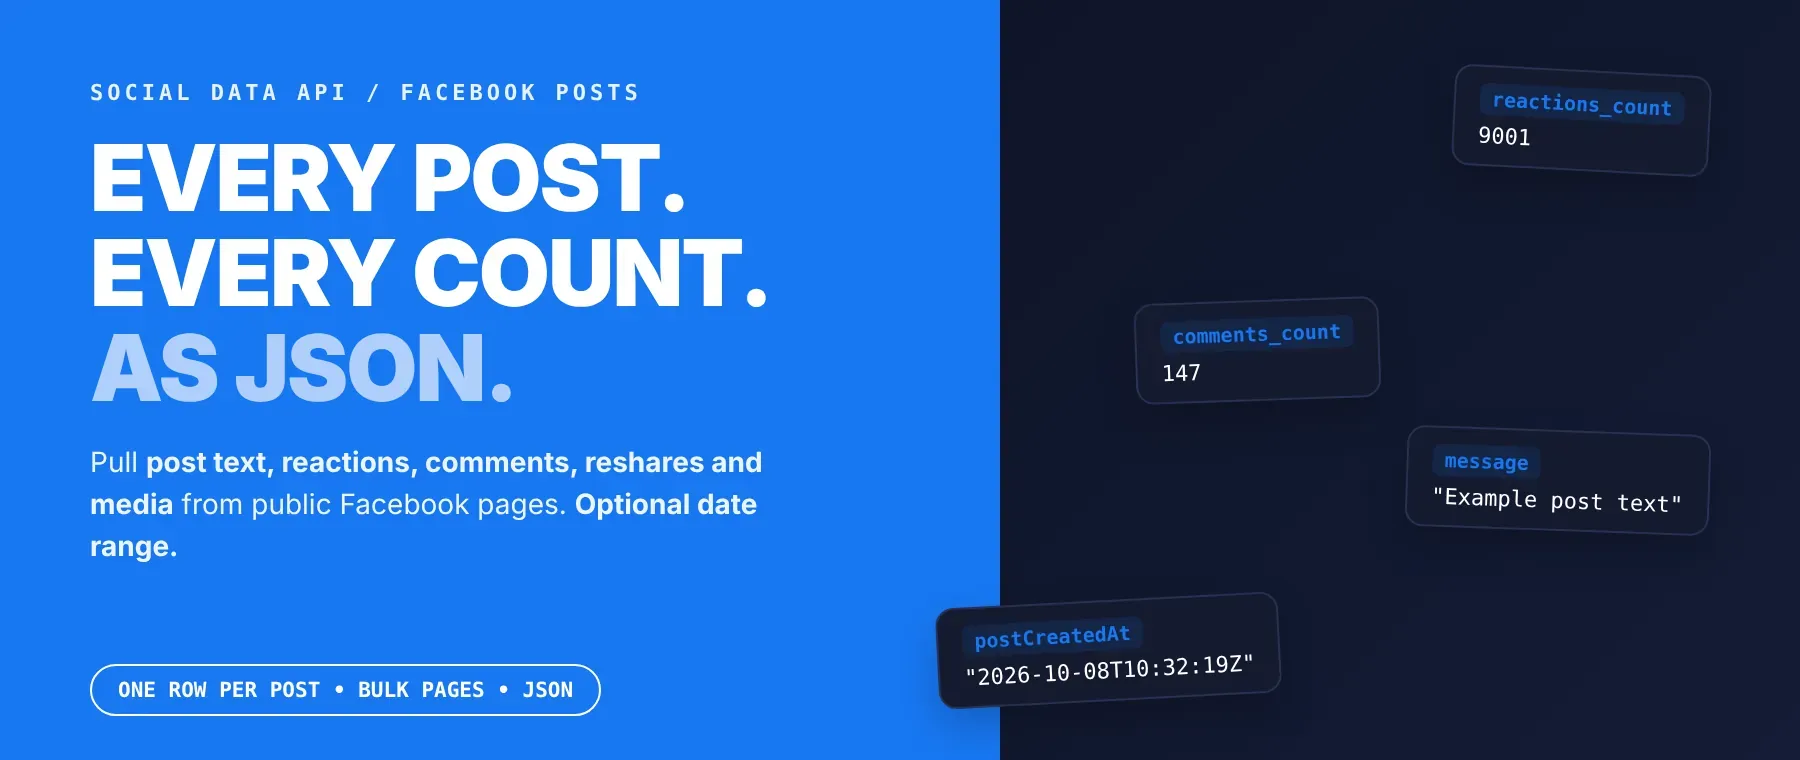
Facebook Page Posts Scraper reads a Facebook page's public timeline and returns every post as structured JSON — text, timestamp, a reactions breakdown by type, comment and share counts, plus any photo, video, album or linked content the post carries. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a brand-monitoring pipeline. No Facebook account or cookies are needed to run it. Add a page now and start tracking its next post the moment it's published.
What data can I extract with Facebook Page Posts Scraper?
Using this Facebook Page Posts API, you will be able to extract the following Facebook page post data:
| 💬 Post text | 📆 Posted at | 🏷️ Post type | 🔗 Post link |
|---|---|---|---|
| ❤️ Reactions by type | 🔢 Total reactions | 💭 Comments | 🔁 Shares |
| 👤 Author (page name + photo) | 🖼️ Image | 🎬 Video (+ file links) | 🗂️ Album photos |
| 🌐 External link | 📎 Attached post | 📅 Attached event | ⏱️ Scraped at |
| 🔗 Page URL | 🔢 Posts collected (summary row) |
How to use Facebook Page Posts Scraper
Marketers, researchers and AI agents use it to scrape Facebook page posts without opening Facebook at all — add a page and get every post back as one typed JSON row each.
Copy to your AI assistant:
Facebook Page Posts Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at the Apify MCP server with this Actor preloaded as a tool and it can call it on its own, reading a page's public posts and reactions like a Facebook page engagement scraper, without any glue code in your prompts.
Step by step
- Create a free Apify account.
- Open this Actor in the Apify Store.
- Enter the Facebook page URL or bare page name you want to track.
- Click Start.
- Download or stream your results in JSON, CSV or Excel.
How to scale Facebook Page Posts Scraper to bulk
This bulk Facebook page posts scraper takes every page you want in one run: add them all to the page list. Each page gets its own independent post cap, so ten pages at twenty posts each still finish in one run with no combined limit across pages on paid plans (the free plan has a run-wide cap, see below). For a rolling dataset, schedule the run daily or weekly and let new posts append to the same dataset, or call the Actor through the API from a cron job or pipeline step.
✨ Features
It fetches clean, structured posts from a Facebook page's public timeline. It's ideal for brand monitoring dashboards, competitor content tracking, social-listening pipelines, and research into posting patterns over time.
It extracts, per post:
- Reactions by type – like, love, haha, wow, sad, angry and care counts, not just one total.
- Post text and timestamp – the message and when it was posted, in both ISO and unix time.
- Media and albums – images, video file variants, thumbnails, and every photo in a multi-image post.
- Attachments – shared posts, linked events, and external links mentioned in the post.
- Comment and share counts – alongside the reaction breakdown, on every post.
⚡ Reads the same public timeline a logged-out visitor sees, so no Facebook account, login or cookies are ever needed.
Use cases 💡
- Brand team — track reactions by type and share counts on every new page post, weekly.
- Facebook brand page scraper for agencies — compare post text and media across several client pages at once.
- AI agent builder — index post text and reactions into a vector store for a brand-monitoring agent.
- Researcher — filter a page's timeline by date range to study a single campaign window.
Building an AI agent? Connect Facebook Page Posts Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Reads a page's post history as live JSON, not a cached snapshot. A recorded run returned 5 posts from Real Madrid's public Facebook page in 5.5 seconds, each with its full reactions breakdown.
- The numbers behind each post. This facebook page post reactions scraper returned 9,001 reactions across all 7 types, 147 comments and 37 shares on one recorded post, alongside a 5-image album.
- 28 output fields, one Actor. Post text, timestamps, reactions by type, media variants, attachments and a per-page summary row, all in one dataset schema.
⬇️ Input
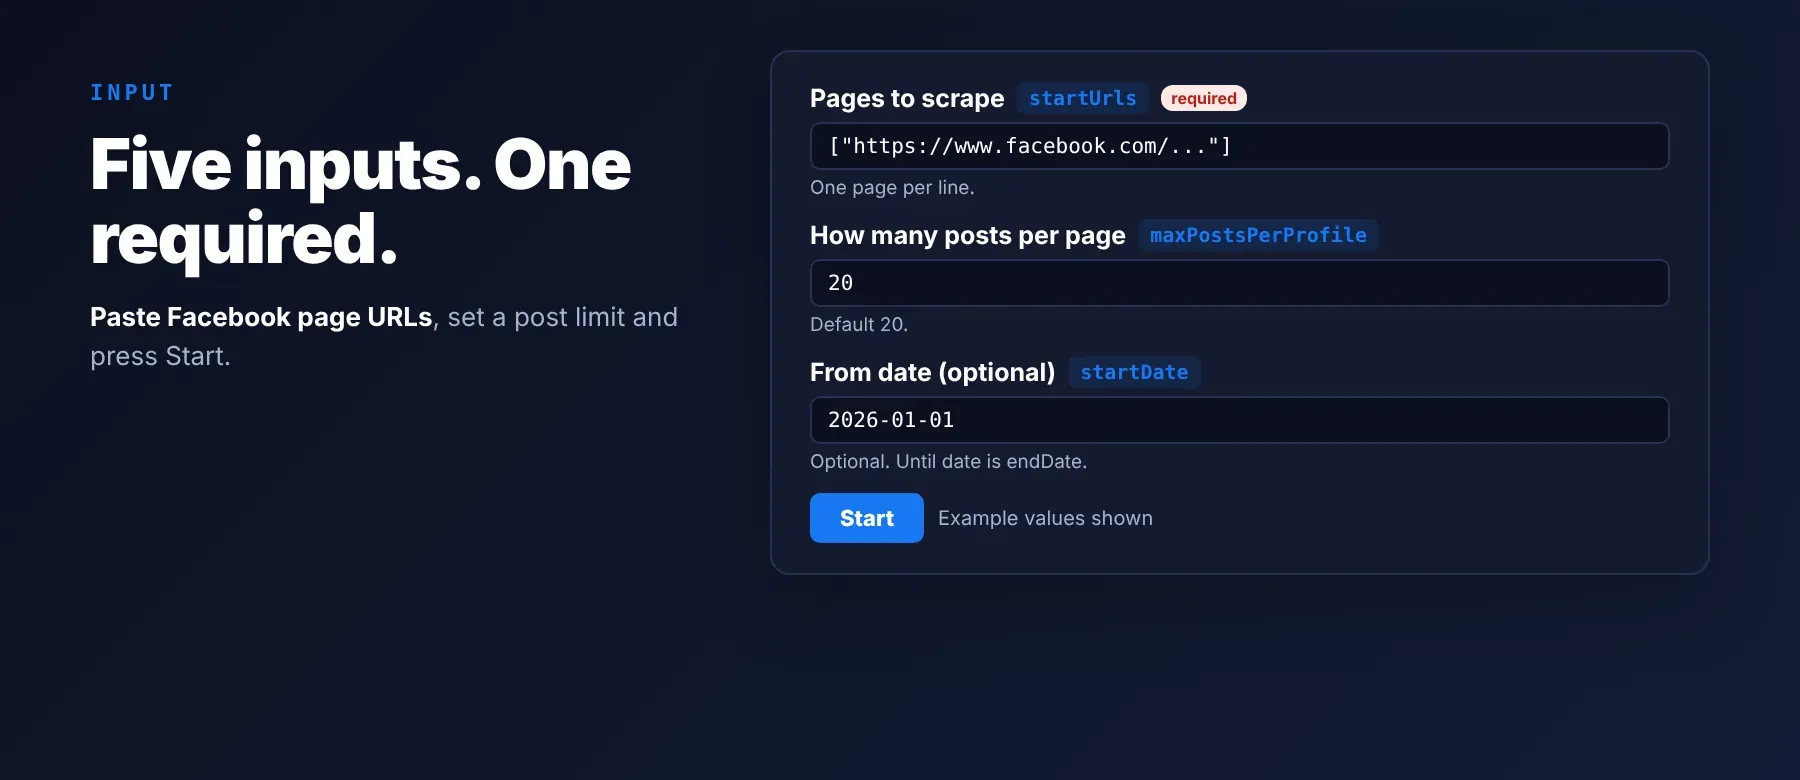
Facebook Page Posts Scraper accepts one or more Facebook page URLs or bare page names, which is the only required input.
| Parameter | Required | Type | Description | Example Value |
|---|---|---|---|---|
startUrls | Yes | array | One or more Facebook page URLs or bare page names | ["https://www.facebook.com/RealMadrid/"] |
maxPostsPerProfile | No | integer | Posts to collect per page (1–5000). Default 20 | 5 |
startDate | No | string | Only include posts on/after this date — absolute (YYYY-MM-DD) or relative ("7 days", "2 weeks"). Leave empty for no lower bound | "" |
endDate | No | string | Only include posts on/before this date — same formats as startDate. Leave empty for no upper bound | "" |
proxyConfiguration | No | object | Apify residential proxy by default; your own proxy URLs are tried first with residential fallback | {"useApifyProxy": true} |
Free plan limits
Users on the Apify free plan can fetch up to 20 posts per run (all pages together) and 200 posts per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
⬆️ Output
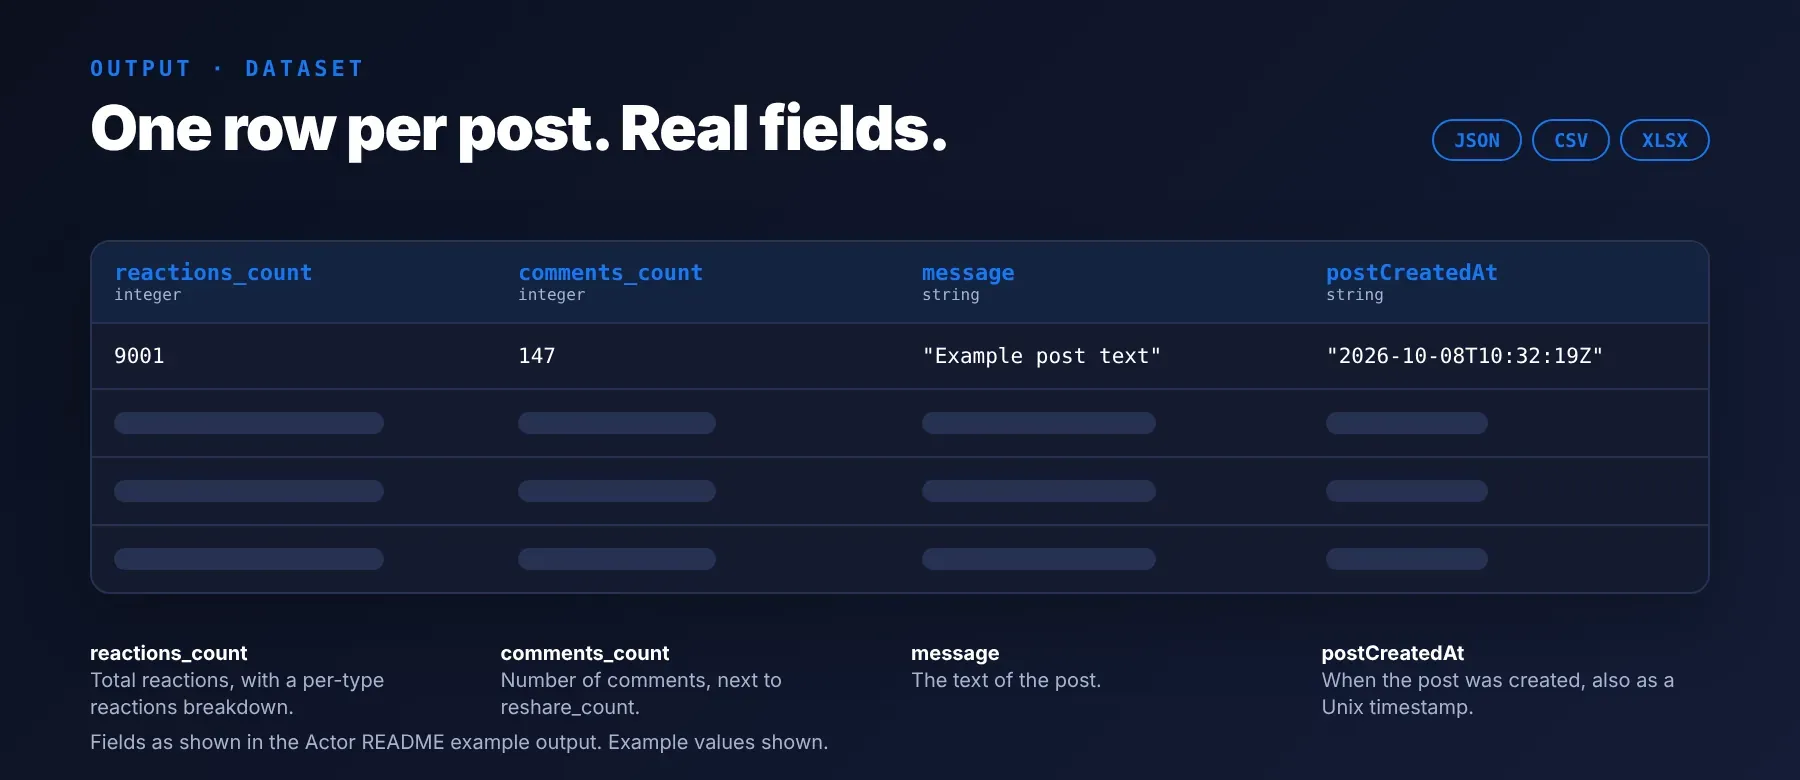
Every post is one typed, normalized JSON item with the same schema on every run — one row per post, streamed to the dataset as soon as it's confirmed, plus one short summary row once a page finishes. Only post rows are billed; the per-page summary row is not. As a facebook page timeline scraper, the per-page post cap (1–5000) applies separately to each page, with no combined cap across pages on paid plans — very high values aren't guaranteed to be fully reached, since a page's own public timeline can simply run out of further posts first, in which case the summary row's post count reports what was actually retrieved. Export as JSON (default), CSV or Excel directly from the dataset, or export Facebook page posts to CSV straight from the Dataset tab.
Example output
(Album preview shortened to 2 of 5 images and CDN query strings trimmed for readability — the real output keeps every image at full length.)
How does it work?
Facebook Page Posts Scraper reads the same public timeline a logged-out visitor sees when they open a Facebook page — no Facebook account, login or cookies are needed. Requests go through Apify's residential proxies by default, with automatic retries and a fresh connection when a request is blocked; if your own proxy URLs are supplied instead, they're tried first with the same residential fallback. The Actor only returns what's publicly visible — no private profiles and no content restricted to logged-in users. Each page is read independently, and new posts are written to your dataset as soon as they're confirmed, so the output table fills in while a page is still being read instead of only once the whole page is done. The output schema stays stable even when Facebook changes its own page layout, so your integration keeps working without changes on your end.
How do you integrate Facebook Page Posts Scraper into your stack?
It works with what you already use: a REST API callable from any language, an MCP server for AI agents, and no-code automation tools.
MCP integration for AI agents
Point your AI assistant at the Apify MCP server and it can read this Actor's output as structured JSON on its own — the command below starts the server with this Actor already added as a tool, so it can call it with your inputs right away. No glue code, no scraping logic in your prompts. Compatible with Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
In n8n, the community Apify node's "Run Actor" operation can run this Actor (picked from your own Actor list) and pass the page list and post cap as JSON, feeding the resulting post rows into downstream nodes. In Make, the Apify app's "Run an Actor or Task" module runs the same Actor, then "Get Dataset Items" maps each post into another scenario step, such as a spreadsheet row. Any LangChain agent can load a finished run's dataset with langchain-apify's ApifyDatasetLoader and use the typed post rows directly as documents — a ready facebook page posts json source for retrieval.
Is it legal to scrape Facebook data?
Scraping publicly accessible Facebook page data is generally lawful. This actor returns only publicly available data — what any visitor sees without logging in, no private profiles and no gated content. The author information reflects the page itself, typically a business or public-figure Page, so most output is organizational data governed primarily by Facebook's Terms of Service rather than personal-data law. Scraping public data is generally permissible under GDPR and similar laws, but storing and using it must still comply with local data-protection rules. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Facebook Page Posts Scraper return?
Every post comes back with its message text, reactions by type, comment count, share count, and any media it carries. See the data fields section for the full list.
Does Facebook Page Posts Scraper require a Facebook account or login?
No. Only public post data is extracted. No credentials are needed.
How fast does Facebook Page Posts Scraper run?
A recorded run collected 5 posts from one page in 5.5 seconds. Every run reads live data from Facebook's timeline at run time — nothing is served from a cache.
What happens if a page is private, deleted, or doesn't exist?
The Actor still writes a summary row for that page, with a post count of zero and a short error message describing what went wrong, while any other pages in the same run continue normally.
Can I scrape multiple Facebook pages at once?
Yes. Add every page you want in a single run; each page gets its own independent post cap, with no combined limit across pages on paid plans. On the free plan, a run returns up to 20 posts for all pages together.
Does Facebook Page Posts Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — it's available as an MCP tool. Run claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/facebook-page-posts-scraper" to register the Apify MCP server with this Actor as a tool in Claude Code, Cursor or Windsurf, or call the REST API directly from any agent that can make an HTTP request.
Does Facebook Page Posts Scraper return data in a format LLMs can use directly?
Yes. Output is typed, normalized JSON with stable field names — no HTML parsing, no selectors. Pass it straight to an LLM, index it into a vector store, or feed it to an agent tool with no transformation step.
What happens when Facebook changes its layout or updates its anti-bot system?
The Actor is actively maintained. When Facebook changes its page layout or defenses, the underlying method is updated so your calls keep returning the same JSON schema with no changes on your end.
Can I use Facebook Page Posts Scraper without managing proxies or browser infrastructure?
Yes. Proxy selection and retries run on the Actor's side using Apify's residential proxies by default. You send one request and get structured JSON back — no proxy accounts and no infrastructure to maintain on your side.
Which Facebook post fields work best for AI training data and RAG indexing?
For RAG: the post text. For training data: the reaction counts by type, comment count and share count — all typed primitives (strings, integers, objects), no normalization needed.
Your feedback
Found a bug, or a field that's missing from your results? Let us know through this Actor's Issues tab in Apify Console — active reports directly shape what gets fixed and maintained next.