
AI Job Match + LinkedIn Jobs Scraper: scored to your CV
Pricing
from $2.00 / 1,000 matched job (rules only)s
AI Job Match + LinkedIn Jobs Scraper: scored to your CV
First 25 jobs free. AI job match for LinkedIn jobs: scrapes your search, drops reposts, agencies and duplicates free, scores each job 0-100 against your CV with a recruiter note. Pay per matched job, no start fee. Free demo on any plan; live search runs on your own Apify account.
Pricing
from $2.00 / 1,000 matched job (rules only)s
Rating
0.0
(0)
Developer

Rich Minds
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
18 hours ago
Last modified
Categories
Share
Get only the new LinkedIn jobs that fit your CV, each scored 0–100 with why it fits, the skills you're missing, visa-sponsorship flags and a link to the person who posted it.
⚡ First 25 jobs free · 💵 $0.002 per matched job · 🤖 AI match ≈ $0.015 all-in ($0.01 + tokens) · 🔑 No API key needed — the AI uses the model access of your Apify plan, or your own key · ⏱️ demo in seconds, live search ≈ 3–6 min (estimate) · 🍪 no LinkedIn cookies
Try it in 30 seconds. Click Try it — the form is pre-filled with 7 sample jobs and a sample CV: free, on any plan. The live LinkedIn search runs on your own Apify account (a plan that runs Store Actors); your first 25 matched jobs are free, and jobs that fail your filters are never charged. → What a run costs · What the AI adds · Daily job alerts
⚡ At a glance
| What you get | a ranked shortlist of LinkedIn jobs that fit your CV: score, skills you match / miss, salary, sponsorship flags, who posted it and how to reach them |
| You provide | 1–5 job search terms, a location and your CV — pasted, or a link to a PDF / DOCX |
| Output | JSON / CSV / Excel dataset, best match first, plus RUN_SUMMARY (funnel + market report) and a DIGEST for Slack / e-mail |
| Typical run | 3 searches × 40 jobs = 120 scraped → ≈ 30 matched (estimate); the demo: 7 sample jobs → 3 matched |
| Cost of that run | $0.24 LinkedIn scraper + 30 × $0.01 AI match + ≈ $0.19 tokens = ≈ $0.73 ($0.30 with AI off) |
| AI tier, all in | ≈ $0.0148 per matched job: $0.01 here + ≈ $0.0048 AI tokens on your account (basic: $0.002) |
| Free tier | first 25 matched jobs per account; filtered, duplicate and below-score jobs are always free |
| Works with | Schedules, webhooks, Sheets, Slack, Notion / Airtable, n8n / Make / Zapier, MCP agents |
🎯 What this Actor does
It scrapes your LinkedIn searches, then does the reading for you — you pay only for jobs that pass your filters and your minimum score:
- A job match score against your resume — 0–100, the reasons, the skills you match and the ones to prepare.
- Junk removed for free — reposts, staffing agencies, excluded companies, too many applicants, too old or below your salary floor: never sent to the AI, never charged.
- Sponsorship and clearance flags with the quoted sentence — "We are unable to sponsor visas" is caught first.
- Who to contact — the poster's profile (else the company page) in
contactUrl, plus a recruiter note and a cover-letter hook for strong and good matches. - Only new jobs on every run, in your inbox — a daily schedule delivers and charges each job once, reposts
included, and
notifyEmaile-mails you the digest. - Ghost jobs flagged — every job carries a
ghostJobRiskwith the reasons;dropGhostJobsremoves the likely ones.
🎯 Job match score against your resume
Paste your CV into candidateProfile, or link it in candidateProfileUrl (PDF, DOCX or text — your LinkedIn
profile's More → Save to PDF works). The free rules score must-have coverage, the description's skills your CV
states, title, seniority and freshness; with AI on, the model re-scores the close calls and explains each score.
🛂 Visa sponsorship jobs and H-1B job alerts
needsVisaSponsorship: true drops every "unable to sponsor" / "U.S. citizens only" job and flags the ones that
sponsor, with the quoted sentence; targetFlags: ["sponsorship_offered"] keeps only those — the
H-1B alert Task runs it every morning.
🌍 Remote jobs — daily remote job alerts
workplace: "remote" is re-applied strictly on the returned fields (LinkedIn's AI search no longer does it
reliably); add datePosted: "past24Hours" and a salary floor for a daily alert.
🎓 New-grad and entry-level jobs
targetSeniority: ["Internship", "Entry level", "Associate"] plus excludeKeywords: ["senior", "5+ years"] keeps the
jobs a graduate can land.
👻 Ghost job detector
Reposted under a new id, open for 30+ days, 200+ applicants, no named poster: each signal is a point, and every row
gets ghostJobRisk (low / medium / high) with ghostJobReasons. dropGhostJobs: true drops the high ones
for free, before any AI call or charge.
✉️ Recruiter note and cover letter generator
Strong and good matches get a ≤ 600-character note to the poster (reachable at contactUrl) and a cover-letter
opening, built only from matchedSkills and your CV — invented numbers, salary talk and placeholders are removed in code.
👥 Several candidates in one run — for coaches and recruiters
Put a roster into candidates ([{"name": …, "candidateProfile": …}, …]): the search runs once, then each
candidate gets their own score, rows (candidateName), memory and DIGEST section — one event per job per candidate.
🆚 Why this instead of a LinkedIn Jobs Scraper?
Linkedin Jobs Scraper (curious_coder/linkedin-jobs-scraper) | AI Job Match + LinkedIn Jobs Scraper | |
|---|---|---|
| Price | $0.002 per job row + $0.00005 per start · 17,864 users / 30 days | $0.002 per matched job (≈ $0.015 all-in with AI), first 25 free, no start fee |
| What you pay for | every row, reposts and agencies included | only jobs past your filters and minimum score |
| Same 100 jobs, all in | $0.20 for 100 raw rows you still read | $0.20 scraper + ≈ 25 × $0.01 + ≈ $0.16 tokens = $0.61, ranked with reasons and notes ($0.25 AI off) |
| Filters after LinkedIn's AI search | converted filters "can't guarantee that this 100% works" | seniority, type, remote, salary, applicants re-applied strictly |
| Repeat runs | dedupes only within one run | memory by job id and company + title + location, per candidate — reposts not charged twice |
| Match to your CV | none | 0–100 score, matched / missing skills, quoted requirements |
| Sponsorship / clearance | raw text | flags with the quoted sentence; "no sponsorship" dropped free |
Other job sources buyers compare with:
| Actor | What it delivers | Unit price | What this Actor adds |
|---|---|---|---|
valig/indeed-jobs-scraper | raw Indeed rows, 3,890 users / 30 days | $0.0001 per row + $0.001 start | a per-CV score, flags, notes (Indeed source on the roadmap) |
fantastic-jobs/career-site-job-listing-api | ATS postings with global AI filters | $0.012 per row + $0.01 start | a match against your CV at $0.01 per matched job |
curious_coder/linkedin-jobs-search-scraper | classic filters, needs your LinkedIn cookies | $0.0015 per row + $0.005 start | no cookies — your account is never at risk |
💵 Pricing — what a run really costs
Pay per result: one event per matched job, nothing else — no start fee.
| Event | When it is charged | Price |
|---|---|---|
free-tier | your first 25 matched jobs on this Actor, in any mode | $0.00 |
qualified-job-basic | AI off (or the AI failed) — normalised job, rule match score, skills, flags with evidence, contact link | $0.002 |
qualified-job-ai | AI on — everything above plus the AI score and reasons, quoted requirements, recruiter note, cover-letter hook | $0.01 |
AI tier, all in: ≈ $0.0148 per matched job — the $0.01 event plus ≈ $0.0048 AI tokens billed to your Apify account at OpenRouter rates (or to your own key): 2,164 tokens per job (1,512 in / 652 out) measured in a local run, not yet on Apify, priced at the default Claude Haiku 4.5.
You are never charged for: the scraping (billed by the source Actor), jobs below minScore, jobs that fail a
filter, duplicates and reposts, jobs you already received, or an AI fallback (charged as basic). Compute is included.
How that compares — $0.002 per matched job is 1.7× cheaper than the $0.0035 median unit price of the 10 job
Actors the Store lists next to this one for "ai job match" (checked 2026-09-25), and a matched job replaces the ≈ 4 raw
rows you would otherwise read — $0.0005 per raw row equivalent. Against the four LinkedIn / Indeed / ATS scrapers of
the research set ($0.00175 median per raw row) it is at parity.
Worked example (estimate until the first live run): 3 searches × 40 jobs = 120 scraped → ≈ 30 matched with AI on:
LinkedIn scraper $0.24 on your account + 30 × $0.01 = $0.30 here + ≈ 40 AI calls × $0.0048 = $0.19 tokens →
≈ $0.73 total, $0.024 per matched job. With AI off: $0.24 + 30 × $0.002 = $0.30, $0.010 per matched job. On your
first run 25 of those 30 are free. An API call that leaves the sizes out gets the same 40 jobs per search, capped at
$2 of scraping (maxDiscoveryChargeUsd; the form starts at $0.50).
🚀 How to use it
- Click
Try it— the form is pre-filled with 7 sample jobs and a sample CV; press Start (free, any plan). - Switch the source (
sourceMode) to Search LinkedIn, type your own Job search terms (searchKeywords), Location and Posted within (datePosted). - Paste your CV into
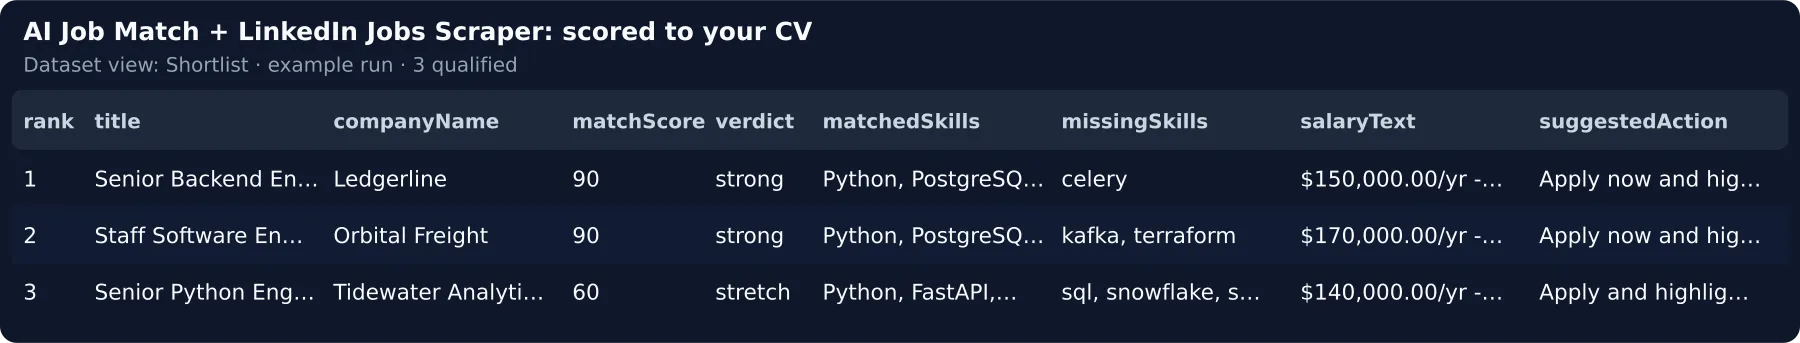
candidateProfile(or its link intocandidateProfileUrl), set the filters that matter (workplace,minSalary,needsVisaSponsorship,mustHaveSkills) and yourminScore. - Open the dataset — the Shortlist view lists the best matches first.
🤖 What the AI tier adds
The same job, AI off (qualified-job-basic, $0.002) — the demo run of storage-example/INPUT.json, 2026-09-25:
AI on (qualified-job-ai, ≈ $0.0148 all-in) — local run of storage-example/INPUT.ai.json (the form's sample
CV), 2026-09-25, with the open gpt-oss-20b model; on Apify the default Claude Haiku 4.5 fills the same fields.
That is 10–15 minutes per job of reading and writing the first message — for ≈ $0.013 more per job, tokens
included. A job the AI scores below minScore is not delivered or charged.
⚙️ Input
| Field | Type | Default | What it does |
|---|---|---|---|
sourceMode | actor | dataset | list | actor | Search LinkedIn, reuse a scraper dataset, or paste jobs (form: the free list demo). With nothing to search — {} over the API: no terms, URLs or CV — the free demo runs, nothing is charged and the scraper is never started |
searchKeywords | string[] | — | One LinkedIn search per term |
location | string | United States | As typed on LinkedIn; empty = worldwide |
candidateProfile / candidateProfileUrl | text / link | — | Your CV, pasted or as a PDF / DOCX / text link — every job is scored against it; with no term typed, its headline role is searched |
datePosted | enum | pastWeek | anyTime · past24Hours (daily alerts) · pastWeek · pastMonth |
maxJobsPerSearch | integer | 40 | Jobs scraped per term at $0.002, cut to fit the spend cap — the same for the form and the API |
maxDiscoveryChargeUsd | number | 2 (form: 0.5) | Hard cap on the scraper's charge to your account; an API call that omits it is capped at $2 |
minScore | 0–100 | 60 | The only field that changes what you pay: below it = not delivered, not charged (first in the filter section) |
workplace · needsVisaSponsorship · minSalary | enum · boolean · integer | any · false · 0 | Strict remote / hybrid / on-site filter · drop "no sponsorship" jobs · salary floor in salaryCurrency per salaryPeriod |
dropGhostJobs | boolean | false | Drop jobs with a high ghost-job risk (free) |
enableAi | boolean | true | AI match, requirements, note (needs a CV) |
candidates | object[] | — | A roster: one shared search, one score and memory per candidate |
dedupeAcrossRuns | boolean | true | Only new jobs on every run, reposts included — kept per CV |
notifyEmail | string | — | E-mail the run's digest (new jobs, top 10, links) after every run with new jobs |
📤 Output
One dataset item per matched job — export as JSON, CSV or Excel, or stream it to a webhook. The top row of the demo run (AI off):
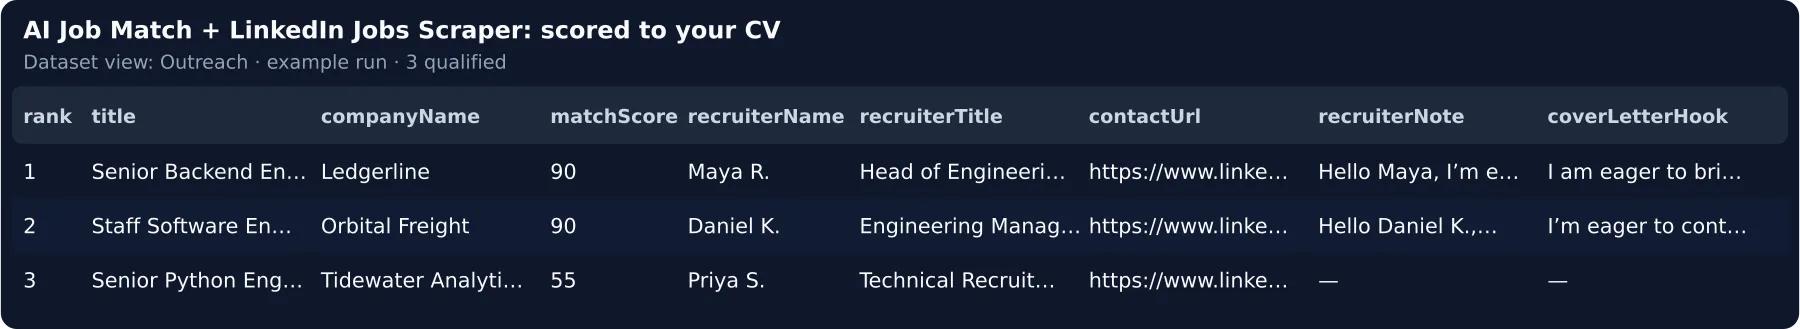
Dataset views: Shortlist (best first) · Outreach (poster, contact, note, hook) · Requirements & flags (years, quoted must-haves, sponsorship evidence, ghost-job risk) · Overview (every column).
Every run that delivered writes a DIGEST (new jobs, top 10 with links, market report — e-mailed with
notifyEmail). RUN_SUMMARY (= OUTPUT) holds the funnel, charged events, yieldByQuery, aiTokens, timing and
the marketReport over every loaded job: median salary per term, most-asked skills and your most frequent gaps.
⭐ Found it useful? A review on the Store helps others find it — it takes a minute on the Actor's page.
🔁 Run it daily — LinkedIn job alerts
- Type your e-mail into
notifyEmail— after every run with new matches the digest (new jobs, top 10 with links and why they fit, the market report) lands in your inbox; no Slack or Zapier needed. - Actions → Schedule in the Console — daily at 7:00 with
datePosted: "past24Hours". - Keep
dedupeAcrossRuns: true— jobs are remembered 60 days by id and company + title + location, so each run charges only what is new. The memory is kept per CV, so several candidates on one account never hide jobs from each other (dedupeStoreNamekeeps one memory across CV edits). - Send new matches to your application tracker (below) or Slack; the market report in
DIGESTtells you what your market pays and asks for — worth a weekly run even once you have a job.
Daily cost for a real job hunt — 5 search terms × 25 jobs posted in the last 24 hours = 125 scraped ($0.25) → ≈ 15 new matches × $0.01 + ≈ $0.10 tokens ≈ $0.50 a day, ≈ $3.50 a week (estimate), and 25 of the first matches are free.
📋 A job application tracker that fills itself
Import docs/tracker/job-application-tracker.csv (Status, Applied on, Next follow-up, Notes + the Shortlist columns)
into Google Sheets, Notion or Airtable; Integrations → Google Sheets (or a Make / Zapier webhook) appends each new
job, keyed by itemId.
🎯 Try it for your niche
A saved Task per use case (storage-example/tasks/*.json) — add your notifyEmail, run it once, then schedule it.
| Niche | What it looks for | Task |
|---|---|---|
| Remote Python job alerts (H-1B) | past 24 h, remote, ≥ $140k, sponsorship | tasks/daily-remote-python-alerts.json |
| H-1B / visa sponsorship job alerts | ML / data, only jobs that sponsor | tasks/h1b-visa-sponsorship-job-alerts.json |
| Remote job alerts in Europe | frontend, remote, ≥ €55k | tasks/remote-europe-job-alerts.json |
| New-grad software jobs | entry level, ≤ 200 applicants | tasks/new-grad-software-jobs.json |
| Career coach: junior data analysts | London, entry / associate, ≥ £28k | tasks/career-coach-weekly-data-analyst.json |
| Career coach: a roster | one search, a score per candidate | tasks/career-coach-roster-weekly.json |
| Recruiter: fintech PM roles | New York, no agencies, poster names | tasks/recruiter-candidate-fit.json |
🔌 Integrations, job search automation and API
- E-mail —
notifyEmail; Google Sheets / Slack — the Integrations tab (Shortlist view /DIGEST). - Webhook —
webhookUrlPOSTs{"event": "job.qualified", "job": {…}, "runId": "…"}per job to Zapier, Make, n8n or Notion, or withwebhookBatchSize> 1{"event": "jobs.qualified", "jobs": [{…}, …], "runId": "…"}per batch. A 429 / 5xx is retried once after 2 s; a failed POST is counted inOUTPUT.webhook.failed, never fails the run. - AI agents / MCP — first call = the free trial:
{"sourceMode": "list", "itemsList": [...]}matches the jobs you send with no scraper run, as the snippets below do. An empty{}runs the free demo.
Use it from Claude, ChatGPT or any MCP client — add Apify's MCP server with this Actor as a tool:
Then ask: "Run linkedin-job-match-ai in list mode on these jobs with my CV (free), then search with
sourceMode: actor and maxDiscoveryChargeUsd: 0.5."
Run outcomes — what your integration sees
👥 Who is it for?
| You are… | You run it to… | Start with |
|---|---|---|
| A job seeker (engineer, analyst, designer, PM) | get only new jobs that fit your CV every morning | the Remote Python Task: past24Hours, AI on |
| Someone who needs visa sponsorship | never apply to a "we cannot sponsor" job again | the H-1B Task: needsVisaSponsorship: true |
| A career coach, bootcamp or outplacement firm | rank each candidate's jobs weekly into their Notion / Airtable board | the roster Task: candidates, one memory per candidate |
| A recruiter or staffing team | find the roles a candidate fits, and who posted them | the Recruiter Task, Outreach view with contactUrl |
| An AI agent / job-search copilot | call "find jobs that fit this CV" as one MCP tool | list mode (free), then actor |
🧠 How the AI works
- One typed call per job returns the match score, the extracted requirements and the note + hook together. It sees your CV (≤ 2,000 characters), your skills, the job's fields and description (≤ 4,000 characters) and the rule findings.
- Grounded, checked in code. Skills only when the description names them; requirements, years and sponsorship only when quoted from the text; verdict from the score bands (≥ 80 strong, ≥ 65 good, ≥ 50 stretch); notes only for strong / good matches, minus any invented number, salary talk or placeholder.
- Tokens only where they matter — only jobs within 20 points of
minScorereach the model. - No keys required. Default
anthropic/claude-haiku-4.5through Apify's model access;llmProvider: "byok"+llmApiKeyfor your own OpenAI / Anthropic / Gemini / Groq key, or any OpenRouter slug inllmModel. - Graceful fallback, one rule. If the model fails — plan, key or rate limit alike — the job keeps its rule score,
reasons, regex years and flags (
aiUsed: false) and notes stay empty. It uses your free jobs except the last 5, which wait for a run where the AI works, and is then billed as basic.
🔒 Data, compliance and limits
- The source reads LinkedIn's public, logged-out job pages — no login, no cookies, your account is never touched.
- Your CV (pasted or linked) is used only for scoring, never written to the dataset; the poster's photo is dropped. A LinkedIn profile page needs a login and is not read — use its "Save to PDF" export.
- Limits: ≈ 1,000 jobs per LinkedIn search (
splitByLocationgets past it); salary, applicants and poster are missing on many jobs; skill and flag rules are English (the AI reads any language); up to 50 candidates per roster run. - Use the output within LinkedIn's terms and privacy law (GDPR, CCPA); contact posters only about their job.
❓ FAQ
How much will one run cost me? A 3-term search of 40 jobs each: $0.24 for the scraping on your account + $0.30 for ≈ 30 AI-matched jobs + ≈ $0.19 tokens ≈ $0.73 (≈ $0.30 with AI off). Filtered and below-score jobs cost nothing.
What is an AI job match? A 0–100 score of how well one job fits your CV, with the reasons, the skills you match and the ones you miss — this Actor computes it for every LinkedIn job your search returns and keeps only the matches.
Is this a LinkedIn jobs scraper? Yes and more: it runs curious_coder/linkedin-jobs-scraper on your account, then
filters, dedupes and scores what it returns — you pay us only per matched job.
Can it replace my LinkedIn job search? It runs the same search and reads every result; scheduled, it is a job alert.
How does resume job matching work here? The rules match your CV's skills against each description with word boundaries (Java never matches JavaScript); the AI scores the fit and cites the requirement or CV fact behind it.
How is this different from Jobscan, Teal or Huntr? Those are monthly seats (roughly $25–$50) where you paste each job yourself. Here search, filters and scoring run on a schedule: 100 matched jobs with AI ≈ $1.50 all-in.
What will my first real search cost? 3 terms × 40 jobs ≈ $0.24 on your account, capped by
maxDiscoveryChargeUsd ($0.50 in the form); of ≈ 30 matched jobs the first 25 are free.
How long does a run take? Demo: 3 s (measured on Apify). AI, per job, measured: 14.6–28 s per call with a
provider key (local runs); Apify's model access has not been timed on the platform yet. With your own key calls run
2 at a time, then one at a time after a rate limit: a rate-limited platform run took 61 s per job. The rate-limit
backoff is capped at 120 s per run, then the rest keep their rule score. Scraping ≈ 1–3 min per 40 jobs
(estimate). Size timeoutSecs for .call() as terms × 180 + AI jobs × 15 + 120 (AI jobs ≈ a third of the jobs
scraped): the form's 3 × 40 search ≈ 540 + 600 + 120 = 1,260 s; AI off, terms × 180 + 60. Every run
reports sourceSecs, aiSecs, aiSecsPerUnit and aiBackoffSecs in OUTPUT.timing.
Which Apify plan do I need? Any plan runs the demo and list / dataset modes. The live search and the built-in
AI need a plan that can run Store Actors; if yours cannot, the run stops at once with the reason and nothing is
charged. Your own key (llmProvider: "byok") works on every plan.
Can it spot ghost jobs? Yes — the ghost job detector rates every posting: reposted, open 30+ days, 200+
applicants, no named poster. ghostJobRisk shows the level and reasons; dropGhostJobs drops the high ones for free.
What happens if nothing matches my filters? The run succeeds with 0 rows, free; OUTPUT.stats names the filter.
What does "matched" mean? A job that passed every free filter and whose final matchScore is at least your
minScore (default 60). Only matched jobs are charged.
Will I be charged for the same job twice? Not with dedupeAcrossRuns on (default): jobs are remembered 60 days
by id and by company + title + location. In a roster, one job for two candidates is two matched jobs.
Is the data public / is this legal? Yes — public, logged-out job listings; use them within LinkedIn's terms.
🧩 More Actors from the same developer
The same pay-per-qualified-result model:
- Linkedin Intent Leads — linkedin buying intent, linkedin intent signals, social selling
- Google Reviews Insights — google reviews analysis, reputation management, google maps reviews
- Local Business Lead — local business leads, google maps scraper, google maps email extractor
- Youtube Video Research Ai — youtube outlier videos, youtube video research, youtube competitor analysis
🆘 Support
Something missing or wrong? Open an issue on the Actor's page — buyer requests are shipped first.
📝 Changelog
One line per published build, newest first — /actor-publish adds it with the commit subject.
- 0.3 (2026-09-25) —
notifyEmaile-mails the daily digest; ghost job detector (ghostJobRisk,dropGhostJobs); one free-reserve rule for every AI failure; a rate-limited AI stops after 120 s of backoff (timing.aiBackoffSecs);minScoreleads the filter section. - 0.2.2 (2026-09-25) — your own AI key (
llmProvider: byok) runs 2 calls at a time and one at a time after a rate limit, so a free-tier key still scores the sample; the rate-limit message namesllmApiKey/llmModel. - 0.2 (2026-09-25) — roster of candidates, CV from a link,
contactUrl, market report, dedupe memory per CV. - 0.1.1 / 0.1 (2026-09-25) — real Actor handle in the snippets · initial release.
Next: Indeed as a second source · an "AI included" tier (tokens paid by us) · the hiring manager's e-mail for strong matches · a cohort report for coaches · tailored CV bullets for strong matches.


