
Reddit Brand Monitoring: AI mentions, sentiment and pain points
Pricing
from $2.00 / 1,000 qualified mention (rules only)s
Reddit Brand Monitoring: AI mentions, sentiment and pain points
First 25 mentions free. Reddit brand monitoring for any subreddit: runs Reddit Scraper Lite, drops off-topic and seen posts free, adds AI sentiment, pain points, keyword alerts. $0.002 per qualified mention, below the median. Free demo on any plan; live search runs on your own Apify account.
Pricing
from $2.00 / 1,000 qualified mention (rules only)s
Rating
0.0
(0)
Developer

Rich Minds
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
8 days ago
Last modified
Categories
Share
Every new Reddit mention of your brand — ranked, with the one to answer first.
⚡ First 25 mentions free · 💵 $0.002 per qualified mention · 🤖 $0.009 + ≈ $0.002 AI tokens with AI assessment, on plans with model access or your key · ⏱️ demo in seconds
Try it in 30 seconds. Click Try it — sample Notion mentions, free. Then type your own brand and press Start — your first 25 qualified mentions are free, AI on. → How to use it · What a run costs · Run it weekly Bring your own data: rows in
itemsListor a dataset ID indatasetId— you pay only for the analysis, no scraper run.
⚡ At a glance
| What you get | Reddit mentions of your brand and competitors, best first: relevance, type, sentiment, priority, action, author link, a verbatim quote |
| You provide | your brand name (e.g. notion), optionally competitors, subreddits and a one-line brand brief |
| Output | JSON / CSV / Excel dataset, four views, a digest with share of voice and the trend vs last run |
| Typical run | 1 brand × 75 Reddit results → ~25 qualified mentions in ~2 minutes (estimate) |
| Cost of that run | $0.32 Reddit scraper on your account + $0.00 here (all 25 free) = $0.32 |
| AI tier, all in | ≈ $0.011 per mention ($0.009 + ≈ $0.002 tokens with the default model) |
| Keys / setup | Plan with Apify model access: no key · Other plans: your first 5 real mentions get live AI verdicts on us, then your own key — free Gemini / Groq = 1–3 AI verdicts per run, paid = every mention |
| Which plan | Free demo and your own list (list mode, template): any plan · live search: a plan that runs Store Actors |
| Works with | Schedules, e-mail digest, Slack, Teams, Google Chat, Discord, Telegram, webhooks, Google Sheets, n8n, MCP & AI agents |
🎯 What this Actor does
It runs Reddit Scraper Lite (trudax/reddit-scraper-lite) — or harshmaur's Reddit Scraper — on your account
for your brand terms, drops the junk free and hands you the one to answer first (priority, an action and the author's
profile link), only new mentions next week, and a digest that opens with "vs last run: complaints 5 → 9".
🔎 Reddit mentions — junk and repeats dropped free
[deleted], bots, ads, NSFW, your excludeTerms and "the notion of…" hits are dropped before any charge; a repeat
run pays only for what is new.
😊 Reddit sentiment analysis and Reddit pain points with a verbatim quote
Type (complaint, pain point, feature request, "alternative to X?"), sentiment and priority — from keyword tables on the
basic tier, from the AI reading your brandBrief on the AI tier; evidenceQuote is copied verbatim.
🧭 Reddit posts search and subreddit monitoring
Up to 10 subreddits (empty = all of Reddit); extraSearchTerms find "what should I use?" threads.
🚀 How to use it
- Click
Try it— the pre-filled sample (9 Notion posts and comments) runs free: 5 qualified mentions. - Type your own
brandTerms(pluscompetitorTerms) and a one-linebrandBrief— your brand replaces the sample and starts the live Reddit posts search (capped bymaxDiscoveryChargeUsd, $0.50). - Keep
enableAion and press Start — your first 5 mentions get live AI verdicts on any plan; all 25 free ones with Apify model access or a paid own key (which AI your plan gets). - Open the Reply queue, then put your e-mail in
notifyEmailand Schedule it weekly — the status message of your first real run links the step.
📚 Learn more: Step-by-step tutorial — Reddit brand monitoring with this Actor
🆚 Why this instead of a Reddit scraper or another monitor?
Against the raw Reddit scrapers (this Actor runs one of them for you):
Reddit Scraper Lite (trudax/reddit-scraper-lite) | Reddit Scraper (harshmaur/reddit-scraper) | Reddit Brand Monitoring | |
|---|---|---|---|
| Price | $0.004 per result + $0.02 per start · 7,362 users / 30 days | $0.002 per result + $0.02 init, AI +$0.0005 per row | from $0.002 per qualified mention, 25 free, no start fee |
| You pay for | every row, incl. community rows, bots, [deleted] | every row — its AI labels junk too | only mentions that pass your filters |
| Your time per 100 mentions | ≈ 6.7 h — find them in 330 rows, then 4 min each by hand | ≈ 6.7 h — the same triage | ≈ 0 h with AI — ranked, typed, quoted |
| Same 100 mentions, all in | $1.34 for ≈ 330 raw rows — you read 230 off-topic ones | $0.85 for 330 labelled rows, junk included | $1.54 ($1.34 scraper + $0.20) · $2.44 with AI — ranked, typed, deduped |
| Relevance to your brand | none | none — no brand brief | rule score + AI check against your brief |
| Repeat runs / failed runs | same threads again · 12 % fail | same threads again · 1.7 % fail | only new mentions · partial runs still used |
Against the other Reddit brand monitors in the same Store search (their cards, 2026-09-26):
Reddit Lead Monitor (scrapemint) | Reddit Brand Monitor (deepmine) | Reddit Keyword Monitor (signalengine) | This Actor | |
|---|---|---|---|---|
| Price | $0.015 per match, 2 free per run | $0.005 per result | $0.001 per new match | $0.002 / $0.009 AI per qualified mention, 25 free |
| Reddit fetched by | itself | itself | itself | a scraper on your plan (+$0.004 a result) |
| Relevance check vs your brand | keyword + intent class | keyword | keyword | rule score + AI against your brief |
| Only new mentions | yes | score changes tracked | yes | yes, per monitor |
| Insight + verbatim quote | — | — | — | yes (AI tier) |
A keyword monitor is cheaper when every hit is about you; this one pays off when your name is a common word ("notion").
Brand24 / Syften / F5Bot alternative? Brand24 ≈ $199/month, Syften ≈ $20/month, F5Bot free alerts with no relevance check — a weekly 3-term Reddit monitor here ≈ $6/month basic or ≈ $9.50 with AI, scraper included.
🧺 Already scraping Reddit? Qualify your Reddit scraper data
Run Reddit Scraper Lite or harshmaur's Reddit Scraper yourself? Point this Actor at that dataset (sourceMode
dataset, datasetId) — no second scrape, you pay only per qualified mention; the recipe is under Integrations.
💵 Pricing — what a run really costs
Pay per result: one event per qualified mention, nothing else.
| Event | When it is charged | Price |
|---|---|---|
free-tier | your first 25 qualified mentions on this Actor | $0.00 |
qualified-mention-basic | AI off — relevance with reasons, type, sentiment, priority, action | $0.002 |
qualified-mention-ai | AI on — plus the AI relevance check, insight, verbatim quote, reply draft | $0.009 |
Never charged: community / user rows, deleted or bot posts, ads, NSFW, off-topic matches, mentions below
minScore, unselected types or sentiments, duplicates, mentions from earlier runs, anything beyond maxQualified.
No start fee; compute included.
How that compares — $0.002 is 0.86× the Store median ($0.0023 across the 10 Actors a reddit brand monitoring search
shows) — cheaper per qualified mention than a raw row there, and only ~30 % of a search is on-topic: one qualified mention
replaces ≈ 3.3 raw rows plus the reading.
Worked example — weekly monitor, 3 terms × 100 results: Reddit Scraper Lite $1.22 on your account (300 × $0.004 +
$0.02; maxDiscoveryChargeUsd 1.25) → ~90 qualified (estimate) × $0.002 = $0.18 → $1.40 total, $0.016 per
qualified mention. AI on: 90 × $0.009 + ≈ $0.18 tokens → $2.21 total, $0.025 per mention.
AI tier, all in: ≈ $0.011 per mention ($0.009 + ≈ $0.002 tokens for ~900 in / 250 out with anthropic/claude-haiku-4.5)
— 4.5× the basic price plus tokens, billed via Apify's model access or your own key.
🤖 What the AI tier adds
The same mention, AI off (real output of the sample run):
AI on — real output of the AI example (local own-key run 2026-10-17 with the own-key default model, 1,573 input / 210 output tokens per mention; wording varies by model, fields and grounding do not):
The AI says why they are leaving and quotes the proof — ≈ 4 min of triage per mention by hand (an estimate: open
the thread, judge relevance and sentiment, copy the quote). Without model access the demo shows aiModel: sample verdicts.
⚙️ Input
Type your brand, a one-line brief, keep AI on — everything else has a default.
📤 Output
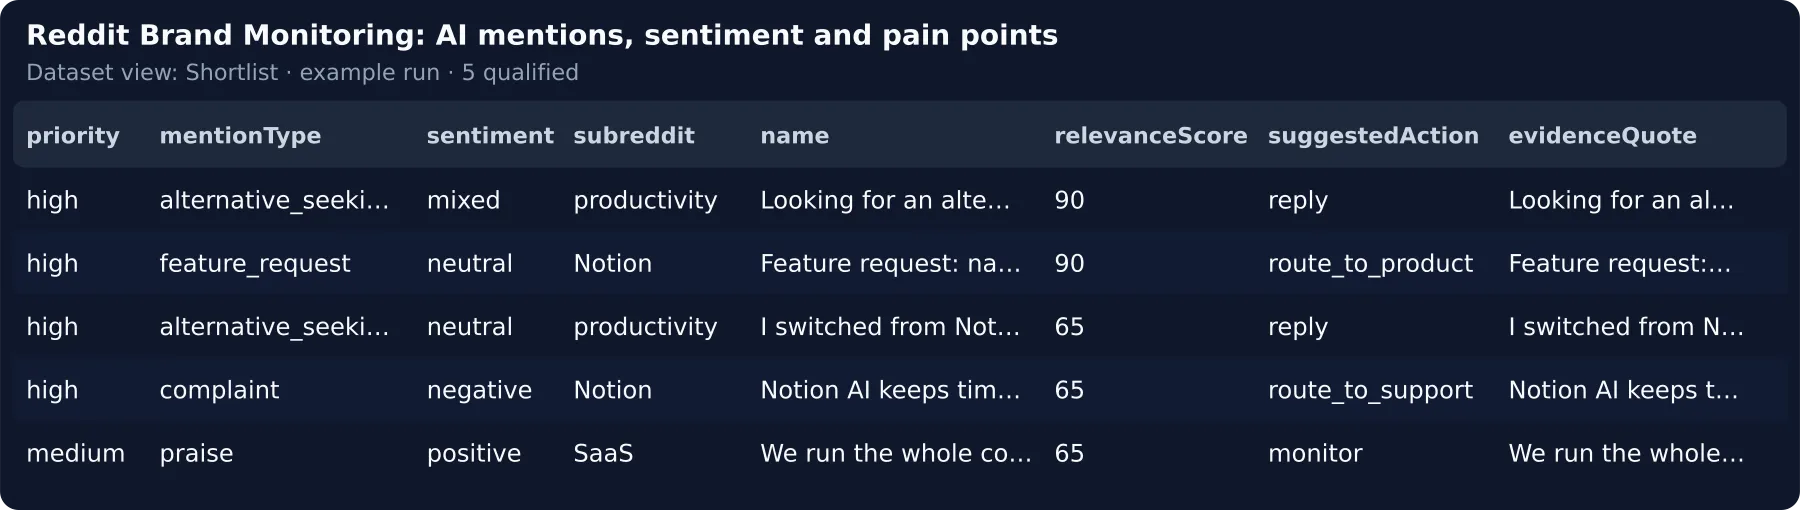
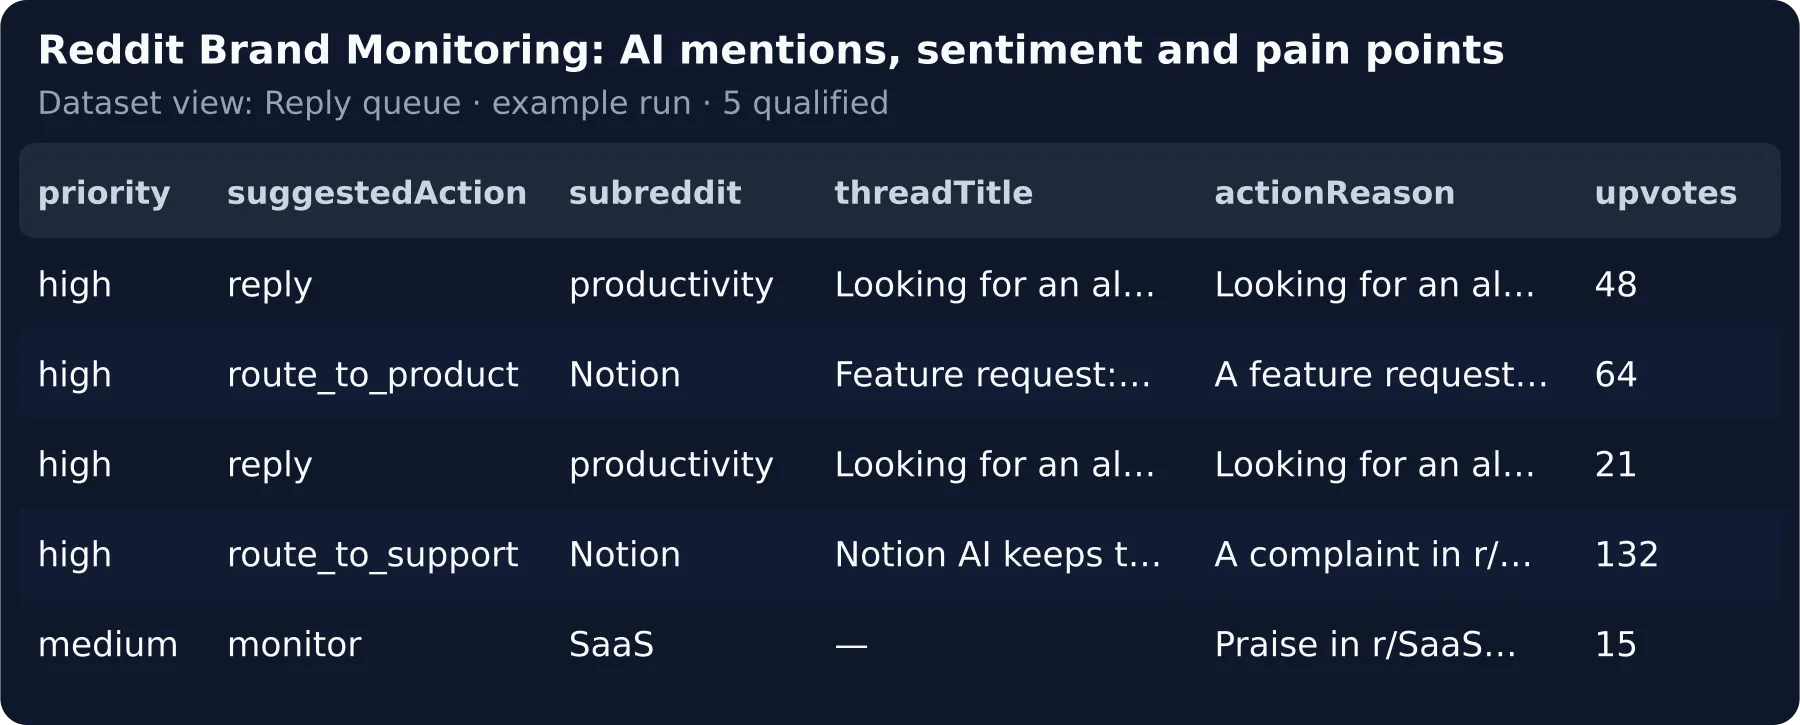
One dataset item per qualified mention. Dataset views: Shortlist (best first), Reply queue (action, reason,
draft, author profile), Pain points & requests (insight + quote) and Competitor mentions (share of voice).
Upsert key for a CRM or Sheet: dedupeKey — built from the Reddit fullname (reddit:t3_1fq2a7x), the key the
cross-run memory uses; itemId is its short hash.
Next to OUTPUT: the DIGEST (Slack / e-mail ready) and the REPORT page; OUTPUT.digest holds counts,
share of voice, themes and trend.
⭐ Found it useful? A review on the Store helps others find it — it takes a minute on the Actor's page.
🔁 Run it weekly — Reddit monitoring on a schedule
- Actions → Schedule (daily or weekly) with your address in
notifyEmail— every run with new mentions e-mails you the digest (top 10 with links), no Slack or Zapier needed. Your first real run's status message says the same. - Leave
dedupeAcrossRuns: true— you pay only for what is new; each monitor (terms + subreddits) keeps its own memory. - From run 2 the digest says what changed: "vs last run: mentions 41 → 55, complaints / pain points 5 → 9"; the
REPORTpage (a link to forward) adds the monitor's history run by run.
Weekly cost is the new mentions only: 3 terms × 100 results, ~90 new ≈ $1.40 a week basic, ≈ $2.21 with AI.
🗂️ A running log, and threads that come back
historyDatasetName (e.g. acme-reddit-log) appends every run's new mentions to one named dataset — a log across
months for Sheets (tracker sheet). dedupeTtlDays (0 = never) delivers — and charges — a
thread again after N days.
🎯 Try it for your niche
| Niche | What it looks for | Input to paste |
|---|---|---|
| SaaS founder | product + 2 competitors in r/SaaS, AI on | saas-founder-monitor.json |
| Community manager | complaints and questions, reply drafts | community-reply-queue.json |
| Product research | pain points and requests, last month | product-pain-points.json |
Replace the brand, paste it into the form's JSON tab (or save a Task per client).
🔌 Integrations, automation and API
- After your own scraper — on your
trudax/reddit-scraper-liteorharshmaur/reddit-scrapertask: Integrations → Run succeeded → this Actor with{"sourceMode": "dataset", "brandTerms": ["acme crm"], "enableAi": false}anddatasetId= the finished run'sresource.defaultDatasetId— rules only, no second scrape. - Google Sheets — import the Sheets template (
dedupeKeyfirst for upserts). - n8n — the weekly workflow (Sheet + Slack) and the
ticket workflow:
route_to_support→ a Zendesk / HubSpot ticket,route_to_product→ a Linear issue,dedupeKeyas the external id. - Webhook, Slack, Teams —
webhookUrl(payload below;webhookSecretsigns each POST withX-Signature: sha256=<HMAC of the body>),slackWebhookUrl, the API-only Teams / Google Chat / Discord / Telegram fields, or the Integrations tab. - AI agents / MCP — plain typed inputs;
{}runs the free demo,"sourceMode": "list"qualifies your rows free of scraper cost.
Run outcomes — what your integration sees
👥 Who is it for?
| You are… | You run it to… | Start with |
|---|---|---|
| SaaS founder / marketer | new mentions of your product and competitors each morning | competitorTerms, enableAi, notifyEmail |
| Community / support manager | the threads that need a reply today, as tickets | alertMinPriority: high, draftReplies, the ticket workflow |
| Product researcher | Reddit market research: pain points and feature requests with citable quotes | extraSearchTerms, mentionTypes |
| Agency / AI agent | a weekly REPORT per client brand · the top 20 mentions of X as JSON | one Task per client · {"brandTerms": ["x"], "maxQualified": 20} |
🧠 How the AI works
- One typed call per mention (post, thread, your brief, the rule baseline); one more writes the digest themes.
- Grounded — a quote that is not an exact substring is dropped (
aiStatus: fallback), competitors must appear verbatim, an off-brand mention is capped at 30; reply drafts claim nothing your brief does not say. - Tokens where they matter — mentions at or above
minScore− 20, best first, up toaiCandidateMultiplier×maxQualified; default modelanthropic/claude-haiku-4.5, orllmProvider: "byok". A second pass retries rate-limited mentions one at a time; a model error never fails the run (the reason is inaiCoverage).
🔒 Data, compliance and limits
Public Reddit data only, no login; up to 10 subreddits per run, text ≤ 4,000 characters, AI best in English.
Respect each subreddit's rules when you reply; use the output within Reddit's terms and GDPR / CCPA.
❓ FAQ
What will my first real search cost? 1 term × 75 results ≈ $0.32 with Reddit Scraper Lite, capped by
maxDiscoveryChargeUsd ($0.50); ~25 mentions qualify — your 25 free ones.
Is this a Reddit Scraper Lite scraper? It runs Reddit Lite or harshmaur's scraper for you, with cost-saving
settings; a dataset from either works in dataset mode.
Does it scrape Reddit comments too, like a Reddit comments scraper? Yes — with their thread's title and URL.
Can I use it for Reddit market research? Yes: extraSearchTerms, mentionTypes, timeWindow: month and the
Pain points view.
Can I use it for Reddit keyword alerts? Yes: webhookUrl + alertMinPriority: high POSTs urgent mentions at once;
draftReplies (AI) drafts a reply — never posted.
Is it a Brand24, Syften or F5Bot alternative for Reddit? For Reddit, yes — per mention instead of a seat, with the relevance check and quotes F5Bot's free alerts lack; those tools also watch other networks.
How long does a run take? The demo: seconds. Live: ~2 min in the scraper per 75 results (estimate; capped by
discoveryTimeoutSecs 600). AI, measured on the 5-mention example with a free Gemini key: 138.5 s, 98.6 s of it
rate-limit waiting (≈ 8 s per mention of model time; 5 of 5 assessed after the second pass); a key whose quota never
answers stops the AI after 20 s, an own key after 60 s of waiting in all — every mention still pushed. Pass
timeoutSecs 3600 with AI; OUTPUT.timing has the phases.
Which Apify plan do I need? Any plan runs the demo and list / dataset mode; the live search needs a plan that
runs Store Actors. The AI on your plan: At a glance.
What does "qualified" mean? It names one of your terms, passed every free filter and scored ≥ minScore.
What happens if nothing matches my filters? The run succeeds with 0 rows and charges nothing.
Will I be charged for the same mention twice? No — delivered Reddit ids are remembered on your account. Adding a
competitor keeps the monitor's memory; another brand or another set of type filters gets its own list, and a mention
already paid for there is delivered as already-charged, never billed twice. dedupeTtlDays lets one come back.
🧩 More Actors from the same developer
Not quite your use case? The same pay-per-qualified-result model, closest to this Actor's buyers first:
- Threads Brand Monitoring — the same brand terms on Threads: every new post about you, the one to answer first.
- Google Reviews Analysis AI — the complaints and pain points in your Google reviews, next to the Reddit ones.
- Website Change Monitor — know when the competitors your Reddit users compare you with change their pricing or pages.
- Twitter Lead Generation — people on X asking for a tool like yours, ready to answer.
- Instagram Competitor Content — what your competitors post that wins, every week.
🆘 Support
Open an issue on the Actor's page — buyer requests ship first.
📝 Changelog
Newest first.
- 0.2.6 (2026-10-17) — Typing only your brand next to the sample now always runs your search: a leftover demo brand description is set aside and named in the status instead of stopping the run; The free demo now shows labelled sample AI verdicts on any plan, and on a plan without model access your first 5 real mentions get live AI verdicts on us; New: a forwardable report page with the monitor's history, a signed webhook option, a running log across runs, digests to Teams, Google Chat, Discord and Telegram, and an alert when Reddit's scraper changes its format instead of a silent empty run.
- 0.2.5 (2026-10-04) — Bring your own data: rows in
itemsListor adatasetIdpick their mode, start no scraper and are charged only for the analysis; unread fields are listed in the log. - 0.2.1–0.2.4 (2026-09-26 – 10-04) — review and listing fixes: clearer statuses, the AI coverage per run, the comparison and the FAQ.
- 0.2 (2026-09-26) — harshmaur's scraper as a source, trend vs last run, presets, Sheets template, n8n workflow.
- 0.1–0.1.1 (2026-09-26) — initial release.


