
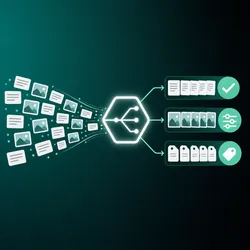
OpenAI GPT-6 Luna Decisions — Bulk Text & Image Classifier
Pricing
from $2.00 / 1,000 evaluated items
OpenAI GPT-6 Luna Decisions — Bulk Text & Image Classifier
Label, score and flag texts, images or scraped records in bulk with OpenAI GPT-6 Luna Decisions — your own categories, one typed answer and confidence per row.
Pricing
from $2.00 / 1,000 evaluated items
Rating
0.0
(0)
Developer
Seemu Scraping
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
4 days ago
Last modified
Categories
Share
Turn a list of texts, images or scraped records into structured columns. Give it your own labels — ticket queues, lead grades, sentiment, product categories, "is there a person in this photo?" — and every item comes back with one typed answer per question, plus a confidence score you can filter on.
Powered by OpenAI GPT-6 Luna Decisions — OpenAI's new Decisions API, which returns typed, probabilistic answers instead of chat text: no prompt engineering, no JSON parsing, no free-form text to clean up. You define the options; the answer is always one of them.
What you get
For every text, image or record, one dataset row with:
- Choice questions — the selected label (
department: "billing"), a confidence score, and the probability of every option - Score questions — a numeric rating against your own ordered levels (
frustration: 1.96), the nearest level's label, confidence, and per-level probabilities - Yes/no questions — a plain
true/falseplus the underlying probability, so you can set your own threshold - Images understood, not just text — evaluate photos on their own, or a record's caption together with up to 4 of its images
- The original text, image URLs and (when reading from a dataset) the full source record, so results stay joinable
- Export to JSON, CSV, or Google Sheets directly from the Apify console
Ask up to 10 questions at once — they are answered in a single pass per item.
Use cases
- Support ticket triage — route each message to the right team and flag the urgent ones
- Social media post classification — label Instagram, TikTok or Facebook posts by caption and photo: promo vs. lifestyle, product category, brand safety
- Product and listing image tagging — categorise marketplace or e-commerce photos, flag low-quality or off-brand images
- Review and comment analysis — sentiment, topic and "is this a complaint?" across thousands of reviews at once
- Lead qualification — score scraped profiles or form submissions against your own ICP criteria
- Content moderation — flag spam, promotional or unsafe text and images with a tunable confidence threshold
How to use
- Paste texts into Texts (one per line) and/or image links into Image URLs — each is evaluated on its own
- Or pick a Dataset ID from a previous run (e.g. a social media or e-commerce scraper) to label its records in place:
- Fields to evaluate — the text fields to send, e.g.
caption,title - Image fields — the fields holding image URLs, e.g.
displayUrl,images
- Fields to evaluate — the text fields to send, e.g.
- Define your Questions. Each one needs:
key— the column name in the outputtype—choice(pick one option),score(rate against ordered levels), ornoul(yes/no)instructions— what you want decidedcriteria— the options forchoice, the ordered levels forscore; optional fornoul
- Set Max Items (default 100; set 0 for no limit) and Concurrency
- Run the actor — results appear in the Dataset tab
Question types
A choice question also accepts a plain list of labels (["positive", "neutral", "negative"]) when the labels speak for themselves.
Output format
Each dataset record:
Image items also carry imageUrls. If an image can't be downloaded it is listed in imageErrors and the item is evaluated on whatever is left. If none of your options fit an item (say, "which support team?" asked about a photo of a cat), that question is left empty and named in refusedQuestions rather than forcing a wrong answer. If an item can't be evaluated at all, its row still appears with an error field — the rest of the run continues.
Pricing
You pay per item evaluated, plus a small fee per image analysed. Items that fail are not charged.
Notes
- Texts and records are truncated to 8,000 characters before they are evaluated
- Images (JPEG, PNG, WebP, GIF; up to 20 MB) are resized automatically; up to 4 images per item
- Confidence is separate from probability: use
<key>_confidenceto decide whether to act automatically or send a row to a human


