Reddit Software Reviews Scraper | Real User Opinions
Pricing
from $9.99 / 1,000 reviews
Reddit Software Reviews Scraper | Real User Opinions
Extract real user opinions on any software product from Reddit. Each result includes sentiment, alternatives mentioned, use cases, and thread context. From Notion to niche tools.
Pricing
from $9.99 / 1,000 reviews
Rating
0.0
(0)
Developer

Zen Studio
Maintained by CommunityActor stats
0
Bookmarked
14
Total users
2
Monthly active users
10 days ago
Last modified
Categories
Share
Reddit Software Reviews Scraper | Real User Opinions & Alternatives (2026)
From Zen Studio, creators of G2 Reviews and Capterra Reviews, with 50,000+ combined runs across those two actors.
Why choose this Reddit software reviews scraper?
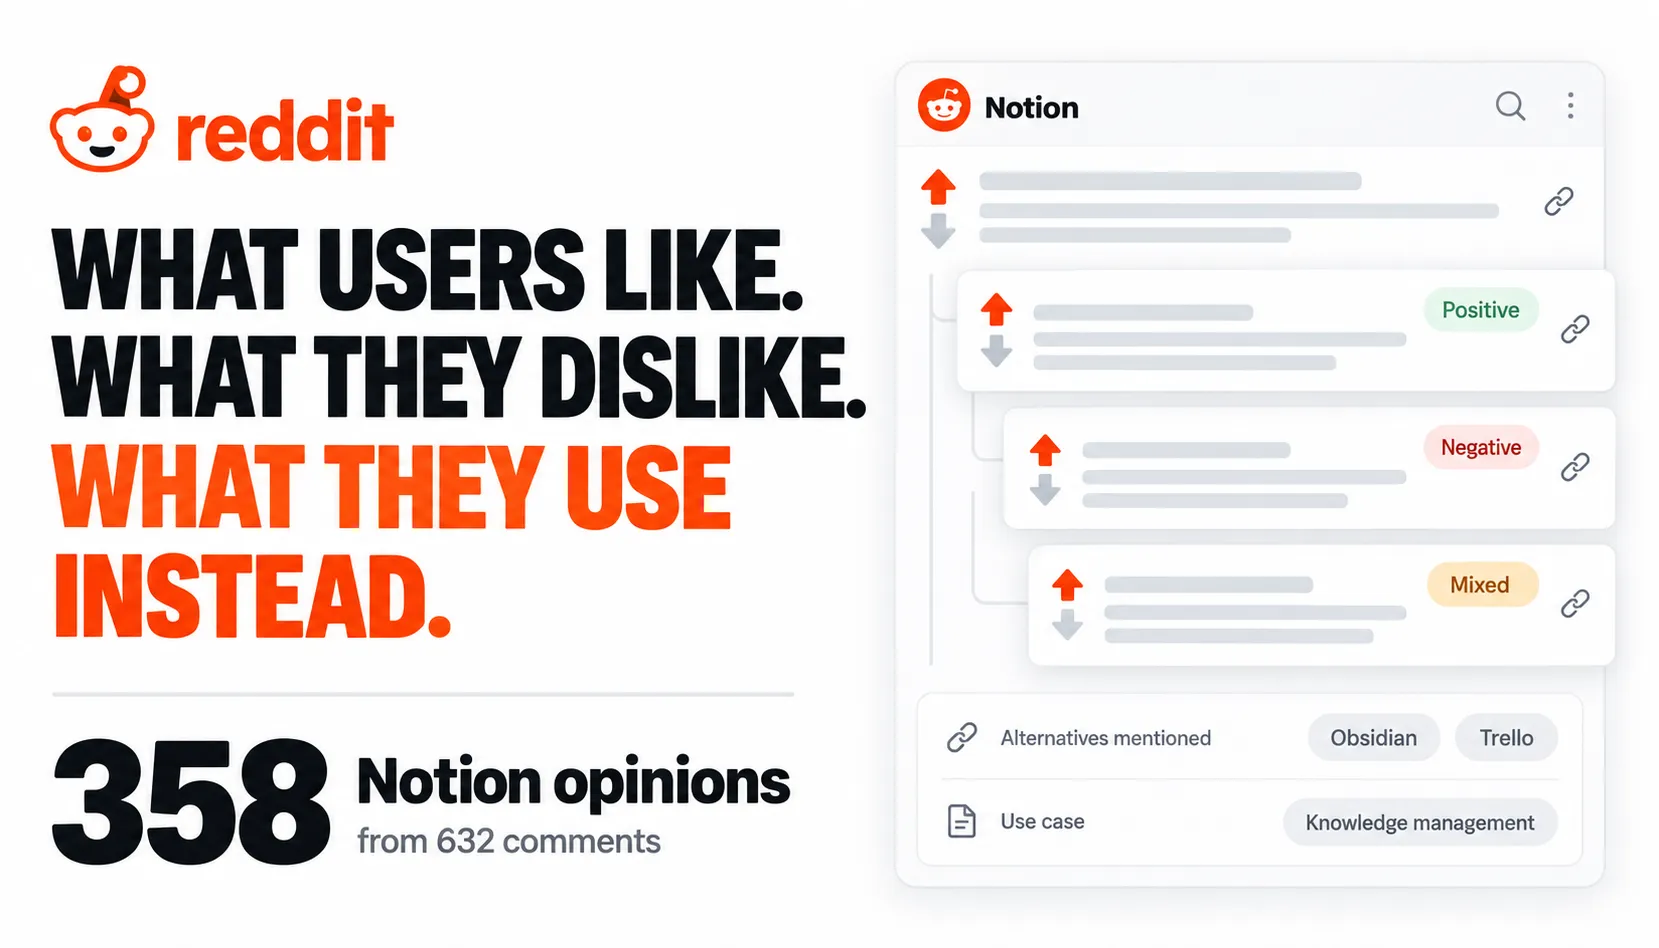
- Find evaluations worth reading. A Notion collection turned 632 comments into 358 software opinions, filtering for product evaluations rather than passing mentions. Search Reddit in real time by product name, domain, review-page URL or a specific Reddit thread.
- See sentiment, alternatives and use cases together. Each opinion keeps the original comment and adds an AI sentiment label: positive, negative, mixed or neutral. See which other tools were mentioned and what the commenter uses the product for, when stated.
- Keep the source beside the opinion. Every record includes its Reddit link, subreddit, author, upvotes and date. Add optional thread context to include the original post's text, author and upvotes for deeper analysis.
Try a product you know
Open actor input and replace Notion with your product. This example requests up to 25 opinions from the past year. Export JSON, CSV or Excel to compare sentiment, alternatives and use cases across comments.
Set includeThreadContext to true to add the original post details; thread context carries an additional charge. For recent feedback, choose past30days or past90days. Results depend on how much the product is discussed. For a combined brand report with competitor comparisons, use Reddit Brand Sentiment.
| Zen Studio · Reviews & Brand Research | ||||
 Reddit Reviews You are here |  Brand Sentiment Compare brands |  G2 Reviews Pros & cons |  Capterra Buyer reviews |  TrustRadius Enterprise reviews |
Copy to your AI assistant
Copy this block into ChatGPT, Claude, Cursor, or any LLM to start building with this data.
How to Get Reddit Software Reviews
Search by product name
Search by G2 review page URL
Recent opinions only
With full thread context (for LLM pipelines)
Input Parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
query | string | required | Product name, domain, G2/Capterra/TrustRadius URL, or Reddit thread URL |
maxResults | integer | 500 | Maximum opinions to extract (10-1000) |
dateRange | select | pastYear | past30days, past90days, pastYear, or allTime |
includeThreadContext | boolean | false | Add original post text, author, and upvotes per thread |
What Data Can You Extract from Reddit?
Every result includes:
- Opinion data -- raw comment text, AI-classified sentiment, use case
- Competitive intelligence -- other software tools mentioned in the same comment
- Source metadata -- subreddit, thread title, author, upvotes, direct URL, date
- Thread context (optional) -- original post that started the discussion
Demo
Output Example
threadBody, threadAuthor, and threadUpvotes only appear when includeThreadContext is enabled.
upvotes and threadUpvotes carry Reddit's net score, which is upvotes minus downvotes and is the figure Reddit itself shows beside a comment. A heavily downvoted comment can therefore be negative. Reddit does not publish the two directions separately, so no finer breakdown exists.
How It Works
The scraper runs a 3-stage pipeline per query:
- Discovery -- identifies the product, finds relevant subreddits and high-signal threads
- Collection -- searches multiple subreddits in parallel, harvests full comment trees from targeted threads
- Extraction -- AI analyzes each comment, keeps only genuine evaluations, classifies sentiment and alternatives
The whole process takes 30-120 seconds depending on how much the product is discussed on Reddit.
Pricing -- Pay Per Event (PPE)
| Event | Cost |
|---|---|
| Actor start | $0.10 |
| Per opinion extracted | $0.00999 |
| Per thread context (optional) | $0.00999 |
Free tier: 5 runs, 25 opinions per run.
Advanced Usage
Competitive analysis
Compare how Reddit talks about your product vs competitors. Run the scraper for each product and compare alternativesMentioned fields.
Sentiment monitoring
Schedule runs with past30days to track how opinions shift over time. Useful for detecting backlash after pricing changes or feature removals.
LLM-powered report generation
Enable thread context and feed the results into GPT-4 or Claude for automated "What does Reddit think about X?" reports.
Extract from a specific thread
Pass a Reddit thread URL to extract opinions from that specific discussion.
FAQ
How many opinions can I get?
Depends on how much the product is discussed on Reddit. Popular products (Notion, Slack, Airtable) can return 500+. Mid-size products (Pipedrive, Linear) typically yield 50-200. Very niche products may return fewer than 20.
What if a product has a generic name like "Linear" or "Monday"?
The scraper uses AI to distinguish between the software product and the common word. Comments about "linear algebra" or "Monday the day of the week" are automatically filtered out.
What if the product isn't discussed on Reddit?
You'll get 0 results. The scraper only returns genuine opinions it can verify. No padding with irrelevant data.
How fresh is the data?
Every run searches Reddit live. There is no cache. With past30days, you get opinions posted in the last 30 days.
What counts as an "opinion"?
A comment where someone evaluates the product. "Airtable is solid for project tracking" counts. "I pipe data into Airtable" does not. Questions like "Is Notion worth it?" are excluded.
Can I use a G2 or Capterra URL as input?
Yes. The scraper extracts the product name from the URL and searches Reddit for opinions about that product.
What's in alternativesMentioned?
Other software tools the commenter mentions in the same comment. If someone says "I switched from Notion to Obsidian," the alternatives array will contain ["Obsidian"].
What does includeThreadContext add?
The original post (OP) that started the Reddit discussion. Includes the post body, author, and upvotes. Useful when you need to understand what question or statement triggered the opinions.
Is there a free tier?
Yes. 5 runs with up to 25 opinions per run.
What subreddits does it search?
The scraper automatically discovers relevant subreddits for each product using AI. It typically searches 10-20 subreddits including the product's own subreddit (e.g., r/Airtable), category subreddits (r/projectmanagement), and general tech communities (r/SaaS).
Support
- Bugs: Issues tab
- Features: Issues tab
Legal Compliance
Extracts publicly available data from Reddit. Users must comply with Reddit's terms of service and applicable data protection regulations (GDPR, CCPA).
Real user opinions on any software product, structured for analysis.