
Deezer Music Scraper
Pricing
from $2.99 / 1,000 results
Deezer Music Scraper
Deezer Music Scraper is a Python tool designed to extract track details, album metadata, artist profiles, playlists, and global music charts from Deezer. It exports structured music catalog data into clean CSV or JSON formats for audio analytics and market research.
Pricing
from $2.99 / 1,000 results
Rating
0.0
(0)
Developer
ZeroBreak
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Deezer Scraper: Tracks, Artists, Albums, Playlists, Charts and ISRC Lookup (Free)
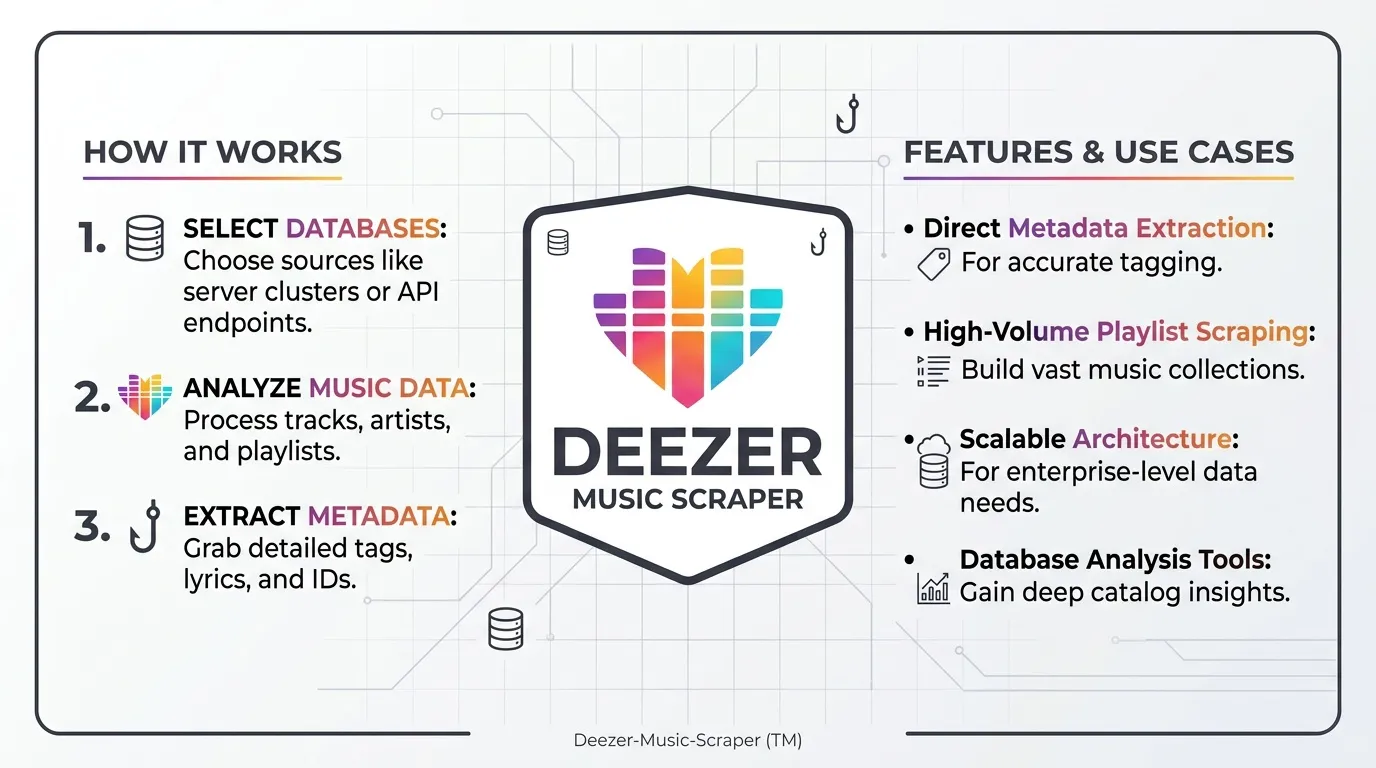
Collect and organize publicly available Deezer music catalog information, including tracks, artists, albums, playlists, charts, and catalog collections. Enrich artist records with fan counts, top tracks, discography, and related artists. Capture track ISRCs, album UPCs, labels, BPM, and release dates when available.
Charts depend on the country associated with the run's IP address. Preview links are temporary 30-second audio previews; this actor stores the URL rather than downloading the audio.
Use Cases
- Music marketing and A&R: Research artist fan counts, album counts, and related artists before outreach.
- Playlist pitching: Organize playlist fan counts, track counts, and creator information.
- ISRC and UPC matching: Match tracks using ISRCs and organize album metadata, including UPCs, labels, and release dates.
- Chart tracking: Collect chart entries by genre and market.
- Music datasets: Build structured collections of search results, discographies, and editorial selections for music research.
What Data Does This Deezer Scraper Extract?
The actor supports several collection modes:
- Search: Find tracks, artists, albums, or playlists using search phrases.
- Artists: Collect artist details, with optional nested top tracks, discography, and related artists.
- Albums: Collect album information and optionally include the full track list.
- Tracks: Collect track metadata and support ISRC-based lookups.
- Playlists: Collect playlist metadata and optionally include tracks across subsequent pages.
- Charts: Collect chart entries for tracks, artists, albums, playlists, and podcasts, with chart positions.
- Catalog: Collect genres, editorial sections, and radio listings, or retrieve tracks for specified radio IDs.
Missing or unavailable records are saved as NO_DATA rows. Quota failures are retried and recorded as QUOTA if they persist. Duplicate records are removed using the record type and ID, and maxItems limits the number of output rows.
Example artist record:
The output preserves type, title, and description alongside the dataset-friendly fields recordKind, itemTitle, and summaryText.
Input Parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
mode | string | search | Collection mode: search, artists, albums, tracks, playlists, charts, or catalog. |
searchType | string | track | Search category: track, artist, album, or playlist. |
queries | array | ["daft punk"] | Search phrases, one per line. |
ids | array | Empty | Deezer IDs, Deezer URLs, short links, or ISRCs such as GBDUW0000059. |
includeTopTracks | boolean | true | Include top tracks in artist records. |
includeAlbums | boolean | false | Include an artist's discography. |
includeRelated | boolean | false | Include related artists with their IDs, names, and fan counts. |
includeTracks | boolean | true | Include album and playlist tracks, including subsequent pages. |
genreId | integer | 0 | Chart genre ID. 0 represents all genres. |
chartTypes | array | ["tracks"] | Chart categories: tracks, artists, albums, playlists, or podcasts. |
maxItems | integer | 200 | Maximum number of data rows, from 1 to 10,000. |
maxRequestsPer5s | integer | 40 | Shared request pacing limit. Maximum allowed setting: 50 per five seconds. |
timeoutSecs | integer | 300 | Maximum total run duration in seconds. |
requestTimeoutSecs | integer | 30 | Timeout for an individual request. |
Example Input: Search for Tracks
Example Input: ISRC and Track Lookup
An ISRC and a track URL can resolve to different track IDs. If their IDs differ, both records are retained.
Output Fields
| Field | Type | Description |
|---|---|---|
recordKind | string | Record category: track, artist, album, playlist, genre, editorial, radio, or podcast. Also available as type. |
itemTitle | string | Record title. Also available as title. |
summaryText | string | Playlist or podcast description. Also available as description. |
id | integer | Deezer record ID. |
name | string | Artist or catalog item name. |
url | string | Link to the corresponding Deezer page. |
isrc | string | Track International Standard Recording Code. |
upc | string | Album Universal Product Code. |
label | string | Album label, when available. |
fans | integer | Artist, album, or playlist fan count, when available. |
albumsCount | integer | Artist album count. |
previewUrl | string | Temporary 30-second preview URL, when available. |
releaseDate | string | Album release date. |
chartPosition | integer | 1-based position within the chart pages read. Only present on rows from charts mode; the field is omitted on all other rows. |
tracks | array | Nested album or playlist tracks. |
topTracks | array | Artist top tracks, when enabled. |
albums | array | Artist discography, when enabled. |
related | array | Related artist information, when enabled. |
error | string | Error category: NO_DATA, QUOTA, INVALID_INPUT, or HTTP_<code>. |
code | integer | Error code or HTTP status code, when available. |
input | string | Original query, ID, or URL associated with an error. |
Limits and Error Handling
Request Limits
The actor uses a default pacing limit of 40 requests per five seconds, with a configured maximum of 50 per five seconds. It runs at most five requests concurrently.
When quota errors occur, the actor waits between five and ten seconds before retrying, for up to five attempts. If the failure persists, the record is saved with a QUOTA error.
Search Results and Pagination
Search results may be limited even when more matching records exist. Requests for large result sets can return fewer records than expected, and pagination may stop after a few hundred results.
For broader coverage, try multiple simpler search phrases rather than complex combinations of artist and track filters.
Chart Localization
Chart results depend on the country associated with the run's IP address. A run originating from one country may not return the chart for another market. If you need country-specific results, configure your run's network settings accordingly.
Preview URLs
Preview links point to temporary 30-second audio previews and can expire. The actor stores the preview URL but does not download the audio file. Do not assume that a stored preview link will remain available indefinitely.
FAQ
Why are the charts from a different country?
Chart availability depends on the country associated with the run's IP address. Check your network configuration if you need results for a particular market.
Why does a search return fewer records than expected?
Search results and pagination may be limited, even when additional matching records exist. Try multiple search phrases and adjust maxItems where appropriate.
How long do preview links last?
Preview links are temporary 30-second audio URLs. They may expire, so do not treat them as permanent audio assets. The actor saves the URL rather than the audio file.
What does an error row mean?
NO_DATA: The requested record is missing or unavailable.QUOTA: A quota-related failure persisted after retries.INVALID_INPUT: The supplied input could not be processed.HTTP_<code>: Another request failure, represented by its status or error code when available.
Trademark Notice
Deezer and its related names, logos, and trademarks belong to their respective owners. They are used in this documentation solely to identify the source of the data and do not imply affiliation, sponsorship, endorsement, or partnership.
Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, sponsored by, or otherwise officially associated with Deezer.
Is Web Scraping Legal?
Collecting information that is already public is generally legal. Scraping is not the same thing as hacking, and there is no single law that bans it. The limits are the usual ones: do not break into accounts, do not take private or confidential data, and be careful with personal data and copyrighted works. A site's terms can also restrict how you access it. Facts such as a public name, price, or rating are not the same thing as republishing someone's article or photo.
This actor collects information from public pages. It does not log in and it does not bypass access controls.
For a longer explanation, see Apify's article Is web scraping legal?.


