
Facebook Public Page Posts Scraper
Pricing
from $5.60 / 1,000 public facebook post delivereds
Facebook Public Page Posts Scraper
Scrape current public Facebook Page posts, messages, dates, Page identity, and validated source links from logged-out Page HTML.
Pricing
from $5.60 / 1,000 public facebook post delivereds
Rating
0.0
(0)
Developer

Tim Zinin
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Turn a public Facebook Page into structured post rows for monitoring, research, or an internal content feed. Submit an exact Page root such as https://www.facebook.com/NASA/; the Actor returns the source post ID, validated first-party permalink, creation time, public message text, Page name and ID, observation timestamp, and source evidence. It reads logged-out public Page HTML through Apify Residential Proxy. No Facebook login, cookies, browser session, or customer credential is required.
Each run observes one currently returned HTML document per requested Page and delivers at most 12 rows in total. This is a bounded current-page observation, not a full Page archive or pagination service. If the first Page fills the shared cap, later Pages are not requested. The retained real NASA source fixture produced one qualifying post and exposed an opaque Relay continuation cursor. The Actor records that continuation as available but does not replay the private Relay request. Likes, comments, and shares are null because the observed anonymous payload did not expose values the Actor could verify.
The price is $0.008 per delivered public post through result-found. There is no start fee or default Dataset-item fee, and source failures or diagnostics are free. Bronze pays $0.0072, Silver $0.0064, and Gold, Platinum, and Diamond $0.0056 per delivered row. Repeating a successful observation is billable again because it delivers a fresh timestamped Dataset row.
Selected fields from the retained public fixture:
What you receive
The default Dataset contains one row per delivered source story. Every row includes schemaVersion, recordType, postId, postUrl, creationTime, text, pageName, pageId, likeCount, commentCount, shareCount, sourceUrl, observedAt, a SHA-256 source reference, and billing metadata. Nullable fields remain null; the Actor does not manufacture engagement counts.
OUTPUT records the outcome, delivery status, per-Page evidence, errors, and a compact snapshot of delivered rows. outcome: "completed" means the available rows were delivered without a source error. deliveryComplete and coverage.complete remain false at the one-document boundary because the result is not a full archive. source_failed, partial, empty, and budget_stopped stay distinct.
How the source is handled
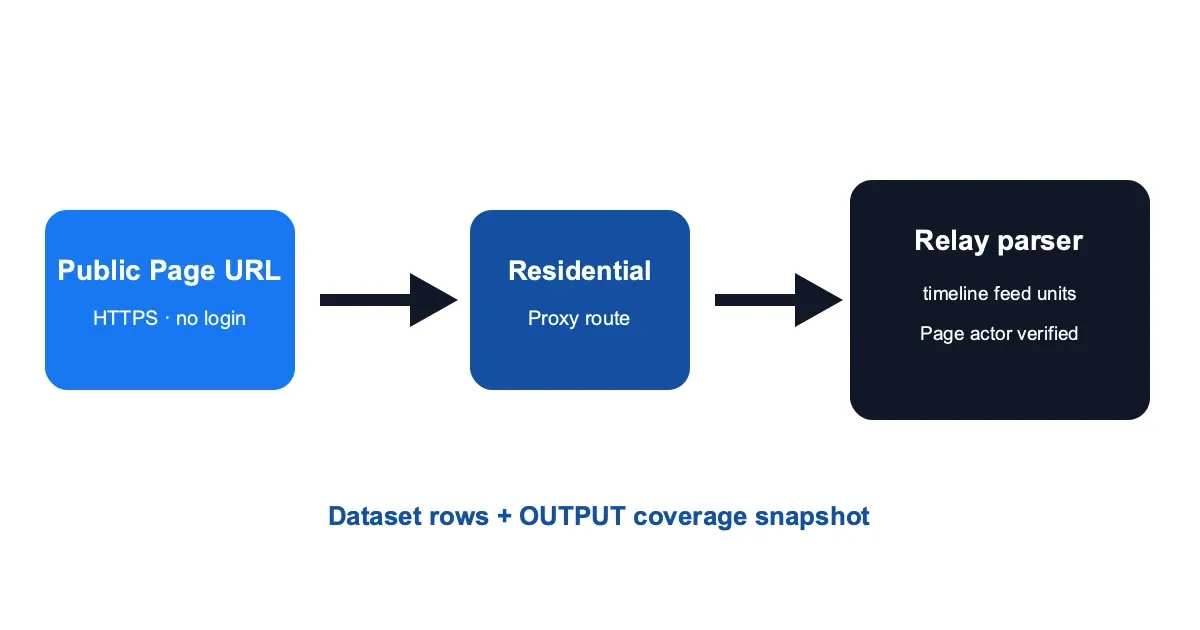
The parser reads only data.user.timeline_list_feed_units.edges[].node from data-sjs Relay payloads in the received logged-out Page. A row is accepted only when its actor URL exactly matches the requested Page root and its permalink is an HTTPS facebook.com/{Page}/posts/{id} URL tied to that Page. Coverage reports whether the document exposed an opaque continuation, while keeping complete: false; the Actor does not create private GraphQL calls or claim that it followed pagination.
Requests use HTTPS with certificate validation, reject redirects, allow one attempt per Page, cap both compressed and decoded content at 5 MiB, and share a bounded run deadline. A login redirect, HTTP error, unexpected content type, malformed Relay data, oversized response, or timeout produces no paid row.
Ready-to-use Task recipes
Current NASA Page observation
One-row source check
Repeat snapshot — schedule the same bounded input
Replace NASA with the exact root of the public Page you are authorized to observe. Inputs can contain up to 10 unique Pages, but the 12-row cap is shared and input order matters.
Costs and run budgets
| Tier | Price per delivered row | 12 delivered rows |
|---|---|---|
| Base | $0.0080 | $0.0960 |
| Bronze | $0.0072 | $0.0864 |
| Silver | $0.0064 | $0.0768 |
| Gold / Platinum / Diamond | $0.0056 | $0.0672 |
The runtime checks the run's effective charge limit before requesting the source and again before each paid write. When starting runs through the Apify API, use a positive maxTotalChargeUsd. A value of 0 can be treated by the platform as unset and replaced by its default. To verify the no-affordable-row path, use a small positive value below one result price, such as 0.0001.
Repeat observations safely
Keep the exact input, run ID, Dataset, and OUTPUT together. Compare postId values only across the same ordered Page list and maxItems. A missing ID means only that the item was not observed within that run's one-document, 12-row boundary; it does not prove deletion. A source failure is reported separately from a valid observed page with no qualifying rows.
Use the data only for lawful purposes and according to Facebook's terms and applicable rights. The Actor reads public Pages and does not access private profiles, groups, messages, or account data.


