
Gelbeseiten Scraper [Only $1/1K💰] | German Business Leads
Pricing
from $0.90 / 1,000 results
Gelbeseiten Scraper [Only $1/1K💰] | German Business Leads
Turn Gelbe Seiten into a German B2B lead list: extract business name, address, phone, website, email, opening hours, categories and reviews from gelbeseiten.de as structured JSON. Search by trade and city. No API key.
Pricing
from $0.90 / 1,000 results
Rating
0.0
(0)
Developer
Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Gelbeseiten Scraper
Gelbeseiten Scraper extracts German business listings from gelbeseiten.de (Gelbe Seiten — the German Yellow Pages) and returns them as clean, structured rows: business name, category, full address, phone, website, opening hours, services, rating and reviews, plus email and geo coordinates when you enable detail pages.
It is built for German B2B lead generation, DACH sales outreach, local-SEO and market research, CRM enrichment and building a German company database (Firmendatenbank) — with per-row provenance (url, scrapedAt) so every record is traceable.
Scrape German Business Leads and B2B Company Data
- German B2B lead generation — build targeted lead lists by trade and city (e.g.
Steuerberater München,Zahnarzt Hamburg), with phone, website and email. - Building a German company database (Firmendatenbank) — collect structured business records across categories and regions into one dataset.
- DACH sales outreach and CRM enrichment — append contact details, opening hours and ratings to existing company records.
- Local SEO and market research — map how many providers serve a category in a city, and compare them by rating and review count.
- Franchise, supplier and partner discovery — find businesses in a niche or service area directly from the directory listing.
- Review monitoring — pull individual reviews (rating, date, author, text, source) to track customer sentiment per business.
How It Works
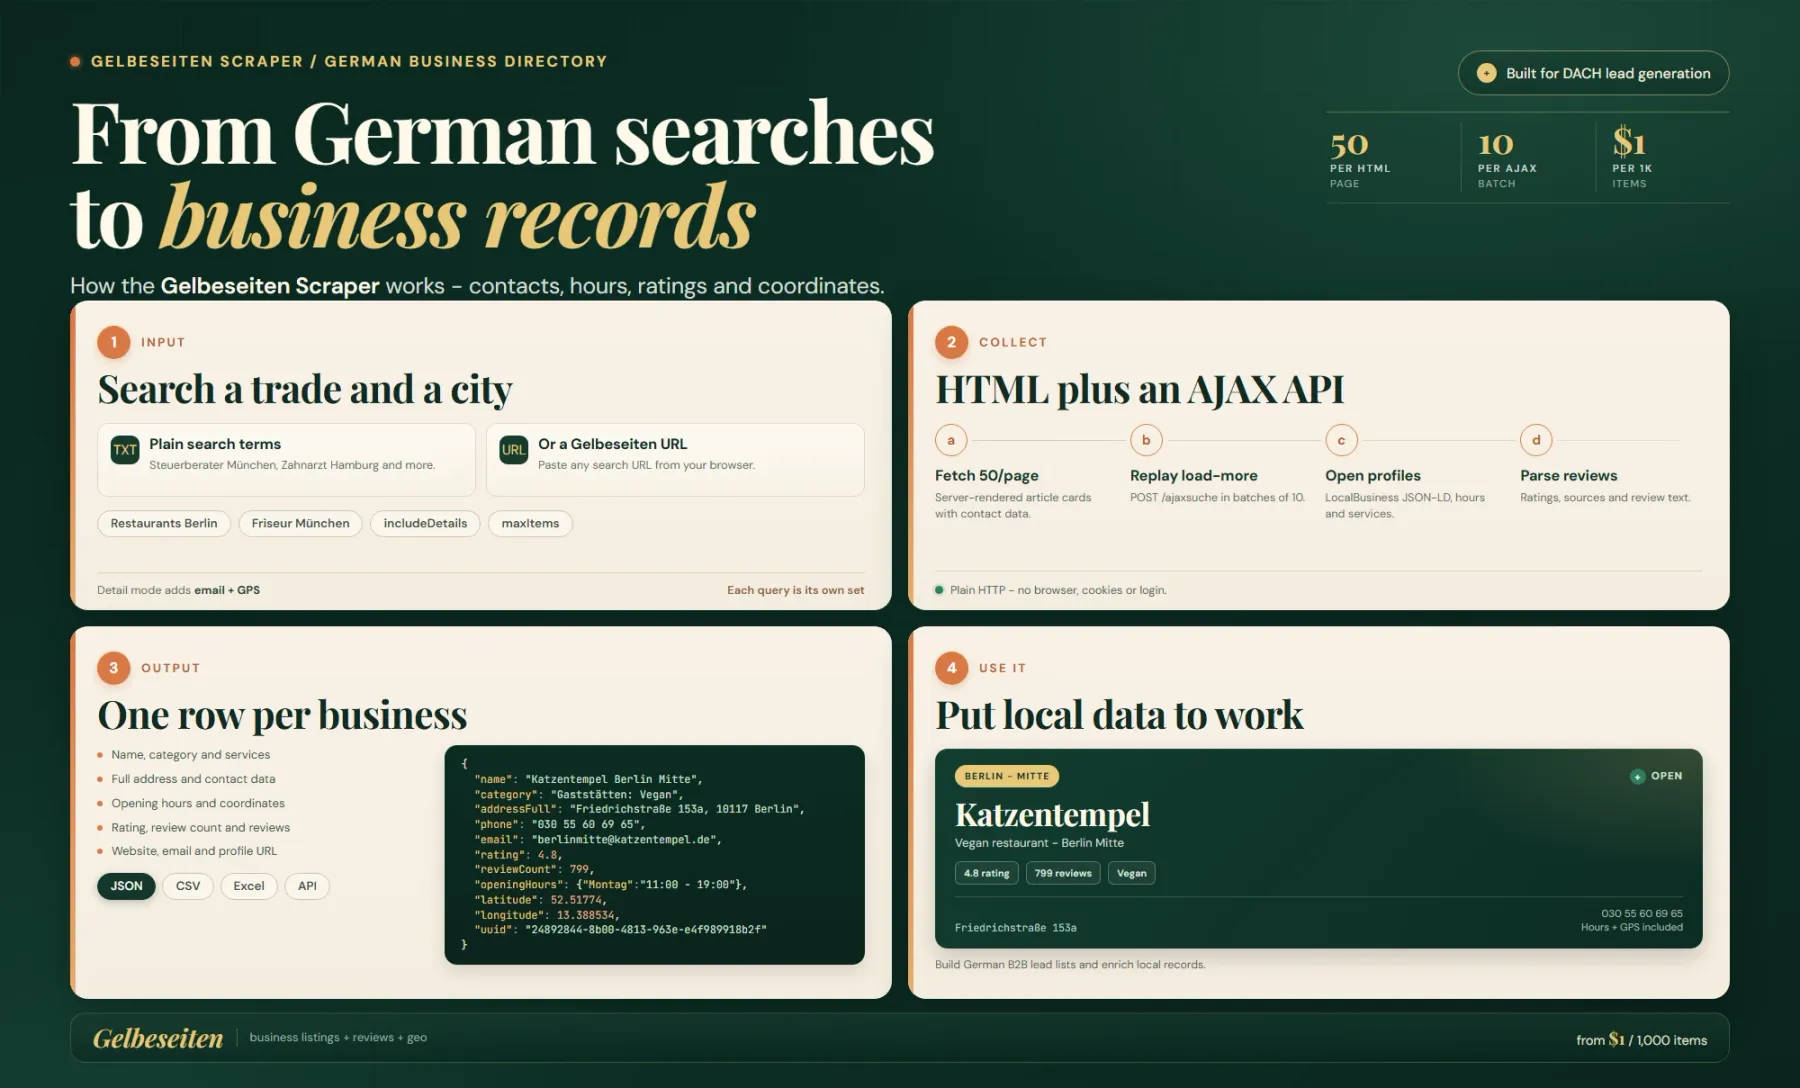
Search pages are server-rendered with 50 listings each, and the Actor replays the site's load-more AJAX endpoint in batches of 10. Detail pages add the LocalBusiness JSON-LD, opening hours, services, email, coordinates and individual reviews.
Each row covers one business with name, categories, full address, phone, website, rating and review count. Detail mode adds email, GPS, hours, service scope, rating sources and review text.
The actor is a CheerioCrawler — plain HTTP plus HTML parsing, no browser and no JavaScript rendering. Every data point is available in server-rendered HTML or an internal JSON API:
-
Search results page —
GET https://www.gelbeseiten.de/suche/<was>[/<wo>]Server-rendered HTML with 50 listings per page (<article class="mod mod-Treffer">). Each listing carries name, category, address, phone, website (base64 indata-webseitelink) and rating. Seed entries can be plain search terms or full search URLs — both are supported. -
Pagination — internal JSON API —
POST https://www.gelbeseiten.de/ajaxsucheThis is the backend of the "Mehr Anzeigen" load-more button and returns clean JSON:{ "anzahlTreffer": 10, "anzahlMehrTreffer": 10, "html": "<article class=\"mod mod-Treffer\">…</article>…" }The form fields (
WAS,WO,umkreis,verwandt,anzahl) are read from the hidden "Mehr Anzeigen" form on the search page itself, so the actor paginates correctly for both plain terms and URL seeds. The server caps each batch at 10 items; the actor walks batches untilmaxItemsis reached.anzahlMehrTrefferis a constant10and is not a reliable "has more" signal — the actor uses the number of articles actually returned in each batch instead. -
Business detail page —
GET https://www.gelbeseiten.de/gsbiz/<uuid>(only withincludeDetails: true) Server-rendered HTML containing anapplication/ld+jsonLocalBusinessblob (authoritative forlatitude,longitude,telephone,addressandsameAswebsite) plus:- opening hours (
#oeffnungszeiten .mod-Oeffnungszeiten__*) - categories and services (
#branchen_und_stichworte) - reviews and rating sources (
#bewertungen .mod-Bewertungen__*) - email (
mailto:on the "E-Mail" action button) - description (
#beschreibung)
- opening hours (
All surfaces are plain HTTP — no Cloudflare challenge was encountered for these endpoints, and no cookies or authentication are required.
Search-only mode vs full-detail mode
| Mode | Detail pages | What you get |
|---|---|---|
Search results only (includeDetails: false, default) | not opened | Name, category, full address, phone, website, rating and review count, profile URL — everything on the search results page. No extra requests. |
Full details (includeDetails: true) | opened (1 extra request per business) | Everything above plus email, geo coordinates, opening hours, services, per-source ratings, individual reviews and description. Billed via the business-detail pay-per-event. |
Input Parameters
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
queries | string[] | Yes | ["Restaurants Berlin"] | Search terms ("Friseur München", "Zahnarzt Hamburg") or full Gelbeseiten search URLs copied from your browser (https://www.gelbeseiten.de/suche/restaurant/berlin). Each entry is scraped as a separate result set. |
maxItems | integer | No | 20 | Maximum listings to scrape per query or URL. Pagination runs automatically until this number is reached. Minimum 1. |
includeDetails | boolean | No | false | Open each business detail page (one extra request per business, billed as the business-detail event). Adds email, geo coordinates, opening hours, services and reviews. |
proxy | object (proxy) | No | Apify Proxy off | Standard Apify proxy picker. |
Output Fields
One dataset item per business listing.
| Field | Type | Available in | Description |
|---|---|---|---|
name | string or null | both | Business name. |
category | string or null | both | Primary branch (Branche). |
categories | string[] | both | All branches listed for the business. |
services | string[] | details | Service scope (Leistungsumfang), e.g. ["Frühstück", "Brunch", "Vegan"]. |
street | string or null | both | Street and number. |
zip | string or null | both | Postal code. |
city | string or null | both | City. |
district | string or null | both | City district (e.g. Mitte), when published. |
addressFull | string or null | both | Full postal address. |
phone | string or null | both | Phone number. |
email | string or null | details | Email address, when published. |
website | string or null | both | Website URL. |
latitude | number or null | details | Latitude, from the detail page JSON-LD. |
longitude | number or null | details | Longitude, from the detail page JSON-LD. |
openingHours | object | details | Opening hours per weekday, e.g. {"Montag": "11:00 – 19:00"}. |
openingHoursNotes | string[] | details | Extra notes about opening hours. |
rating | number or null | both | Aggregate rating (0–5). |
reviewCount | integer or null | both | Number of reviews. |
ratingSources | object[] | details | Per-source ratings (golocal, google, resmio, …) with source, rating and count. |
reviews | object[] | details | Individual reviews with rating, date, author, text, source and sourceUrl. |
description | string or null | details | Business description. |
id | string or null | both | Internal Gelbe Seiten participant (Teilnehmer) ID. |
uuid | string or null | both | UUID of the business profile on gelbeseiten.de. |
url | string | both | Gelbeseiten detail page (profile) URL. |
query | string | both | The search term or search URL this listing was found with. |
scrapedAt | string | both | ISO 8601 timestamp of when the record was created. |
Example Input
The smallest input that produces results:
Example Output
With includeDetails: true (Katzentempel Berlin Mitte):
With includeDetails: false, detail-only fields are null or empty: email, latitude, longitude, openingHours, openingHoursNotes, services, ratingSources, reviews, description.
Integrations & Automation
- Apify API — start a run programmatically and read results from the default dataset; every run also exposes the dataset as JSON, CSV, Excel, XML or through Apify's table view.
- Webhooks — get notified when a run finishes, then push new German business leads into your CRM or database.
- Zapier / Make / n8n — connect the actor through Apify's no-code integrations to write results to Google Sheets, Airtable, HubSpot or Slack.
- Scheduling — run the actor weekly to catch newly listed businesses for a category, or monthly to refresh an existing German lead list; diff by
uuidto detect new or changed listings.
Related Actors
- 11880.com Business Directory Scraper — a second leading German business directory; combine it with Gelbe Seiten for wider German B2B lead coverage.
- BBB Business Directory Scraper — the largest business-directory actor in the Store; use it for US directory coverage alongside German data.
- PagesJaunes Scraper — French Yellow Pages business listings, the same structured-lead approach for France.
- PagineGialle Scraper — Italian Yellow Pages listings with phone, address and website.
- Yell.com Scraper — UK Yellow Pages business listings for British lead generation.
Frequently Asked Questions
Why use this actor instead of the official Gelbe Seiten API?
Gelbe Seiten does not publish a documented public developer API for third-party access to its directory. Third-party "Gelbe Seiten APIs" are either resellers wrapping the same public pages or a commercial enrichment service built on a different data source (for example the German commercial register). This actor reads gelbeseiten.de's own public pages directly and returns one structured row per business — no API key, no account and no approval step.
What are alternatives to this actor or to Gelbe Seiten data?
- Other Gelbe Seiten scrapers in the Apify Store — several cover the same public pages; compare on price per result, whether detail pages are included and which fields are parsed.
- Other directories — 11880.com and WLW.de cover German businesses from different sources.
- Commercial firm data — CompanyData and Firmium sell German company data sourced from the official Handelsregister (commercial register) rather than the Yellow Pages; useful when you need register numbers, legal form and financials, not local-business contact details.
- Managed scraping services — providers such as Bright Data and Octoparse offer Gelbe Seiten templates on a subscription model.
Does Gelbe Seiten have an API?
No. Gelbe Seiten does not offer a documented public API. This actor provides API-style structured access by reading the public site and returning JSON, CSV or Excel you can call over the Apify API.
How do I scrape German business leads from Gelbe Seiten?
Pass one or more trade-and-city queries in queries (e.g. "Steuerberater München") and run the actor. Each run returns one row per business with the name, address, phone, website and rating from the search page; enable includeDetails to add email, opening hours, services and reviews.
How can I build a German B2B company list or Firmendatenbank?
Run the actor across your target categories and cities, then map the output fields — name, categories, addressFull, phone, email, website, openingHours, rating — into your CRM or warehouse. Every row carries url and scrapedAt for provenance.
How do I get business emails from Gelbe Seiten?
Emails are published on business detail pages, not on the search results page. Set includeDetails: true to open each detail page and capture email (plus geo coordinates, opening hours and reviews). This adds one request and one business-detail charge per business.
Is scraping Gelbe Seiten GDPR-compliant?
The actor returns publicly published business data, but many German listings are sole traders or small businesses, so a row can contain personal data (a person's name and email). You are responsible for complying with the GDPR/DSGVO and Gelbe Seiten's terms when you use the data — including any duty to inform data subjects when you did not collect the data from them directly. The url and scrapedAt fields exist to support that traceability.
How do I keep a German business list up to date?
Schedule the actor to run weekly or monthly against your queries and compare runs by uuid to detect businesses that are new or whose details changed since the previous run.
For AI Agents & LLM Apps
Purpose: return one row per public business listing from gelbeseiten.de (German Yellow Pages) for a list of trade-and-city queries or search URLs — name, category, address, phone, website, rating and review count, plus optional email, coordinates, opening hours, services and reviews.
Minimal working input:
Full-detail variant (adds email, geo coordinates, opening hours, services, reviews):
URL-seed variant (reuse a search URL copied from a browser):
Output fields: name, category, categories, services, street, zip, city, district, addressFull, phone, email, website, latitude, longitude, openingHours, openingHoursNotes, rating, reviewCount, ratingSources, reviews, description, id, uuid, url, query, scrapedAt.
Behaviors an agent should know:
queriesis required — an empty list produces no output.- Free (non-paying) runs are hard-capped at 10 listings per query; only paying runs return the full
maxItems. includeDetails: false(default) returns search-page fields only.email,latitude,longitude,openingHours,services,ratingSources,reviewsanddescriptionare only populated withincludeDetails: true.includeDetails: trueadds one extra request per business and onebusiness-detailcharge per business opened.- Pagination is automatic and proceeds in server-side batches of 10 items after the first 50-item page.
- Long review texts are truncated by Gelbe Seiten server-side (they end with
......); the actor returns the text as served. - The search page's
rating/reviewCountmay differ slightly from the aggregate shown on the detail page, because Gelbe Seiten mixes review sources. - Payment methods are not published on Gelbe Seiten business pages, so that field is not extracted.
Billing: pay-per-event — $1 per 1,000 dataset items ($0.001 each), plus $1 per 1,000 business-detail enrichments ($0.001 each) when includeDetails is on, plus a small per-run start fee.
Legal & Compliance Disclaimer
This actor is an independent tool and is not affiliated with, endorsed by or sponsored by Gelbe Seiten (gelbeseiten.de).
It accesses only the publicly available pages that gelbeseiten.de serves to any anonymous visitor; it does not log in, bypass authentication, solve CAPTCHAs or access non-public data.
You are responsible for ensuring your use complies with Gelbe Seiten's terms of service and with applicable data-protection law. Because German directories list many sole traders and small businesses, a record can contain personal data (a person's name and email address). If you use this data for outreach, you are responsible for compliance with the GDPR/DSGVO — including the duty to inform data subjects when you did not collect the data from them directly — and with any restrictions on unsolicited commercial contact.
SEO Keywords
gelbeseiten scraper, gelbe seiten scraper, gelbe seiten api, gelbe seiten api alternative, german business directory scraper, german business leads, b2b leads germany, firmendaten, firmenverzeichnis, branchenverzeichnis, scrape gelbeseiten, germany company data, local business leads germany, lead generation germany, dach lead generation, business listing scraper, company email list germany, german yellow pages scraper, firmendatenbank, local seo germany, german business data export, gelbeseiten to json, gelbeseiten to csv, b2b company data germany, germany market research data


