
Hirist Scraper [$1.5/1K💰] | India Tech Jobs | Salaries
Pricing
from $1.40 / 1,000 results
Hirist Scraper [$1.5/1K💰] | India Tech Jobs | Salaries
Scrape tech job listings from Hirist — titles, companies, locations, salary ranges in LPA, experience, skills and application links — keyless, no browser. Built for recruitment research and job-market intelligence across India. $1.50 per 1,000 jobs.
Pricing
from $1.40 / 1,000 results
Rating
0.0
(0)
Developer
Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
14 days ago
Last modified
Categories
Features
Share
Hirist Scraper
Scrape tech job listings from Hirist (hirist.tech) — one of India's largest tech-focused job boards — with titles, companies, locations, salary ranges, experience, skills and application links, keyless and browser-free, at $1.50 per 1,000 jobs.
Built for:
- Recruitment agencies and HR-tech teams building India tech talent pipelines
- Job-market intelligence: which skills, roles and cities are hiring
- Aggregating Indian software job listings into your own database
- Salary benchmarking (LPA ranges where employers publish them)
- Career platforms and counselling services that need fresh tech openings
Collect Indian Tech Job Listings for Recruitment Research
Give the actor search keywords (java developer, data scientist, product manager) — each is paginated (50 jobs per page) up to maxPagesPerQuery — or paste Hirist job URLs directly for full-detail rows. Every job is one dataset item: title, designation, company, locations, experience (min/max), salaryMin/salaryMax in LPA with salaryHidden when employers hide pay, skills and mandatorySkills, remote, industry, companyRating, postedAt, jobUrl / applicationLink (external ATS link when provided), plus searchQuery for provenance. Turn on includeDescription to attach the full JD HTML per job.
How It Works
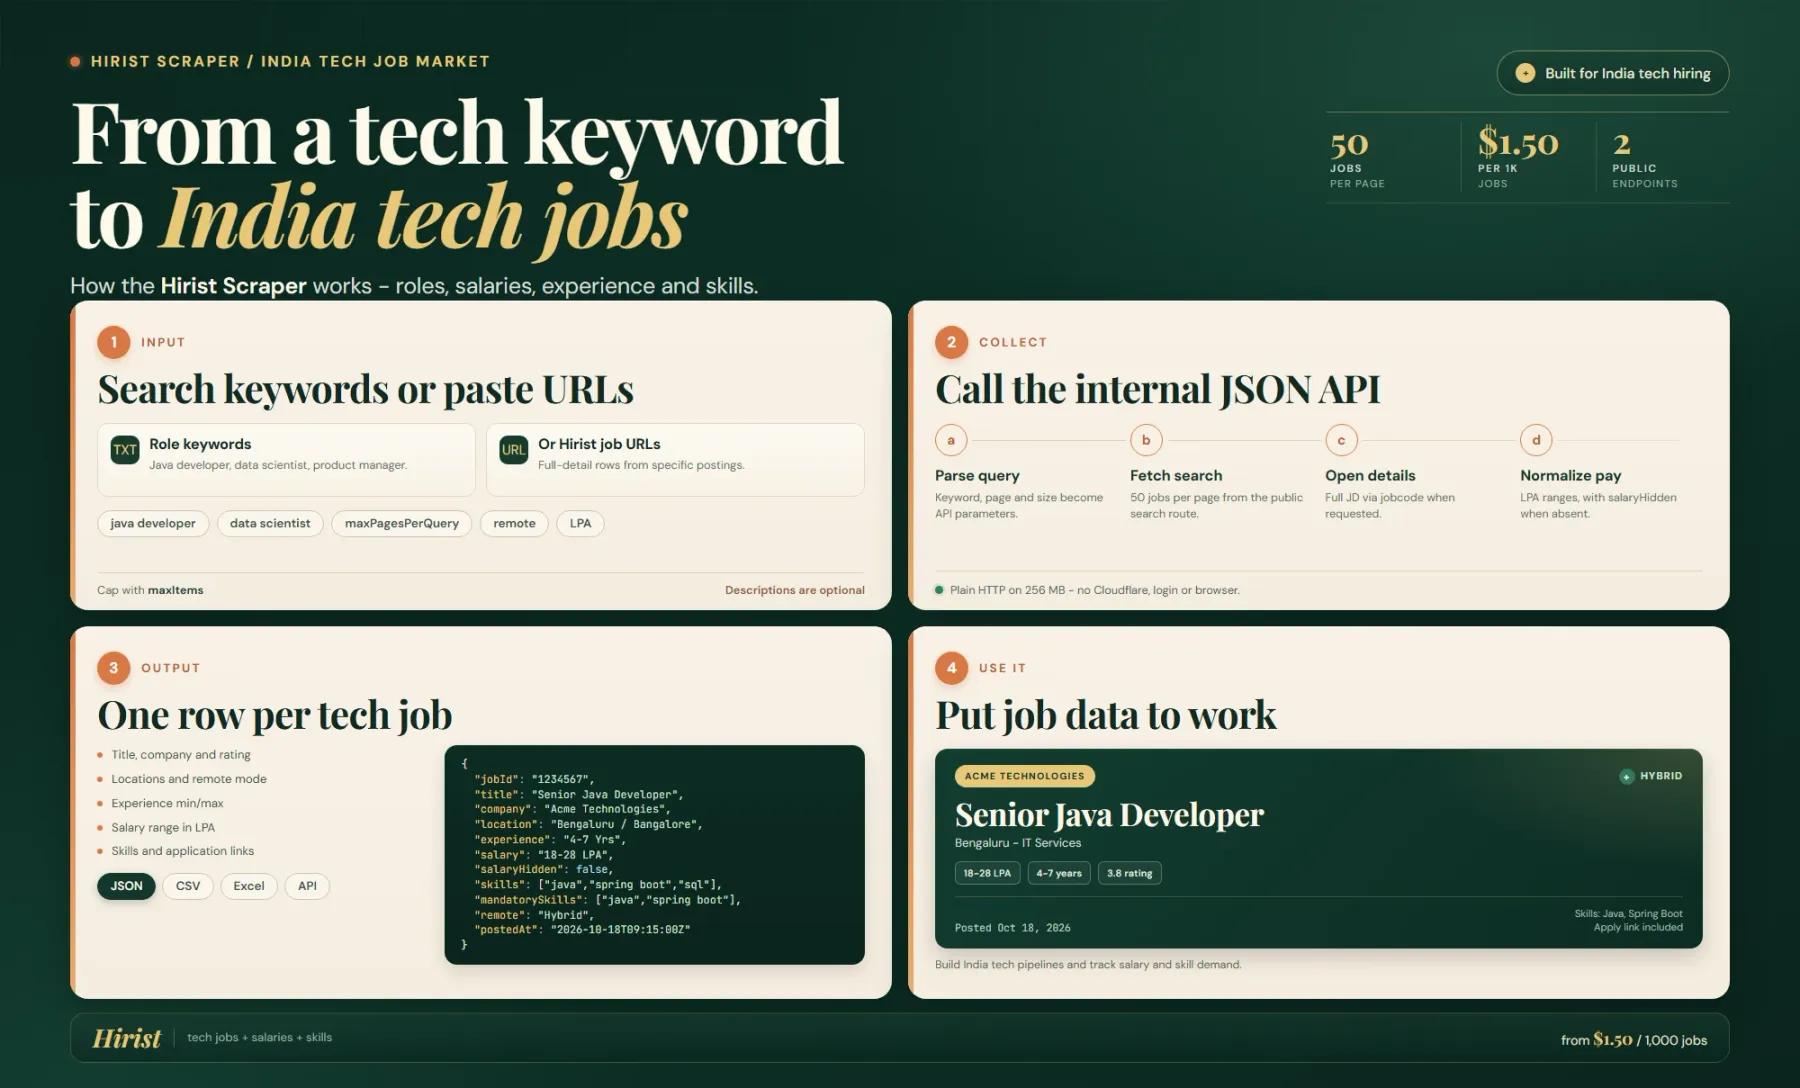
The Actor calls Hirist's public search JSON directly, 50 jobs per page, and the companion detail endpoint when full descriptions are requested. Both routes are keyless, browser-free and outside Cloudflare.
Each row covers one job with title, company, locations, remote mode, experience range, LPA salary range, hidden-salary flag, skills, mandatory skills, rating and application links.
Hirist is a Next.js app whose server-rendered HTML does not contain the job data — the page renders from a client-side call, and launching a browser for that would be wasteful. Instead the actor calls Hirist's own internal JSON API directly. Both endpoints are public, need no login or cookies, and are not Cloudflare-walled:
| Purpose | Endpoint |
|---|---|
| Keyword search (paginated) | GET https://gladiator.hirist.tech/job/search?query=<keyword>&page=<0-based>&size=<n> |
| Full job detail (complete JD) | GET https://gladiator.hirist.tech/job/detail?jobcode=<jobId> |
The API base was reverse-engineered from the site's Next.js build manifest and client-side JS bundles; required headers (version: 2, browser User-Agent, Referer/Origin: https://www.hirist.tech) are set by the actor. Because the surface is plain JSON, extraction runs as a CheerioCrawler (HTTP only) on 256 MB of memory — no browser rendering. The authenticated /job/jobfeed route (401 without a session) is not used.
Input Parameters
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
searchQueries | array | No* | [] | Job keywords, e.g. ["java developer", "data scientist"]; pages are scraped for each. |
startUrls | array | No | [] | Hirist job URLs (https://www.hirist.tech/j/...-<id>) fetched directly with full detail. |
maxItems | integer | No | 100 | Max jobs saved to the dataset. |
maxPagesPerQuery | integer | No | 5 | Result pages per keyword (50 jobs each). |
includeDescription | boolean | No | false | Enrich each job with the full description (one extra request per job). |
proxy | object | No | disabled | Standard Apify proxy picker; off by default (the API does not require it). |
* Provide at least one search query or job URL.
Output Fields
One dataset item per job:
- Role:
jobId,title,designation,description(whenincludeDescriptionis on),postedAt,jobUrl,applicationLink,applyUrl,searchQuery,isDetail - Company:
company,companyLogo,companyRating,industry,functionalArea,categoryId,recruiterName - Location & mode:
locations,location,remote - Compensation & experience:
experienceMin,experienceMax,experience,salaryMin,salaryMax,salary,salaryHidden(salary values are in LPA — lakhs per annum; hidden when the employer doesn't publish pay) - Skills:
skills,mandatorySkills(the required subset)
Example Input
Example Output
Automate Job-Market Monitoring With Schedules & Webhooks
- Daily new-roles feed: schedule per keyword and diff rows by
jobIdto surface openings posted since the last run (postedAtsupports the ordering). - Skill-demand tracking: aggregate
mandatorySkills/skillsover weekly runs to chart which technologies hiring in India's tech market. - Pipeline alerts: attach a dataset webhook so rows matching seniority or city criteria reach your ATS or Slack automatically.
- Recurring, re-run-heavy usage also improves this actor's Store recommendation signals.
Related Actors
- Naukri Job Scraper | India & Gulf Jobs — the most-used India job-market actor on the Store; broaden coverage beyond tech.
- Naukri Jobs Scraper - India & Gulf Jobs, 60+ Fields — Naukri coverage with an expanded field set.
- Instahyre Jobs Scraper: India Tech Jobs & Hiring Monitor — another India tech-job board, good for cross-board comparison.
- Instahyre Jobs Scraper — India Tech Jobs & Hiring Monitor — Instahyre coverage as an alternative.
- IIMJobs Jobs Scraper – MBA, Finance & Management Jobs India — management/finance roles in India, complementary to tech listings.
Frequently Asked Questions
Why use this actor instead of the official API?
Hirist has no official public API. Its jobfeed route requires a logged-in session (it answers 401 without one), and the site itself renders listings client-side, so there is no static HTML to parse either. This actor calls the public JSON endpoints the Hirist front end uses — no login, no cookies, no browser — and turns them into a paginated dataset with caps, exports, scheduling and webhooks.
Is there a Hirist API?
Not an official one. Community scrapers on GitHub have documented adjacent Hirist endpoints over the years, but nothing is published, versioned or guaranteed. The endpoints used here (gladiator.hirist.tech/job/search and /job/detail) are public and unauthenticated as of the actor's last update; if Hirist changes them, the actor needs a small update — which is exactly the maintenance burden this actor takes on for you.
How do I scrape Indian tech job listings at scale?
Enter several keywords, set maxItems and maxPagesPerQuery, and run — results across all pages are collected per keyword. For broader India/Gulf coverage or non-tech roles, pair it with the Naukri and IIMJobs actors listed under Related Actors; for another India tech board, add Instahyre.
What salary fields are returned, and in what unit?
salaryMin / salaryMax are in LPA (lakhs per annum) with a formatted salary string. Many employers hide pay on Hirist — then salaryHidden is true and salary fields are null. Use salaryHidden: false filters downstream when you only want pay-transparent rows.
Do I need a login or API key?
No — both endpoints are public and read without any account. Free Apify accounts get a capped preview (10 items); paid accounts unlock the full input caps. includeDescription: false (default) keeps runs fast; enable it only when you need full JDs.
For AI Agents & LLM Apps
Purpose: returns Indian tech job listings from Hirist — title, company, location, experience, LPA salary, skills, apply links — keyless, HTTP only.
Minimal input:
Direct-URL variant:
Output fields: jobId, title, designation, company, companyLogo, locations, location, experienceMin, experienceMax, experience, salaryMin, salaryMax, salary, salaryHidden, skills, mandatorySkills, remote, industry, functionalArea, categoryId, companyRating, postedAt, applicationLink, applyUrl, jobUrl, recruiterName, description, searchQuery, isDetail.
Behaviors an agent should know:
- Provide
searchQueriesand/orstartUrls; pagination is 50 jobs per page andmaxPagesPerQuery(default 5) bounds each keyword. includeDescriptiondefaults tofalse— each enabled job costs one extra request, so turn it on deliberately.- Salary values are LPA (lakhs per annum), and
salaryHidden: truemeans the pay fields arenull. - Free accounts are capped at a 10-item preview per run regardless of input.
- No proxy is needed by default; the actor runs at concurrency 5 with 3 retries and a 60 s per-request timeout.
Billing: pay-per-event — result at $0.0015 per saved job, plus a run-start event.
Legal & Compliance Disclaimer
This actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Hirist (hirist.tech). It reads only public, unauthenticated JSON endpoints — no login, no session cookies, no browser automation against the site, and no authenticated feed. Job listings can contain recruiter names and company details; users are responsible for their own compliance with Hirist's Terms of Service and applicable data-protection law (e.g. India's DPDP Act, GDPR where relevant) when storing, redistributing or automating access to the collected data.
SEO Keywords
hirist scraper, hirist api, scrape hirist jobs, hirist.tech jobs, india tech jobs data, indian job listings api, software developer jobs india, tech job board scraper, job market data india, remote jobs india data, recruitment research data, java developer job data, salary data india tech jobs, job listing database india, hirist alternative, data scientist jobs india, tech hiring data india, job scraping api india, engineering jobs data, indian tech salary data


