
Facebook Ads Library Scraper [$0.13/1K💰] | Meta & IG Ad Spy
Pricing
from $0.11 / 1,000 results
Facebook Ads Library Scraper [$0.13/1K💰] | Meta & IG Ad Spy
Spy on any brand's Facebook & Instagram ads with no login or Meta API token. Scrape ad copy, creatives, CTA, landing pages, run dates and EU reach into 46-field JSON rows — and track new, edited and ended ads on a schedule.
Pricing
from $0.11 / 1,000 results
Rating
0.0
(0)
Developer
Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
2
Monthly active users
a day ago
Last modified
Categories
Share
Facebook Ads Library Scraper — Meta & Instagram Ads Without A Login
Extract every ad a brand runs on Facebook and Instagram from the public Meta Ad Library into 50+ field JSON rows — ad copy, creatives, CTA, landing URL, run dates and EU/UK/BR reach — with no Meta API token, no login and no browser. At $0.13 per 1,000 ads it is the lowest per-ad price among the Meta Ad Library scrapers on the Apify Store, and it tracks new, edited and ended ads across scheduled runs.
Main Use Cases: Competitor Ad Spying, Creative Research And Ad Monitoring
- Facebook ad spy / competitor ad analysis — pull every active ad an advertiser is running, then read the copy, creative, CTA and landing page to reverse-engineer their angles.
- Creative swipe file — the raw
image_urls,video_urlsandcarousel_cardslet you download the winning creatives in bulk instead of screenshotting them one by one. - Ad running-days intelligence —
running_days/total_active_timeshow which creatives a brand keeps spending on; long-running ads are the strongest available proxy for a proven winner. - Competitor ad monitoring on a schedule — a
watchlistIdremembers every ad already delivered, so daily runs return only the ads that arenew,editedorended. - Dropshipping and e-commerce product research — search by keyword across a whole niche (e.g. "weight loss", "black friday") and export the full Meta Ad Library result set to CSV or Excel.
- EU / UK / Brazil transparency and reach data — for regulated categories the rows carry Meta's own
data_reach,impressions_with_indexandtransparency_by_locationbreakdowns (age, gender, region).
How It Works
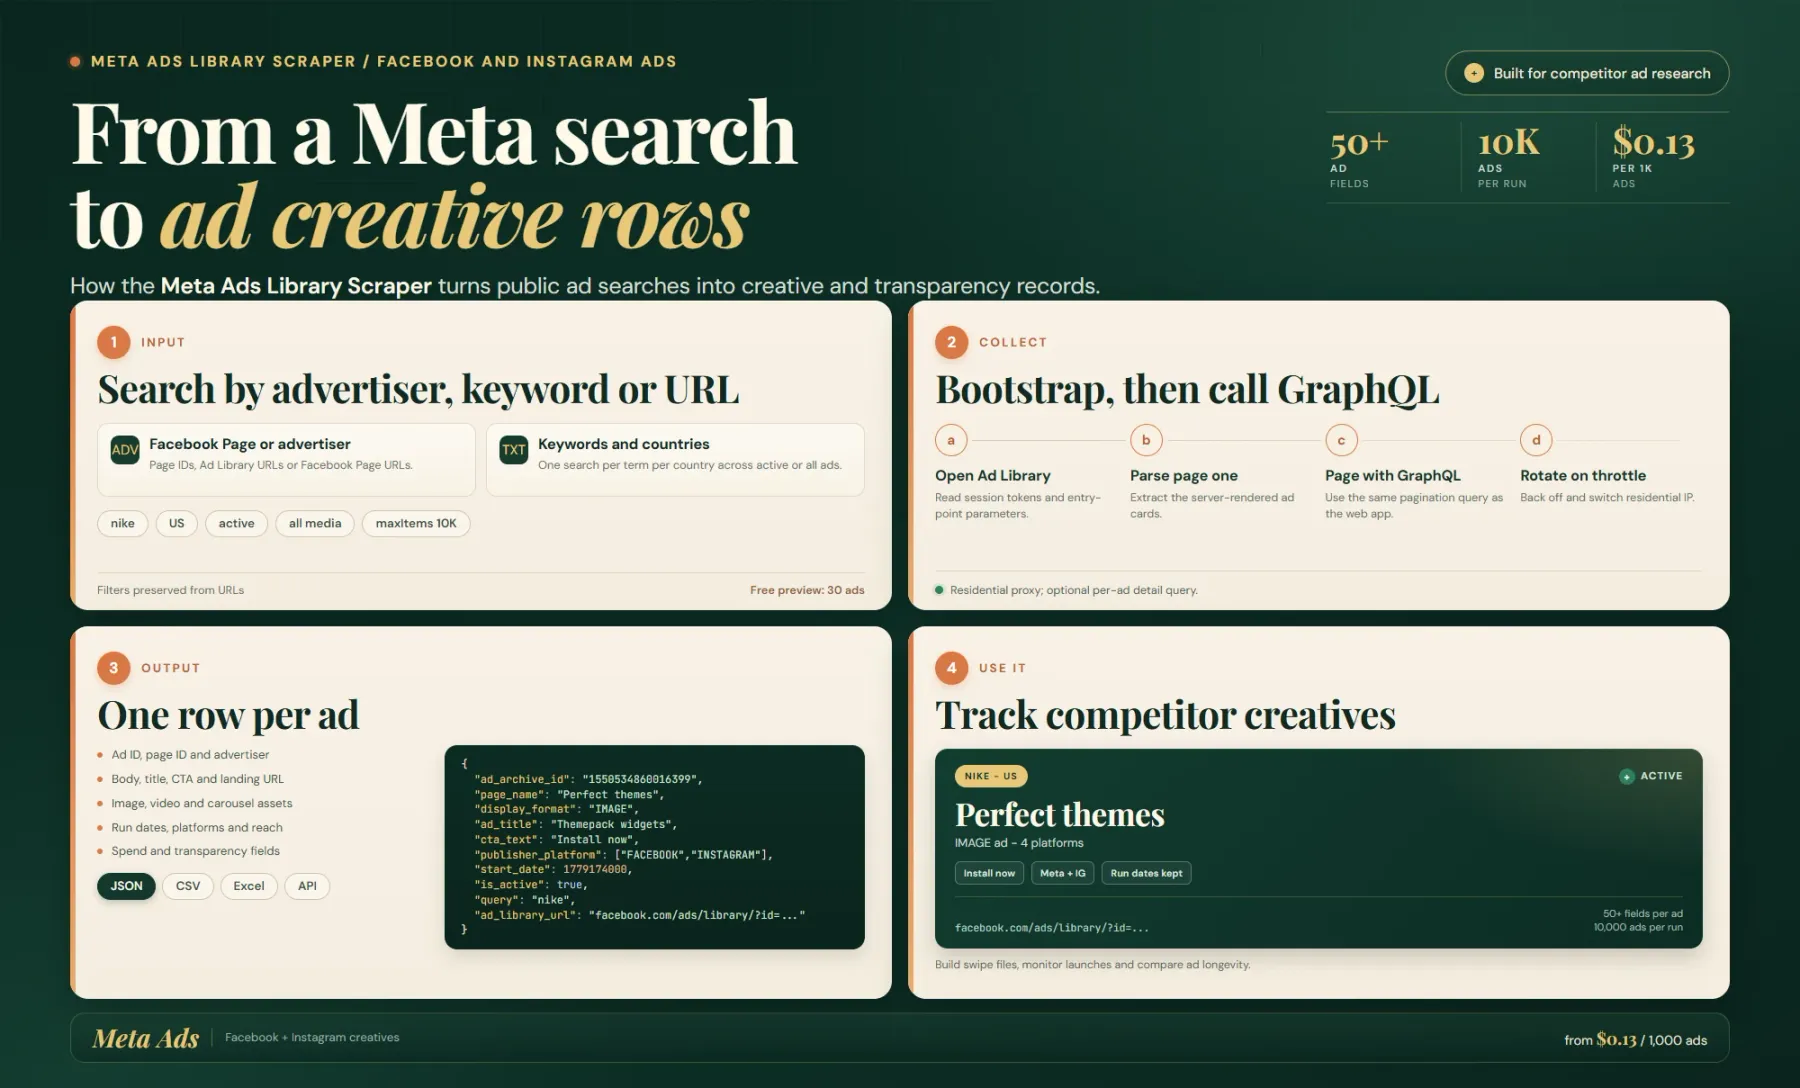
The Actor bootstraps the public Ad Library page to obtain the current session parameters, parses the server-rendered first page, then follows the same paginated GraphQL query the web app uses. Requests run through residential proxies with backoff and proxy rotation when Meta throttles; optional detail queries enrich individual ads.
Each row is one ad with 50+ top-level fields depending on format and detail mode, including advertiser identity, ad copy, CTA, landing URL, image/video/carousel assets, run dates, platforms, reach, spend and transparency objects. Search is by advertiser, keyword or Ad Library URL; no Meta login or official API token is required.
Extract Facebook & Instagram Ads Without A Meta API Token
The official Meta Ad Library API is built for transparency, not research: it returns political and social-issue ads worldwide plus all ad types only for the EU and the UK (the last 12 months), requires Facebook Developer credentials and app review, and expires its access token every 60 days. For commercial ads outside the EU/UK it returns nothing.
This actor reads Meta's own public Ad Library response instead, so it returns commercial ads from every country you name with no account, no app review and no token. Two things you should know before you scale it up:
- Country (
searchCountries) controls the result set, not the proxy exit country. - Pagination needs a residential-class proxy — Meta returns page 1 to any IP but serves the GraphQL pages only from high-quality IPs (
Rate limit exceeded, code1675004). The actor defaults to Apify Residential and rotates on throttle; passproxyonly to bring your own. - Meta only exposes reach/impression figures for the transparency categories (political/issue, housing, employment, credit). For everything else those fields are absent in Meta's own response — this actor does not invent them.
Meta Ad Library scrapers compared (verified, 2026-10-09)
| Actor | Price per 1,000 ads (BRONZE) | Notes |
|---|---|---|
| This actor | $0.13 | Cheapest verified; watchlist change tracking; no login |
jmlp/meta-ad-library-scraper | $0.15 | |
solidcode/meta-ads-library-scraper | $0.40 | |
memo23/facebook-ads-library-scraper-cheerio | $0.45 (+ $1/1K details) | Very close input schema |
igolaizola/facebook-ad-library-scraper | $0.50 | |
automation-lab/facebook-ads-library | $0.50 | |
azzouzana/meta-facebook-instagram-ads-library | $0.50 | |
scrapesage/facebook-ad-library-scraper | $0.75 | |
dltik/facebook-ads-scraper | $3.00 | Ad-spy positioning, AI add-ons |
brilliant_gum/facebook-ads-library-scraper | $15.00 | |
apify/facebook-ads-scraper | $5.00 + $3.20 e-commerce add-on | Official Apify, largest in the cluster |
Facebook Ads Library Scraper Input Parameters
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
startUrls | array | One of* | Ad Library "nike" URL | Full Meta Ad Library URLs (all filters honoured) or Facebook Page URLs. |
advertisers | array | One of* | [] | Facebook Page IDs, Ad Library URLs with view_all_page_id=…, or Page URLs — every ad of each advertiser is returned in full. |
searchTerms | array | One of* | [] | Keywords/brand names, one search per term per country. |
searchCountries | array | No | ["US"] | ISO‑2 country codes or ALL; each country is queried per term. |
adDetailIds | array | No | [] | Re-fetch specific ads by archive id or ?id=… link. |
adActiveStatus | string | No | active | active, inactive or all. |
mediaType | string | No | all | all, image or video. |
adType | string | No | all | all or a regulated category: political_and_issue_ads, housing_ads, employment_ads, credit_ads, financial_products_and_services_ads. |
publisherPlatforms | array | No | [] | facebook, instagram, messenger, audience_network. |
contentLanguages | array | No | [] | ISO 639‑1 creative languages (en, de, …). |
searchMode | string | No | keyword_unordered | keyword_exact_phrase for phrase matching. |
sortBy | string | No | "" | total_impressions for most-impressions-first. |
startDateMin | string | No | "" | YYYY-MM-DD lower bound on the ad start date. |
startDateMax | string | No | "" | YYYY-MM-DD upper bound on the ad start date. |
categories | array | No | [] | Keep only ads whose Meta category matches (case-insensitive). |
includeAdReach | boolean | No | false | Keep data_reach, reach_estimate and impression fields on every row. |
scrapeAdDetails | boolean | No | false | One extra GraphQL query per ad → advertiser, aaa_info and full transparency_by_location. Bills the additional_data event. |
includeTotalActiveAds | boolean | No | false | Ask Meta for the advertiser's total active ad count. |
filterDuplicatePageIds | boolean | No | false | Keep only the first ad per page_id. |
watchlistId | string | No | "" | Named memory of which ad_archive_ids this run already delivered. Letters, numbers, -, _. |
newAdsOnly | boolean | No | false | Drop already-seen ads (they are not billed). Requires watchlistId. |
trackChanges | boolean | No | false | Add change_type (new/edited/unchanged/ended). Requires watchlistId. |
emitEndedAds | boolean | No | false | Also emit rows for ended ads. Combine with trackChanges. |
raw | boolean | No | false | Emit only Meta's untouched ad node. |
maxItems | integer | No | 10000 | Hard cap on ads per run. Free Apify plan caps at 30 ads + 1 search target. |
detailsConcurrency | integer | No | 15 | Parallel per-ad detail queries when scrapeAdDetails is on. |
minDelay | number | No | 0 | Lower bound of the randomized pause after each GraphQL page. |
maxDelay | number | No | 1 | Upper bound of that pause. |
maxConcurrency | integer | No | 10 | Search targets processed at once. |
maxRequestRetries | integer | No | 8 | Retries with exponential backoff; throttled requests also rotate the proxy. |
proxy | object | No | (empty) | Leave empty — Apify Residential is used by default; set only for your own proxies. |
debug | boolean | No | false | Emit session tokens, chosen doc_ids and pagination progress. |
* The schema requires no field formally, but a run needs at least one target: startUrls, advertisers, searchTerms or adDetailIds.
Main Ad Fields Returned By The Facebook Ad Library Scraper
One dataset row per ad (50+ possible fields; recent samples expose 52 top-level keys, depending on ad format and detail mode). The dataset ships four views — Overview, Creatives, Transparency and Changes — and exports as JSON, CSV or Excel.
Ad identity (9) — ad_archive_id (row key for dedup and change tracking), page_id, page_name, Company Name, FB AD Link, ad_library_url, url, FB Link, Website.
Creative (10) — display_format, ad_body, ad_title, cta_text, cta_type, link_url, image_urls, video_urls, carousel_cards, and the raw snapshot (Meta's untouched creative object).
Run dates (7) — start_date, end_date (unix seconds), start_date_formatted, end_date_formatted (ISO 8601), running_days, total_active_time, is_active.
Delivery & transparency (10) — publisher_platform, categories, spend, currency, impressions_with_index, reach_estimate, data_reach, targeted_or_reached_countries, is_aaa_eligible, plus the detail-only advertiser, aaa_info, transparency_by_location, verified_voice_context, contains_digital_created_media, contains_sensitive_content.
Search context (5) — position, total, query, scraped_at, plus change_type when a watchlist is active. Raw fields such as snapshot, collation_count, collation_id, menu_items, regional_regulation_data, fev_info and the transparency objects are passed through when Meta returns them.
Example Input And Output: Facebook Ad Library Rows
Example input — an ad spy sweep over one brand keyword in two countries, with watchlist tracking:
Example output (one dataset row, values illustrative):
Competitor Ad Monitoring With Scheduled Watchlist Runs
The watchlist is the actor's change-tracking memory. It lives in the actor's key-value store under watchlist:<id> and survives across runs — point a schedule at one watchlistId and only new/changed ads are billed.
newAdsOnly— already-seen ads are dropped from the dataset (and not billed); the search still runs in full. RequireswatchlistId.trackChanges— every row gainschange_type:new,edited,unchanged, plusendedfor ads that stopped running.emitEndedAds— also emit rows for ended ads (combine withtrackChanges).
ended is produced only for a search that was scanned to completion in that run. If a run stops early (maxItems reached, or Meta throttles), nothing is marked ended — so a partial crawl can never mass-close ads. A recommended setup is a daily schedule on a competitor's Page ID or a keyword, with trackChanges: true, feeding a Slack or Sheets webhook.
Integrations & Automation
- Apify API — start runs, poll status and pull dataset items as JSON; the output
adsfield links to the default dataset items endpoint. Export JSON, CSV or Excel from the console. - Webhooks — fire on run success/failure to push only the
new/editedrows into a pipeline, Slack channel or Google Sheet. - Zapier and Make — trigger workflows on new dataset items (append to Sheets, create CRM/Airtable records, alert on a competitor's new creative).
- Schedules — for competitor ad monitoring, run daily or weekly against the same
watchlistId; recurring runs also feed the Apify Store recommendation signals that surface the actor in searches.
Related Actors
- apify/facebook-ads-scraper — the largest and most authoritative actor in the topic cluster (official Apify), covers Facebook, Instagram, WhatsApp, Threads.
- igolaizola/facebook-ad-library-scraper — the second-largest Meta Ad Library scraper by users.
- memo23/facebook-ads-library-scraper-cheerio — closest feature/schema parity, "richest schema" positioning with EU reach and transparency.
- automation-lab/facebook-ads-library — no-login Ad Library scraper by keyword, Page URL or pasted URL.
- solidcode/meta-ads-library-scraper — Ad Library scraping across Facebook, Instagram, Messenger, Audience Network, Threads and WhatsApp.
FAQ
What is the Meta Ad Library?
The Meta Ad Library (facebook.com/ads/library) is Meta's free, public transparency database. It shows all active ads running across Facebook, Instagram, Messenger and the Audience Network. Political and social-issue ads are archived for 7 years with spend and reach data; ads that reached the EU are archived for one year. This actor reads that public Ad Library and turns it into structured JSON.
Is there a Meta Ad Library API?
Yes, but it is narrow: Meta's official Ad Library API returns political/social-issue ads worldwide and all ad types only for the EU and UK (last 12 months). It requires Facebook Developer credentials, app review and a token that expires every 60 days — and returns no commercial ads outside the EU/UK. This actor is the alternative that returns commercial ads from any country without a token.
What are the limitations of the Meta Ad Library API?
Documented limits (2026): political/EU-only content scope, bucketed spend ranges rather than exact figures, strict per-hour call limits, mandatory app review, and 60-day token expiry. There is no official API for commercial ads outside the EU/UK — which is the gap this actor fills by reading the public Ad Library directly.
Do I need a Meta login or API token to use this actor?
No. It runs against the public Ad Library with no account, no API key and no browser. The only requirement is that large paginated runs use a residential-class proxy (the actor defaults to Apify Residential, which is already configured) because Meta serves its GraphQL pages only to IPs of that quality.
Does this actor return Instagram ads?
Yes. The Meta Ad Library covers Facebook, Instagram, Messenger and the Audience Network; every row reports publisher_platform, and you can narrow a run with the publisherPlatforms input (e.g. ["instagram"]).
How do I download all ads from the Meta Ad Library?
Give the actor a searchTerms keyword, an advertisers Page ID, or a full startUrls Ad Library URL. It paginates the entire result set automatically (raise maxItems for a complete crawl) and writes one row per ad, which you can export as JSON, CSV or Excel — including the image_urls and video_urls creative assets.
Why is my run returning only a few ads?
Two common reasons: (1) on a free Apify plan a run is capped at 30 ads and one search target — paid plans remove both caps; (2) Meta throttled pagination, in which case the actor rotates to a fresh residential IP and reports an empty page rather than silently stopping. Watch the run log (debug: true) and raise maxItems for a full crawl.
What are the alternatives to this actor?
Other Meta Ad Library scrapers on the Apify Store include apify/facebook-ads-scraper (official, multi-platform), igolaizola/facebook-ad-library-scraper, memo23/facebook-ads-library-scraper-cheerio, automation-lab/facebook-ads-library, solidcode/meta-ads-library-scraper and jmlp/meta-ad-library-scraper. Beyond Apify, paid ad-spy tools (Minea, BigSpy, Foreplay, AdSpy) add multi-platform coverage and saved swipe files on subscription, while this actor gives you the raw Meta rows on a pay-per-ad basis.
How do I track when a competitor changes their ads?
Set a watchlistId and turn on trackChanges (add emitEndedAds to also receive ads that stopped). Every subsequent run labels each ad new, edited, unchanged or ended, so you can detect a rewritten creative or a launched campaign without diffing exports by hand.
SEO Keywords
facebook ads library scraper, meta ad library scraper, facebook ads library api, meta ad library api, facebook ad spy, ad spy tool, competitor ads analysis, download facebook ads, scrape facebook ads without login, facebook ads library download, facebook ads library search, competitor ad tracking, ad library api, instagram ad library, meta ads library scraper, facebook ads scraper, dropshipping ad spy, ecommerce competitor ads, facebook ads transparency, political ads api, eu ad transparency data, facebook ads library bulk download, ad creative research, ad library alternative
For AI Agents & LLM Apps
Purpose: return structured Meta Ad Library ads (one JSON object per ad, 50+ fields) for a keyword, advertiser Page ID or Ad Library URL, without a login, token or browser.
Minimal working input:
Variant — ad spy by advertiser Page ID with change tracking:
Output fields (one dataset object per ad): ad_archive_id, page_id, page_name, Company Name, FB AD Link, ad_library_url, url, FB Link, Website, display_format, ad_body, ad_title, cta_text, cta_type, link_url, image_urls, video_urls, carousel_cards, snapshot, start_date, end_date, start_date_formatted, end_date_formatted, running_days, total_active_time, is_active, publisher_platform, categories, spend, currency, impressions_with_index, reach_estimate, data_reach, targeted_or_reached_countries, advertiser, aaa_info, transparency_by_location, verified_voice_context, is_aaa_eligible, contains_digital_created_media, contains_sensitive_content, position, total, query, change_type, scraped_at, plus raw collation, menu, regulation and transparency objects when present.
Behaviors an agent should know:
- At least one target is needed:
startUrls,advertisers,searchTermsoradDetailIds. A run with none produces no rows. searchCountriescontrols the result set; the proxy exit country is separate and does not filter results.scrapeAdDetails: trueissues one extra billedadditional_dataquery per ad and impliesincludeAdReach;includeTotalActiveAdsadds another request per advertiser.newAdsOnly,trackChangesandemitEndedAdsrequirewatchlistId; without it they do nothing. Already-seen ads skipped bynewAdsOnlyare not billed.endedis only emitted for a search scanned to completion in that run — a run cut short bymaxItemsor throttling marks nothing as ended. DefaultmaxItemsis10000; on a free Apify plan a run is capped at 30 ads and one search target.- Pagination requires residential-class IPs; leave
proxyempty to use the built-in Apify Residential rotation (minDelay/maxDelaypace GraphQL calls;maxConcurrencycaps targets at 10 by default). - Data is emitted only for ads Meta actually returns — reach/impression fields exist only for the transparency categories (political/housing/employment/credit) and EU/UK/BR delivery.
Billing: pay-per-event — apify-actor-start ($0.00005), result ($0.00013 per emitted ad on FREE/BRONZE, lower on higher tiers), additional_data ($0.0004 per scrapeAdDetails query). Ads filtered out by newAdsOnly/filterDuplicatePageIds are not billed.
Legal & Compliance Disclaimer
- This is an independent third-party tool. It is not affiliated with, endorsed by, sponsored by or connected to Meta Platforms, Inc., Facebook or Instagram.
- The actor reads only publicly available Ad Library data (Meta's server-rendered search page and the same GraphQL queries the public Ad Library web app issues). It does not log in, bypass authentication, defeat CAPTCHAs or access private data.
- You are solely responsible for ensuring your runs and your use of the output comply with Meta's Terms of Service and applicable data-protection law. Because rows can include EU/UK ad transparency data, GDPR obligations may apply to how you store and process that data.
- The output describes advertisers and their creatives. Do not use it for unlawful targeting or for unsolicited commercial outreach that violates applicable law.
- Data is provided as-is with no warranty of completeness or accuracy; the Ad Library changes constantly and Meta may throttle or alter its responses at any time.


