Yupoo Downloader [💰$0.5/1k] | Bulk Images | Albums | Catalog
Pricing
from $4.97 / 1,000 product/album catalog records
Yupoo Downloader [💰$0.5/1k] | Bulk Images | Albums | Catalog
Download Yupoo album images in bulk with catalog extraction for wholesale product photography
Pricing
from $4.97 / 1,000 product/album catalog records
Rating
0.0
(0)
Developer

Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
99
Total users
2
Monthly active users
10 hours ago
Last modified
Categories
Share
Yupoo Bulk Image Downloader
Extract and download images from Yupoo photo albums at scale. This actor scrapes high-resolution product photos, gallery images, and catalog content from Yupoo-hosted albums, making it ideal for wholesale product photography, sneaker catalogs, and brand inventory management.
What It Does
The Yupoo Bulk Image Downloader fetches image URLs from Yupoo album pages, resolving direct links to original high-resolution photos. It handles multi-image albums, pagination, and catalog navigation to deliver a complete dataset of image metadata including URLs, dimensions, file sizes, and album context.
How It Works
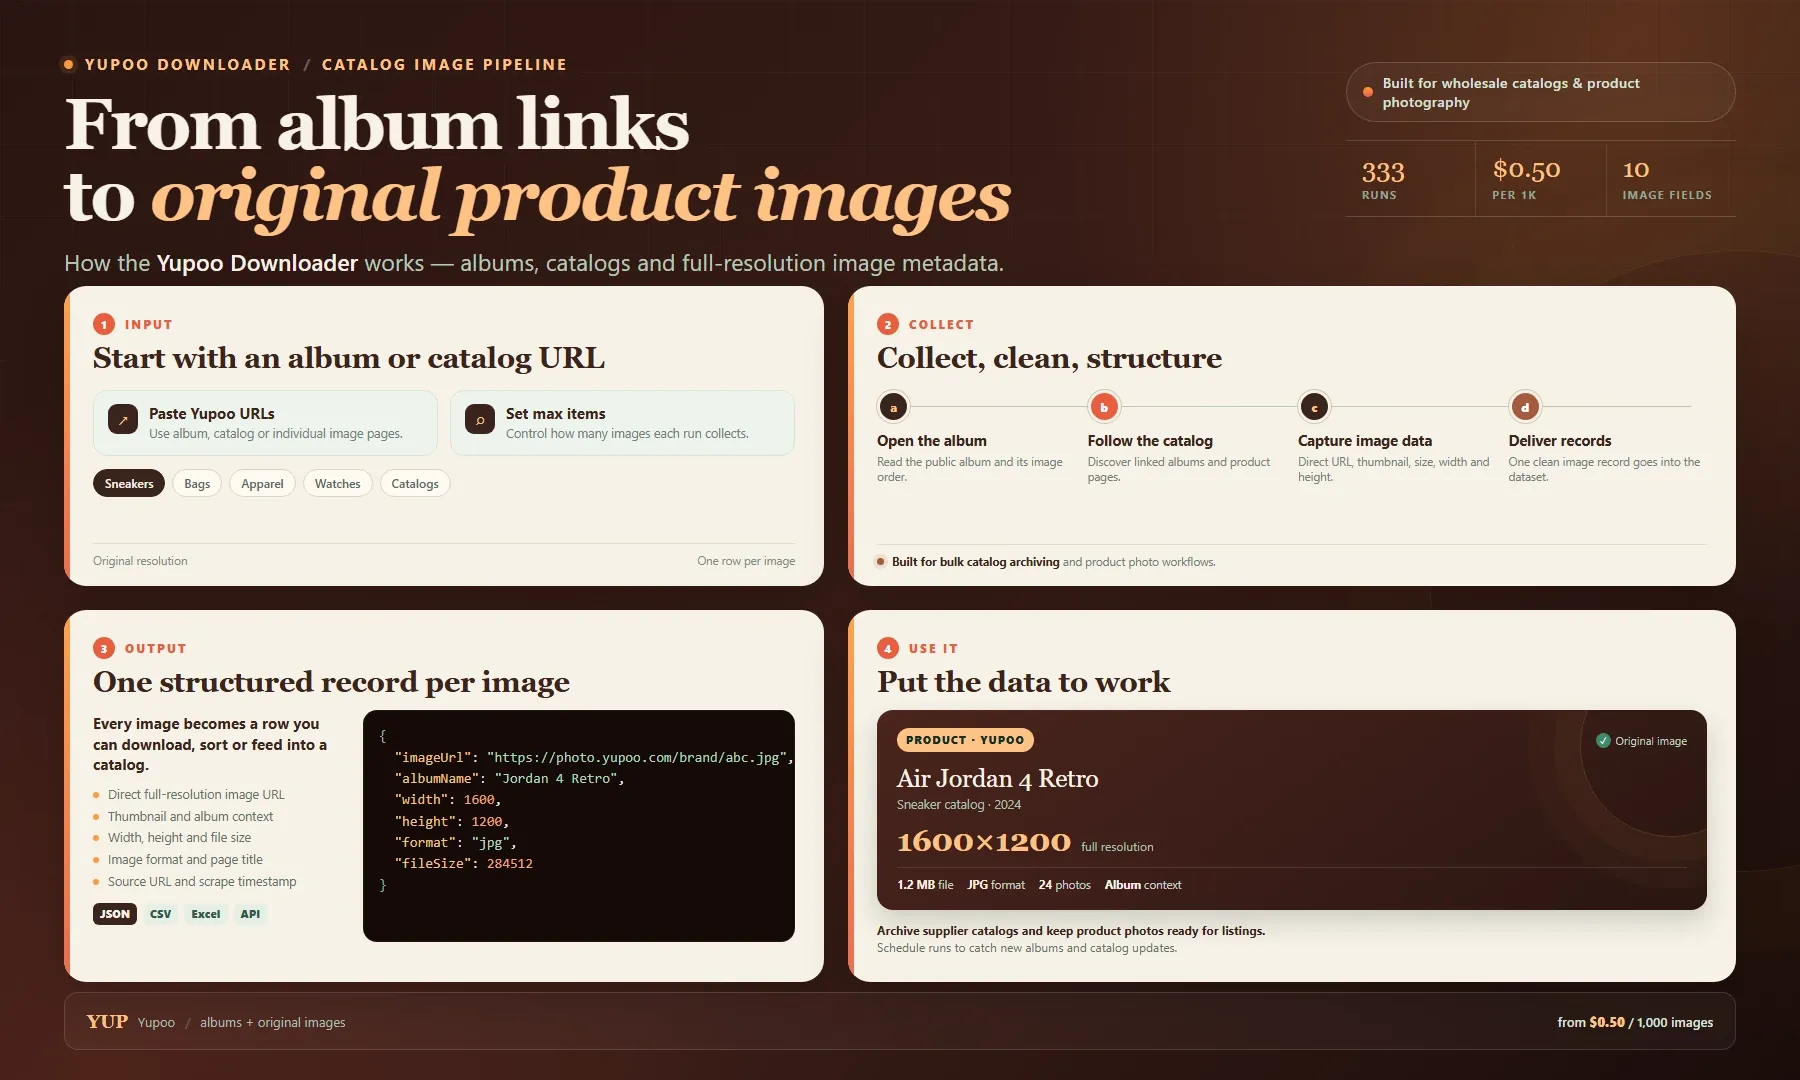
Looking for a Yupoo downloader or a practical Yupoo API alternative? Paste album or catalog URLs and get direct full-resolution image URLs, thumbnails, album context, dimensions, file size and format. Ideal for wholesale buyers, sneaker resellers and e-commerce catalog teams.
Use the dataset to build product feeds, archive supplier catalogs, compare new arrivals or download images for listings. Export as JSON, CSV or Excel, or pull results through the Apify API. Start with a small album, then pay from $0.50 per 1,000 images.
Input
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
startUrls | array | Yes | — | List of Yupoo album or catalog page URLs to scrape |
maxItems | integer | No | 100 | Maximum number of images to extract per run |
proxy | object | No | — | Proxy configuration for request routing |
startUrls Format
Each URL should point to a Yupoo album page, catalog listing, or individual image page. The actor discovers linked albums and images from the provided starting points.
Output
The actor stores results in a dataset with an images_overview view. Each item contains:
| Field | Description |
|---|---|
imageUrl | Direct URL to the full-resolution image |
thumbnailUrl | Smaller thumbnail variant if available |
albumName | Name of the source album |
albumUrl | URL of the album page |
pageTitle | Title or caption of the image |
fileSize | Approximate file size in bytes |
width | Image width in pixels |
height | Image height in pixels |
format | Image format (jpg, png, webp) |
scrapedAt | Timestamp of extraction |
Dataset Views
- images_overview: Grid layout optimized for browsing extracted images with thumbnails and key metadata.
Pricing
| Action | Cost |
|---|---|
| Per image scraped | $0.0005 |
| Per catalog record | $0.005 |
Example Use Cases
- Sneaker resellers: Bulk-download product photos from Yupoo sneaker catalogs
- Wholesale buyers: Extract catalog images from supplier galleries for comparison
- Brand monitoring: Archive product photography across multiple Yupoo storefronts
- E-commerce sellers: Collect high-res product images for listings
- Inventory tracking: Monitor new arrivals and catalog updates
Tips
- Use specific album URLs for faster, targeted extraction
- Combine multiple URLs in
startUrlsfor batch processing across catalogs - Increase
maxItemsfor comprehensive catalog scans - Use Apify Proxy for large-scale extraction runs
- Large catalogs may take longer; start with a specific album for a quick test
Categories
- Automation
- Developer Tools
- Other
Keywords
Yupoo scraper, Yupoo image downloader, Yupoo album scraper, bulk image download, Yupoo gallery scraper, photo album downloader, Yupoo catalog extraction, image batch download, Yupoo API alternative, product photo scraper, catalog image extractor, wholesale catalog scraper, Yupoo bulk export, image archive downloader, product photography data
SEO Keywords
yupoo scraper, yupoo data, yupoo API alternative, yupoo extraction, yupoo automation, yupoo data scraping, web scraping yupoo, yupoo lead generation, yupoo data mining, yupoo crawler, scrape yupoo, yupoo dataset, yupoo web data, yupoo data extractor, yupoo scraping tool, automated yupoo, yupoo data collection, yupoo intelligence
For AI Agents & LLM Apps
This Actor is callable via the Apify MCP server and Apify API.
Purpose: Yupoo Downloader [0.5/ea] | Bulk Images | Albums | Catalog
Minimal working input:
Output fields: url, title, description, metadata (varies by Actor)
Behaviors:
- Returns structured data in JSON format
- Returns structured image records ready for export or API use
- Output saved to Apify dataset
Billing: Pay-per-result pricing applies.
Legal & Compliance Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Yupoo Downloader.
This Actor only accesses publicly available pages and does not bypass authentication or access private content.
Users are solely responsible for ensuring their use of this Actor complies with Yupoo Downloader's Terms of Service and all applicable data-protection laws and regulations.
The developer assumes no liability for misuse of this tool or for any consequences resulting from data extraction activities.
FAQ
Why use this Actor instead of building my own scraper?
This Actor handles extraction, parsing and dataset delivery so you can focus on the catalog rather than maintaining your own pipeline.
What data format does this Actor return?
The Actor returns structured JSON data. Results are stored in an Apify dataset which can be exported as JSON, CSV, XML, or Excel.
Can I use this Actor with scheduling?
Yes. You can create a task from this Actor and schedule it to run automatically at regular intervals for monitoring or data collection purposes.
Is there a way to filter or limit results?
Yes. Check the input parameters for options like maxItems, maxPages, or similar limiting fields to control how much data is extracted per run.
What happens if the Actor encounters a blocked page?
If a page cannot be accessed, the Actor skips it and continues with the remaining items. The dataset contains everything that returned data.
Related Actors
Verified related actors on Apify that pair well with this one. All links point to real, publicly available actors.