
Yelp Business Scraper — Phones, Emails & Website Leads
Pricing
from $1.00 / 1,000 business-scrapeds
Yelp Business Scraper — Phones, Emails & Website Leads
Collect source-returned Yelp business fields from direct URLs, with optional public website enrichment. Bulk export: JSON, CSV, Excel and API. PPE: from $1/1K business results; start fee, usage extra.
Pricing
from $1.00 / 1,000 business-scrapeds
Rating
0.0
(0)
Developer
Apivault Labs
Maintained by CommunityActor stats
0
Bookmarked
45
Total users
2
Monthly active users
16 days ago
Last modified
Categories
Security
Limited permissionsShare
Yelp Business Scraper — Source Fields, Website Signals & MCP
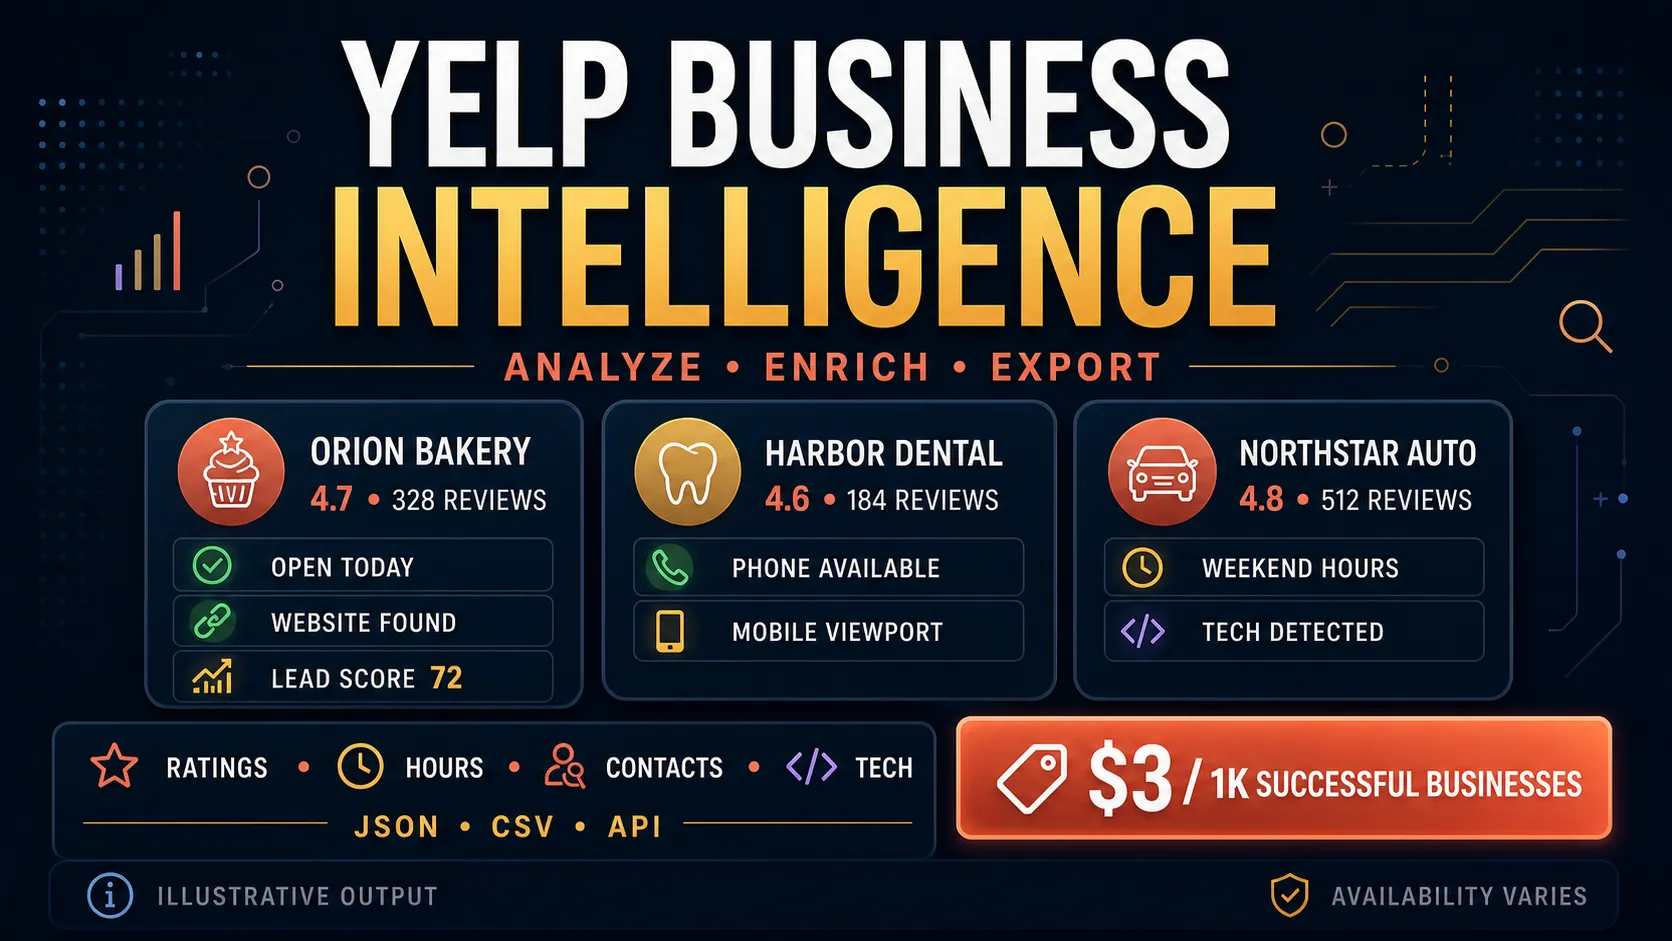
Submit direct Yelp business URLs for business research and CRM preparation. Collect available name, ratings, review counts, categories, price range, address, phone and hours; optionally inspect a listing-returned business website for public contact, technology and SEO signals. Fields depend on the source response and can be unavailable.
Free:$1.50 per1,000 useful business rows; Bronze–Diamond:$1 per1,000, plus startup and separate platform/proxy resources. Startup is$0.00005 perGB of run memory, minimum1 event; at256MB it is$0.00005. See the Pricing tab for the current tier. A row may contain only the basic fields the source returned; this is not a guaranteed full-contact lead.
First run: one business, basic fields
Read the Dataset and SUMMARY together. Check businessName, rating_normalized, reviewsCount_int, sourceMode, coreVerification and collectedAt. Do not equate a successful run with complete fields or independently confirmed company identity.
Only direct /biz/... URLs on supported Yelp domains are accepted. They are canonicalized and deduplicated before source access. The runtime default is10 unique inputs, with a maximum10000. Empty input succeeds with zero result events; invalid-only input or a run with no substantive business extraction fails with free diagnostics. A small run-start charge still applies.
Sources and limitations
The production path currently uses structured extraction of the requested business page. sourceMode:structured_extraction distinguishes it from an optional configured structured API source (structured_source). coreVerification:source_returned_fields_not_independent_identity_check means the fields were returned for the submitted URL; their identity was not separately established from original Yelp HTML.
At the October2026 checks, direct Yelp HTTP and a residential-proxy probe returned403/challenge pages. The working extraction path does not require a customer-supplied external key, but depends on an external source's availability and field coverage. No guarantee of native HTML access, all pages, every country or exact freshness is made. Source-returned values can require manual verification. Names, cities or guessed websites derived solely from the URL slug do not become paid Yelp records.
Keyword/location search is not configured in production and is not offered in the form. Legacy searchTerms calls receive SOURCE_ERRORS; a search-only request fails with zero business result events. Search results are not substituted with URL guesses. This Actor does not promise whole-city discovery, full reviews, review-history monitoring or an indexed Yelp database.
Input and field coverage
| Option | Default | Behavior |
|---|---|---|
businessUrls | sample URL in form | At most10000 direct business URLs. |
maxResults | 10 | Cap unique inputs analyzed and rows delivered; remaining URLs go to continuation. |
maxConcurrency | 2 | Bounded business batches,1–5. Event budget can reduce the batch size. |
timeout | 90 | Total processing budget per business,10–300seconds. Run deadline reserves report time. |
maxRetries | 1 | 0–5 retries within the total source deadline. More retries can increase time and resource cost. |
extractWebsite | true | Analyze an available listing-returned website. |
extractContactEnrichment | true | Public email/phone/social/SEO/schema signals from a fetched website. |
extractHoursIntel | true | Normalize available schedule text. Missing schedules stay unknown. |
extractAmenities | true | Pattern-based amenity observations; verify ambiguous or negated source text. |
extractLeadScore | true | Optional prospecting heuristic and reasons. |
extractOutreachPitch | true | Draft text only; no message is sent. |
guessEmailPatterns | false | Explicitly separated speculative addresses; never verified email contacts. |
websiteDiscoveryFallback | false | Opt-in search candidate, labeled unverified association. |
extractAge | false | Available Wayback snapshot observation, not business founding date. |
extractDomainAge | false | Optional public certificate-history signal, not confirmed domain registration age. |
extractGeocoding | false | Approximate address coordinates when enough source data is available. |
excludeChains | false | Filter records scoring at least50 on the chain heuristic; skipped rows are not billed. |
exportFormat | default | Full JSON or flattened CSV-friendly records. |
writeSummary | true | Controls optional TOP_LEADS; operational counts/diagnostics are always saved. |
Business fields include available businessName, rating, rating_normalized, reviewsCount, reviewsCount_int, categories, priceRange, address, phone, website, hours and image. Rating is0–5; invalid/non-finite normalized values are null. Missing website/address/contacts remain unknown, not proof that the business lacks them.
Website findings include available websiteCheckStatus, websiteFinalUrl, websiteBodyTruncated, website_tech_stack, emails_from_website, phones_from_website, social_profiles and SEO/schema fields. A403, challenge or non-HTML response does not establish a healthy website or paid technology finding. Technology matches are passive pattern observations, not executed scripts or independent backend proof. websiteAssociation distinguishes a listing-returned link, an unverified search candidate and unavailable association.
Exact is_open_now stays null without a verified timezone and exception-hours context. A state-derived zone is exposed only as timezoneEstimate. Weekly hours can exclude holiday changes or overlapping intervals; verify the original schedule before operational use. waybackClosestSnapshotDate and waybackSnapshotAgeYears describe a returned snapshot closest to the requested historical date, not the earliest listing or the age of the business.
Popularity, presence, chain and lead scores are heuristics derived from available fields. leadScoreMethod:heuristic, reasons and audit-method fields expose this limitation. A chain filter can misclassify a business. Review and personalize any generated outreach draft. Guessed emails are kept separately from extracted addresses and are not selected as verified email contacts.
Results, billing and continuation
Only successful source-returned rows with a business name and substantive rating/review evidence, phone or address enter the paid Dataset. There is one apify-default-dataset-item event per useful row; the event title is business-scraped. Do not manually charge the synthetic event again. Duplicate URLs, invalid inputs, failed extraction, URL-only guesses, skipped chains, summaries and diagnostics incur no result event.
Free key-value records:
SUMMARY: requested/validated/delivered/duplicate/failed/pending/skipped counts,status,coverageComplete, limits andnextInput.FAILED_BUSINESSES: rejected or insufficient-source inputs with safe reason codes.SOURCE_ERRORS: unsupported legacy search diagnostics.SKIPPED_BUSINESSES: heuristic filter exclusions.RETRY_INPUT: source-failure candidates. Run only ifbusinessUrlsis non-empty, after reviewing access and limits; not every source failure is temporary.TOP_LEADS: optional useful rows sorted by the heuristic score, maximum20; not a guarantee of contactability or commercial intent.
status distinguishes complete, partial, empty and source_unavailable. A budget/time/result cap leaves unprocessed URLs in SUMMARY.nextInput. Use that input for a subsequent run after adjusting the limit. If a failed extraction also needs another attempt, review RETRY_INPUT. Budget limits are checked before source work; separate platform/proxy usage can still apply.
REST API, MCP and agent contract
Use this Actor when you already have Yelp business URLs. Do not ask it for unconfigured keyword discovery, all city businesses, complete reviews, ownership verification or verified private contact details.
Start with POST https://api.apify.com/v2/acts/apivault_labs~yelp-business-scraper/runs, authenticate using Authorization: Bearer <APIFY_TOKEN>, and send the JSON input above. Poll GET /v2/actor-runs/{runId} to a terminal status. Read GET /v2/datasets/{defaultDatasetId}/items and key-value records at /v2/key-value-stores/{defaultKeyValueStoreId}/records/{recordKey}. Read diagnostics even if the run failed. Dataset items support ?format=csv&clean=true and ?format=xlsx&clean=true; credentials belong in your client configuration.
Connect an authenticated MCP client to:
https://mcp.apify.com/?tools=apivault_labs/yelp-business-scraper
Discover tools/list, then call apivault_labs--yelp-business-scraper with the same inputs. A short waitSecs may return before completion; poll the returned run instead of creating duplicates. Use discovered get-dataset-items and get-key-value-store-record to read the Dataset, SUMMARY and FAILED_BUSINESSES.
Agents should begin with an explicit small cap, set extractWebsite:false when only listing metrics are needed, and keep email guessing/search-candidate discovery off unless explicitly wanted. Report missing fields as unknown, read provenance and website status, and include partial scope/continuation in the answer. Do not describe source-returned extraction as independently verified native Yelp HTML. Only the useful Dataset rows incur result events; a source failure or an empty Dataset is not evidence that the requested business does not exist.
Yelp business research and CRM preparation workflows
This Yelp business scraper enriches known listing URLs with available business metrics and optional website signals. It helps agencies prepare account reviews and teams organize a local-business research file. It does not provide city-wide keyword discovery, a complete review corpus or independently verified ownership.
| Goal | Starting point | Keep with the result |
|---|---|---|
| Basic listing research | Website analysis off | Source mode and coreVerification |
| CRM-ready export | CSV format, small cap | Canonical business URL and collection time |
| Website review | Optional website checks | Association, final URL and fetch status |
| Public contact context | Contact enrichment | Extracted versus guessed addresses |
| Repeatable bounded batches | SUMMARY.nextInput | Scope, pending count and exclusions |
Keep the first request limited to listing fields
This reduces optional work while you verify business identity and substantive field coverage. A returned business name alone is not independent ownership verification; inspect provenance and the original source for important decisions.
Prepare a spreadsheet research row
CSV mode flattens Dataset rows. Download them as CSV/Excel through Apify; it does not guarantee a destination CRM can import all columns without mapping review.
Inspect an available website without guessed email addresses
Use listing-returned association and actual fetch status. A missing contact does not prove the business has none. An unavailable website is not evidence of poor technical quality, and pattern observations do not prove executed technologies.
Collect available hours evidence
Weekly hours can omit holiday exceptions. Exact open-now remains unknown without verified timezone and exception context; do not convert an estimate into operational certainty.
Research interpretation and downstream decisions
Ratings and review counts are source-returned observations at collection time. They are not a verified measure of service quality, customer identity or future performance. Lead, popularity and chain scores are heuristics affected by field availability. Review reasons and source evidence before routing an account.
Guessed addresses, when explicitly enabled, remain separate speculative values. They are not deliverability checks or extracted public contacts. Outreach text is a draft: this Actor sends no message. Listing-returned websites and search candidates also carry different association evidence; do not merge them without review. Keep guessing and candidate discovery off when they are unnecessary.
Pricing and bounded batch handoff
At the active paid-plan rate, ten useful business rows have $0.01 in result events; on Free they have $0.015. Add the $0.00005 start event per GB, minimum one, and user-paid platform/proxy usage. Website and enrichment requests can increase resources without creating extra business rows. Use maxResults and the run charge/time controls rather than relying on the row fee as an all-in cost.
Read SUMMARY and FAILED_BUSINESSES before continuing. nextInput contains unprocessed inputs; RETRY_INPUT concerns failed source candidates and should be reviewed for actual access recovery before another request. A successful partial batch is not completion of the entire supplied list. No repeated-run business history or review monitoring is maintained by this Actor.
Yelp business scraper FAQ
Can I search all plumbers in a city? Not through this deployed form. Supply known direct Yelp business URLs; legacy search-only input is unsupported.
Are website emails verified? They are extracted visible text when available, not confirmed mailboxes or permission to send marketing.
Can MCP agents use it? Yes, with the current authenticated tool contract described above. Start with one URL, read actual Dataset/provenance and free diagnostics, and cite incomplete field coverage rather than filling gaps.
n8n and developer integrations
Use this Actor in your automation or application with the existing community integrations below. An Apify account and API token are required; Actor and platform charges follow the current pricing.
- n8n community node: n8n-nodes-apivault-yelp. Install package name
n8n-nodes-apivault-yelpin a self-hosted n8n instance that permits community packages. - Python client and examples: GitHub.
- Python client and examples: GitHub.
- n8n source and usage: GitHub.
- n8n source and usage: GitHub.
These are community packages. Publication on npm does not establish n8n verification or availability in n8n Cloud. Review the linked package README for supported inputs and setup.


