
🔥 Welcome To The Jungle Jobs Scraper
Pricing
from $0.20 / 1,000 job listing with salary & companies
🔥 Welcome To The Jungle Jobs Scraper
ℹ️ Retrieve jobs, articles, & organizations from "Welcome to the Jungle" using this Actor. Precision meets ease in this modern data tool. Perfect for recruiters, jobseekers, & researchers. Your key to the latest job market insights.
Pricing
from $0.20 / 1,000 job listing with salary & companies
Rating
0.0
(0)
Developer
Bebity
Maintained by CommunityActor stats
8
Bookmarked
244
Total users
9
Monthly active users
12 days ago
Last modified
Categories
Share
🔥 Welcome to the Jungle Scraper — jobs, companies & articles
What does the Welcome to the Jungle Scraper do?
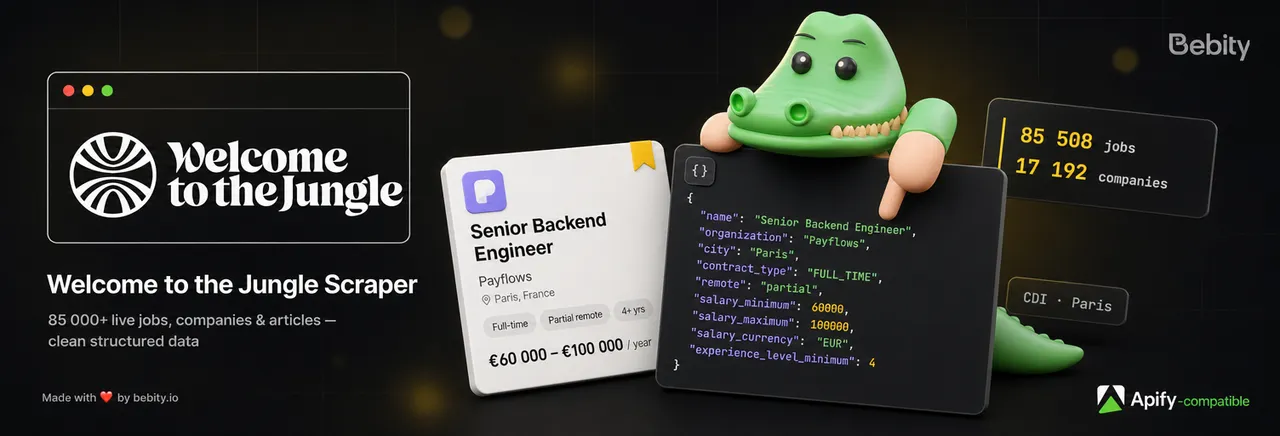
This Welcome to the Jungle scraper turns welcometothejungle.com into structured data. One Actor covers four datasets — job listings, company profiles, articles and promoted jobs — exported as JSON, CSV or Excel. Pick an action, add a filter or paste a page URL, and the Actor returns every field the platform publishes — 199 columns per job, including the direct apply URL and the full job description in HTML, Markdown and plain text.
It is an unofficial Welcome to the Jungle API: no browser, no fragile page scraping, no rate-limit games — and 1 000 fully enriched jobs come back in about 40 seconds.
🇫🇷 Welcome to the Jungle (WTTJ) is the largest employer-branding job board in France, with 85 000+ live listings and 17 000+ company profiles. France dominates with ~80 000 listings, followed by Spain, the UK, the US, Germany, Belgium, Canada, Italy and Morocco — 30 countries in all.
⚡ Still working after the 2026 WTTJ marketplace change
In 2026 Welcome to the Jungle rolled out its new marketplace. The public filtered job search disappeared: /jobs became a matching landing page and the search box now routes into a signed-in funnel. Scrapers that read the search results page lost their entry point.
This Actor never depended on that page, so the redesign did not touch it: it kept returning complete data straight through the rollout. Version 2 is a full rebuild on that foundation.
Four Welcome to the Jungle scrapers in one
One Actor, four datasets, one price list. Pick the 🚀 Action and the same filters, the same export formats and the same API apply to all of them.
| Action | What you get | Columns |
|---|---|---|
| 💼 Jobs | Every public job listing, with the apply URL, full description, salary, contract, seniority and the hiring company's profile attached to each row | 199 |
| 🏢 Organizations | Company profiles on their own: headcount, sector, revenue, founding year, tech stack, every office location, social links, official website and the gender-equality index | 91 |
| 📰 Articles | WTTJ's editorial content — title, summary, authors, categories, cover image, publication date — in French, English, Spanish, Czech and Slovak | 28 |
| ⭐ Promoted jobs | Only the listings WTTJ currently flags as promoted. A deliberately narrow filter — usually just a handful of listings at a time, not a shortcut to the whole board | 199 |
Scraping companies without scraping jobs is what makes this useful for sales teams: 17 000+ French employer profiles, with headcount, sector and offices, is a lead list on its own. And because a company profile is enriched the same way whichever route you use, you can also paste a single company URL and get that one profile back.
Why use this Welcome to the Jungle scraper?
- 🥇 The most complete data on the market. We benchmarked all 43 Welcome to the Jungle Actors on Apify Store in September 2026 against a canonical list of 61 fields. This Actor returns 60 of them — the highest coverage of any WTTJ scraper, and every single one is named in a dataset view, so nothing is buried in a raw JSON blob.
- 🔗 Direct apply URLs.
apply_urlis the field recruiters and job aggregators actually need, and it comes with full job details. Only 18 of the 43 Actors expose it; here it is on every listing whose employer provides one. - 💸 Pay per result, platform usage included. From $0.50 per 1 000 jobs with full details ($0.80 on Apify's free plan), against a market median of $2.00 per 1 000 results. No subscription — see pricing.
- 🤖 Built for AI agents and pipelines. Typed output schema, stable field names, no HTML to clean, one API call.
- ✅ 100 % success rate over the last 30 days of public runs, across 5 000+ runs since launch.
- 🚫 No proxies to configure and no extra proxy bill. Proxying is built in and paid for by us.
What data can you extract from Welcome to the Jungle?
| Data | Fields you get |
|---|---|
| 💼 Job listing | Title, public URL, direct apply URL, description, candidate profile, recruitment process, required skills, key missions, benefits, start date, publication date |
| 💰 Compensation | Salary minimum, maximum, currency, period, yearly minimum, contract duration |
| 📋 Contract & seniority | Contract type (CDI, CDD, internship, apprenticeship, freelance…), remote policy, years of experience, education level |
| 🏢 Company | Name, logo, profile URL, headcount, sector, industry, description, headquarters, all office locations, tech stack, social links, official website |
| 🎯 Diversity | Gender-equality index, pay gap, promotion gap, parity, average age |
| 📍 Location | Address, city, district, region, country, postcode, GPS coordinates |
| 🗂️ Classification | Profession, sub-category, sector, all localized in 5 languages |
| 📰 Articles | Title, summary, authors, categories, image, publication date |
Every HTML field also ships as _markdown and _text, so you never have to strip tags yourself.
How to scrape Welcome to the Jungle jobs
- Click Try for free — Apify's free plan needs no credit card.
- Choose an Action —
Jobs,Organizations,ArticlesorPromoted jobs(see the four actions). - Add a Query (
data engineer), or filter by sector, profession, contract type, salary, remote policy, city or GPS radius. 119 sectors and 109 professions are available as dropdowns. - Set Max items and click Start.
- Download the dataset as JSON, CSV, Excel, XML or HTML, or pull it from the API.
Scraping a specific job or company
Paste any welcometothejungle.com page URL into 🔗 Page URLs and you get that exact page back as a row:
https://www.welcometothejungle.com/en/companies/{company}/jobs/{job}→ that jobhttps://www.welcometothejungle.com/en/companies/{company}→ that company's full profile
To collect all jobs from selected companies, leave Page URLs empty and list the companies in the 🏢 Companies filter instead — it accepts slugs or full company URLs, as many as you like.
How much does it cost to scrape Welcome to the Jungle?
You pay per result, and Apify platform usage is included — no subscription, no compute bill on top. Prices go down on paid Apify plans:
| Price per 1 000 | Free plan | Starter | Scale | Business and above |
|---|---|---|---|---|
| 💼 Job listing — every job row | $0.30 | $0.20 | $0.20 | $0.20 |
| 🔎 Full job details & apply link — add-on, per job | $0.50 | $0.40 | $0.40 | $0.30 |
| 🏢 Enriched company profile — every company row | $0.40 | $0.30 | $0.30 | $0.20 |
| 📰 Article — every article row | $0.40 | $0.30 | $0.30 | $0.20 |
Each run also carries one Actor start event at $0.00005 — five cents per thousand runs.
How the full-details add-on works
- Every job row is billed once as a Job listing, whether it comes from a search, the Promoted jobs action or a pasted job URL.
- 🔎 Fetch full job details is on by default. Each job that comes back with its full page — description, candidate profile, skills, benefits, recruitment process, apply URL and extended company profile — is also billed the add-on.
- No details, no add-on. A listing whose full page can't be retrieved (typically a job closed moments ago) is billed as a listing only, and says so in
detailsError. - Turn the option off to pay for listings only — title, company, location, contract, salary bands, seniority and URLs, about twice as fast.
- Companies and articles have no add-on: one price per row.
What typical runs cost
| Run | Free plan | Starter / Scale | Business and above |
|---|---|---|---|
| 100 jobs with full details | $0.08 | $0.06 | $0.05 |
| 1 000 jobs with full details | $0.80 | $0.60 | $0.50 |
| 1 000 job listings, details off | $0.30 | $0.20 | $0.20 |
| 1 000 company profiles | $0.40 | $0.30 | $0.20 |
| The whole board — ~85 000 jobs with full details | $68 | $51 | $42.50 |
For comparison, WTTJ scrapers on Apify Store charge a median of $2.00 per 1 000 results, and most of them do not return the apply URL at all.
Keep control of what a run costs
- Max items caps the rows — and therefore the bill.
- Maximum cost per run, in the run options, is always honoured: the Actor checks the budget left before each batch, delivers only what it covers, and ends the run as Succeeded with a status message saying how many items it delivered. You are never billed past your limit.
Input
Only 🚀 Action is required, and it defaults to Jobs — so an empty input already returns the latest listings. Everything else narrows or enriches the run. Click the Input tab for the full list.
The four inputs that change what a run does
🚀 Action — which of the four datasets you want: Jobs, Organizations, Articles or Promoted jobs. Everything below applies to jobs unless noted.
🔗 Page URLs — paste welcometothejungle.com page URLs to get those exact pages back, one row each, with no search at all. A job URL returns that job; a company URL returns that company's full profile. Use it when you already know what you want. It is not a way to filter a search — that is what the next one is for.
🏢 Companies — restrict a search to one or more employers, by slug (doctolib) or by pasting the full company URL. This is how you get all of a company's jobs, and it takes as many companies as you like. The difference matters: Page URLs with a company URL gives you 1 company row; Companies with the same company gives you its N job rows.
🔎 Fetch full job details — on by default. It is the single biggest lever on what you get and what a run costs:
| On (default) | Off | |
|---|---|---|
| Speed | 1 000 jobs in ~40 s | about 2× faster |
| Price per 1 000 jobs | $0.50–$0.80 — listing + details add-on | $0.20–$0.30 — listing only |
| You get | Everything — apply_url, description, candidate profile, recruitment process, skills, benefits, extended company profile | Title, company, location, contract, salary bands, seniority, URLs |
| Best for | Anything you will act on: applying, enriching a CRM, feeding an LLM | Counting, monitoring, or a first pass before enriching |
The filters
All optional, all combinable — they stack with AND, so each one you add narrows the result.
| Filters | |
|---|---|
| 🔎 Text | Query (free text) · Match the query in the job title only |
| 📍 Where | Country code (ISO, 30 countries) · City · Latitude / Longitude + Radius (km) for a geo search around any point |
| 💼 The role | Profession (109 values — Dev Fullstack, Dev Backend, DevOps / Infra, Data, UX/UI, and every non-tech job family too) · Contract type (10: full-time, internship, apprenticeship, freelance, VIE…) · Remote policy (5: fulltime, partial, punctual, none, unknown) |
| 💰 Pay & seniority | Minimum yearly salary · Only listings that disclose a salary · Required experience (5 bands, plus unknown) · Minimum education level (10, from no diploma to PhD) |
| 🏢 The employer | Company sector (119 values) · Company size (5 bands) · Companies · Partner job board (WTTJ's white-label boards, e.g. la-french-tech) |
| 📅 When | Published within (days) — walks the date-sorted index and stops at your cutoff, so "last 7 days" costs a fraction of a full export |
| 🔃 Order | Sort by relevance or publication date · Max items |
Input example
Annotated for clarity — strip the // comments before pasting into the Actor's JSON editor.
Output example
You can download the dataset in JSON, CSV, Excel, XML or HTML. Every example below is a real row from a live run — only long text bodies and image URLs are truncated.
Job output
One job with Fetch full job details on, out of 199 columns:
Turn off Fetch full job details and the run is about twice as fast and billed at the listing price only: you keep the title, company, location, contract, salary bands, seniority and URLs, but lose the fields that only come with full details — apply_url, the description, the candidate profile, the recruitment process, skills, benefits and the company's extended profile.
Company output
The Organizations action, out of 91 columns. The same row comes back if you paste a company URL:
Article output
The Articles action, out of 28 columns:
Welcome to the Jungle API for AI agents
The output is designed to be consumed by an LLM or an agent with no cleaning step:
- Stable, typed schema. Every field is declared and validated, so a column never changes type between runs.
- Ready-to-read text.
description_markdownanddescription_textmean you can feed a job straight into a prompt — no HTML, no entity decoding, no token waste on markup. - One call, whole task. Search, filter and full enrichment happen in a single run; there is no crawl to orchestrate.
- Three focused views — one per object type — so an agent can request only the columns it needs.
Run it from any agent framework through the Apify API:
It also works as a tool inside Apify's MCP server, so Claude, ChatGPT or a LangChain agent can call it directly.
Who uses this Welcome to the Jungle data scraper?
- Recruiters & staffing agencies — track which companies are hiring, for which roles, at which salaries.
- Job boards & aggregators — ingest listings with working apply links.
- Sales & lead generation — 17 000+ company profiles with headcount, sector, tech stack and offices. Hiring is the strongest buying signal there is.
- Market researchers & data teams — salary benchmarks, remote-work trends, skills demand over time.
- Job seekers — filter the whole French market by salary, remote policy and seniority in one sheet.
What's new in version 2
Version 2 is a rebuild, not a patch:
- ⚡ Unaffected by the 2026 marketplace redesign that broke page-based scrapers.
- 📊 Every field reachable. Three dataset views — jobs, companies, articles — with 318 columns between them, each verified against the live platform so no column is ever silently empty.
- 🏢 Companies are first-class. A company profile is the same complete record whether you ask for it by URL or through the Organizations action — including the gender-equality index and all office locations.
- 🔗 Page URLs do one thing. Paste a job or company URL, get that page back as a row.
- 🚀 Faster: 1 000 fully enriched jobs in about 40 seconds.
- 💸 Pay per result. No subscription, platform usage included, and your maximum cost per run is respected.
- 🔁 Renamed companies still resolve — 13 % of WTTJ companies are reachable under an old slug, and those are followed automatically.
See the full changelog.
FAQ
Is it legal to scrape Welcome to the Jungle?
This Actor extracts only publicly available data — job listings and company profiles that employers chose to publish. It does not collect private user data, candidate profiles or anything behind a login. Scraping public data is generally legal, but your results may still contain personal data (for example a recruiter's name in a job description). Personal data is protected by the GDPR in the EU and by similar laws elsewhere; only process it if you have a legitimate reason. If you are unsure, consult a lawyer.
How many results can I get in one run?
There is no hard cap. Requests of up to 1 000 items come back ranked by relevance; larger exports have no ceiling but come back in no particular order rather than by relevance. For the best matches first, keep maxItems at 1 000 or below and narrow with filters — the Actor tells you in the log which mode it used.
Can I cap how much a run costs?
Yes, two ways. Max items limits the rows; Maximum cost per run (in the run options) limits the spend. When the budget runs out, the Actor stops fetching, keeps everything already delivered and ends the run as succeeded — you are never billed beyond your limit.
Can I scrape only recent job listings?
Yes. Set 📅 Published within (days) and the Actor walks the date-sorted index and stops as soon as it passes your cutoff, so a "last 7 days" run costs a fraction of a full export.
Do I need proxies?
No. Proxying is built in and paid for by us — there is nothing to configure and no separate proxy bill.
Can I schedule runs or connect this to my stack?
Yes. The Apify platform gives you scheduling, run monitoring and alerts, a full REST API, webhooks, and integrations with Make, Zapier, Google Sheets, Slack, Airbyte and more. Datasets are retained and versioned for you.
Does it work for countries other than France?
Yes. Listings span 30 countries. France is by far the largest (~80 000 listings), then Spain (~1 250), the UK, the US, Germany, Belgium, Canada, Italy and Morocco. Filter with 🌍 Country code using an ISO code such as ES, GB or DE, or search by city and GPS radius. Listings come in 14 languages, mostly French and English.
Something is broken or missing
Open the Issues tab on the Actor page. Bugs are fixed and new fields added on request — feature requests are welcome, and so are custom builds.
Other scrapers by Bebity
Looking for data from other job boards or platforms? Browse all Bebity Actors on Apify Store.
Made with ❤️ by Bebity.io


