

Podcast Episodes Scraper: audio links, dates, durations
Pricing
$0.50 / 1,000 episodes
Podcast Episodes Scraper: audio links, dates, durations
Monitor competitors, build research corpora or give AI agents structured metadata. Missing values stay null, owner emails are never read, no login or proxy needed.
Pricing
$0.50 / 1,000 episodes
Rating
0.0
(0)
Developer

BEPO Labs
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Security
Limited permissionsShare
🎙️ What is Podcast Episodes?
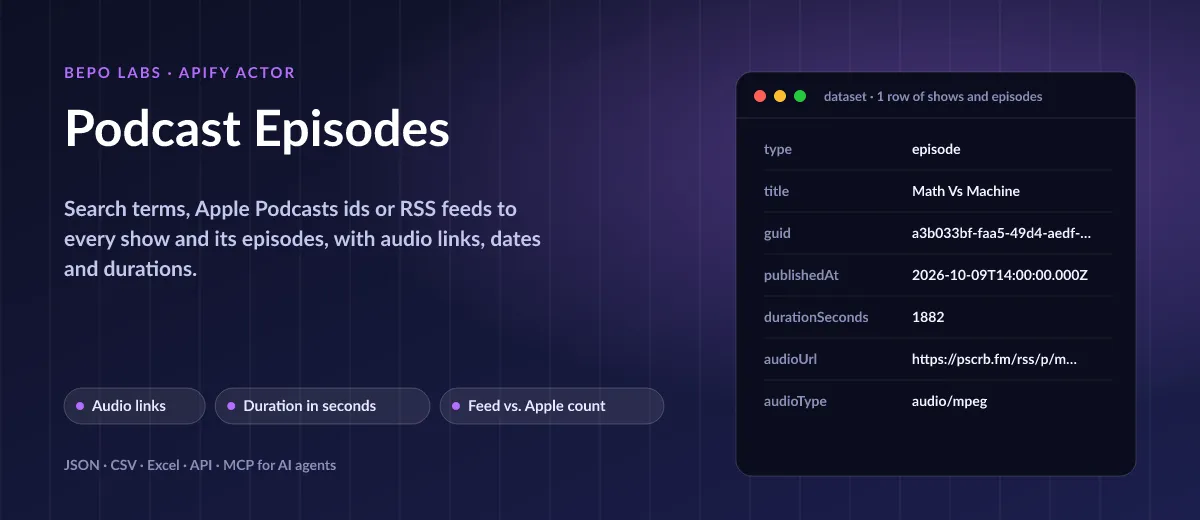
Get a whole back catalogue in one table: this Actor takes keywords, directory ids or XML addresses and returns the programme record plus its newest podcast episodes, with ISO release stamps, runtime in seconds, the direct enclosure URL with byte size, episode and season counters and the notes as plain text. A gap counter shows when a feed only keeps recent items.
- Transcription and AI pipelines: get the direct MP3 link of every new episode and send it to Whisper, a speech-to-text Actor or your RAG index
- Podcast research and media monitoring: track what shows in your niche publish, how often and how long their episodes are
- Guest and sponsor prospecting: collect episode titles and show notes to see who appears where
- Podcast directories and apps: fill your catalog with shows, artwork, categories and episode lists in one format
- Archives and analytics: build a dated list of every episode a show still has in its feed, with durations for statistics
✨ Why use this Actor?
- ✅ Three ways in: search terms, Apple Podcasts ids or show links, or plain RSS feed URLs, mixed in one run
- ✅ Typed, ready-to-use fields: dates in ISO, durations in seconds (also from "1:02:03" style values), audio size in bytes
- ✅ Feed gap made visible: feedEpisodeCount, appleEpisodeCount and feedGap on every show row explain short episode lists
- ✅ Nothing guessed: a field the feed does not carry is null, never filled in
- ✅ Privacy first: the show owner's contact email in the feed is never read into the output
- ✅ No login, no proxy: Apple's public search API plus the show's own RSS feed; one failing input never stops the run
📦 What data can you get with Podcast Episodes?
| 🎙️ Show title and author | 🍎 Apple Podcasts id and URL | 📡 RSS feed URL and website |
| 🏷️ Categories and language | 🖼️ Show artwork and episode image | 🔢 Feed vs. Apple episode count |
| 🎧 Episode title and GUID | 📅 Publish date (ISO) | ⏱️ Duration in seconds |
| 🔗 Direct audio URL, type and size | #️⃣ Episode and season number | 📝 Show notes as plain text |
Each record has
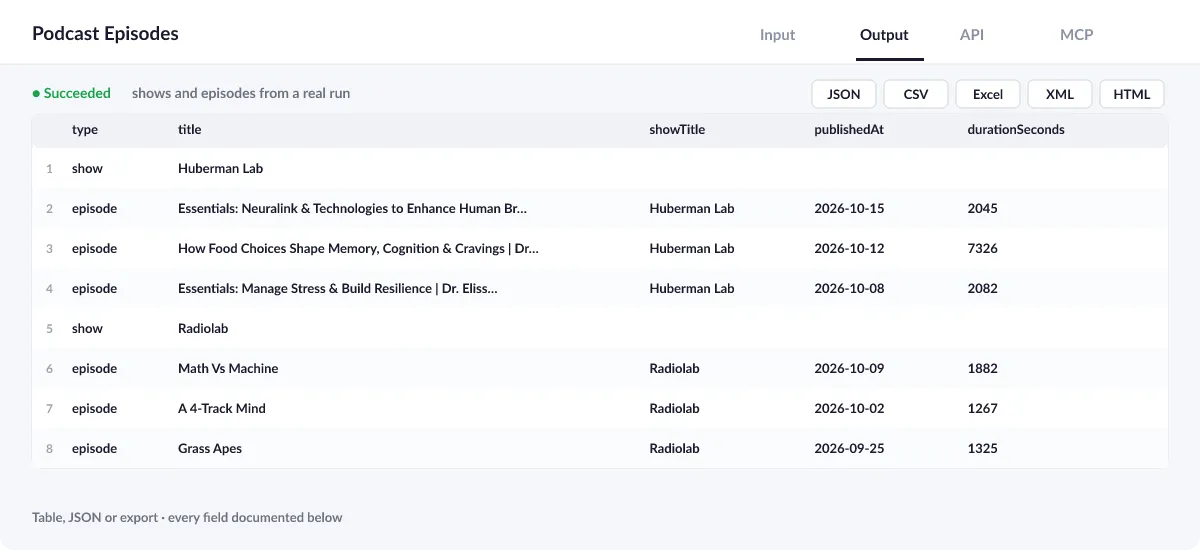
type(showorepisode); a show is followed by its episodes, newest first.
🚀 How to use Podcast Episodes
Podcast Episodes works in a few clicks, no coding needed:
- Create a free Apify account (the free plan includes 5 USD of monthly credit).
- Open Podcast Episodes and click Try for free.
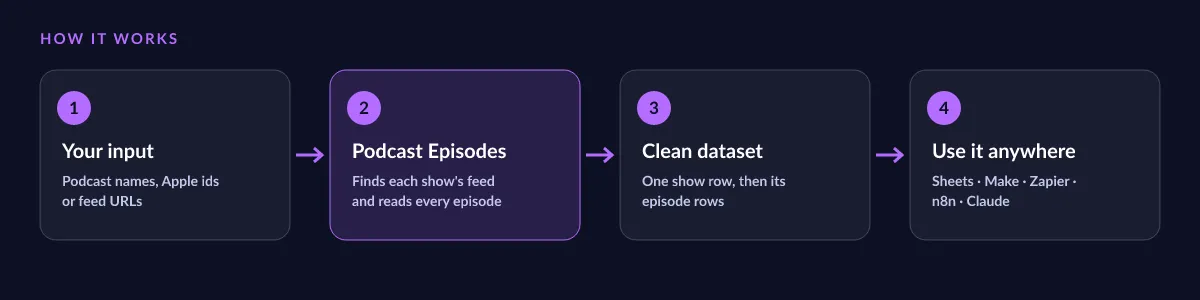
- Type podcast names in Search terms, or paste Apple Podcasts ids or RSS feed URLs, and set how many episodes per show you want.
- Click Start and wait for the run to finish (most runs take seconds).
- Download your data as JSON, CSV, Excel, XML or HTML, or send it straight to Google Sheets, Make, Zapier or your AI agent.
⬇️ Input
Give any mix of search terms, Apple Podcasts ids or links and RSS feed URLs. Everything else is optional.
Term, id or address?
A search term finds programmes in Apple Podcasts (maxShowsPerTerm top hits each, default 5). A numeric id (1200361736) or store link picks one programme exactly. A feed address is read directly, skipping the directory.
Only new episodes
Set since to a date such as 2026-10-01 to keep only episodes published on or after it, and maxEpisodesPerShow to cap each programme (newest first). 0 returns the show records alone.
Speed
The directory allows about 20 searches a minute, so each search term adds about 3 seconds. Ids are looked up 100 at a time, and feed URLs need no call to Apple at all.
| Field | Type | What it does | Default |
|---|---|---|---|
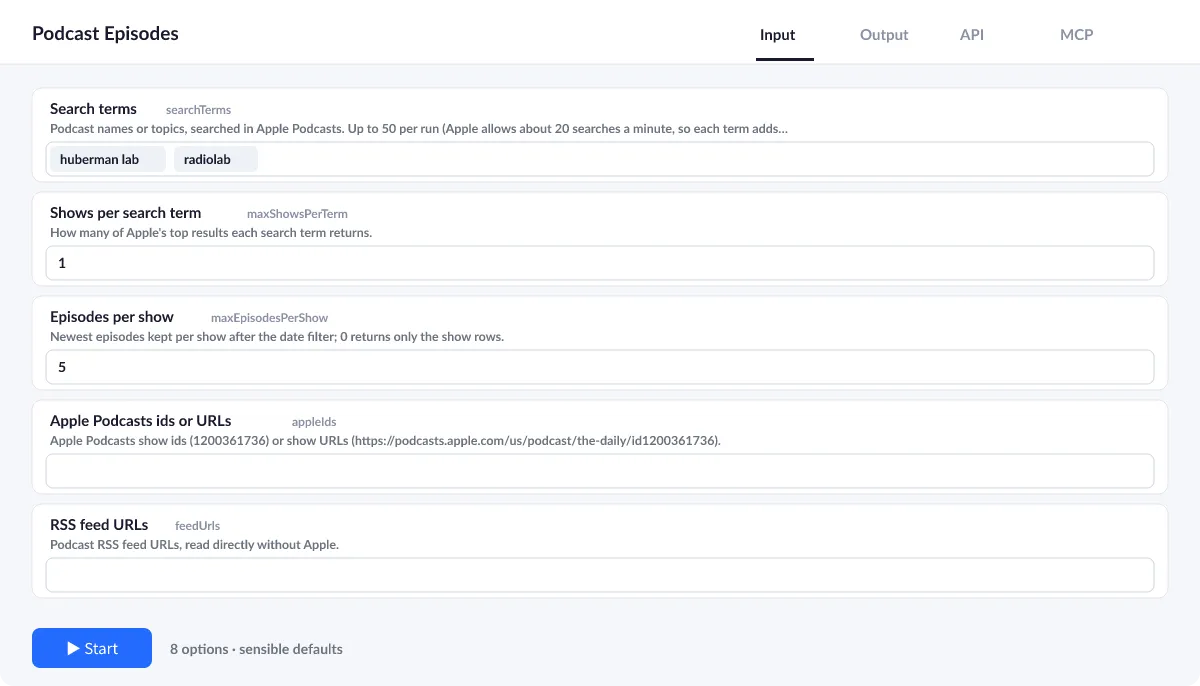
Search terms (searchTerms) | array | Podcast names or topics, searched in Apple Podcasts. | ["huberman lab"] |
Apple Podcasts ids or URLs (appleIds) | array | Apple Podcasts show ids (1200361736) or show URLs (https://podcasts.apple.com/us/podcast/the-daily/id1200361736). | |
RSS feed URLs (feedUrls) | array | Podcast RSS feed URLs, read directly without Apple. | |
Shows per search term (maxShowsPerTerm) | integer | How many of Apple's top results each search term returns. | 5 |
Episodes per show (maxEpisodesPerShow) | integer | Newest episodes kept per show after the date filter; 0 returns only the show rows. | 100 |
Published since (since) | string | Keep episodes published on or after this date, e.g. | |
Apple store country (country) | string | Two-letter Apple Podcasts store code used for search and ids, e.g. | "US" |
Maximum retries (maxRetries) | integer | Retries per request with exponential backoff on network errors, 429 and 5xx. | 3 |
Input example
⬆️ Output
Two record types share one dataset: a show, then that show's episode records, newest first. The run summary in the key-value store (OUTPUT) lists every input with its feed, the episodes found and kept, and the error if an input failed.
Output example
One episode row (Radiolab, long values shortened):
Show row example
The show row before its episodes (Radiolab: the public feed holds 674 of the 870 episodes Apple lists, so feedGap is 196):
Why are there fewer episodes than on Apple?
Episodes come from each programme's own open RSS feed, the one every podcast app reads. Many keep only recent items there: in our test run The Daily's archive held 65 of the 2,750 episodes Apple lists, Hard Fork's 3 of 219. feedEpisodeCount, appleEpisodeCount and feedGap reveal this on every show record, so a short list is explained, not a bug.
View the results as a table or JSON in the Output tab and download them as JSON, CSV, Excel, XML, HTML or RSS, all fields or only those you pick.
💰 How much does Podcast Episodes cost?
Podcast Episodes is priced per event: 0.5 USD per 1,000 episodes (0.0005 USD each), with no monthly rental. Each show adds 0.002 USD (2 USD per 1,000 programmes), so 100 shows with 50 episodes each cost 2.70 USD in total. Failed inputs are free.
| You get | You pay |
|---|---|
| 100 episodes | 0.05 USD |
| 1,000 episodes | 0.5 USD |
| 10,000 episodes | 5 USD |
| 100,000 episodes | 50 USD |
💡 Apify's free plan gives you 5 USD of credit every month, enough for about 10,000 episodes at no cost. Set a spending limit per run and the Actor stops there.
⚖️ Podcast Episodes vs. the alternatives
| Podcast Episodes | Basic podcast scrapers | Paid podcast APIs | |
|---|---|---|---|
| Search, Apple id and RSS feed input | ✅ all three | often one of them | ✅ |
| Duration in seconds, audio size in bytes | ✅ | often raw strings | ✅ |
| Feed vs. Apple episode count | ✅ on every show | ❌ | ❌ |
| No personal host emails | ✅ never collected | varies | varies |
| Pay per result, no subscription | ✅ 0.5 USD per 1,000 episodes | ✅ | ❌ monthly plans |
🔌 Integrations, API and MCP
Connect Podcast Episodes to your AI agent (MCP)
Give Claude, ChatGPT, Cursor or any MCP client direct access to Podcast Episodes through the Apify MCP server. Add this URL to its settings:
For Claude Desktop, add it under mcpServers in claude_desktop_config.json:
Then ask: "Find the Huberman Lab podcast and list its last 5 episodes with their length in minutes and audio links."
Run it from your code
Python (pip install apify-client):
JavaScript (npm install apify-client):
No-code integrations
Send results to Google Sheets, Slack, Airtable, HubSpot, Make, Zapier, n8n and more from the Integrations tab, start runs on a schedule, or trigger your own endpoint with a webhook when a run finishes. The Apify API gives you full control over runs and datasets.
❓ FAQ
Why fewer episodes than Apple counts?
The public RSS feed holds only what its publisher keeps there. feedGap on the programme record tells you how many extra episodes Apple lists.
Can I download or transcribe the audio?
Yes. audioUrl is the direct media link from the feed (usually MP3), ready for a download or a speech-to-text tool. Respect the show's rights when you reuse the audio.
Do you return host emails?
No. The owner's email in a feed is personal data and is never read into the output.
How do I get only new episodes every day?
Schedule the Actor daily with since set to yesterday's date, or keep maxEpisodesPerShow small and drop GUIDs you already have.
Which countries does search cover?
Any Apple Podcasts store: set country to a two-letter code such as US, GB or DE (default US).
How many podcasts can I read in one run?
Up to 50 search terms plus up to 500 Apple ids and feed URLs per run, with up to 5,000 episodes per show (maxEpisodesPerShow, default 100).
What happens when an input fails?
The other inputs still run, the run summary names the failed input and why, and you are not charged for it. The run fails only if no show could be read.
Is it legal to use Podcast Episodes?
Podcast RSS feeds are published for podcast apps to consume, which is their intended use. Apple's iTunes Search API serves only to find a programme's feed, at its rate of about 20 calls a minute. The Actor collects no personal data: the owner's email is never read into the output. Episodes, notes and audio belong to their creators; you are responsible for how you use and republish them.
What if something is missing or does not work?
Open an issue on the Issues tab; we read each one and reply. Feature requests are welcome too.
💬 Your feedback
Tell us what Podcast Episodes should add on the Issues tab or leave a review; your notes decide what we work on next.
🔗 Related Actors
| Actor | What it does |
|---|---|
| 📰 RSS Feed Reader | Any RSS, Atom or JSON feed, or just a website URL, to one clean list of articles, with full text on request. |
| 🦋 Bluesky Posts | Bluesky posts for any search or handle with text, date, author, likes, reposts, replies, links and hashtags. No login. |
| 📈 Google Trends Scraper | Interest over time for up to five keywords on one 0 to 100 scale, any country or worldwide, plus top and rising related queries. |
| 🟧 Hacker News Search | Hacker News stories, comments, Ask HN, Show HN and jobs for any search, with points, comment count, date and text. |
| 🔤 Image OCR | Extract text from images in 29 languages: plain text, clean Markdown and every word with its pixel box and confidence. |
| 🌍 Remote Jobs | Remote jobs from Remote OK, Himalayas, Jobicy and Arbeitnow in one deduped feed, with salary, posted date and apply link. |
| 📸 Website Screenshot | Full-page PNG, JPEG or PDF of any URL, on desktop, tablet and phone, with cookie banners closed. |
| 📈 Wikipedia Pageviews | Daily or monthly views of any Wikipedia article in any language, with totals and averages, from the official Wikimedia API. |


