
Reddit Search Scraper - Keyword Monitoring | $0.99/1K
Pricing
from $0.99 / 1,000 results
Reddit Search Scraper - Keyword Monitoring | $0.99/1K
Search Reddit posts and comments by keyword and monitor brand mentions on a schedule, for $0.99 per 1,000 results. Boolean operators, exact phrases, subreddit scoping or auto-discovery, 5 sort orders and time filters. Full text, scores, authors, dates, media and parent-post context.
Pricing
from $0.99 / 1,000 results
Rating
1.0
(1)
Developer
ClearPath
Maintained by CommunityActor stats
3
Bookmarked
1.4K
Total users
438
Monthly active users
a day ago
Last modified
Categories
Share
Reddit Search Scraper | Fast Bulk Keyword Search (2026)
2026-10-07: With auto-discovery on, about half of maxResults is reserved for the discovered communities, so they shape the results at any size; the global search fills whatever they leave open, so a run returns as many rows as before. The communities found are saved as the key-value store record DISCOVERED_SUBREDDITS, named in the run's status message and listed in the run log.
2026-10-06: Comment search with sort Hot or Most comments now returns comments, ranked by relevance. Several subreddit names in one entry are split, and a subreddit list with no valid name says so instead of searching all of Reddit. Field names from other Reddit actors (maxItems, limit, time, type, queries, ...) are now read when this actor's own field is absent.
Built by Clearpath, with 150,000+ combined lifetime runs across Reddit Search, Post & Comments and Subreddit Posts. A specialist suite for Reddit research.
Copy to your AI assistant
Copy this block into ChatGPT, Claude, Cursor, or any LLM to start building with this data.
Why choose this actor?
Collect hundreds of results in seconds. Search posts, comments or both, with full text, scores, authors, dates and source links ready to export. Move from a keyword to a dataset you can analyse.
Find the communities you would otherwise miss. The actor discovers relevant subreddits automatically and searches across them. Go beyond the roughly 300 results available from a single global search, or select your own communities.
Keep the context behind each match. Post records include media and subreddit details; comment records include parent-post context. Use exact phrases, exclusions, date filters and sort options to focus your research.
Quick start
Try a small search across both posts and comments, with automatic community discovery.
Open actor input to enter your keyword, choose a time range or select subreddits. Export JSON, CSV or Excel; JSON preserves nested media and discussion context.
In both mode posts and comments each get up to maxResults, so a run can return up to twice that many rows. Available matches depend on the query and filters. This example returns matching comments; use Post & Comments to collect complete discussion threads.
| Clearpath · Reddit Suite |
 Search You are here  Comments Full discussions  Subreddits Community feeds  User Content Posts & comments  Profiles Karma & accounts  Medium Articles & full text  Substack Newsletters & full text |
Key Features
- Smart subreddit auto-discovery — just type a keyword and the actor automatically finds the top 20 most relevant subreddits and searches across all of them, with about half of
maxResultsreserved for them. The communities found are saved as the key-value store recordDISCOVERED_SUBREDDITS. Get targeted results without knowing which subreddits to target - Advanced query syntax: boolean operators, exact phrases, grouping, exclusion, and field operators (
author:,title:,selftext:,self:,flair:,url:). Turn a blunt keyword into a precise brand monitor or lead-gen filter. See Query recipes - Rich 56-field output: every post carries media and video URLs, galleries, polls, full subreddit context (subscriber count, type, icons), and author metadata. Comments add parent-comment linkage and parent-post context
- Posts, comments, or both — a single
contentTypetoggle controls whether you get posts, comments, or both result types in one run. No need to run the actor twice - 5 sort orders — relevance, new, top, hot, and most comments. Choose how results are ranked to match your use case
- Time filtering — restrict results to the past hour, day, week, month, or year. Combine with any sort order to narrow the window
- Subreddit scoping — search all of Reddit at once, target a single subreddit, or search across multiple subreddits in one run
- Bulk subreddit input — paste subreddit names in any format:
python,r/python,https://reddit.com/r/python. Mix formats freely in the same input - Fast — results stream in within seconds. Multiple subreddits run concurrently, so adding more subs doesn't proportionally increase run time
How to Search Reddit
Auto-discover subreddits (easiest)
Just enter a keyword. The actor finds the top 20 relevant subreddits automatically and searches across them.
Searches all of Reddit, then relevant communities such as r/notion, r/obsidianmd and r/productivity. How many results come back depends on how many matches exist: often several hundred for a popular topic, fewer for a niche one.
About half of maxResults is reserved for the discovered communities, so at any size the results come from both Reddit's global ranking and the relevant subreddits. When the communities hold fewer matches than their share, the global search fills the rest. The communities found are saved in the run's key-value store as the record DISCOVERED_SUBREDDITS (name, link, subscriber count, description and icon for each), the run's status message names the record, and the run log lists them.
Basic keyword search
Enter a search query. The actor searches all of Reddit and returns up to 100 posts sorted by relevance.
Search for comments instead of posts
Set contentType to comments to search comment text instead of post titles and bodies.
Get both posts and comments
Set contentType to both to retrieve matching posts and comments in a single run. Results are labeled with _type so you can filter them downstream.
Search within a specific subreddit
Use subreddit to scope results to a single community. Any format works.
Search across multiple subreddits
Use the subreddits array to search several communities in parallel. Mix name formats freely.
Newest results with time filter
Combine sort: "new" with a time filter to find the most recent discussions within a specific window.
Input Parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
query | string | required | Keywords to search for. Supports boolean operators and quoted phrases (max 700 characters) |
maxResults | integer | 100 | Maximum number of results to return. Set to 0 for unlimited |
contentType | enum | posts | What to search: posts, comments, or both |
sort | enum | relevance | Sort order: relevance, new, top, hot, comments |
timeFilter | enum | all time | Time range: hour, day, week, month, year. Applied to the matches after they are fetched. Leave empty for all time |
postedAfter | string | — | Keep only results created at or after this date (midnight UTC) or date-time, e.g. 2026-10-01 or 2026-10-01T12:00:00Z. Older results are skipped and not charged; with sort: "new" the search stops at the first older result |
postedBefore | string | — | Keep only results created before this date or date-time |
subreddit | string | — | Scope search to a single subreddit. Leave empty to search all of Reddit, plus auto-discovered communities when auto-discovery is on |
subreddits | string[] | [] | Search across multiple subreddits. Names separated by commas or spaces in one entry are split. Results are merged and deduplicated. When given, auto-discovery is skipped and the run log says so |
autoDiscoverSubreddits | boolean | true | Auto-find relevant subreddits when none specified. About half of maxResults goes to them, and the list is saved as the key-value store record DISCOVERED_SUBREDDITS |
maxSubreddits | integer | 20 | Max subreddits to auto-discover (1-50) |
Field names from other Reddit actors are read when the matching field above is absent: maxItems, maxPosts, limit, resultsLimit (maxResults); time, timeRange, timeframe (timeFilter); type, searchType (contentType); queries, searches, searchQueries, keyword, search (query, first entry). A field of this actor always wins.
Sort order reference
| Value | Behavior |
|---|---|
relevance | Reddit's default. Balances keyword match quality with engagement signals |
new | Most recent results first, regardless of score |
top | Highest score (upvotes minus downvotes) |
hot | Currently trending content. Balances recency and engagement. Comment search ranks by relevance instead |
comments | Most commented results first. Comment search ranks by relevance instead |
Time filter reference
| Value | Window |
|---|---|
hour | Past 60 minutes |
day | Past 24 hours |
week | Past 7 days |
month | Past 30 days |
year | Past 365 days |
| (empty) | All time (default) |
Subreddit input formats
All of these are equivalent and can be mixed in the same subreddits array:
pythonr/python/r/pythonhttps://reddit.com/r/pythonhttps://www.reddit.com/r/pythonhttps://old.reddit.com/r/python
Search query syntax
The query field supports Reddit's full search syntax: boolean operators, exact phrases, grouping, and field operators that target a specific part of a post. This is what lets you go from a blunt keyword to a precise, repeatable monitor. Maximum query length is 700 characters.
Boolean and phrase operators
| Syntax | Example | Behavior |
|---|---|---|
| Keywords | kubernetes terraform | All terms must appear, ranked by relevance |
| Exact phrase | "web scraping" | Matches the exact phrase only |
| OR | flask OR django | Matches either term |
| AND | python AND scraping | Both terms must appear |
| NOT | jaguar NOT car | Excludes results with the second term |
| Exclude | python -snake | Same as NOT, using a leading - |
| Grouped | ("flask" OR "django") AND "REST API" | Combine operators with parentheses |
A lowercase or or and between two terms is read as OR or AND. A lowercase not stays an ordinary word, so write NOT or a leading - to exclude a term.
Field operators scope a term to one part of the post:
| Operator | Example | Matches |
|---|---|---|
author: | author:spez | Posts by a specific user |
title: | title:"show reddit" | Term appears in the title |
selftext: | selftext:"changed my life" | Term appears in the post body |
self: | self:yes climate change | Text posts only (self:no for link posts only) |
flair: | flair:"Discussion" | Posts with a specific flair (most precise inside one subreddit) |
url: | url:youtube.com | Link posts pointing to a domain |
subreddit: | subreddit:python | Limit to one subreddit (combine with OR for several). Works inline, or use the subreddits field |
Operators stack with grouping and phrases, and they work whether you search all of Reddit or scope to specific subreddits.
Query recipes
Each recipe is a complete, ready-to-run input. Paste it straight into an API call or the Console, then swap in your own terms.
Brand and competitor monitoring. Track your product and every alternative in one run, newest first, to build a live mention feed:
Buying-intent lead generation. Surface people actively asking for a recommendation, and drop the noise with an exclusion:
Title-only topic tracking. Catch posts that are actually about the subject, not ones that mention it in passing:
Account monitoring. Pull everything a specific user posts, newest first:
Deep body-text search. Match a phrase inside the post body, where keyword search alone would miss it:
Discussion mining in one community. Combine a flair filter with the subreddits field to read just the long-form threads from a single subreddit:
What Data Can You Extract?
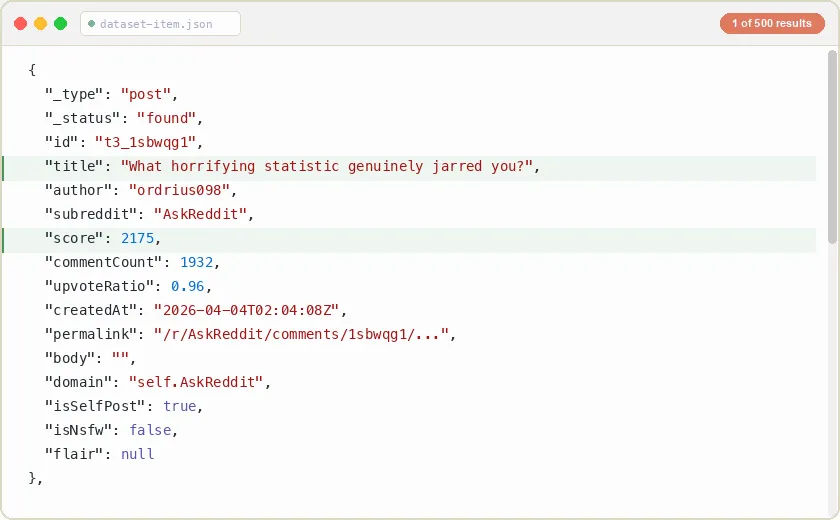
The output contains two row types depending on your contentType setting: post rows and comment rows. Each row includes a _type field so you can distinguish them when using both mode.
Every row is rich by default. Posts carry 56 fields and comments carry 37 fields, including media URLs, full subreddit context (subscriber count, type, icons), author metadata, and parent-post context on comments. Nothing the source exposes is dropped except viewer-specific noise.
Post row (56 fields)
The media, gallery, and poll objects are null on text posts and populate by post type. Their shapes (arrays truncated):
Post fields (56): _type, _status, id, title, author, subreddit, score, commentCount, upvoteRatio, createdAt, editedAt, permalink, threadUrl, url, body, bodyMedia, domain, outboundUrl, postHint, languageCode, isSelfPost, isNsfw, isSpoiler, isLocked, isStickied, isArchived, isContestMode, isCrosspostable, isGildable, isScoreHidden, isPollIncluded, isCommercialCommunication, isCrowdControlFilterEnabled, crowdControlLevel, distinguishedAs, removedByCategory, suggestedCommentSort, isTranslated, translatedLanguage, isThumbnailEnabled, flair, thumbnail, authorId, authorType, authorFlair, authorIsNsfw, authorIsCakeDayNow, authorIconUrl, media, gallery, poll, postEventInfo, crosspostRoot, subredditInfo, searchQuery, scrapedAt
Comment row (37 fields)
parentId is the parent comment's ID (or null for a top-level comment), so you can reconstruct full reply threads from a flat result set.
Every row also carries threadUrl (an absolute link to the match on Reddit), searchQuery (your query, so merged results stay attributable) and scrapedAt. bodyMedia lists the images embedded in a post or comment body (the markdown shows them only as ; each entry has that id and the image url). Comment rows add _post_id and _subreddit, the join keys the other Clearpath Reddit actors use, and authorCreatedAt, the author's account creation date.
Comment fields (37): _type, _status, id, parentId, author, subreddit, score, createdAt, editedAt, permalink, threadUrl, _post_id, _subreddit, body, bodyMedia, isScoreHidden, isOP, authorId, authorKarma, authorCreatedAt, authorType, authorIsAcceptingFollowers, authorIconUrl, postId, postTitle, postUrl, postAuthor, postScore, postCommentCount, postFlair, postDomain, postIsSelfPost, postCreatedAt, postLanguageCode, subredditSubscribers, searchQuery, scrapedAt
Pricing - Pay Per Event (PPE)
| $0.99 per 1,000 results |
You pay only for what you scrape. Each result (post or comment) counts as one result-scraped event.
Budget controls: Set a spending limit on any run from the Apify Console. The actor stops automatically when the budget is reached, and you keep all data scraped up to that point. The run's status message then says it stopped at your limit and how much it delivered, so a capped run never looks complete.
Use Cases
Brand monitoring. Search for your company or product name across all of Reddit. Use sort: "new" to catch mentions as they appear. Schedule daily or hourly runs to build a continuous feed of brand mentions with scores, timestamps, and subreddit context.
Market research. Search keywords related to your industry to understand what real users discuss, recommend, and complain about. The score and commentCount fields reveal which topics generate the most engagement. Scope to relevant subreddits for focused insights.
Content research. Find top-performing discussions on any topic. Use sort: "top" with timeFilter: "month" to surface the highest-scoring content from the past 30 days. The body field gives you the full text, and upvoteRatio tells you how universally the community agrees.
Competitor analysis. Search competitor names and products to see what customers say on Reddit. Compare engagement metrics across different brands. The subreddit field reveals which communities discuss each competitor most.
Sentiment analysis. Pull thousands of comments mentioning a topic and feed them into your NLP pipeline. Each row includes the full text, score, and metadata needed for downstream analysis. Use time filters to segment sentiment by period.
Lead generation. Monitor subreddits where your target audience asks for recommendations. Search for phrases like "looking for", "best tool for", or "alternative to" to find high-intent posts. Export to your CRM or outreach tool via Apify integrations.
Academic research. Build datasets of public Reddit discussions on any topic. The structured output with timestamps, scores, and subreddit metadata supports quantitative analysis of online discourse, community dynamics, and information spread.
SEO and content strategy. Analyze which questions and topics generate engagement in your niche. Use comment search to find the specific advice and recommendations that get upvoted. Map these insights back to your content calendar.
Monitor Bluesky as well. Track the same keywords on Bluesky with Bluesky Scraper: post search far past the first page, filtered by date, language or author.
FAQ
Why did I get zero results with a time filter?
Reddit search has no server-side date filter. The actor walks the search results and keeps the posts inside your window, so timeFilter: "hour" on a niche query often finds nothing because nothing matched in that hour. Most empty runs use hour or day together with sort: "relevance". Use sort: "new" with short windows, widen the window, or drop the filter and sort by new to see the latest matches.
How many results can I get per run?
No hard limit. Set maxResults to 0 for unlimited. A single search of all of Reddit reaches about 300 matches per sort order; auto-discovery adds matches from relevant subreddits. The actual count depends on how many matching posts or comments exist: a popular topic can return several hundred, a niche one far fewer. In both mode each type gets up to maxResults, so the total can be up to twice that.
What's the difference between searching posts and comments?
Post search matches against post titles and body text. Comment search matches against comment text. Use contentType: "both" to search both simultaneously. Each type is returned as separate rows with a _type field.
How does multi-subreddit search work?
When you provide multiple subreddits, the actor searches each one in parallel. Results are merged into a single dataset. Each row includes a subreddit field so you can filter or group by community.
What subreddit formats are accepted?
Plain name (python), prefixed (r/python), full URL (https://reddit.com/r/python), old/new/mobile URLs, and any combination in the same input. The actor normalizes everything before searching.
Can I search all of Reddit at once?
Yes. Leave both subreddit and subreddits empty, and the actor searches across all public subreddits. With auto-discovery on (the default) it then also searches the most relevant communities for your query, with about half of maxResults reserved for them; turn it off for one search of all of Reddit only.
Which subreddits were auto-discovered?
The run's key-value store holds the record DISCOVERED_SUBREDDITS: every community found, with its name, link, subscriber count, description and icon. The run's status message names the record, and the run log lists the communities. Pass them as subreddits to search exactly those next time.
Can I search an exact date range?
Yes. Set postedAfter and/or postedBefore to a date (2026-10-01, read as midnight UTC) or a date-time (2026-10-01T12:00:00Z). Only results created inside the range are delivered and charged. With sort: "new" the search stops at the first result older than postedAfter, which makes a scheduled monitor cheap: set postedAfter to the previous run's start. It combines with timeFilter (both apply).
How do time filters work?
Time filters restrict results to a specific window: past hour, day, week, month, or year. Leave empty to search all time. The filter is applied to the matches after they are fetched, so it works with every sort order, but a narrow window under relevance or top can take longer and return few rows. sort: "new" suits short windows best.
What happens if I search a subreddit that doesn't exist? The actor skips it and continues with the remaining subreddits. You are not charged for failed searches. An entry that is not a valid subreddit name is skipped and named in the run log; if none of the names you gave is valid, the run searches nothing and its status message says so, instead of widening to all of Reddit.
What does the _status field mean?
"found" means the result was successfully scraped. This field is consistent across all actors in the Clearpath Reddit Suite, so you can build pipelines that handle status uniformly.
How does "both" mode split the results?
When contentType is "both", the actor runs post search and comment search in parallel. Each type gets up to maxResults results independently. The total output can be up to twice maxResults.
Can I use boolean operators in the search query?
Yes. The query supports AND, OR, NOT, quoted phrases for exact matching, a leading - to exclude a term, and parentheses for grouping. For example: ("flask" OR "django") AND "REST API". Maximum query length is 700 characters.
Can I monitor my brand and its competitors in one search?
Yes, and it's the most popular use of this actor. Group every name with OR inside parentheses and anchor it with a phrase: ("1Password" OR "Bitwarden" OR "Dashlane") "switched". Set sort: "new" and schedule the run to get a continuous feed of every mention across Reddit.
Can I search only post titles, or only post bodies?
Yes. Use title: to require a term in the title (title:"show reddit") and selftext: to require it in the body (selftext:"changed my life"). This cuts out posts that only mention your term in passing.
Can I find every post from a specific user?
Yes. Use author:username (for example author:AutoModerator). Combine it with keywords or the subreddits field to narrow further.
Can I limit results to text posts or link posts?
Yes. Add self:yes for text (self) posts only, or self:no for link posts only. You can also target link posts by domain with url: (for example url:youtube.com).
Can I filter by post flair?
Yes. Use flair:"Discussion" to match a specific flair. Flair filtering is most precise when you also scope the run to one subreddit with the subreddits field, since flairs are defined per community.
What sort orders work for comments?
relevance, new, and top work for both posts and comments. hot and comments (most comments) rank posts; when comments are searched with them, the comments are ranked by relevance.
Can I schedule recurring searches?
Yes. Set up a schedule in the Apify Console to run the actor at any interval. Combine sort: "new" with a time filter that matches the schedule (for example day for a daily run) to build a continuous monitoring pipeline. Each run returns what matches at that moment, so a row can appear in two runs; deduplicate on id downstream.
What output formats are available? The Apify Console lets you download results as JSON, CSV, Excel, XML, or RSS. You can also access the dataset via the Apify API in any of these formats.
How does this compare to the Subreddit Posts Scraper? This actor searches by keyword across Reddit. The Subreddit Posts Scraper scrapes a subreddit's feed (hot, new, top, rising, controversial) without a keyword filter. Use this actor when you need to find specific content. Use the Subreddit Posts Scraper when you want everything from a subreddit's feed.
How does this compare to the Post & Comments Scraper? This actor finds posts and comments by keyword. The Post & Comments Scraper starts from specific post URLs and extracts full comment trees with nested replies. Use this actor for discovery, and the other for deep extraction of known threads.
More Clearpath scrapers for Reddit
- Reddit Subreddit Posts Scraper
- Reddit Post Comments Scraper
- Reddit Profile Scraper
- Reddit User Posts & Comments Scraper
- Reddit MCP Server
Also from the same studio (name, then account/slug for the URL https://apify.com/account/slug):
- Reddit Answers API (
clearpath/reddit-answers-api) - Reddit to LLM (
clearpath/reddit-to-llm-api) - Bluesky Scraper (
clearpath/bluesky-scraper)
Full directory: Clearpath on Apify
Support
- Bugs: Issues tab
- Features: Email or issues
- Email: max@mapa.slmail.me
Legal Compliance
Extracts publicly available data. Users must comply with Reddit terms and data protection regulations (GDPR, CCPA).


