
Kompas News Scraper
Pricing
from $1.50 / 1,000 results
Kompas News Scraper
Scrapes news articles from Kompas.com, including headline, author, editor, publish date, category, images and full article text.
Pricing
from $1.50 / 1,000 results
Rating
0.0
(0)
Developer
ActorFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Kompas.com News Scraper - Indonesian News Articles & Headlines
Scrape news articles from Kompas.com (kompas.com), one of Indonesia's leading news portals: headline, summary, author, editor, publish and update time, category, keywords, images and the full article text. Export the results as JSON, CSV or Excel, or call the actor as an API. Paste a Kompas listing or article URL, press Start, and get a clean Indonesian news dataset.
Target website: kompas.com
✨ Features of this Kompas news scraper
- Article extraction — headline, summary, authors, editor, publish and update timestamps, category, section, keywords, images, full body text and word count.
- Full multi-page articles — long stories split across several pages are fetched complete, in one record.
- Pagination support — walks the listing pages automatically until Max items per start URL is reached.
- Automatic URL detection — listing pages and article URLs are told apart automatically, so you can mix both in Start URLs.
- Whole-site mode — one toggle crawls the index of every major Kompas channel instead of a hand-picked list.
- Optional sentiment analysis — switch on Analyze sentiment to label every article positive, negative, neutral or mixed, with a confidence score. Off by default.
- Incremental runs — with a cache project name, articles you already scraped are skipped on later runs.
- Proxy support — optional Apify Proxy; Kompas normally works without one.
- No browser required — plain HTTP requests keep runs fast and cheap.
🚀 How to scrape Kompas news in 5 steps
- Sign up for a free Apify account — includes $5 monthly credit.
- Open the actor page and click Try for free.
- Fill in the Input fields (at least one Kompas start URL is required).
- Click Start and wait for the run to complete.
- Download results from the Output tab in JSON, CSV, or Excel format.
You can also run this actor via the Apify API or integrate it directly into your workflows using Zapier, Make, or n8n.
💰 Kompas scraper pricing
This actor uses pay-per-result billing: you pay for each article saved to the dataset.
- New Apify accounts include $5 of free monthly credit.
- The actor uses plain HTTP requests, so it costs significantly less to run than browser-based scrapers.
- Articles skipped by the cache are not saved and not charged.
- Kompas works without a proxy, so switching Apify Proxy off keeps runs cheapest.
🔧 Kompas scraper input configuration
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
Start URLs (startUrls) | array | ✅ | kolom.kompas.com (prefill) | Kompas listing URLs (indeks.kompas.com or channel front pages) or direct article URLs. The type of each URL is detected automatically. |
Max items per start URL (maxItems) | integer | — | 5 | Maximum number of articles to scrape for each start URL. |
Cache project name (cacheProjectName) | string | — | — | Use the same name on each run to skip articles already scraped under it. |
Scrape the whole site (scrapeWholeSite) | boolean | — | false | Ignore Start URLs and crawl the index pages of every major Kompas channel. |
Analyze sentiment (analyzeSentiment) | boolean | — | false | Classify each article as positive, negative, neutral or mixed. Adds sentiment, sentimentConfidence and sentimentScores. |
Proxy configuration (proxyConfiguration) | object | — | {"useApifyProxy": true} | Kompas responds without a proxy. Try datacenter proxies first if you get blocked, residential only if that still fails. |
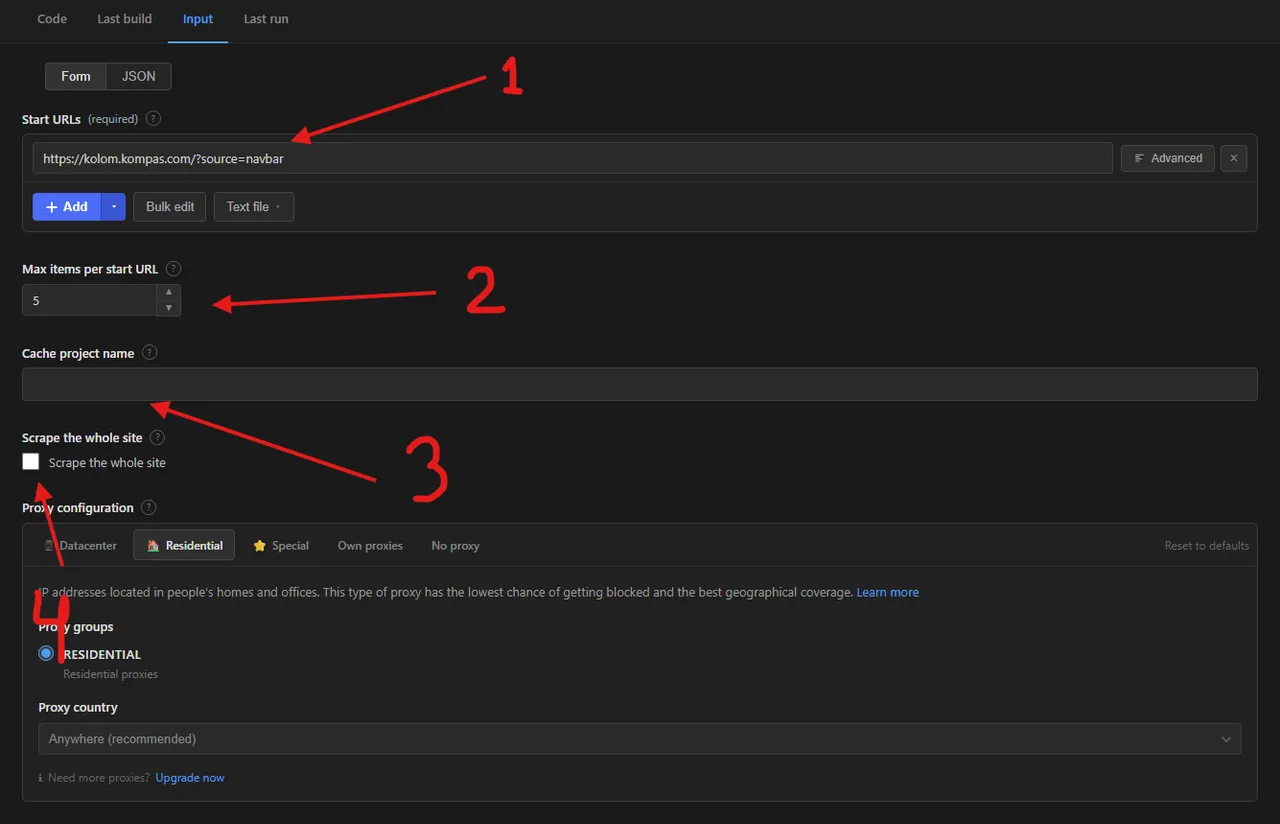
The numbered markers in the screenshot show the four fields most runs use:
- Start URLs — a Kompas listing page (for example a channel front page) or a direct article URL.
- Max items per start URL — how many articles to save for each URL.
- Cache project name — optional; reuse the same name on every scheduled run to get only new articles.
- Scrape the whole site — tick it to crawl every major channel and ignore Start URLs.
Supported URL types:
- Listing pages — the index at
https://indeks.kompas.com/and channel front pages such ashttps://tekno.kompas.com/. - Article pages — any URL under
/read/{yyyy}/{mm}/{dd}/, for examplehttps://edukasi.kompas.com/read/2026/09/10/091950471/cerita-mendikti.
📦 Kompas scraper output data
Each article is one dataset item with the fields url, title, description, authors, editor, publisher, publishedAt, modifiedAt, category, section, keywords, images, body and wordCount, plus sentiment, sentimentConfidence and sentimentScores when Analyze sentiment is on. The dataset has 1 view, Overview, a table of title, category, authors, publish date, sentiment, word count and article link. The sentiment column is empty unless Analyze sentiment is on.
With Analyze sentiment on, each article gets a sentiment (positive, negative, neutral or mixed), a sentimentConfidence between 0 and 1, and sentimentScores with the probability of every label, based on the headline, summary and the start of the article text:
Output at a glance:
| Title | Category | Authors | Published | Words |
|---|---|---|---|---|
| Demokrasi Tanpa "Delivery" | Nasional | Raisa Ayu Rininta | 2026-09-10 | 869 |
| Mengenang Airlangga Pribadi, Intelektual Penjaga Nalar | Nasional | Aji Cahyono | 2026-09-10 | 1,567 |
| Bangun Bursa Mineral dan Komoditi Strategis yang Kredibel | Ekbis | Gusmardi Bustami | 2026-09-10 | 1,143 |
Sample output (raw JSON):
🐍 How to scrape Kompas with Python, JavaScript or the API
Run the actor programmatically with the official Apify clients. Replace <YOUR_API_TOKEN> with the token from your Apify Console.
Python (pip install apify-client):
JavaScript (npm install apify-client):
cURL — start a run and wait for the dataset:
💡 What you can use Kompas news data for
- Tracking how a topic, company or public figure is covered in Indonesian media over time
- Building a searchable archive of Indonesian news articles
- Training or evaluating Indonesian-language NLP and sentiment models
- Competitive and brand monitoring across Kompas channels
- Feeding dashboards, alerts and newsletters with fresh headlines
Media monitoring teams, researchers, data scientists, PR and marketing agencies, and analysts covering Indonesia typically use this data.
⚠️ Kompas scraper limitations and known issues
- Live front pages change constantly — running the same listing URL twice may return a different set of articles as new stories are published.
❓ Kompas scraper FAQ
Can I scrape Kompas.com legally?
The actor only collects data that is already publicly visible on Kompas.com: it does not log in, bypass a paywall or access private content. Scraping publicly available data is generally considered lawful (see hiQ Labs v. LinkedIn), but you are responsible for complying with Kompas's Terms of Service and applicable laws such as GDPR if article text or bylines contain personal data.
What data does the Kompas news scraper return?
Every article has its URL, headline, summary, authors, editor, publisher, publish and update time, category, section, keywords, images, full body text and word count.
How many Kompas articles can I scrape from one URL?
maxItems limits the number of articles per start URL, not for the whole run. On listing pages the actor keeps moving to the next page until that limit is reached.
Do I need a proxy to scrape kompas.com?
No. Kompas responds without a proxy, which keeps runs cheapest. If you start seeing blocks, enable datacenter proxies first and use residential proxies only if datacenter still fails.
How do I scrape Kompas news with Python?
Use the Python example above: call the actor with ApifyClient, then iterate over the dataset items of the finished run.
Can I run this Kompas scraper on a schedule?
Yes. Use Apify Schedules to run it daily or hourly. Set a Cache project name and every scheduled run saves only articles that earlier runs under that name have not already scraped.
What formats can I export Kompas news in?
JSON, CSV, Excel, XML and RSS, either from the Output tab or through the Apify API.
Can I get the sentiment of Kompas articles?
Yes. Switch on Analyze sentiment and every article is classified as positive, negative, neutral or mixed, with a confidence score and per-label probabilities. It is off by default and the four labels are fixed.
Does the scraper get full articles that are split across several pages?
Yes. Multi-page stories are requested in full, so each long article comes back as a single record with the complete text.
🔗 Other actors you may find useful
| Scraper | Description |
|---|---|
| 📰 Detik News AI Scraper | Indonesian news from Detik.com: headline, author, publish date, category, images and full article text. |
| 🗞️ Sydney Morning Herald (SMH) News Scraper | News articles from smh.com.au: headline, author, publish date, section, keywords and full text. |
| 🔎 Google News AI Scraper | Google News by keyword, with optional full article text and AI-generated summaries. |
| 💬 Sentiment Analysis Using Jev | Classifies article text as positive, negative, neutral or mixed, or into your own custom labels. |
| ✍️ Substack Scraper | Substack posts and comments by keyword, publication or post URL: title, author, date and full text. |
💬 Support & contact
If you encounter any issues or have questions, please open an issue or reach out via the Apify Community Forum.
You can also find more of our actors on the Actor Flow page.
🇮🇩 Scraper berita Kompas.com: panduan singkat (Bahasa Indonesia)
Actor ini mengambil artikel berita dari Kompas.com secara otomatis.
Cara pakai:
- Isi Start URLs dengan halaman indeks (misalnya
https://indeks.kompas.com/) atau langsung URL artikel. Jenis URL dideteksi otomatis. - Atur Max items per start URL untuk membatasi jumlah artikel per URL.
- Aktifkan Scrape the whole site jika ingin menelusuri seluruh kanal utama Kompas.
- Isi Cache project name (opsional) agar artikel yang sudah diambil pada run sebelumnya dilewati.
- Klik Start, lalu unduh hasilnya dalam format JSON, CSV, atau Excel.
Data yang diambil: judul, ringkasan, penulis, editor, tanggal terbit dan perubahan, kategori, kata kunci, gambar, serta isi lengkap artikel (termasuk artikel yang terbagi ke beberapa halaman).
Catatan: actor ini hanya mengambil data yang memang tampil untuk publik di Kompas.com — tanpa login dan tanpa menembus konten berbayar.


