
Instagram Reels Scraper
Pricing
from $1.50 / 1,000 reel results
Instagram Reels Scraper
Scrape public Instagram Reels from profiles or direct Reel URLs. Extract captions, hashtags, likes, comments, shares, views, play counts, duration, creators, tagged users, collaborators, music, transcripts, thumbnails and video URLs. Export clean JSON, CSV or Excel.
Pricing
from $1.50 / 1,000 reel results
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
5
Total users
2
Monthly active users
9 days ago
Last modified
Categories
Share
Scrape public Instagram Reels from profiles or direct Reel URLs. Extract captions, hashtags, likes, comment counts, play counts, duration, creators, tagged users, collaborators, music, thumbnails and video URLs. Export clean JSON, CSV or Excel.
What this actor does
Instagram Reels Scraper takes Instagram usernames, profile URLs, Reels-tab URLs, Reel URLs or shortcodes and returns one clean row per Reel:
- 🎬 Reels only: you never pay for photo posts or carousels
- ▶️ Play counts on every Reel:
videoPlayCount, plusvideoViewCountwhere Instagram reports it separately. Never estimated - 📊 Engagement: likes and the exact total comment count
- 🙈 Hidden likes done right:
likesCount: nullwithlikesHidden: true. Never a fake zero - 🎵 Music / audio for Reels collected from profiles: song title, artist, audio ID, original-audio flag and audio URL where public
- 👥 People: creator (name, verified, followers), collaborators/co-authors and tagged users
- 🎞️ Video: duration, width, height, thumbnail and direct video URL
- 📌 Pinned flag, plus 📍 location and 💬 comments-disabled where Instagram includes them
- 🤝 Sponsorship: paid-partnership flag and sponsor name, taken from Instagram's own label (never guessed from
#ad) - 🗓️ Date filtering that stays correct around old pinned Reels
For profile metadata (bio, follower counts, business contact) use Instagram Profile Scraper. For photos, carousels and Reels together use Instagram Posts Scraper.
How it works
- Detect inputs. Each entry is classified on its own: profile (
natgeo,@natgeo,instagram.com/natgeo), Reels tab (instagram.com/natgeo/reels/), Reel URL (/reel/…,/reels/…, share links) or bare shortcode. Tracking parameters are stripped and duplicates are removed. You never pick a mode. - Profiles. The profile is resolved first, so private and nonexistent accounts are reported straight away. Its Reels tab is then paged newest-first until your limit, your date cutoff or the last Reel.
- Direct Reels. Each Reel URL is looked up directly and returns at most one row.
- Retry safely. Rate limits, login walls and temporary errors are retried on a fresh session/IP with backoff, and a profile resumes from where it stopped. If Instagram keeps refusing, the Reels come from an alternative source instead of waiting out the throttle.
- Export. One row per Reel. Inputs that can't be served get a free status row, so every input can be matched to an output.
FAQ
Which inputs are supported? Usernames, @handles, profile URLs, profile Reels-tab URLs (/natgeo/reels/), direct Reel URLs (/reel/…, /reels/…, and /p/… links that point to a Reel), Instagram share links (/share/reel/…), and bare shortcodes in the URL field. Mix them freely in one run.
Do I need an Instagram login or cookies? No. You don't provide any login, password, cookies, session IDs or Meta token. The actor only reads public content.
Can I scrape all Reels from a profile? Yes. Set resultsLimit at or above the number of Reels the profile has. Instagram serves a Reels tab 12 at a time, so very large exports take longer.
Can I scrape direct Reel URLs? Yes. Put them in Instagram URLs. Each one returns at most one row. A URL that turns out to be a photo or carousel post gets a free status row and is not charged.
Are views and play counts included? Play counts, yes: videoPlayCount is filled on every Reel. Instagram reports a separate view count (videoViewCount) only for direct Reel URLs, and there it currently equals the play count. For Reels collected from a profile, videoViewCount is null. The actor never copies one metric into the other or estimates a missing one.
Are shares included? Not at the moment. Instagram doesn't expose share counts through the sources this actor uses, so sharesCount is null. The field stays in the output so your columns don't change if that changes.
Is music/audio included? Yes, for Reels collected from a profile or Reels tab: music holds the audio ID, title, artist, whether it's the creator's original audio, and the audio file URL when Instagram provides one. For direct Reel URLs Instagram doesn't send audio details, so music is null there. No audio fingerprinting is done. Turn it off with includeMusic: false.
Are transcripts included? Not at the moment. The actor only reads Instagram's own captions and never transcribes audio itself, and Instagram currently doesn't expose those captions through the sources this actor uses. Every Reel therefore comes back with transcript.available: false. The transcript field and the includeTranscript switch stay in place so captions appear automatically if Instagram exposes them again.
Are collaborators included? Yes. coauthors lists collab accounts (ID, username, full name, profile URL, verified flag), and taggedUsers lists people tagged in the Reel.
Are trial Reels included? Trial Reels that appear on a profile are returned like any other Reel. Instagram doesn't currently say which Reels are trials, so isTrialReel is null rather than a guess.
Are video URLs included? Yes, as videoUrl, plus thumbnailUrl. Turn video URLs off with includeVideoUrls: false. The actor doesn't download video files into storage.
Do video URLs expire? Yes. Instagram CDN links are signed and stop working after a while. Download the files soon after the run if you need them.
Can I filter by date? Yes. reelsNewerThan accepts 2026-09-01 or a period like 7 days, 30 days or 24 hours. Paging stops as soon as older Reels are reached. reelsOlderThan returns only Reels before a date. Filtered-out Reels are not charged.
What happens with pinned Reels? They are returned with isPinned: true, and an old pinned Reel at the top of a profile never stops date-based paging early. Set skipPinnedReels: true to leave them out entirely.
What happens with private profiles? You get a free PRIVATE_PROFILE status row and no Reels. The actor never tries to access private content. For the public metadata of a private account, use Instagram Profile Scraper.
Are comments included? The total, yes: commentsCount is on every Reel. Comment text isn't: Instagram doesn't currently send any comments with the Reel data this actor reads, so latestComments stays empty even with includeLatestComments: true. For comment text, see the next question.
How do I get full comment threads? Use a dedicated comments scraper such as Instagram Comment Leads Extractor, feeding it the url values from this actor.
How is pricing calculated? Per returned Reel. See Pricing.
Are creator follower counts included? Yes for Reels collected from a profile (with includeOwnerDetails: true). For direct Reel URLs, and for collab Reels authored by another account, owner.followersCount is null; use Instagram Profile Scraper for follower counts.
How does resultsLimit work? It's the maximum number of Reels per profile input. Two profiles with resultsLimit: 100 return up to 200 Reels. Direct Reel URLs always return at most one Reel each.
Can I use it through the API or MCP? Yes. Like every Apify actor it can be run from the Apify API, the Apify client libraries, scheduled tasks, integrations (Make, Zapier, n8n) and the Apify MCP server for AI agents.
Input
| Field | Type | Default | Description |
|---|---|---|---|
startUrls | array | — | Profile, Reels-tab, Reel or share URLs, or bare shortcodes |
profiles | array | — | Usernames or @handles |
resultsLimit | integer | 100 | Max Reels per profile (1–10,000) |
reelsNewerThan | string | "" | Only Reels after this date / period |
reelsOlderThan | string | "" | Only Reels before this date / period |
skipPinnedReels | boolean | false | Leave out pinned Reels |
includeVideoUrls | boolean | true | Return direct video URLs |
includeMusic | boolean | true | Return music/audio metadata (Reels from profiles) |
includeTranscript | boolean | true | Instagram's own caption text; currently always unavailable (see FAQ) |
includeLatestComments | boolean | false | Comments already included with the Reel; currently none are (see FAQ) |
includeOwnerDetails | boolean | true | Creator name, verified flag and followers |
proxyConfiguration | object | Apify Proxy | See Proxy policy |
maxConcurrency | integer | 5 | Inputs processed in parallel |
maxRetries | integer | 4 | Retries per input on rate limits and temporary errors |
debugMode | boolean | false | Verbose logging |
Use startUrls, profiles or both. Up to 1,000 inputs per run.
Example 1: The latest Reels of a profile (used for the screenshot and samples below)
Example 2: Direct Reel URLs
Example 3: Monitor competitors' last 30 days (schedule it)
Example 4: Lightweight metrics only
Output
One row per Reel. Every row (Reel or status) has the same set of keys, so CSV and Excel exports keep stable columns. Values Instagram doesn't expose are null, never guessed. The dataset has four tabs: Reels, Music & transcripts, Creators & collaborations and Status & errors.
The screenshot and records below come from Example 1: 100 Reels from natgeo, all returned as SUCCESS. CDN URLs are shortened.
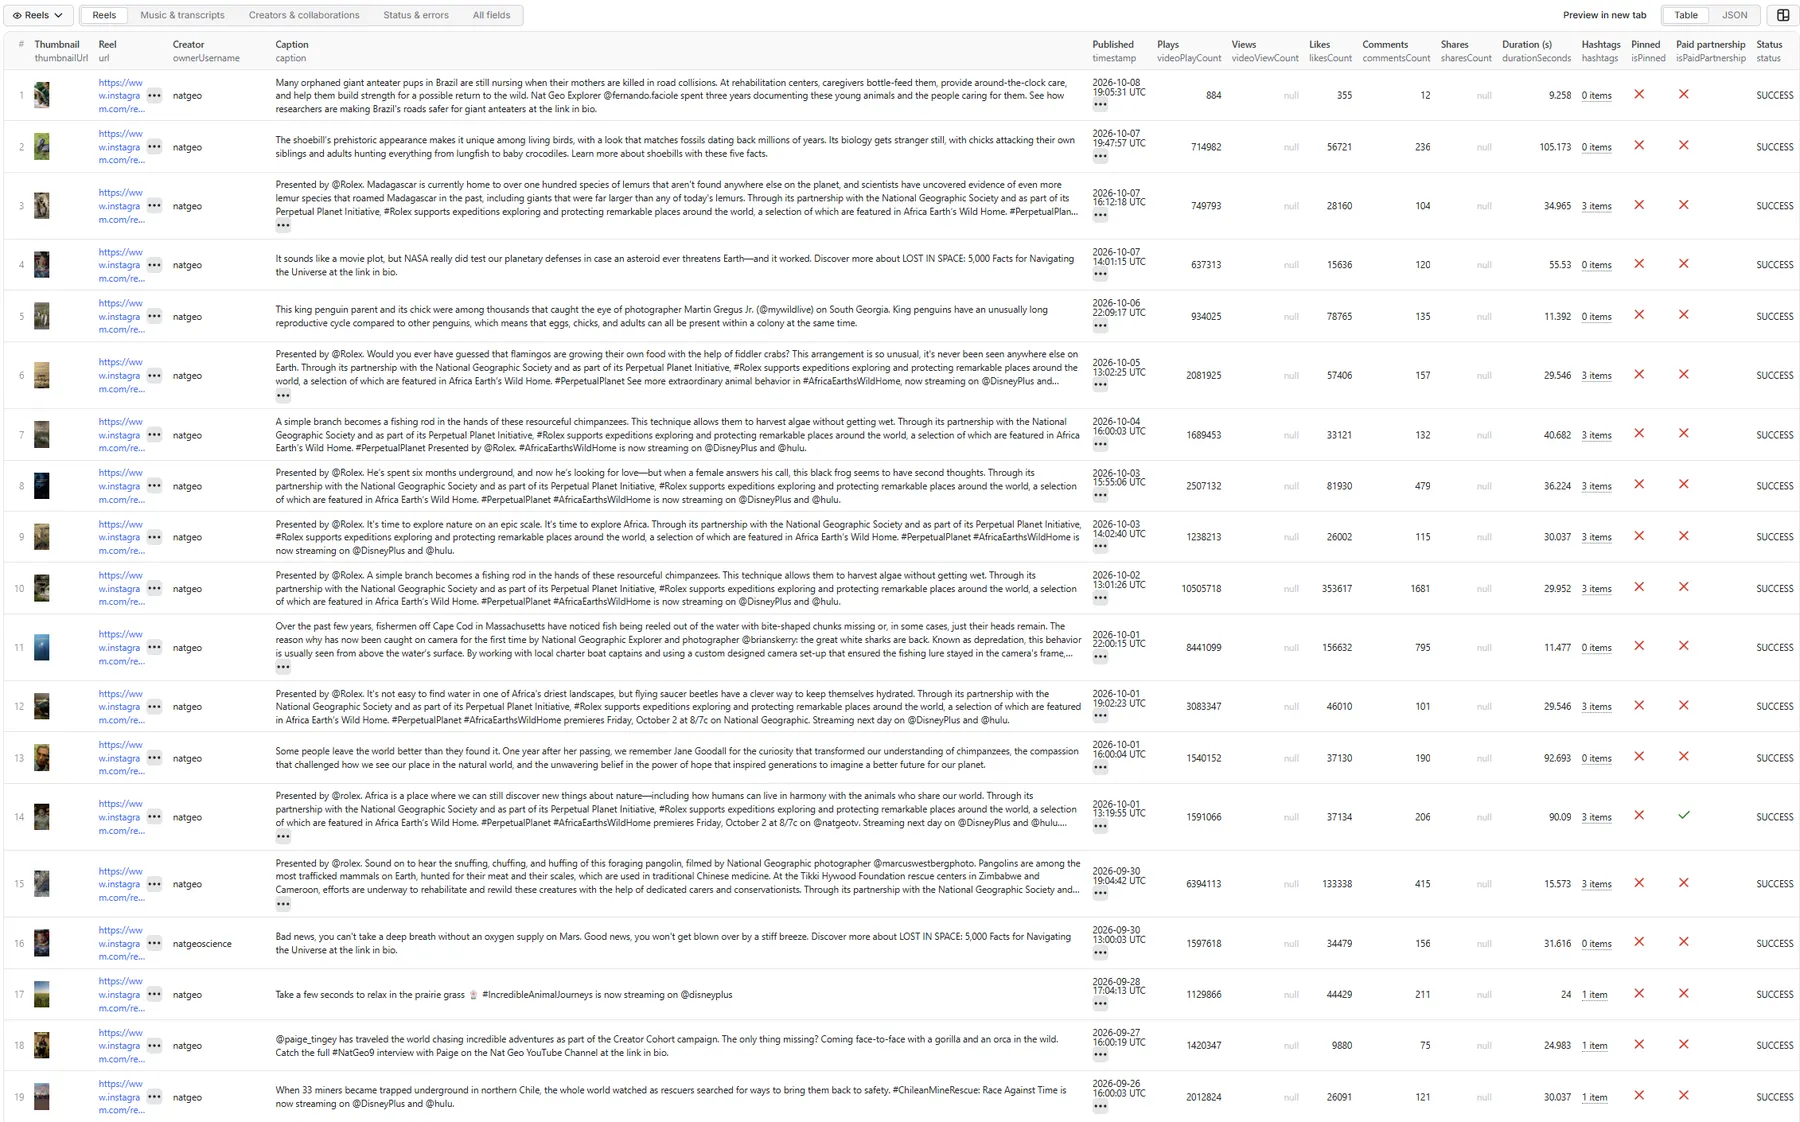
Reels tab: sample record
Music & transcripts tab: sample record
A Reel set to a licensed track. Most natgeo Reels use their own original audio (isOriginalAudio: true, with the creator as artist).
Creators & collaborations tab: sample record
A collab Reel authored by another creator, with natgeo as co-author and paid-partnership sponsor. owner.followersCount is null because the author isn't the profile that was scraped.
Status & errors tab: sample record
The sample run had no failed inputs, so this example shows the row a private profile produces. All other keys are present with null values.
Full record (all fields)
The same Reel requested by its URL comes back with videoViewCount and videoPlayCount both filled (Instagram reports the same number for both there) and commentsDisabled: false, but with music and owner.followersCount as null.
Status values
| Status | Meaning | Charged |
|---|---|---|
SUCCESS | Reel returned | ✅ |
PARTIAL_RESULT | A Reel missing core fields, or a profile whose Reels feed stopped early (the Reels already returned are kept) | — |
INVALID_INPUT | Not a recognizable Instagram username, URL or shortcode | — |
PROFILE_NOT_FOUND | The profile doesn't exist | — |
REEL_NOT_FOUND | The Reel doesn't exist or was removed | — |
PRIVATE_PROFILE | The profile is private | — |
CONTENT_UNAVAILABLE | Instagram refused this content, or the URL is a photo/carousel post rather than a Reel | — |
AGE_RESTRICTED | The content needs a logged-in, age-verified viewer | — |
LOGIN_WALL / RATE_LIMITED / BLOCKED | Instagram kept refusing after all retries and the fallback | — |
TEMPORARY_INSTAGRAM_ERROR / PROVIDER_ERROR | Upstream failure after all retries | — |
A missing transcript or video URL doesn't fail the row: the Reel is still returned, with transcript.available: false or videoUrl: null.
Run summary and retry input
Each run writes RUN_SUMMARY to the key-value store: inputs, successful and failed inputs, Reels saved, pinned and trial Reels, transcripts and music available, duplicates skipped, Reels filtered by date, and availability rates for views, plays, shares, video URLs, music and transcripts. If any input failed for a temporary reason, RETRY_INPUT holds a ready-to-run input containing just those inputs.
Pricing
Pay per event, per returned Reel. You are not charged for profile lookups, pagination, retries, music data, transcripts, the comments preview, media URLs, tagged users, collaborators, invalid inputs, duplicates, filtered-out Reels, partial results or error rows. A Reel reached both through a profile and a direct URL is charged once. There is no start fee. The per-Reel rate can differ by Apify plan, so see the Pricing tab for the current rate on yours. This README deliberately doesn't quote figures.
The actor respects the spending limit you set for a run: when it's reached, the run stops cleanly and no further Reels are fetched.
🚦 Proxy policy
Use Apify Datacenter proxy (the default) or no proxy for normal runs. Both work for Instagram Reels tabs and Reel lookups at this actor's conservative concurrency.
Apify Residential proxy is not supported. The actor fails at startup if apifyProxyGroups includes RESIDENTIAL. In pay-per-event actors, residential bandwidth is billed per GB to the developer, not the run user, so a single bandwidth-heavy run could cost more than the per-result revenue.
If you need residential routing, supply your own residential provider in the proxy editor's Custom proxy URLs field. That traffic goes through your provider, not Apify, and is unaffected:
Limitations
- Public Reels only. Private accounts, Stories, Highlights and close-friends content are out of scope.
- Instagram decides what's public. Share counts, trial-Reel state, transcripts and comment text aren't currently exposed, so those fields come back
null, empty or unavailable. Views are reported only for direct Reel URLs, and music and follower counts only for Reels collected from profiles. Likes on hidden-like Reels arenull. - No AI transcription. The actor never transcribes audio itself.
- Media URLs expire. Instagram's CDN links are temporary, and files are not stored by the actor.
- Large exports take time. Instagram serves a Reels tab 12 at a time, and the actor pages one profile sequentially to stay under rate limits.
- Not included: full comment threads, likers, follower lists, hashtag or keyword search, media downloads into storage, and AI analysis. These belong to separate actors.
- Public data availability on Instagram can change at any time.
Related actors
- Instagram Profile Scraper: profile metadata, follower counts, bio links and public business contact
- Instagram Posts Scraper: photos, carousels, videos and Reels from profiles
- Instagram Reel Hooks & Competitor Analyzer: what makes competitors' Reels work
- Instagram Comment Leads Extractor: commenters on posts and Reels as leads
Legal and privacy
This is an unofficial tool. It is not affiliated with, endorsed by or sponsored by Instagram or Meta. It processes only publicly accessible content and never accesses private accounts. Public Reels and creator profiles can contain personal data (names, faces, voices, tagged people, locations). You are responsible for having a lawful basis for collecting and processing it (for example under GDPR or CCPA), for collecting only the data relevant to your use case, and for complying with Instagram's terms in your use of the data.
Local development


