
Instagram Posts Scraper
Pricing
from $1.50 / 1,000 post results
Instagram Posts Scraper
Scrape public Instagram posts, carousels and Reels from profiles or direct URLs. Extract captions, hashtags, mentions, likes, comment counts, Reel views, timestamps, media URLs, tagged users, collaborators, locations and owner details. Export clean JSON, CSV or Excel.
Pricing
from $1.50 / 1,000 post results
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
7
Total users
3
Monthly active users
4 days ago
Last modified
Categories
Share
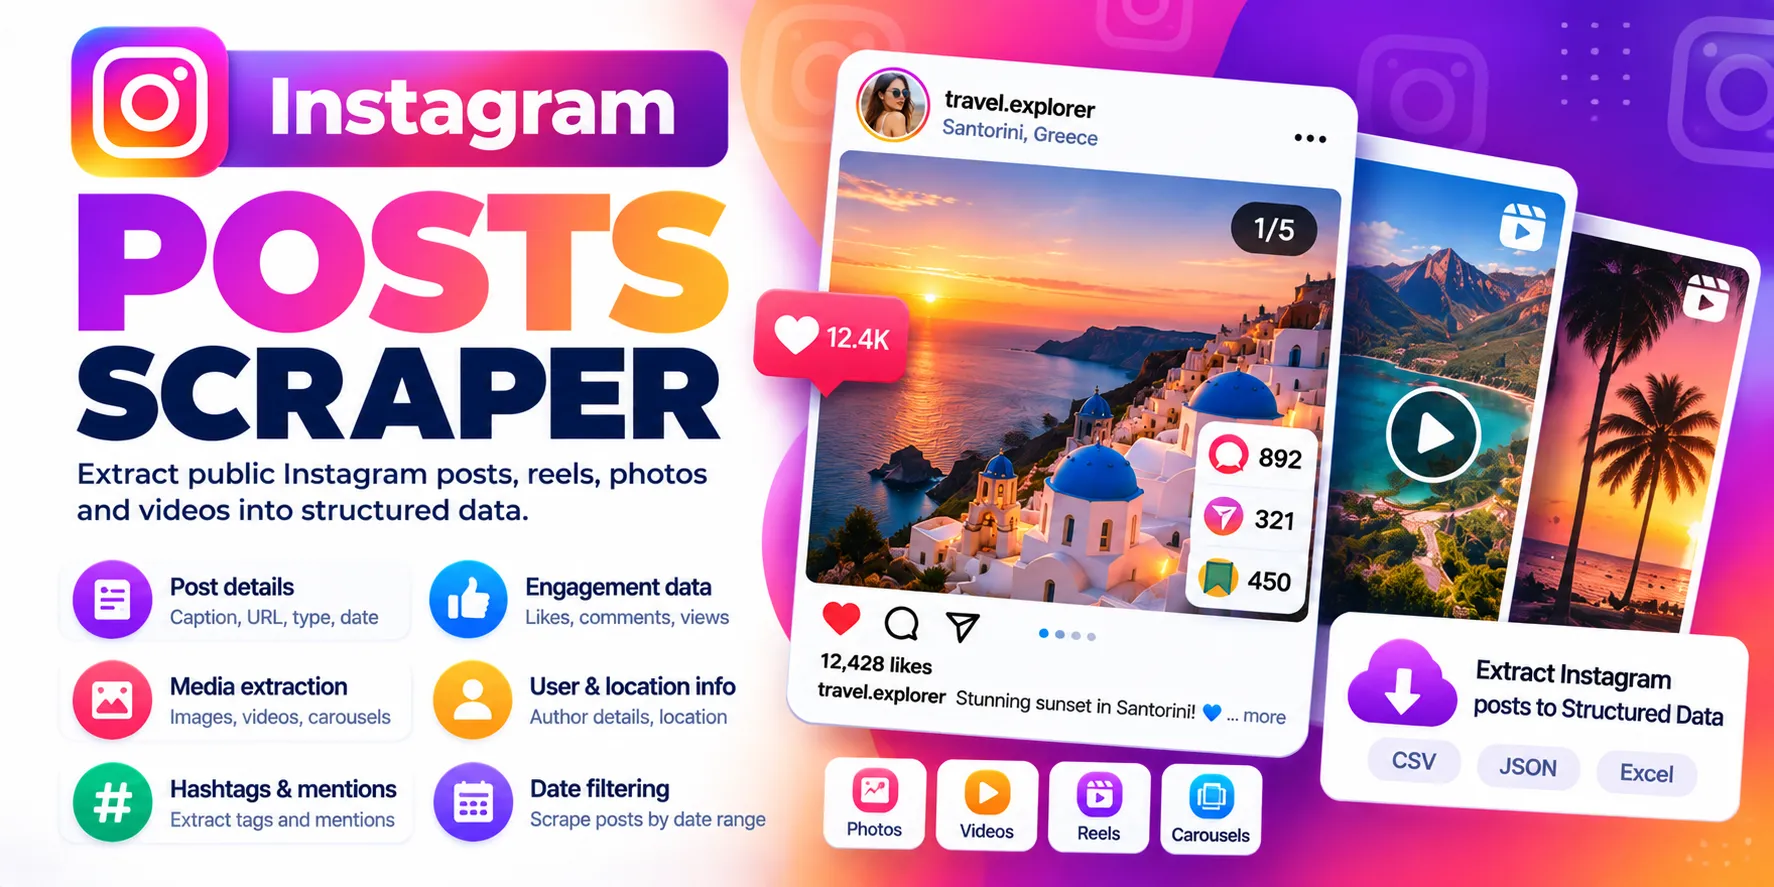
Scrape public Instagram posts, carousels and Reels from profiles or direct URLs. Extract captions, hashtags, mentions, likes, comment counts, Reel views, timestamps, media URLs, tagged users, collaborators, locations and owner details. Export clean JSON, CSV or Excel.
What this actor does
Instagram Posts Scraper takes Instagram usernames, profile URLs, post URLs, Reel URLs or shortcodes and returns one clean row per post:
- 🖼️ Every format: image posts, video posts, carousels (multi-slide) and Reels, all in one stable schema
- 📝 Text: caption, hashtags and mentions (parsed, without
#/@) - 📊 Engagement: likes, the exact total comment count, Reel/video plays and views, shares where public
- 🙈 Hidden likes done right:
likesCount: nullwithlikesHidden: true. Never a fake zero - 🎠 Complete carousels: every slide as a nested
childPostsentry, with no extra charge - 👥 People: owner (name, verified, followers), collaborators/co-authors and tagged users
- 📍 Location, 📌 pinned and ✏️ edited flags
- 🤝 Sponsorship: paid-partnership flag and sponsor name, taken from Instagram's own label (never guessed from
#ad) - 🎞️ Media: image, thumbnail and video URLs, video duration, dimensions and alt text
It is a posts and Reels scraper. For profile metadata (bio, follower counts, business contact) use Instagram Profile Scraper.
How it works
- Detect inputs. Each entry is classified on its own: profile (
natgeo,@natgeo,instagram.com/natgeo), post (/p/…), Reel (/reel/…), TV (/tv/…) or bare shortcode. Tracking parameters are stripped and duplicates are removed. You never pick a mode. - Profiles. The profile is resolved first, so private and nonexistent accounts are reported straight away. The feed is then paged newest-first until your limit, your date cutoff or the end of the feed.
- Direct URLs. Each post or Reel URL is looked up directly and returns at most one row.
- Retry safely. Rate limits, login walls and temporary errors are retried on a fresh session/IP with backoff, and a profile resumes from where it stopped. If Instagram keeps refusing, the content comes from an alternative source instead of waiting out the throttle.
- Export. One row per post. Inputs that can't be served get a free status row, so every input can be matched to an output.
FAQ
What input formats are supported? Usernames, @handles, profile URLs, /p/ post URLs, /reel/ and /reels/ URLs, legacy /tv/ URLs, the newer /{username}/p/{shortcode}/ form, and bare shortcodes in the URL field. Mix them freely in one run.
Do I need an Instagram login or cookies? No. You don't provide any login, password, cookies, session IDs or Meta token. The actor only reads public content.
Can I scrape an entire profile? Yes. Set resultsLimit at or above the profile's post count. Very large exports take longer because Instagram serves a profile 12 posts per page.
Can I scrape direct post or Reel URLs? Yes. Put them in Instagram URLs. Each one returns at most one row.
Are Reels included? Yes. Reels in a profile feed come back as mediaType: "REEL", and Reel URLs work directly. Use mediaTypes to keep only Reels or exclude them.
Are carousel slides included? Yes. A carousel is one row (one result) with every slide nested in childPosts. Slides are never charged separately.
What happens when likes are hidden? likesCount is null and likesHidden is true. The actor never substitutes zero for a count Instagram hides.
Are comment counts exact? commentsCount is the total Instagram reports for the post, not the number of comments loaded on the page. If a source reports 0 for a post that has comments turned on and the count can't be verified (this happens on some direct post URLs), commentsCount is null rather than a fake zero.
Are video and Reel views included? Yes, where Instagram exposes them: videoPlayCount (plays) and videoViewCount (views). Missing values stay null and are never estimated.
Can I filter by date? Yes. postsNewerThan accepts 2026-09-01 or a period like 7 days or 24 hours. Paging stops as soon as older posts are reached, and old pinned posts at the top of a profile don't stop it early. postsOlderThan returns only posts before a date.
Can I filter by media type? Yes. mediaTypes takes any of IMAGE, VIDEO, CAROUSEL, REEL. Filtered-out posts are not returned and not charged.
How does resultsLimit work? It's the maximum number of posts per profile input. Two profiles with resultsLimit: 100 return up to 200 posts. Direct URLs always return at most one post each, and carousel slides don't count toward the limit.
What happens with private profiles? You get a free PRIVATE_PROFILE status row and no posts. The actor never tries to access private content. For the public metadata of a private account, use Instagram Profile Scraper.
Are media URLs permanent? No. Instagram CDN links are signed and expire after a while. Download the media soon after the run if you need it. Set includeMediaUrls: false if you don't need them.
How is pricing calculated? Per returned post. See Pricing.
Can I schedule recurring collection? Yes. Schedule the actor in Apify with postsNewerThan: "24 hours" (or "7 days") to collect only new public content on each run.
Can I call it through the API or MCP? Yes. Use the Apify API, any Apify client library, or Apify's MCP server so AI agents can call it as a tool. See the API tab for ready-made snippets.
How do I get full comments? This actor returns the comment count, not the comment threads. Feed the post URLs into a comments scraper such as Instagram Comment Leads Extractor.
Input
| Field | Type | Default | Description |
|---|---|---|---|
startUrls | URL list | — | Profile, post, Reel or TV URLs, or bare shortcodes |
profiles | string[] | — | Usernames or @handles. Merged with startUrls, up to 1,000 inputs per run |
resultsLimit | int | 100 | Max posts per profile (direct URLs return at most one) |
postsNewerThan | string | — | Only posts after this date or period, with early stop |
postsOlderThan | string | — | Only posts before this date or period |
mediaTypes | string[] | all | Any of IMAGE, VIDEO, CAROUSEL, REEL |
includeCarouselChildren | bool | true | Nested childPosts for carousels |
includeOwnerDetails | bool | true | Owner full name, verified flag and follower count (the follower count comes from the profile, so it's set for posts from a profile input and null for direct URLs and collaborators' posts) |
includeMediaUrls | bool | true | Image, thumbnail and video URLs (CDN URLs expire) |
proxyConfiguration | object | Apify Proxy on | Proxy settings, see Proxy policy |
maxConcurrency | int | 5 | Inputs processed in parallel (pages of one profile are always sequential) |
maxRetries | int | 4 | Retries per input on rate limits, login walls or temporary errors |
debugMode | bool | false | Verbose logging |
Provide at least one entry in startUrls or profiles. A completely empty input runs the example profile natgeo.
Example 1: The latest posts of a profile
Example 2: Direct post and Reel URLs
Example 3: Last 30 days from several profiles
Example 4: Images and carousels only
Example 5: Daily monitoring of competitors (schedule it)
Output
One row per post or Reel, deduplicated by post ID: content reached through both a profile and a direct URL is returned and charged once. Unavailable values are null, never guessed. Every row has the same columns, so CSV/Excel exports stay stable.
The dataset has five tabs: Posts, Engagement, Media & carousels, People, location & partnerships and Status & errors.
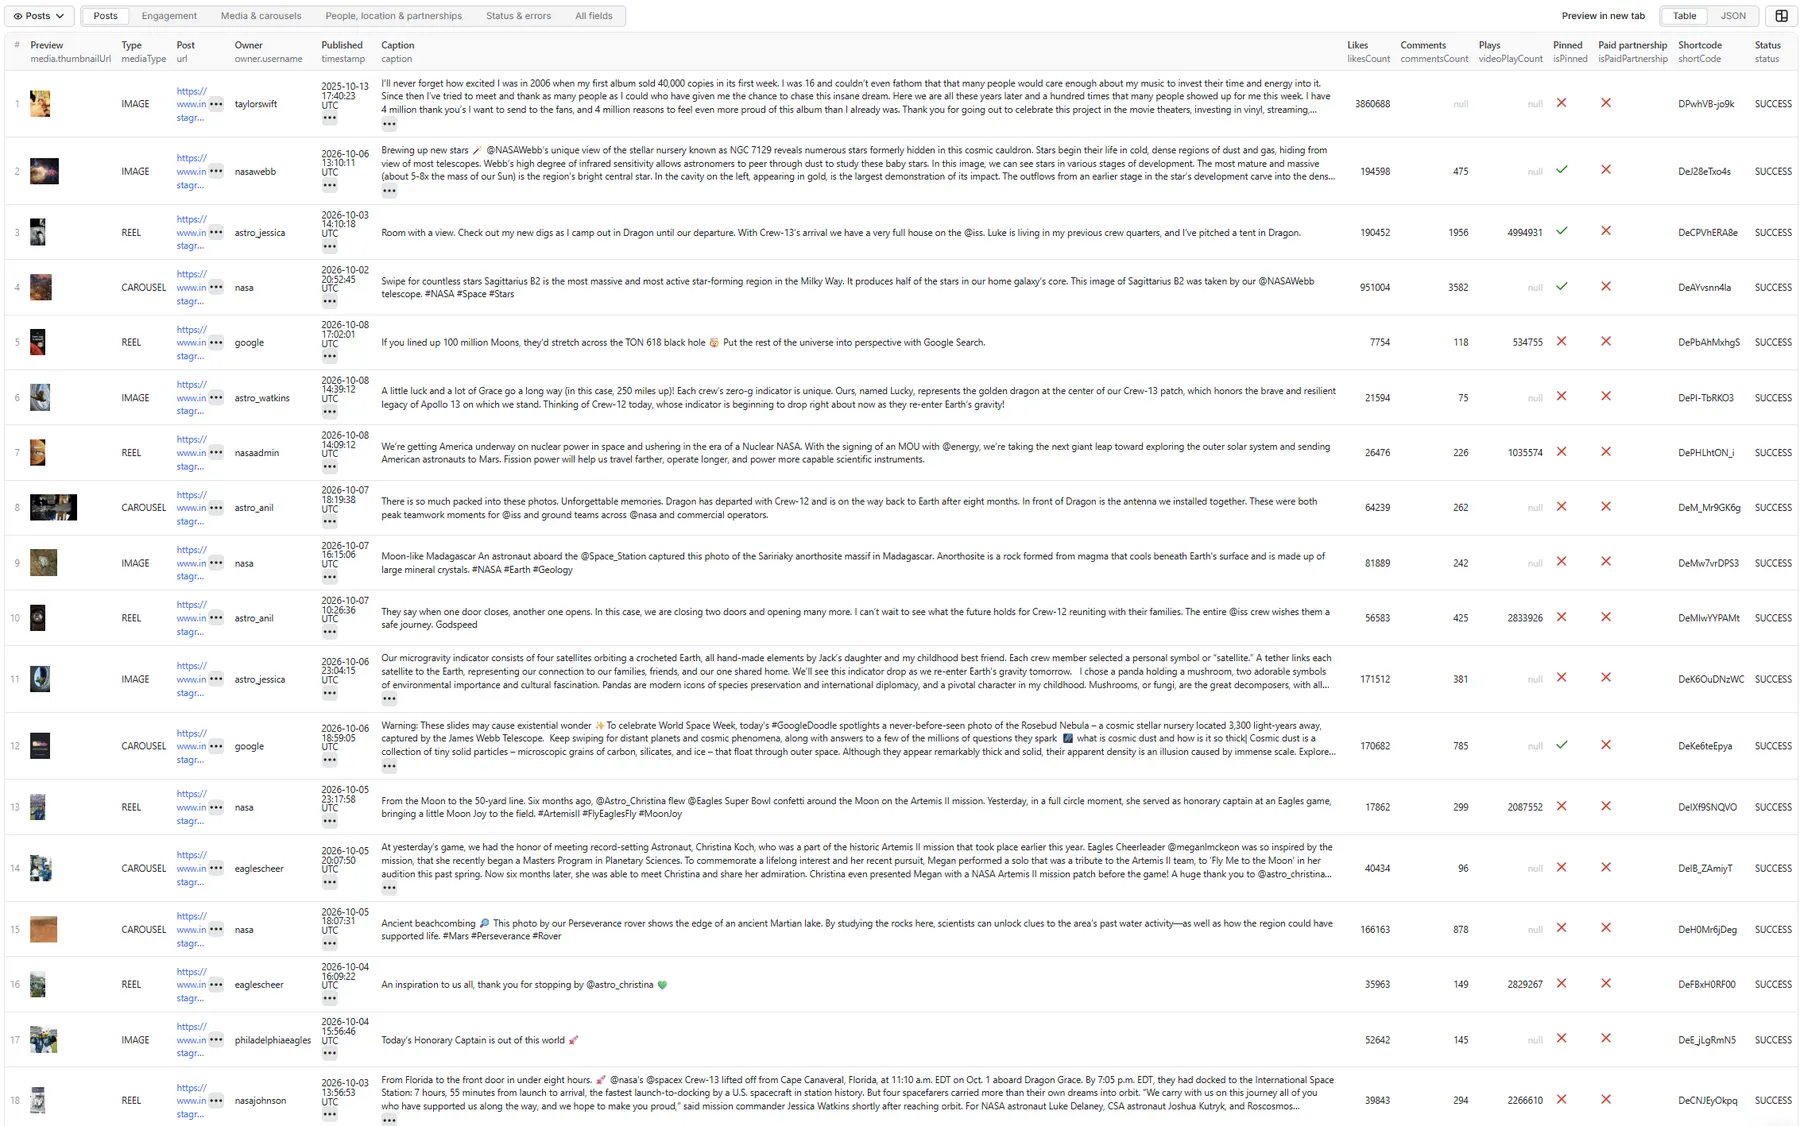
The records below come from a real run with this input (21 posts: 20 from nasa, 1 direct URL). Long Instagram CDN URLs are shortened with ….
Full record: a pinned carousel from a profile
Posts tab: a Reel
Engagement tab: the same Reel
videoViewCount and sharesCount are null here because Instagram didn't expose them for this Reel. When a post's likes are hidden, likesCount is null and likesHidden is true.
Media & carousels tab: the Reel's video
For a carousel, childPosts holds every slide (see the full record above).
People, location & partnerships tab: a collaboration post with a location
This post appeared in nasa's feed as a collaboration, but its author is astro_watkins. The row names the real author as owner, and nasa appears among the coauthors.
Status & errors tab: a direct post URL
Inputs that can't be served get an error row instead, with the same columns (type: "error", the status code in status, a human-readable errorMessage). Error rows are free. For example (illustrative):
Status values
| Status | Meaning | Charged |
|---|---|---|
SUCCESS | Post returned | ✅ |
PARTIAL_RESULT | A post missing core fields, or a profile whose feed stopped early (the posts already returned are kept) | — |
INVALID_INPUT | Not a recognizable Instagram username, URL or shortcode | — |
PROFILE_NOT_FOUND | The profile doesn't exist | — |
POST_NOT_FOUND | The post doesn't exist or was removed | — |
PRIVATE_PROFILE | The profile is private | — |
CONTENT_UNAVAILABLE | Instagram refused this content | — |
AGE_RESTRICTED | The content needs a logged-in, age-verified viewer | — |
LOGIN_WALL / RATE_LIMITED / BLOCKED | Instagram kept refusing after all retries and the fallback | — |
TEMPORARY_INSTAGRAM_ERROR / PROVIDER_ERROR | Upstream failure after all retries | — |
Run summary and retry input
Each run writes RUN_SUMMARY to the key-value store: input counts, posts saved by type (posts, Reels, carousels), duplicates skipped, posts filtered by date and by media type, and availability rates (hidden likes, Reel views, locations, collaborators). If any input failed for a temporary reason, RETRY_INPUT holds a ready-to-run input containing just those inputs.
Pricing
Pay per event, per returned post or Reel. One carousel is one result, whatever its slide count. You are not charged for carousel slides, profile lookups, pagination, retries, invalid inputs, duplicates, filtered-out posts, partial results or error rows. There is no start fee. The per-post rate can differ by Apify plan, so see the Pricing tab for the current rate on yours. This README deliberately doesn't quote figures.
The actor respects the spending limit you set for a run: when it's reached, the run stops cleanly and no further posts are fetched.
🚦 Proxy policy
Use Apify Datacenter proxy (the default) or no proxy for normal runs. Both work for Instagram profile feeds and post lookups at this actor's conservative concurrency.
Apify Residential proxy is not supported. The actor fails at startup if apifyProxyGroups includes RESIDENTIAL. In pay-per-event actors, residential bandwidth is billed per GB to the developer, not the run user, so a single bandwidth-heavy run could cost more than the per-result revenue.
If you need residential routing, supply your own residential provider in the proxy editor's Custom proxy URLs field. That traffic goes through your provider, not Apify, and is unaffected:
Limitations
- Public content only. Private accounts, Stories, Highlights and close-friends content are out of scope.
- Instagram decides what's public. Some counts (likes on hidden-like posts, views on some videos, shares) are simply not exposed and come back as
null. - Media URLs expire. Instagram's CDN links are temporary.
- Large exports take time. Instagram serves a feed 12 posts at a time, and the actor pages one profile sequentially to stay under rate limits.
- Filters have a scan limit. With date or media-type filters, a profile is scanned for up to 10×
resultsLimitposts (at least 240), then stops with what it found. A run also stops fallback work that keeps returning nothing billable, such as filters that match nothing or long lists of private or missing accounts. Affected profiles get a freePARTIAL_RESULTrow that says so. Narrow the filters or split the run if you hit this. - Not included: comment threads, likers, follower lists, hashtag or keyword search, media downloads into storage, and AI analysis. These belong to separate actors.
- Public data availability on Instagram can change at any time.
Related actors
- Instagram Profile Scraper: profile metadata, follower counts, bio links and public business contact
- Instagram Reel Hooks & Competitor Analyzer: what makes competitors' Reels work
- Instagram Comment Leads Extractor: commenters on posts as leads
- Instagram Creator Leads Scraper: find creators by niche
Legal and privacy
This is an unofficial tool. It is not affiliated with, endorsed by or sponsored by Instagram or Meta. It processes only publicly accessible content and never accesses private accounts. Public posts can contain personal data (names, faces, tagged people, locations). You are responsible for having a lawful basis for collecting and processing it (for example under GDPR or CCPA) and for complying with Instagram's terms in your use of the data.
Local development


