
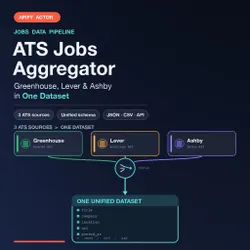
ATS Jobs Aggregator — Greenhouse, Lever & Ashby in One Dataset
Pricing
from $2.00 / 1,000 results
ATS Jobs Aggregator — Greenhouse, Lever & Ashby in One Dataset
Aggregate job postings from Greenhouse, Lever and Ashby ATS job boards into ONE normalized, deduplicated dataset. No login, no API key, no proxies needed — all three ATS expose public boards.
Pricing
from $2.00 / 1,000 results
Rating
0.0
(0)
Developer

Donglin Li
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 hours ago
Last modified
Categories
Features
Share
ATS Jobs Aggregator — Greenhouse, Lever & Ashby Jobs Scraper & API in One Dataset
Keywords: greenhouse jobs scraper · lever jobs API · ashby job board · ATS job listings · job postings API · hiring data · salary data · incremental job monitoring
Get job postings from Greenhouse, Lever and Ashby ATS job boards as one clean, deduplicated dataset — no login, no API key, no proxy setup.
If you track hiring signals, build lead lists, or monitor competitors' headcount, you already know the pain: every company uses a different ATS, every API returns a different shape, and you end up writing three scrapers and a merge script before you get a single usable table.
This Actor does that for you.
What you get
One row per job posting, normalized across all three ATS platforms:
| Field | Example |
|---|---|
ats | greenhouse |
company | Anthropic |
title | Account Executive, AI Native |
location | New York City, NY; San Francisco, CA |
department | Sales |
is_remote | true |
published_at | 2026-10-19T11:17:24-04:00 |
updated_at | 2026-11-08T09:12:00-05:00 |
url | https://job-boards.greenhouse.io/anthropic/jobs/5456619008 |
salary | $180,000 - $240,000 (when the ATS exposes it) |
Download as JSON, CSV, or Excel straight from the dataset tab.
Sample output
How to use it
companies— the company slugs from their careers page URL:boards.greenhouse.io/stripe→stripejobs.lever.co/spotify→spotifyjobs.ashbyhq.com/notion→notion
ats— pick which platforms to query (default: all three)sinceDays— optional. Set to1for a daily scheduled run and only pay for new or changed postings.
That last one matters: schedule this Actor every morning with sinceDays: 1 and you get a cheap daily diff of every company you track, instead of re-pulling everything.
Why this instead of three separate scrapers
- Cross-ATS deduplication built in. Companies migrate between ATS platforms and some run two at once. Duplicate postings are collapsed by company + title + location, so your counts stay honest.
- Normalized schema. Greenhouse returns
idas an integer and location aslocation.name; Lever returns a UUID and a nestedcategoriesobject; Ashby returns yet another shape. You get one schema. - No authentication. All three ATS expose public job boards. Nothing to configure, nothing to rotate.
- Failures are visible. Per-company/per-ATS errors are reported rather than silently dropping rows, so you know when a slug is wrong.
Why teams pick this over full-dataset vendors
- Real salary numbers: we regex-extract published ranges from job description bodies — 37.8% coverage vs 0% on the largest competitor's AI-enhanced fields (measured same-day).
- Incremental monitoring:
sinceDays+ cross-ATS fingerprint dedup means you can schedule daily runs and get only new or changed postings — "new-job alerts for my tracked companies", not a full re-download. - Honest coverage numbers: we publish measured field coverage instead of claiming completeness.
Typical use cases
- Hiring signal / growth tracking — count open roles per company per week to spot expansion or a freeze
- Lead generation — hiring for a specific stack often means budget; filter by department and stack keywords
- Competitive research — see which teams a competitor is staffing up
- Job board aggregation — feed your own board with fresh, deduplicated postings
Pricing
Pay per job posting returned. Duplicates and out-of-range postings (when using sinceDays) are not billed.
Field coverage (measured on 3,453 postings from 9 companies, Nov 2026 — refreshed daily)
We publish real numbers rather than claiming "complete data":
| Field | Filled | Notes |
|---|---|---|
ats, company, job_id, title, location, url | 100% | always present |
department | 100% | from ATS taxonomy, falls back to company metadata |
published_at, updated_at | 99.9% | drives incremental sinceDays mode |
is_remote | ~49% | inferred from ATS field, title, or location text |
salary | ~38% | extracted from job description text where the employer publishes a range (e.g. Anthropic: 77% of postings) |
employment_type | 96.5% | normalized to a fixed enum (Full-time / Internship / Contract / Part-time / Fellowship / Apprenticeship) via two-stage inference |
Employment type is normalized rather than passed through, because each ATS uses different labels (FullTime, Full-time, Permanent, Intern, Internship). Two-stage inference: special types (Intern / Contract / Part-time) are detected from title and description text first; standard roles (engineer, manager, analyst, director…) default to Full-time. You get one consistent enum you can filter on.
Salary is genuinely hard: most ATS boards simply don't have a salary field, so this Actor scans the job description body for phrases like "salary range is $X–$Y" (with $, USD, k, per year/hour variants). Where a company publishes pay ranges, coverage is much higher — e.g. Anthropic: 77% of postings carry a salary range.
If a field matters to your workflow and you need higher coverage, open an issue and tell us which companies you track.
Notes and limits
- Some companies use more than one ATS but not all three — an ATS returning 404 for a slug is expected, not an error (18 of 27 company/ATS combinations in our test).
- Very large boards (e.g. Anthropic with full descriptions, ~10 MB) are read in streamed chunks; the Actor degrades gracefully rather than failing outright.
- Respect each platform's terms and your local regulations when using this data.
Support
Something broken or a company slug missing? Open an issue on the Actor page — response time is tracked publicly, and legitimate data-source changes get fixed fast.


