
Rotten Tomatoes Scraper - Tomatometer & Audience Score Data
Pricing
from $4.45 / 1,000 titles
Rotten Tomatoes Scraper - Tomatometer & Audience Score Data
Rotten Tomatoes scraper for movie and TV ratings, by title or URL. Each row holds the Tomatometer and Popcornmeter with review counts and averages, the critics consensus, cast and crew, genres, runtime, release dates, US box office and poster. A single season works too. $4.60 per 1,000 titles.
Pricing
from $4.45 / 1,000 titles
Rating
0.0
(0)
Developer
Dami's Studio
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
a day ago
Last modified
Categories
Share
Rotten Tomatoes scraper for film and TV titles or Rotten Tomatoes URLs, one row per title: the Tomatometer and the Popcornmeter with their review counts, average ratings and fresh-rotten splits, the critics consensus, genres, age rating, runtime, release dates, US box office, cast and crew, the poster and the site's own ids.
The critic review texts are not in there. You get the scores, the counts and the consensus, plus a link to the reviews pages if you want to read them yourself.
| Input | Film or TV titles, or Rotten Tomatoes URLs |
| Output | One row per title: both scores with counts and averages, consensus, genres, rating, runtime, dates, US box office, credits, poster, ids |
| Ceiling | 10,000 titles per run |
| Account needed | None, and no API key |
| Price | $4.60 per 1,000 titles on the Free plan, a little less on paid plans. The free plan's $5 a month covers about 1,000 |
| Using an AI agent? | |
|---|---|
| Actor | dami_studio/rotten-tomatoes-scraper |
| Set one field | searchQueries, labelled "Titles to look up" in the Console |
| Cap the bill | maxTotalChargeUsd on the run, for example 0.10: it never charges past that |
| MCP, one link | https://mcp.apify.com/?tools=fetch-actor-details,dami_studio/rotten-tomatoes-scraper |
| How often | Weekly, or daily in a film's first weeks |
🔍 What Rotten Tomatoes Scraper does
Give it titles and it searches the site the way its own search box does, then reads the page it lands on. Give it URLs and it reads exactly those. You can do both in one run, and a title that turns up in both is read once.
Titles are the safer input, not slugs. Rotten Tomatoes puts a year in the slug when something
has been remade, and not where you would guess. /m/cats is not the 2019 musical, which lives at
/m/cats_2019. /m/oppenheimer is not the Nolan film, which is /m/oppenheimer_2023. Casablanca
sits at /m/1003707-casablanca. Searching oppenheimer lands on the right one.
Search has the opposite trap. breaking bad on the default setting comes back as El Camino: A
Breaking Bad Movie, because the film outranks the series in the site's own relevance. Set
Movies, TV, or both to TV when you mean the show, or paste /tv/breaking_bad.
📋 What data you get from each Rotten Tomatoes title
| What you get | Field |
|---|---|
| Tomatometer, its sentiment and Certified Fresh flag | tomatometer, tomatometerSentiment, tomatometerCertifiedFresh |
| Critic average, review count and fresh-rotten split | criticsAverageRating, criticReviewCount, criticsFreshCount, criticsRottenCount |
| Top critics' score and count | topCriticsScore, topCriticsReviewCount |
| Popcornmeter, audience average, counts and liked split | audienceScore, audienceAverageRating, audienceReviewCount, audienceRatingCountText, audienceLikedCount, audienceNotLikedCount |
Whether the Popcornmeter carries its certified badge, and which audience it counts (VERIFIED or ALL) | audienceCertified, audienceScoreType |
| The critics consensus and the synopsis | criticsConsensus, synopsis |
| Genres, age rating, language and runtime | genres, contentRating, originalLanguage, runtime, runtimeMinutes |
| Release, rerelease, streaming and air dates, US box office, as the site writes them | releaseDateTheaters, rereleaseDateTheaters, releaseDateStreaming, airDate, boxOfficeGrossUsa |
The same dates as YYYY-MM-DD and box office as a number of dollars | releaseDateTheatersIso, releaseDateStreamingIso, boxOfficeGrossUsaUsd |
| The release line in the page header, like "In Theaters Dec 18" or "Now Playing" | releaseStatusText |
| Directors, writers, producers, creators, distributor, studios | directors, writers, producers, creators, distributor, productionCompanies |
| Sound mix and aspect ratio | soundMix, aspectRatio |
| Actor names, as a plain list | cast |
| The top of the credits, with profile links | castAndCrew |
| Optional: the people on the title's Cast & Crew page, with credit, character and profile link | fullCastAndCrew |
| Movie or TV, and the show's name on a season row | isMovie, seriesTitle |
| TV only: network and seasons | network, numberOfSeasons, seasons |
| Poster, review page links and the site's ids | posterUrl, criticReviewsUrl, audienceReviewsUrl, emsId, rtId |
▶️ How to scrape Rotten Tomatoes
- Open Rotten Tomatoes Scraper and click Try for free.
- Put titles into Titles to look up, one per line, or paste links into Rotten Tomatoes URLs.
- Set Movies, TV, or both if a title is ambiguous.
- Set Maximum titles, then click Start.
- Download the dataset as JSON, CSV or Excel, or read it from the Apify API.
Run it with no titles and no URLs and you get one labelled sample row, which is not charged.
💰 How much does it cost to scrape Rotten Tomatoes?
$4.60 per 1,000 titles on the Free plan. Paid plans pay a little less: $4.55 on Starter, $4.50 on Scale and $4.45 on Business. On the free plan, the $5 Apify gives you each month covers about 1,000 titles.
You pay per title row delivered, and with Add a row for each season on, each season row is a title row. Reading the Cast & Crew page costs nothing extra. Diagnostic rows, a title the site has no match for, a page with no scores yet, a duplicate across your two input fields, and the sample row are not charged. Set a maximum cost on the run and it stops when it gets there.
📥 What you give it
Or by URL:
| Field | Default | What it is |
|---|---|---|
searchQueries | none, the form starts with dune part two and severance | One title per line. Add the year when a title has been remade: "cats 2019" lands right, "cats" may not. |
startUrls | none | Film pages, TV series pages or a single season like /tv/severance/s02. A /reviews or /cast-and-crew link is trimmed back to the title page, and a bare /m/anora works. |
mediaType | any | any, movies or tv. It steers the search only. Pasted URLs are read as given. |
resultsPerQuery | 1 | Search matches to read per line, up to 20. Raise it when a term is genuinely ambiguous and you want the alternatives too. |
maxItems | 50 | Rows for the whole run, across every search term and URL, season rows included, up to 10,000. |
expandSeasons | false | Turn it on and each TV series also gives one row per season, read from that season's own page. The series row stays. Each season row is charged as a title. A season you also pasted is read once. |
fullCredits | false | Turn it on to also read each title's Cast & Crew page into fullCastAndCrew. One more page per title and no extra charge. If that page can't be read, the title still comes back, with fullCastAndCrew: null. |
proxyConfiguration | none | Optional, and not needed for a normal run. |
📤 What you get back
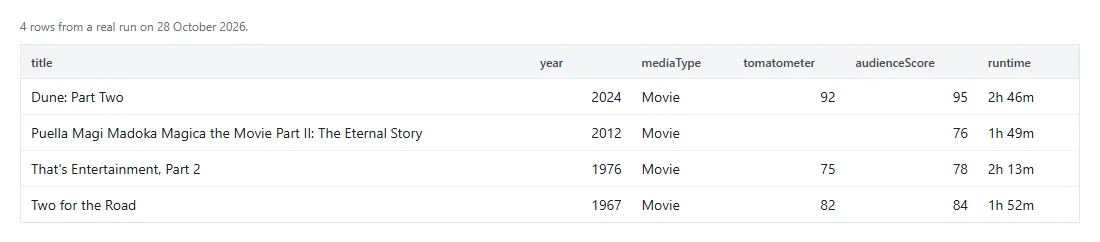
A real row from 17 October 2026, with the synopsis, the producer list, the credits and the poster URL cut short:
With Read the Cast & Crew page on, the row ends with one more field, one entry per person:
| Field | How to read it |
|---|---|
tomatometer, audienceScore | The two percentages. criticsAverageRating is out of 10 and audienceAverageRating out of 5, which is how the site keeps them. |
castAndCrew | The half-dozen people the title page puts in its Cast & Crew strip, each with a profile link. Not the full ensemble. |
cast | Actor names only, top-billed first. Directors, writers and producers are never in it. |
fullCastAndCrew | Only there when you turn on Read the Cast & Crew page. role is the credit, character is filled for cast, and isCast / isCrew say which tab the site files the person under. null when that page could not be read. |
directors, writers, producers, creators, distributor, productionCompanies | Complete, because they come from the page's own credits table. |
releaseDateTheaters, boxOfficeGrossUsa | As the site writes them: "Mar 1, 2024, Wide", "$282.0M". Box office is US gross only. |
releaseDateTheatersIso, releaseDateStreamingIso, boxOfficeGrossUsaUsd | The same values as "2024-03-01" and 282000000. null when the site's text is not a whole date or a dollar figure, so "Dec 2026" stays text only. |
releaseStatusText | Only when the page header shows a release line, like "In Theaters Dec 18". null on most released titles. |
audienceScoreType | VERIFIED when the Popcornmeter on the row is the site's verified-audience score, ALL when it is the all-audience one. |
seasons, numberOfSeasons, network | TV rows. seasons is a list of links. Turn on Add a row for each season to get a row for each of them. |
searchQuery, position | Which of your lines found this row and where it ranked, so you can join back to your list. |
TV series pages carry an averaged score and no consensus. That is how the site presents them.
Ask for one season, /tv/severance/s02, and you get a real Tomatometer, a real review count and that
season's consensus. Or turn on Add a row for each season and get the series row plus one per season.
🧾 Reading the output
| Row | How to spot it | Billed |
|---|---|---|
| A title | _sample and _diagnostic both absent | yes |
| The sample row | _sample: true | no |
| A diagnostic | _diagnostic: true and an errorCode | no |
Every diagnostic row carries a hint alongside its code.
| Code | What it means |
|---|---|
NO_MATCH | The search found nothing for that term. Try the title as the site writes it, and add the year for a remake. |
NOT_FOUND | The URL is a 404. Usually the slug: a remade title carries its year. |
BAD_URL | Not a Rotten Tomatoes film or TV address. |
NOT_A_TITLE_PAGE | The link redirected to a list or a franchise hub rather than a title. |
NOT_SCORED_YET | The page exists but has no Tomatometer or Popcornmeter yet. Unreleased titles and stub pages look like this. |
SEARCH_FAILED | The site search was unreachable for that term. Re-running usually clears it. |
NOT_SERVED | This request was not served this run. Re-run it later. Runs before 13 October 2026 wrote BLOCKED here. |
PARSE_FAILED | The page came back in a shape this could not read. Worth reporting. |
TIME_LIMIT | The run reached its time limit before it finished. The titles before it are delivered and charged, and titlesDelivered says how many. Give the run more time to get the rest. |
UNEXPECTED_ERROR | The run stopped early on an unexpected error. The results before this row are kept. |
One bad title never stops the rest, and a diagnostic row never fails the run, TIME_LIMIT included: a run the time limit stopped before any title came back still ends as succeeded, with an amber status message.
💡 What people use it for
- Running a watchlist weekly and diffing on
tomatometerandcriticReviewCountto watch a score settle after release. - Pulling scores for a catalogue of titles to sit beside your own data.
- Comparing the critic score against the audience score across a genre or a studio.
- Checking a season at a time on a returning series, rather than the averaged series score.
🚧 What it does not do
- No individual critic reviews. Scores, counts, the split and the consensus, yes. The quotes
from each named critic, no.
criticReviewsUrlandaudienceReviewsUrlpoint at those pages. castAndCrewis the top of the credits. A 60-name ensemble is not in there unless you turn on Read the Cast & Crew page, and even then you get what that page lists.- TV series pages have an averaged score and no consensus. Ask for a season instead.
- Some titles simply have no scores, and come back as an uncharged
NOT_SCORED_YETrow rather than a row full of nulls. - Box office is US gross, and missing on most TV and on anything without a wide US release.
- Search is a search, not an exact-match lookup. One line in, the best match out. Use the URL when you need a guarantee.
- No episodes, showtimes or streaming prices. Seasons come back as rows only when you turn on Add a row for each season.
- It is not an official Rotten Tomatoes tool. Dami's Studio is independent and is not affiliated with or endorsed by Rotten Tomatoes, or by any other company named on this page.
🧭 Which film, TV, music or game scraper do you need?
| If you want | Use |
|---|---|
| IMDb IDs for films, shows and people | IMDb Search Scraper |
| Critic and audience scores for a film or show | This one |
| TV shows, full episode lists and main cast | TV Show Scraper |
| Artists, releases, recordings and labels, with their MBIDs | MusicBrainz Scraper |
| Steam games, store details and player reviews | Steam Scraper |
| Goodreads ratings and rating counts for books | Goodreads Books Scraper |
| Wikidata Q-ids and claims for the same people and works | Wikidata Scraper |
❓ Questions people ask
Is there an official Rotten Tomatoes API?
Not one you can sign up for: Rotten Tomatoes reviews each request for its APIs and data feeds through a business proposal form. This reads the public title pages and needs nothing from you but the titles.
Do I need a login?
No. No account, no cookie, no key.
How do I look up one season rather than the whole show?
Paste the season link, like https://www.rottentomatoes.com/tv/the_last_of_us/s01. Searching the
show name gives you the series page and its averaged score. Turn on Add a row for each season
and the same search gives you the series and each of its seasons.
How do I get a Rotten Tomatoes dataset as a CSV?
Run it on your titles and download the results as CSV or Excel with the run's Export button. It holds today's scores, not a frozen file, up to 10,000 titles a run.
Why does the score differ from the one on the site?
Scores and counts keep moving as reviews come in, most of all in the weeks after a release. A row is
a snapshot; scrapedAt says when it was taken.
Can I call it from code or connect it to an AI assistant?
The API tab has code for Python, JavaScript and
the CLI. MCP clients like Claude and ChatGPT use
https://mcp.apify.com/?tools=fetch-actor-details,dami_studio/rotten-tomatoes-scraper; coding assistants can load
our skill
file.
All three bill your Apify account at the same price.
Is scraping Rotten Tomatoes legal?
These are public title pages. The site's terms govern what you may do with the content, so read them against your plan. Apify's write-up on the legality of web scraping is a good starting point, and we are not lawyers.
🆘 If something breaks
Open the Issues tab on the actor page. Send the run ID and the titles or URLs you used. The
errorCode on the diagnostic row usually names the problem on its own.


