
Broken Link & Image Checker - Sitemap or Crawl
Pricing
$0.89 / 1,000 checked urls
Broken Link & Image Checker - Sitemap or Crawl
Find broken links and images on your site: crawl pages or read a sitemap.xml, check every link, image and srcset once, and get the status, redirects and the pages each one is on. $0.00089 per URL checked; crawled pages and robots-skipped URLs free. Respects robots.txt.
Pricing
$0.89 / 1,000 checked urls
Rating
0.0
(0)
Developer
DigiVibeTech
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Features
Share
Broken Link & Image Checker — find broken links and images on your site: crawl pages or read a sitemap.xml, check every link, image and srcset once, and get the status, redirects and the pages each one is on.
Try it free: press Start — the prefilled input runs a small real job (up to 20 × checked url, about $0.018 in events). Apify's free plan includes monthly platform credit, so a first test costs you nothing. You can also set a maximum cost per run.
- What you get:
state,status,type,url,redirectedTo,error - Who it's for: site owners, SEO teams and web shops
- Price: $0.00089 per checked url
- Data source: Checks the public pages of sites you enter or own, respects robots.txt and never logs in.
What is Broken Link & Image Checker?
Find broken links and broken images on your website in one run. Start from a page (the actor crawls internal links) or from your sitemap.xml. Every unique link and image is checked once, and you get its HTTP status, where it redirects, and the pages it appears on, so you know exactly what to fix.
Built for shop owners, SEOs and developers: after a catalog update, a migration or a theme change, catch 404 product pages, deleted product photos, broken srcset variants and dead outbound links before customers or Google do.
✅ Why this one
- Checks links and images: img tags, data-src, every srcset candidate, picture sources and og:image / twitter:image, not only anchor href links.
- Every broken URL lists the pages it was found on (up to 10) and a found-on count, so you know exactly what to fix.
- $0.00089 per checked URL with no start fee, against $0.001 per link plus a start fee at the most-used rival (checked 27 Oct 2026). Scanning pages and robots-skipped URLs are free.
- Start from a page or from sitemap.xml, with a maximum cost per run.
Speed and the run timeout
To stay polite, each site gets about one request per second. Pages are scanned first, then every found URL is checked (up to 16 at a time, but still about 1 per second per host). Rough guide with the default 1-hour timeout:
- 20 pages (the default) take about 20-30 seconds to scan.
- 1,000 URLs on your own site (the default limit) take about 17 minutes; links to other hosts are checked in parallel.
- Large sites (thousands of pages or URLs) need a longer timeout, or several runs with lower limits.
The actor watches its own timeout. Shortly before it (10 % of the run time, at least 30 seconds), it stops, keeps every result found so far, and finishes as Succeeded. Page scanning uses at most half of the time, so links always get checked. SUMMARY then has stoppedEarly: true, pagesLeft (pages not scanned) and urlsLeft (found URLs not checked, not charged). Raise the timeout or lower maxPages / maxUrlsToCheck to finish the rest.
📸 Real-run screenshots
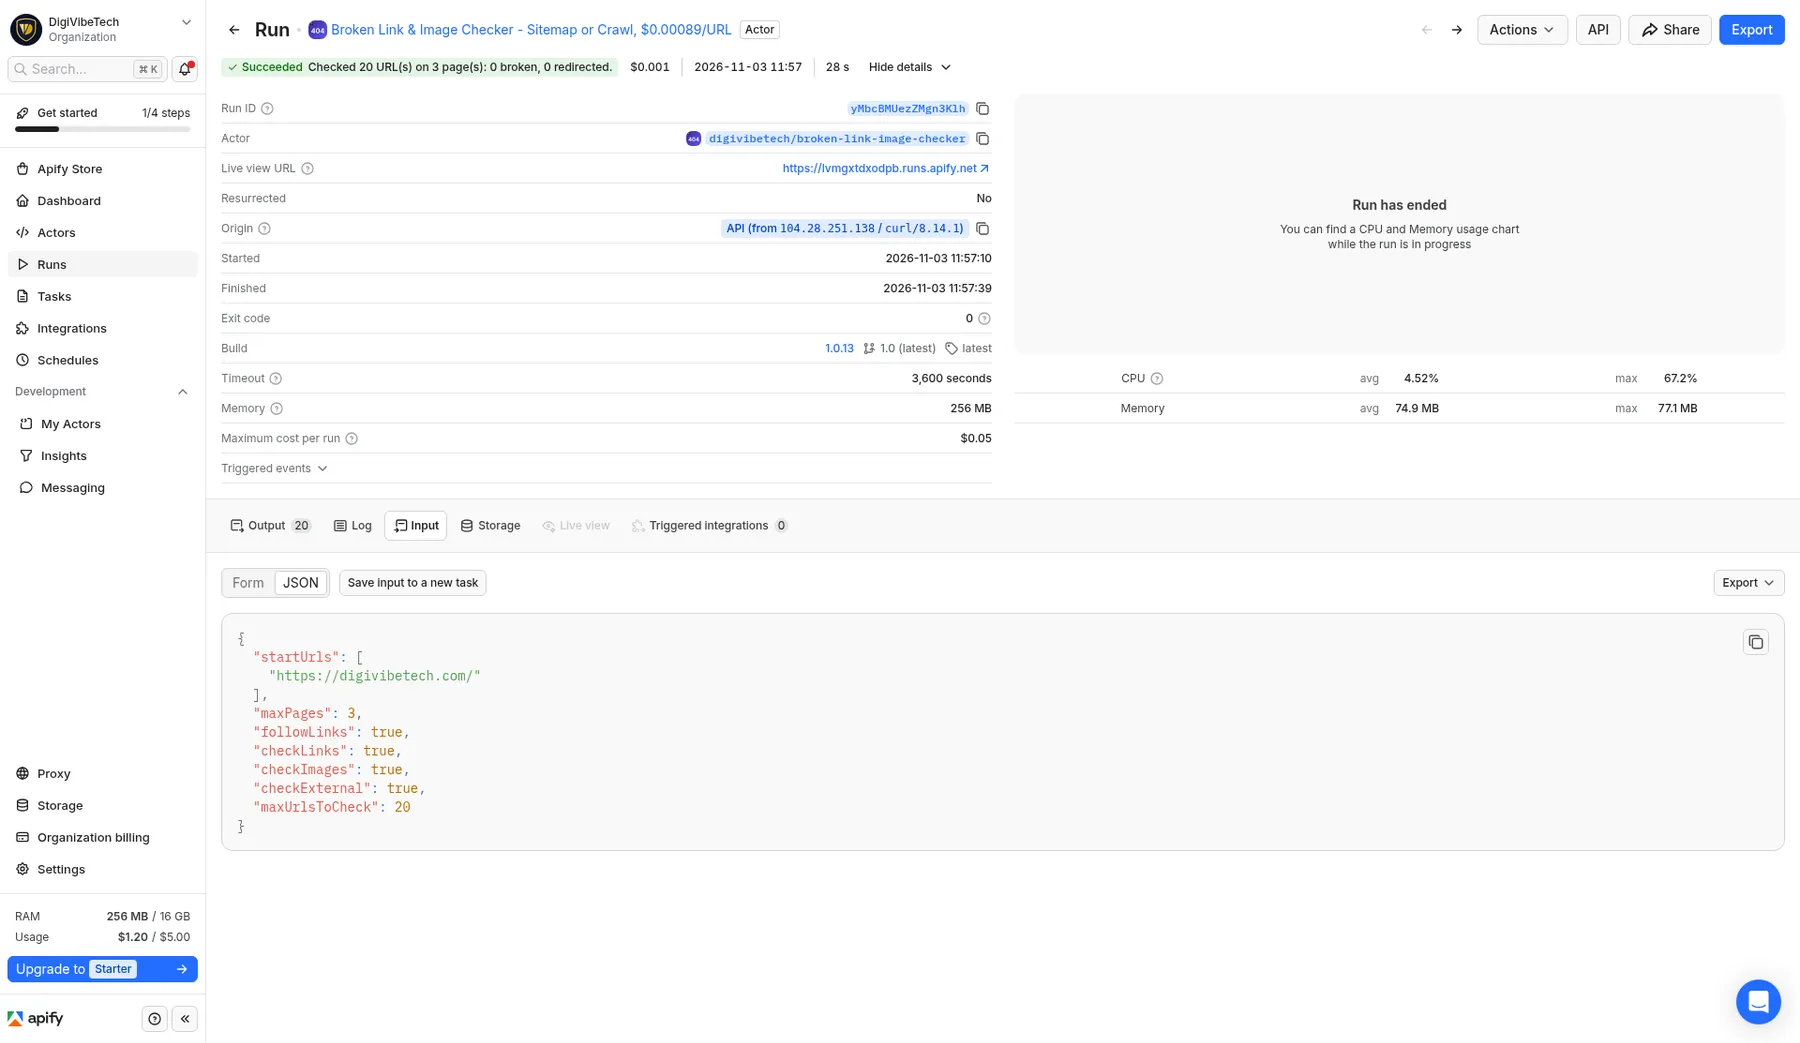
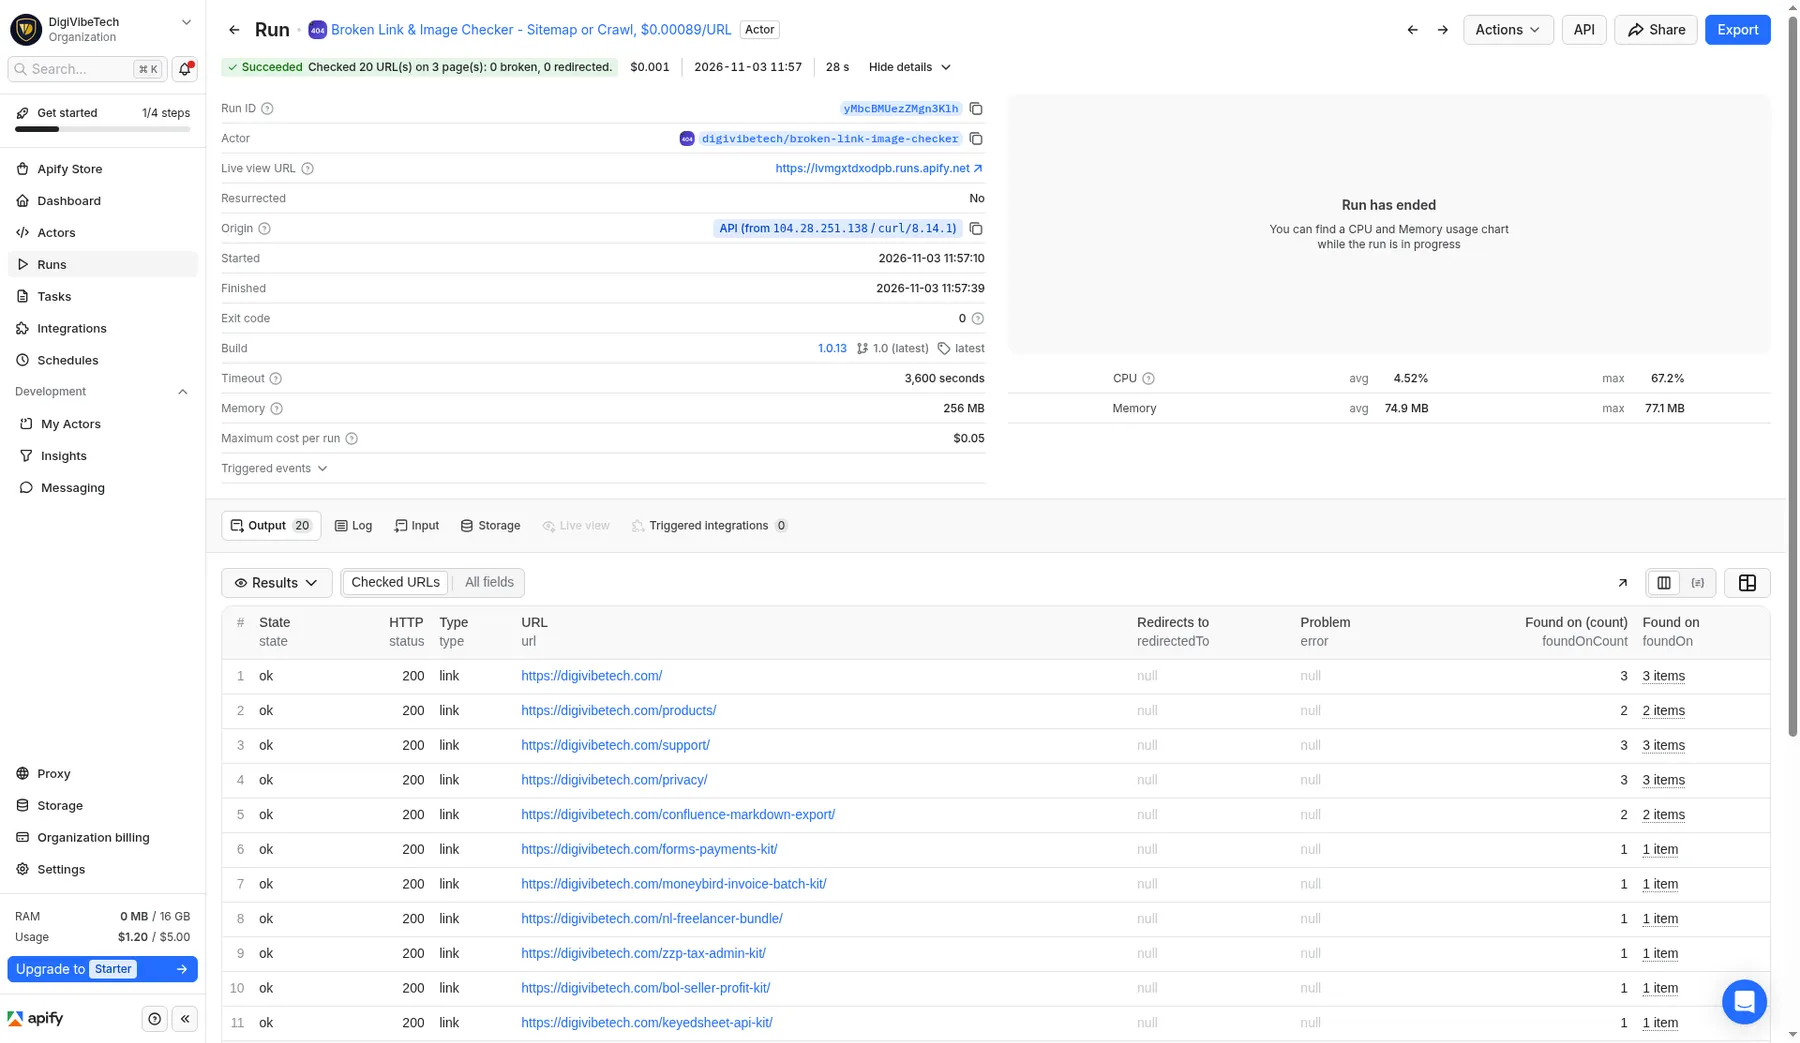
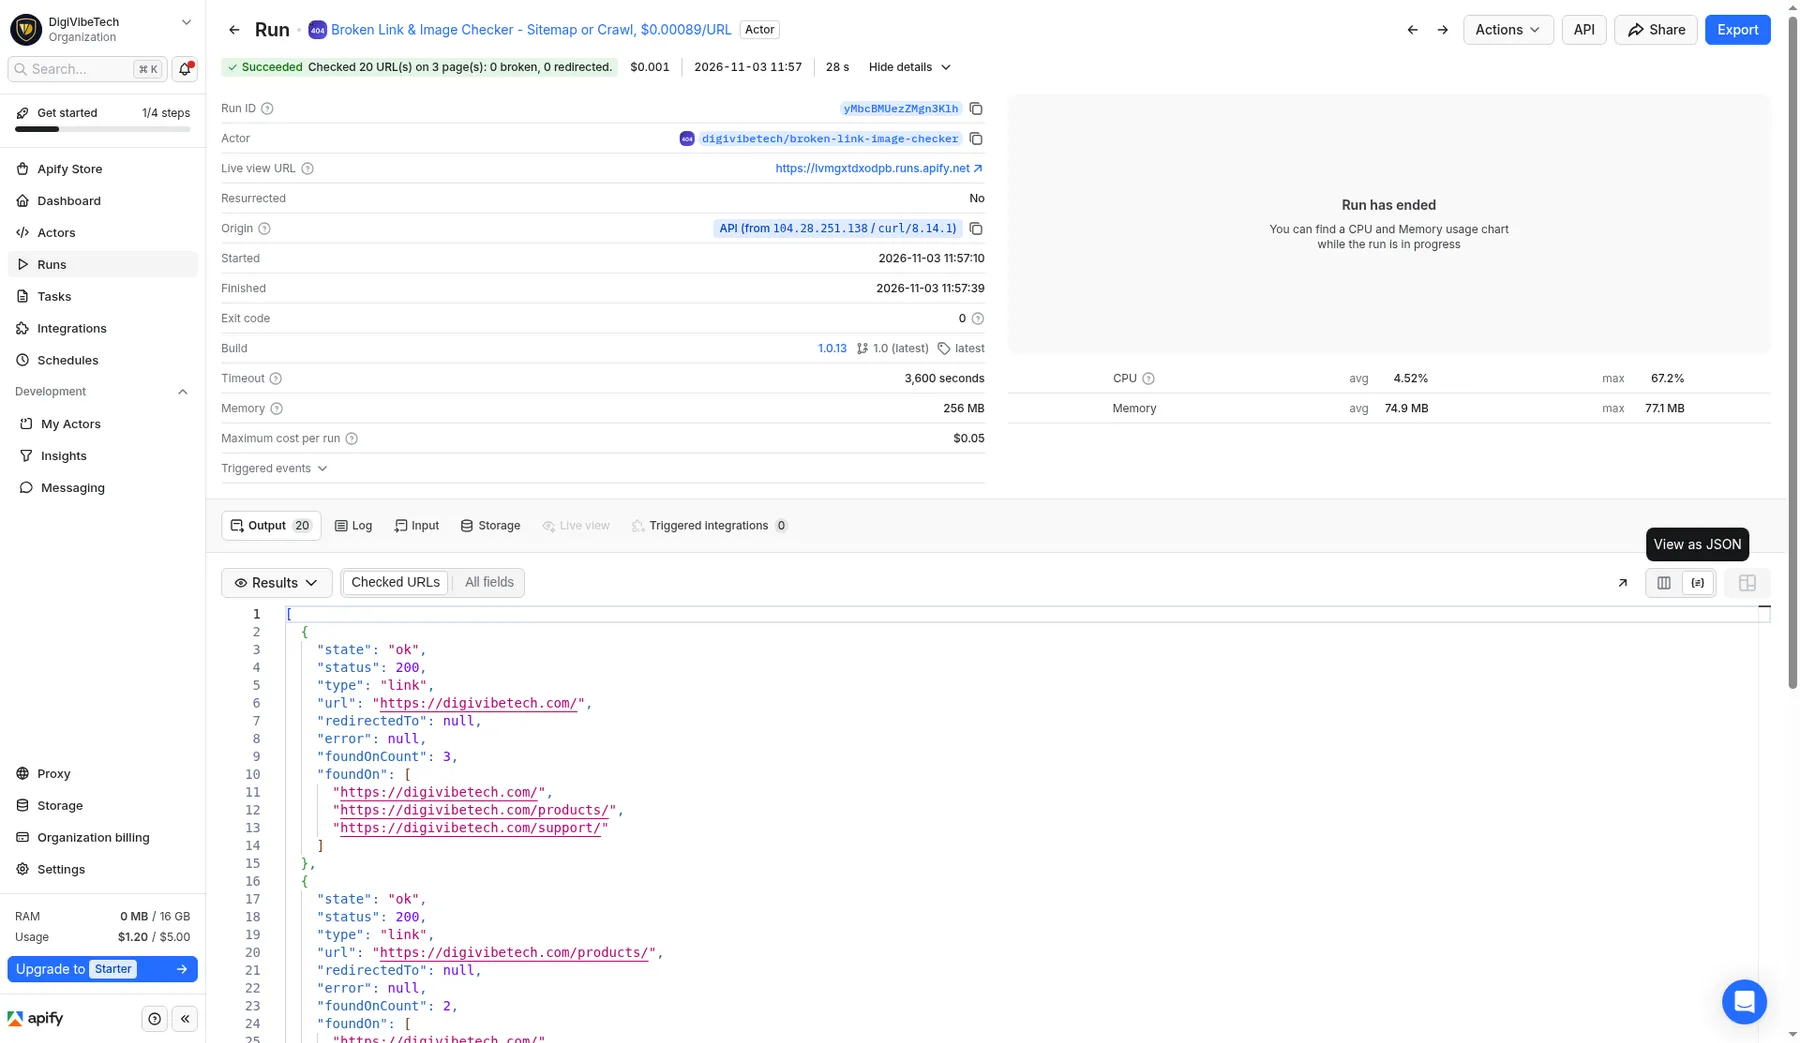
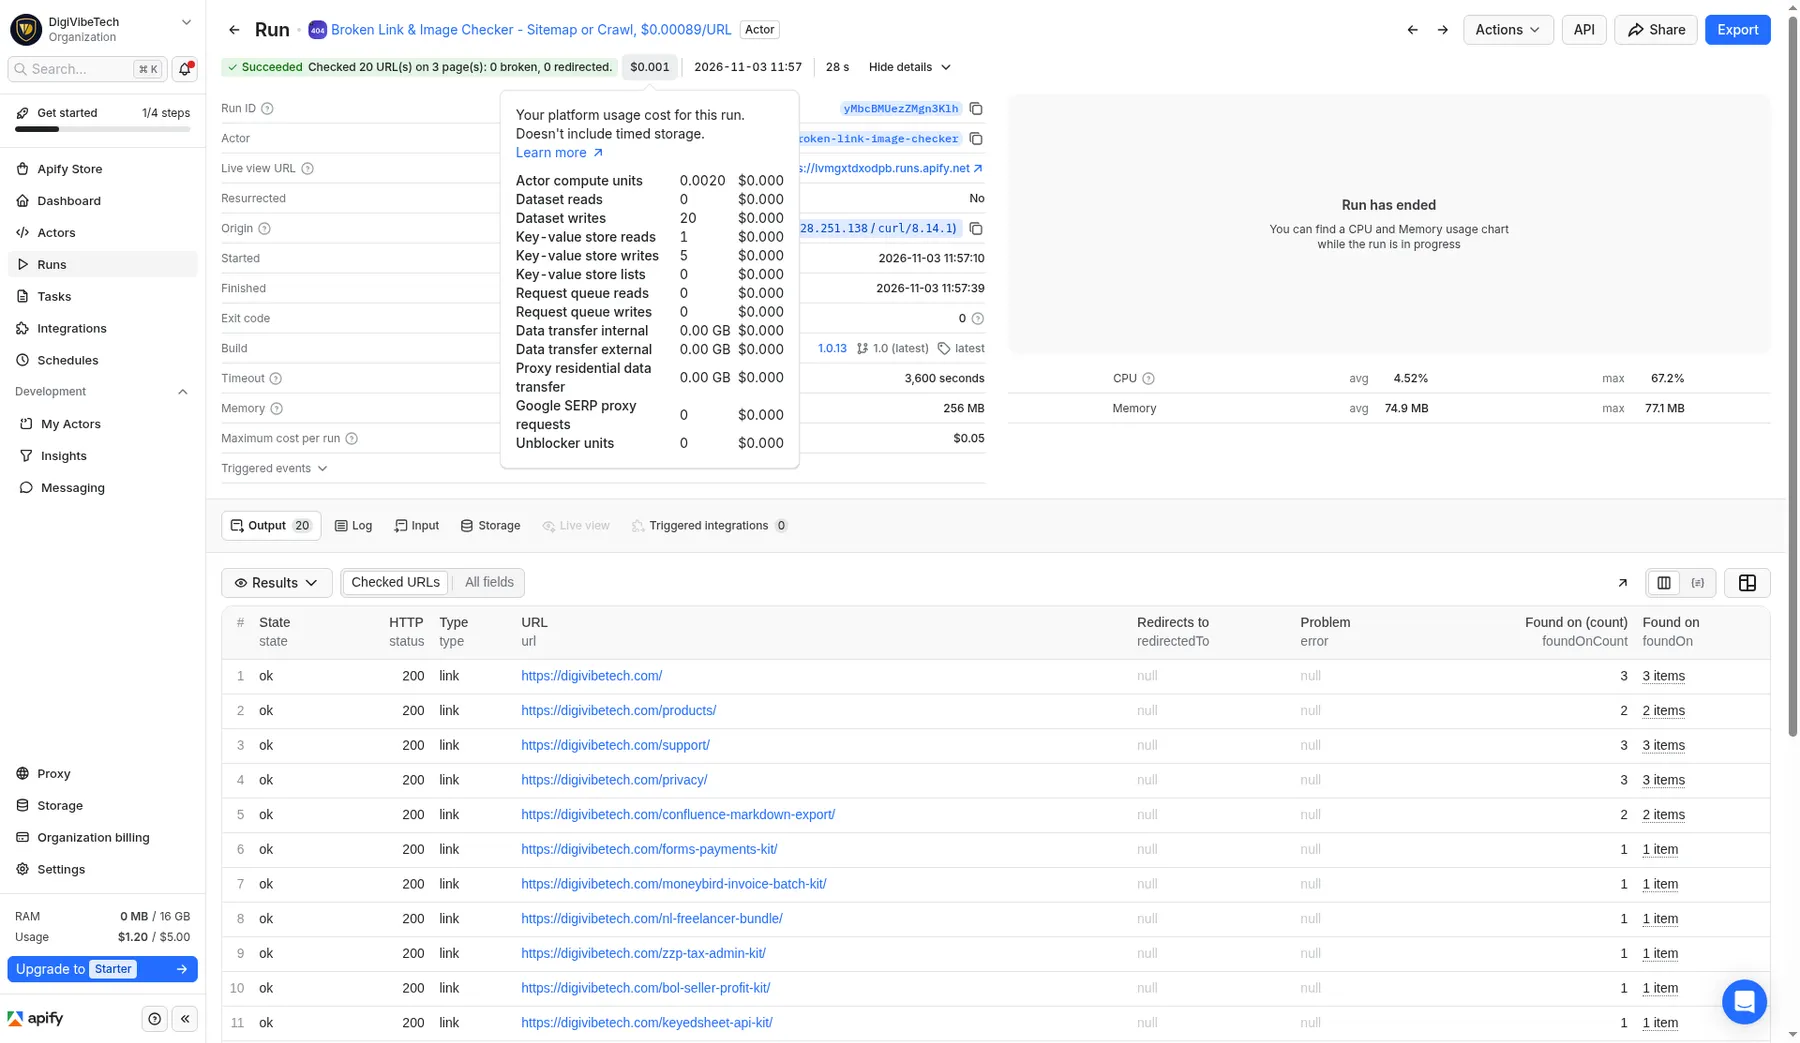
From a real run on 3 Nov 2026 (Europe/Amsterdam) checking digivibetech.com: 3 pages scanned, 27 URLs found, 20 checked (cap), all 20 OK, 0 broken.
⬇️ What data you get
- Links: every
<a href>(internal, and optionally external) - Images:
<img src>,data-src, everysrcsetcandidate,<picture><source>andog:image/twitter:image - States:
ok(2xx),redirect(3xx or redirected to another URL),broken(4xx/5xx, or an image URL that does not return an image) andunreachable(DNS, timeout, TLS) - Where:
foundOn(up to 10 pages) andfoundOnCountfor each URL
🎯 Use cases
- Find 404 links and broken product images before customers do
- Check a sitemap after a migration or redesign
- Run a scheduled weekly link check and alert on new breaks
▶️ How to use
- Open the actor; the input is prefilled with a small real example.
- Replace it with your own input and set
maxPagesto control the cost. - Press Start. Results appear in the Output tab (Overview view).
- Download JSON, CSV or Excel, call the results via API, or schedule the actor.
⚙️ Input
| Field | Default | Meaning |
|---|---|---|
startUrls | (required) | Pages or sitemap.xml / sitemap index URLs |
maxPages | 20 | HTML pages scanned per start URL (scanning is free) |
followLinks | true | Crawl internal links on the same host |
checkLinks / checkImages | true | What to check |
checkExternal | true | Also check other hosts (image CDNs, outbound links) |
maxUrlsToCheck | 1000 | Limit on checked (charged) URLs |
Example input
⬆️ Output
One dataset item per checked URL: url, type (link/image), status, state, ok, redirectedTo, contentType, error, external, foundOn, foundOnCount.
The BROKEN record in the key-value store lists only the problems. SUMMARY (also saved as OUTPUT) has the counts. ERRORS lists pages that could not be scanned and URLs skipped by robots.txt.
Example output (one record)
Real record from a test run on the input above.
💵 Pricing and cost estimate
| Event | Price |
|---|---|
| URL checked (link or image status determined) | $0.00089 |
Scanning pages is free, robots-skipped URLs are free, and there is no start fee. A shop with 300 unique links and images costs $0.27. Set a maximum cost per run and the actor stops checking before it is reached.
Cost estimate
| Checked urls | Cost |
|---|---|
| 100 | $0.089 |
| 1,000 | $0.89 |
| 10,000 | $8.90 |
You pay only for these events: no subscription.
🔌 Integrations and API
Run it from n8n, Make, Zapier, Clay or any tool that can call an HTTP endpoint, connect a webhook to get notified when a run finishes, or let AI agents call it through the Apify MCP server (mcp.apify.com).
Run it and get the results in one call:
Python (pip install apify-client):
Use it in n8n, Make or Zapier
Schedule a weekly run, then read the BROKEN record (/key-value-stores/{id}/records/BROKEN) and send it to Slack or email when it is not empty.
⚠️ Limits
- It reads the HTML the server sends (no browser), so text, links or markup added later by JavaScript are not seen.
- Sites that block automated requests or rate-limit hard can show up as
brokenorerroreven if a browser loads them. - Pages disallowed by robots.txt are not crawled, so links found only there are not checked.
🛡️ Data source, privacy and legality
Checks the public pages of sites you enter or own, respects robots.txt and never logs in.
Responsible crawling
We follow each site's robots.txt for every page and every checked URL (disallowed URLs are skipped and not charged), send at most about one request per second per host, check with HEAD first (a small GET of at most 1 KB only if the server does not support HEAD), use an honest User-Agent (LinkImageChecker/1.0) and never log in, use proxies or bypass bot protection. Check sites you own or are allowed to check.
❓ FAQ
How much does Broken Link & Image Checker cost?
$0.00089 per checked url. See the cost estimate table above. There is no monthly fee.
Can I try it for free?
Yes. Press Start with the prefilled input: it runs a small real job (up to 20 × checked url, about $0.018 in events). Apify's free plan includes monthly platform credit, which covers a first test.
Is it legal to use Broken Link & Image Checker?
Checks the public pages of sites you enter or own, respects robots.txt and never logs in. Use the results lawfully (terms of the source, GDPR where it applies). This is not legal advice.
Can I use it through the API or an MCP server?
Yes. Every run is available through the Apify API and the official client libraries, and AI agents can call the actor through the Apify MCP server. See Integrations and API above.
Something does not work. Where do I get help?
Open an issue on the Issues tab or use digivibetech.com/support. Include the run ID so we can reproduce it.
📝 Changelog
20 Nov 2026 — listing refresh
- README, listing text and input form restructured to the DigiVibeTech Apify quality standard v1. No feature or price change.
1.0 — builds 1.0.1 to 1.0.14
- First build 2026-10-14, latest build 2026-11-03 (14 successful builds).
🧩 More DigiVibeTech actors
- Shop SEO & Product Schema Audit - Merchant-Ready Check
- Website SEO & AI Search Audit (GEO/AEO)
- Bulk WHOIS & DNS Lookup - Domain Expiry, RDAP, SPF, DMARC
- Redirect Chain & Migration Map Checker
Maintained by DigiVibeTech. Questions or bugs: use the Issues tab or digivibetech.com/support; we reply within 2–5 business days.


