
YouTube Transcript Scraper: Channel, Playlist & Keyword Search
Pricing
from $1.00 / 1,000 transcript hours
YouTube Transcript Scraper: Channel, Playlist & Keyword Search
YouTube transcript scraper: search a channel's transcripts, get timestamped quotes with links. Watch channels for new uploads with Slack alerts. RAG chunks, SRT, VTT. Videos, Shorts, playlists. From $1 per 1,000 transcript hours (a video under an hour counts once); failed videos free. No login.
Pricing
from $1.00 / 1,000 transcript hours
Rating
0.0
(0)
Developer

Fulox
Maintained by CommunityActor stats
1
Bookmarked
1
Total users
1
Monthly active users
10 days ago
Last modified
Categories
Share
Get the transcript of any YouTube video, Short, channel or playlist as clean text, timed segments, SRT, VTT, Markdown or RAG chunks. Then search every transcript for your keywords and get each hit as a quote with a link that opens the video at that second. Schedule it and only new uploads are delivered, with a digest in Slack.
From $1.00 per 1,000 transcript hours (a video under an hour counts once). Videos without captions, listings and keyword matches are free. No login, no API key. Built for RAG and AI-agent pipelines, content and SEO teams, brand and PR monitoring, and research.

▶️ Watch the demo: paste a channel, search its transcripts, open each quote at the second it was said, then get only new uploads.
⚡ Try it in 30 seconds
Click Start with the default input. It reads two public videos (a 15-minute talk and a 19-second clip) and returns two transcripts for $0.003 on the Free or Starter plan. Then paste your own links: videos, Shorts, @channel names or playlists.
✨ Key features
-
🔎 Search a whole channel like Ctrl+F. Put words in
searchTermsand every hit comes back as a quote with the second it was said, a clickableyoutu.be/<id>?t=<seconds>link and the chapter. A phrase that spans two caption lines still matches. Matches are free.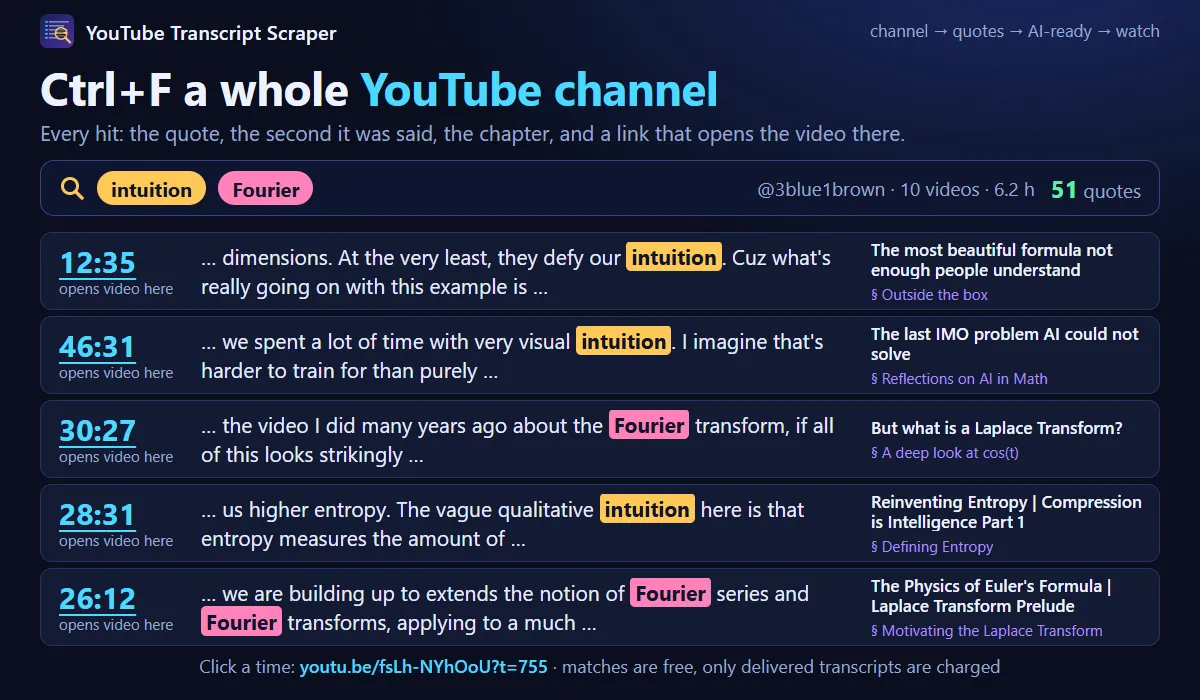
-
🔔 Watch mode. Turn on
watchand schedule the Actor. Each run delivers only the uploads it has not delivered before, plus a free digest row and an optional Slack or webhook message with the new videos and the top quotes. -
🧠 AI-ready output. RAG
chunkswith a stable id (<videoId>#3), start and end seconds, a token estimate, the chapter and a deep link. Or onemarkdowndocument with YAML front matter and a[m:ss](link)anchor per paragraph. Clean text without[Music]and>>. -
📑 Chapters. Read from the timestamps in the video description, and attached to every chunk and match.
-
🅰️ Quality grade. A to D from the caption kind (written by a person or auto-generated), how much of the video the captions cover, words per minute and the share of music cues, so you can filter weak transcripts before you embed them.
-
🔍 YouTube searches as input. Give
searchQueries(what you would type into YouTube) and every query becomes a source: its first results are fetched like a channel's uploads. Listing is free. -
📅 Publish date for every video (
publishedAt,YYYY-MM-DD), also for links you paste directly. -
📺 Videos, Shorts, live recordings, channels and playlists in one list, mixed.
channelContentpicks videos, Shorts or live streams of a channel.publishedAfterkeeps recent ones. -
🌍 Languages in order of preference, with a fallback to the best available track (the row says if your language was missing). Each row lists the languages the video has (
availableLanguages). -
👀 Free preview.
listOnlyreturns one free row per video with its length, its caption languages and what it would cost, without downloading any transcript. -
💶 Fair pricing. One result per started hour of video: a 10-minute video and a 59-minute one cost the same, a 3-hour podcast costs three. Failures, listings, matches, digests and alerts are free.
-
🔑 No login, no API key, no personal data beyond the public channel name.
👥 Who it is for
- 🤖 AI and RAG builders. Use case: load 300 videos of a conference channel into a vector store. Set
formats: ["chunks"]; each chunk has a stable id, a token estimate and a deep link, so an answer can cite the exact second. Filter onquality.gradebefore embedding. - ✍️ Content repurposing. Use case: turn a podcast back catalogue into articles and show notes. Set
formats: ["markdown"]for a document with front matter, chapter headings and timestamp links per paragraph. - 📈 SEO and competitor research. Use case: find every video where a competitor's channel mentions "pricing" or your product name. Set
searchTermsandformats: []and read the quotes and links. - 📣 Brand and PR monitoring. Use case: "tell me every time one of these 20 channels says our name".
watchplussearchTermson a daily Schedule, with the top quotes sent to Slack. - 🔬 Researchers and journalists. Use case: export a playlist of hearings or lectures as text and find who said what, with a link to the moment.
- 🧩 AI agents and MCP. Use case: an agent answers "what did this channel say about X" with one call and cites
matches[].url. See the agent notes below.
🚀 How to use it
- Paste YouTube links into Videos, channels or playlists:
https://www.youtube.com/watch?v=...,https://youtu.be/..., a Shorts link,@mkbhd, a channel link or a playlist link. Or type a search into YouTube searches. - Choose the output formats and, if you want quotes, add search terms.
- Click Start. Download the dataset as JSON, CSV or Excel, or send it to Google Sheets, Make, Zapier, n8n or Clay.
- For a recurring feed, turn on Watch mode, open Schedules and run the Actor daily or weekly with the same input. Each run delivers only new uploads.
Not sure what a channel will cost? Turn on listOnly first: it lists up to 200 videos with their lengths and caption languages, free.
📥 Input
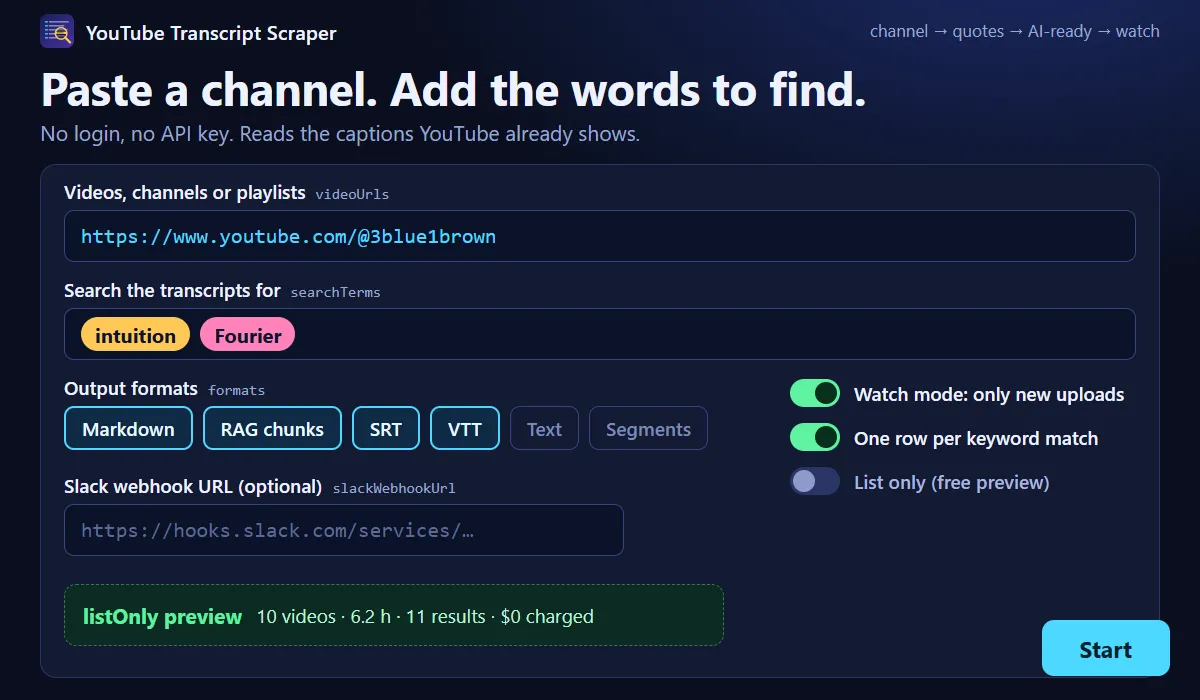
Example input:
| Field | What it does | Default |
|---|---|---|
videoUrls | Videos, Shorts, /live/ links, channels (@handle, /channel/UC..., /c/name, /user/name) and playlists (list=PL...). Up to 500 entries, 5,000 videos per run (300 on the Apify free plan). Duplicates and invalid entries are reported in free rows. Can be empty when you use searchQueries. | two public videos |
searchQueries | Texts to search on YouTube (videos only, in YouTube's relevance order). Each query gives up to maxVideosPerSource videos (about 600 at most). Up to 20 queries of 200 characters. Listing is free. | none |
searchTerms | Words or phrases to find in every transcript, ignoring case. Each hit becomes a quote with a timestamp link. Up to 50. | none |
matchRows | Besides the video row, add one free match row per keyword hit (term, second, link, quote, chapter), up to 50 per video. | off |
languages | Caption languages in order of preference (en, de, pt-BR). en also matches en-US and en-GB. | ["en"] |
preferAutoGenerated | Read the auto-generated track before the one written by a person. | off |
fallbackToAnyLanguage | If none of your languages exists, deliver the best available track (requestedLanguageFound: false). Off: a free language_not_found row that lists what exists. | on |
formats | text, segments, srt, vtt, markdown, chunks. Empty gives metadata, chapters, quality and matches only, at the same price. | ["text", "segments"] |
chunkTokens | Target chunk size, 100 to 2000 tokens. Chunks end at a sentence end or a pause of 2 seconds or more. | 400 |
channelContent | For channels: videos, shorts, live. | ["videos"] |
maxVideosPerSource | Newest first, per playlist and per selected channel tab. | 100 |
publishedAfter | A date (2026-09-01) or an age (7 days, 3 weeks, 2 months) for channels and playlists. Uses the listing's relative date ("3 days ago"). Shorts list no date, so their exact date is checked when they are fetched: an older Short comes back as a free too_old row. A video whose date cannot be found at all is kept. | none |
includeDescription | Adds the video description (up to 5,000 characters). | off |
listOnly | Free preview: one preview row per video with hasCaptions, languages, length and estimatedResults, no transcript, never charged. Checks at most 200 videos per run; watch mode is ignored. | off |
watch | Deliver only videos not delivered by an earlier run with the same watchlistName. | off |
watchlistName | Separate memory per name (letters, digits, -, _). | default |
slackWebhookUrl / webhookUrl | A hooks.slack.com URL, or an https URL, that receives the digest when at least one transcript was delivered. Stored as secrets, never logged. | none |
resetState | Forget what watch mode delivered for the sources in this run. | off |
📤 Output
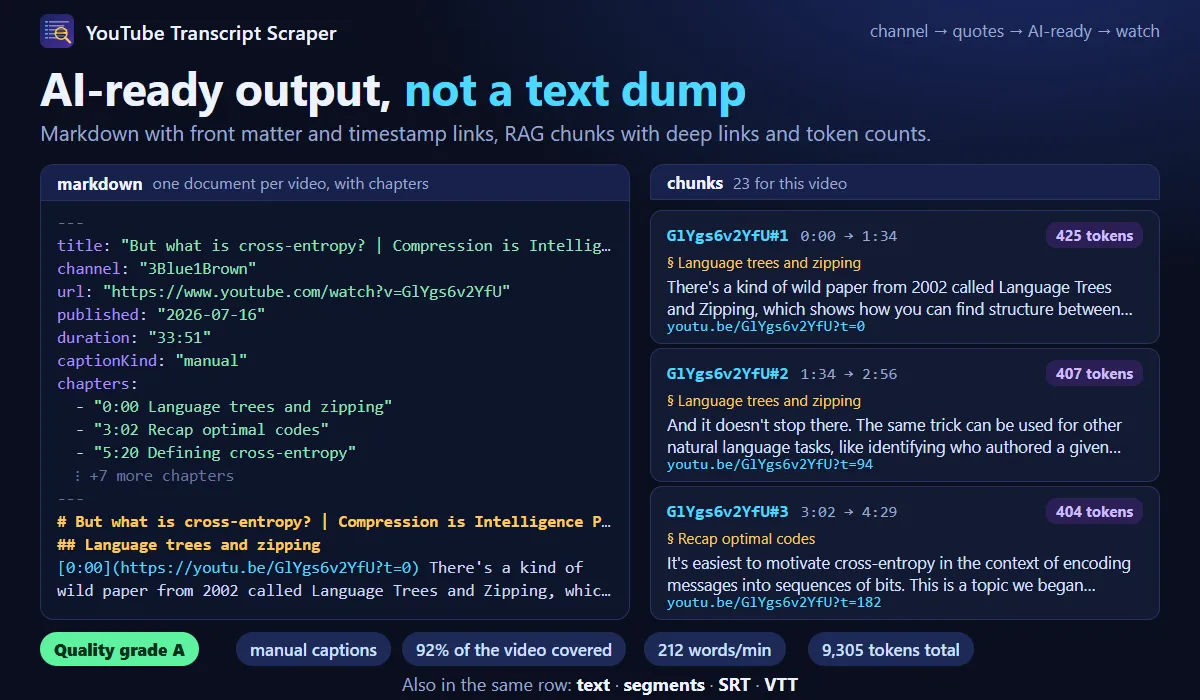
One dataset with five kinds of rows. Filter the type column: video, match, input, digest, run (and preview with listOnly). Fields a format did not ask for are null.
A delivered video (type: "video", status: "ok"), shortened:
Other fields: channelId, channelUrl, tags, thumbnailUrl, availableLanguages, translationLanguages (information only: the languages YouTube lists as translatable; this Actor does not translate), srt, vtt, markdown, description (when asked), source (the channel or playlist the video came from) and publishedText (the listing's "3 days ago", for videos that came from a channel, playlist or search). publishedAt is the exact date for every delivered video; it comes from a second, tiny request, and is null if YouTube does not answer it.
- A video that failed has
statusno_captions,language_not_found,unavailable,age_restricted,live_in_progress,blocked,pot_required,fetch_failedortoo_large, areason, andresultsCharged: 0. Never charged. matchrows (free, only withmatchRows): one per keyword hit, right after the video row.previewrows (free, only withlistOnly):status: "preview",hasCaptions,availableLanguages,lengthSeconds,estimatedResults.inputrows (free): invalid or duplicate entries, and for each channel or playlist asource_resolvedrow (listed,afterFilters,alreadySeen), orsource_not_found,source_empty,source_truncated.digestrow (free, last): the sources with counts,videosDelivered,hoursOfVideo,resultsCharged,matchesTotal, the 10topMatches, up to 20newVideosand thealertstatus.runrow (free): says why nothing was delivered or why the run stopped early.
A run summary (OUTPUT) lists the counts and, for your own checks, the proxy bytes per video.
💸 Pricing
Pay per result, cheaper on higher Apify plans. A result is one transcript of up to 60 minutes of video (the Store calls it a "transcript hour"); a longer video counts one result per started hour (a 25-minute video is 1, a 2.5-hour podcast is 3).
| Your Apify plan | Per 1,000 results | Per result |
|---|---|---|
| Free and Starter | $1.50 | $0.0015 |
| Scale | $1.25 | $0.00125 |
| Business | $1.00 | $0.0010 |
| Enterprise | $1.00 | $0.0010 |
Apify's standard Store tiers apply: Free and Starter are the Free and Bronze tiers, Scale is Silver, Business is Gold, Enterprise is Platinum and Diamond.
Free: videos without captions, unavailable, age-restricted, live or refused videos, channel, playlist and search listings, listOnly previews, keyword matches and match rows, digests, alerts, and input and run rows.
| Results | Free / Starter | Scale | Business | |
|---|---|---|---|---|
| 🆕 The default input (2 short videos) | 2 | $0.003 | $0.0025 | $0.002 |
| 📅 100 ten-minute videos | 100 | $0.15 | $0.125 | $0.10 |
| 🎙️ One 3-hour podcast | 3 | $0.0045 | $0.00375 | $0.003 |
| 📚 A 1,000-video channel, 10% without captions | about 900 | $1.35 | $1.125 | $0.90 |
| 🔔 Weekly watch of 20 channels, 60 new uploads | 60 | $0.09 | $0.075 | $0.06 |
Set a maximum cost per run to stay in control. A run on the Apify free plan processes up to 300 videos; paid plans up to 5,000.
🔌 Alerts and integrations
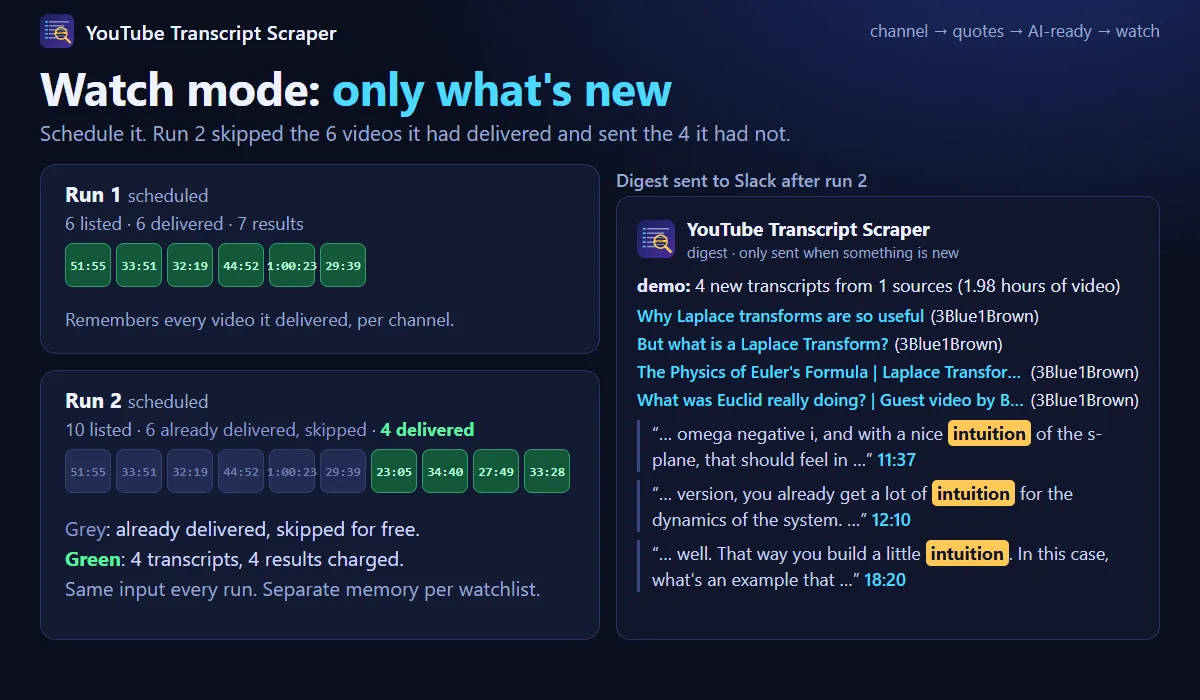
- 💬 Schedule plus Slack:
watch: true, aslackWebhookUrl, and a daily Schedule. Slack gets one message per run with the new videos and the top quotes, and nothing when there is nothing new. Free. - 🔗 Webhook:
webhookUrlreceives the same digest as JSON, no polling. - 📑 Google Sheets: Integrations > Google Sheets appends the dataset after every run. Filter the
typecolumn tovideo. - 🔁 Make, n8n, Zapier: run the Actor, then send
videorows to your tool. - 📓 NotebookLM, Claude Projects, Cursor: set
formats: ["markdown"]and upload themarkdownfield of each row as a document. - 🧱 Clay: an HTTP API column that calls this Actor's
run-sync-get-dataset-itemsendpoint with your Apify token and the body{"videoUrls":["{{url}}"],"formats":["text"]}. - 🛠️ API: call it from any language and read the dataset.
🤖 For AI agents
Call with {"videoUrls": ["https://www.youtube.com/watch?v=<id>"], "formats": ["text"]} and read the dataset. Row type is video (status: "ok" has the transcript, any other status is a free failure with a reason), match, preview, input, digest or run. To work from a topic instead of links, pass "searchQueries": ["your topic"]. To check what exists before paying, add "listOnly": true; the estimatedResults of each preview row is what a real run would charge for it. Add "matchRows": true to get one flat row per quote. To find what someone said, add "searchTerms": ["phrase"] and "formats": [], then read matches[].quote and matches[].url (the link opens the video at that second). quality.grade A to D says how far to trust the text.
🆚 How it compares (October 2026)
Facts from each Actor's Apify Store page and README, read on 2026-10-14. Prices per 1,000 results are not like-for-like, and competitors may change.
| This Actor | starvibe/youtube-video-transcript | johnvc/YoutubeTranscripts | pintostudio/youtube-transcript-scraper | |
|---|---|---|---|---|
| Input | videos, Shorts, channels, playlists, searches, mixed, up to 500 entries | one video or one channel (max 200) per run | up to 100 URLs, channels (max 1,000) | one video |
| Playlists | yes | not documented | not documented | no |
| Keyword search with timestamp links | yes | no | no | no |
| New-uploads-only mode, digest, Slack | yes | no | no | no |
| RAG chunks, Markdown, chapters, quality grade | yes | no | no | no |
| SRT / VTT / text / segments | yes | segments, text | yes | segments |
| Translation | no | no | yes | no |
| Failed videos | free | charged as items | free | charged |
| Price per 1,000 | $1.50 Free/Starter, $1.25 Scale, $1.00 Business, per transcript hour | $5 | $2.75 down to $2.00 (+$3 for extended metadata) | $10 |
Where others do better: johnvc offers translation, a cache of popular videos and extended metadata. starvibe returns richer video metadata such as likes, and has more ratings. This Actor has no translation, no audio transcription and a shorter track record.
⚠️ Limitations
- Captions only. It reads the captions YouTube already has (written by the creator, or auto-generated). It does not transcribe audio, so a video without captions is a free
no_captionsrow. Captions that hold only music or sound cues are treated the same way. - No translation. You get the transcript in a language the video already has.
availableLanguagesshows which.translationLanguagesonly lists what YouTube says it could translate to; this Actor does not request translations. - YouTube can change. Caption availability and the way YouTube serves it change from time to time. If YouTube refuses 8 requests in a row the run stops, writes a free
runrow, and charges nothing for the refused videos. Try again in a few minutes. - Dates:
publishedAtis the exact date of every delivered video (one small extra request). Videos from a channel, playlist or search also carry the listing's relative date inpublishedText("3 days ago"), andpublishedAfteruses that one, rounded in your favour. - YouTube search returns what YouTube returns: relevance order, at most about 600 results per query, and results can differ between runs and regions. Watch mode on a query delivers videos it has not delivered before, but a new video that ranks low may not be listed.
- Live streams are delivered after the stream has ended. A stream in progress is a free
live_in_progressrow. - Watch mode remembers up to 5,000 video IDs per source. A video that failed for a temporary reason (
blocked,pot_required,fetch_failed,live_in_progress, or a very fresh upload without captions yet) is tried again next run. The memory is saved with the run's progress (every 25 videos and whenever Apify moves or stops the run), so a hard kill delivers again at most the videos since the last save, up to about 25 plus the one in flight. A run that Apify restarts continues with the video list it saved at the start and never charges a video twice. - Very long captions: captions over 2 MB are a free
too_largerow. A row over 8 MB dropssegments,vtt,srtandchunks(in that order) and lists them intruncated, at the same price. - Search is a case-insensitive text match, not meaning-based. Hyphens, spaces and punctuation between words count as the same, so "product-market fit" also finds "product market fit". At most 50 matches are listed per video;
matchCountis the full count. - Slack and webhook URLs must be https with a public host (Slack only
hooks.slack.com). The host is also resolved, and an address that is private, loopback, link-local, shared (CGNAT) or reserved is refused before anything is sent. listOnlychecks at most 200 videos per run.
❓ FAQ
Is this legal? The Actor reads captions of public videos, the same text YouTube shows to anyone who turns subtitles on. It collects no comments and no personal data beyond the public channel name. You are responsible for how you use the text and for the laws that apply to you, including YouTube's terms and the creators' rights. It does not download any video or audio.
What if YouTube changes something?
Caption delivery on YouTube changes from time to time, and scrapers break when it does. If that happens, the run stops early, charges nothing for refused videos and says so in a free run row. Report it on the Issues tab and I fix it; I reply within 12 hours.
What does "failed videos are free" cover? Everything that is not a delivered transcript: no captions, wrong language (with fallback off), private, deleted, age-restricted, live, refused by YouTube, a network failure, captions that are too large.
How does watch mode work?
At the end of each run the Actor saves the IDs it handled, per channel or playlist, in a key-value store named youtube-transcript-scraper-state in your account. The next run lists the source again and fetches only new IDs. A different watchlistName has its own memory. resetState clears it.
Why is a video I pasted charged more than one result? It is longer than an hour. Each started hour is one result: 1:00:01 is two.
How much will it cost me?
$1.50 per 1,000 results (transcript hours) on Free and Starter, $1.25 on Scale, $1.00 on Business and Enterprise (see Pricing for worked examples). Use listOnly to see estimatedResults before a big run, and set a maximum cost per run.
Can I get the transcript in another language than the video has?
No, translation is not offered. See availableLanguages on each row for the languages the video has, and put your preferred ones in languages.
How fast is it? About 6 videos are fetched in parallel. A hundred videos take a minute or two. A run can hold up to 5,000 videos.
Something is wrong or missing. Who do I ask? Open an issue on the Actor's Issues tab. I reply within 12 hours.
🛠️ Need a custom feature?
A different output, a corpus file for a whole channel, a signal you need? Open an issue on the Actor page and describe it.
Changelog
- 1.1.1 (2026-10-21):
publishedAfternow also filters Shorts (older ones are a freetoo_oldrow, never charged);publishedTextis kept on every listed video. - 1.1 (2026-10-14):
searchQueries(YouTube search as input),publishedAtfor every video,listOnlyfree preview,matchRows, other YouTube clients tried beforepot_required, a restarted run keeps its saved video list and never charges twice, watch memory saved with every progress save, alert hosts resolved and private addresses refused. - 1.0 (2026-10-14): first version. Videos, Shorts, channels and playlists; text, segments, SRT, VTT, Markdown and RAG chunks; chapters; quality grade; keyword search with timestamp links; watch mode with digest, Slack and webhook; one result per started hour, failures free.


