
Google News Scraper | Articles by Keyword & Topic
Pricing
from $1.54 / 1,000 news articles
Google News Scraper | Articles by Keyword & Topic
Get Google News articles by keyword, topic, place or top stories: title, source, publish time, position, related coverage and Google News link. 86 editions (country + language), date ranges, many queries per run, no login.
Pricing
from $1.54 / 1,000 news articles
Rating
0.0
(0)
Developer
Flowo
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Features
Share
Google News Scraper — Articles by Keyword, Topic, Country & Language
This actor returns Google News articles as flat rows: title, source (publisher), sourceUrl, publishedAt, position in the feed and the Google News url, plus the story cluster in relatedArticles and relatedCount. Search by keyword (with Google operators), by topic section, topic page or local place, or take the top stories — in any of the Google News editions (country + language). No login or API key.
What it does
- Searches Google News by keyword with operators (
"exact phrase",OR,-word,site:,intitle:,source:,when:,after:/before:). - Reads the 8 topic sections (World, Nation, Business, Technology, Entertainment, Sports, Science, Health), any Google News topic page (id starting with
CAAqor URL), local news by place name, and the top stories of an edition. - Works per edition:
country(ISO 3166-1, e.g. US, GB, DE, IN, BR, JP) andlanguage(e.g. en, de, es, pt-BR, zh-Hant). - Filters by time range (past hour, 24 hours, 7 days, 30 days, year) or by Date from / Date to. With a date range each keyword is split into one search per day, so you get far more than the ~100 articles a single search returns.
- Returns the related coverage of a story (other articles in the same cluster) in
relatedArticleswhere Google groups them. - Optional paid add-ons:
publisherUrl(the real article URL on the publisher's site) andimageUrl,description,authorfrom the publisher's page.
How to use
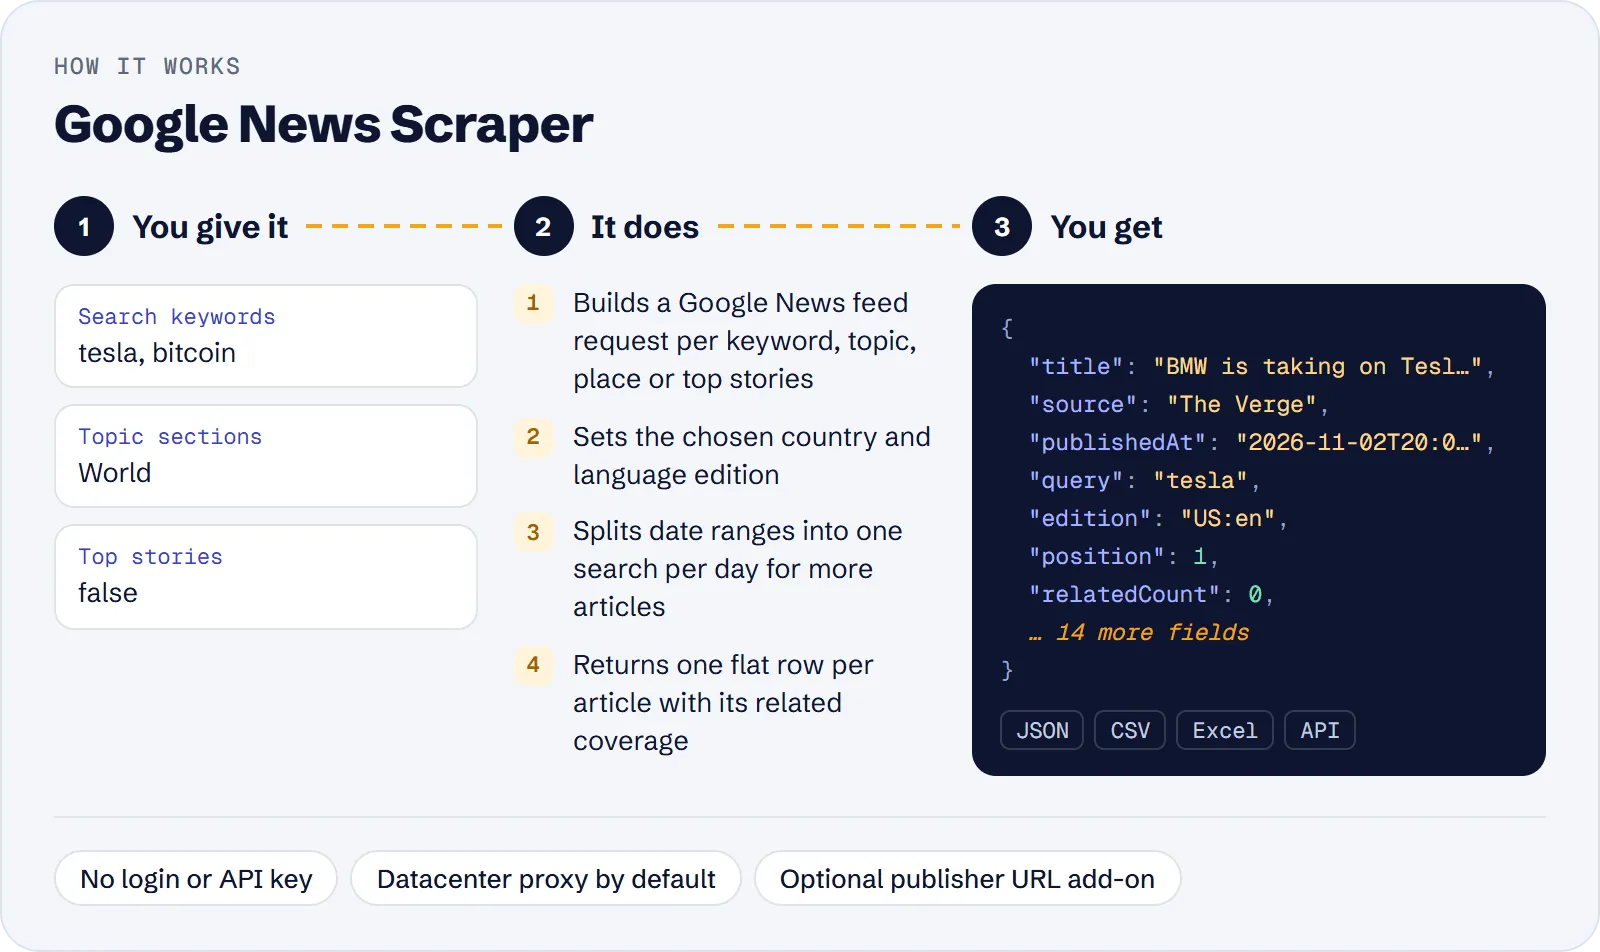
- Open the actor in Apify Console and add keywords, topics, topic pages or places. With none of these, the top stories of the edition are fetched.
- Choose Country and Language (default US / the country's main language).
- Optionally set a time range or dates, and set Max articles.
- Run it and download the dataset as JSON, CSV, Excel or HTML, or read it through the API.
Example input:
Pricing
Pay per event:
| Event | Price |
|---|---|
| News article (one dataset row) | $0.0022 (about $2.20 per 1,000 articles) |
| Add-on: publisher URL, per article where decoding succeeds | $0.0008 |
| Add-on: image, description, author, per article where at least one is found | $0.0008 |
| Actor start | $0.00005 |
Searches that return nothing are free. maxItems caps the number of paid articles in a run.
Input
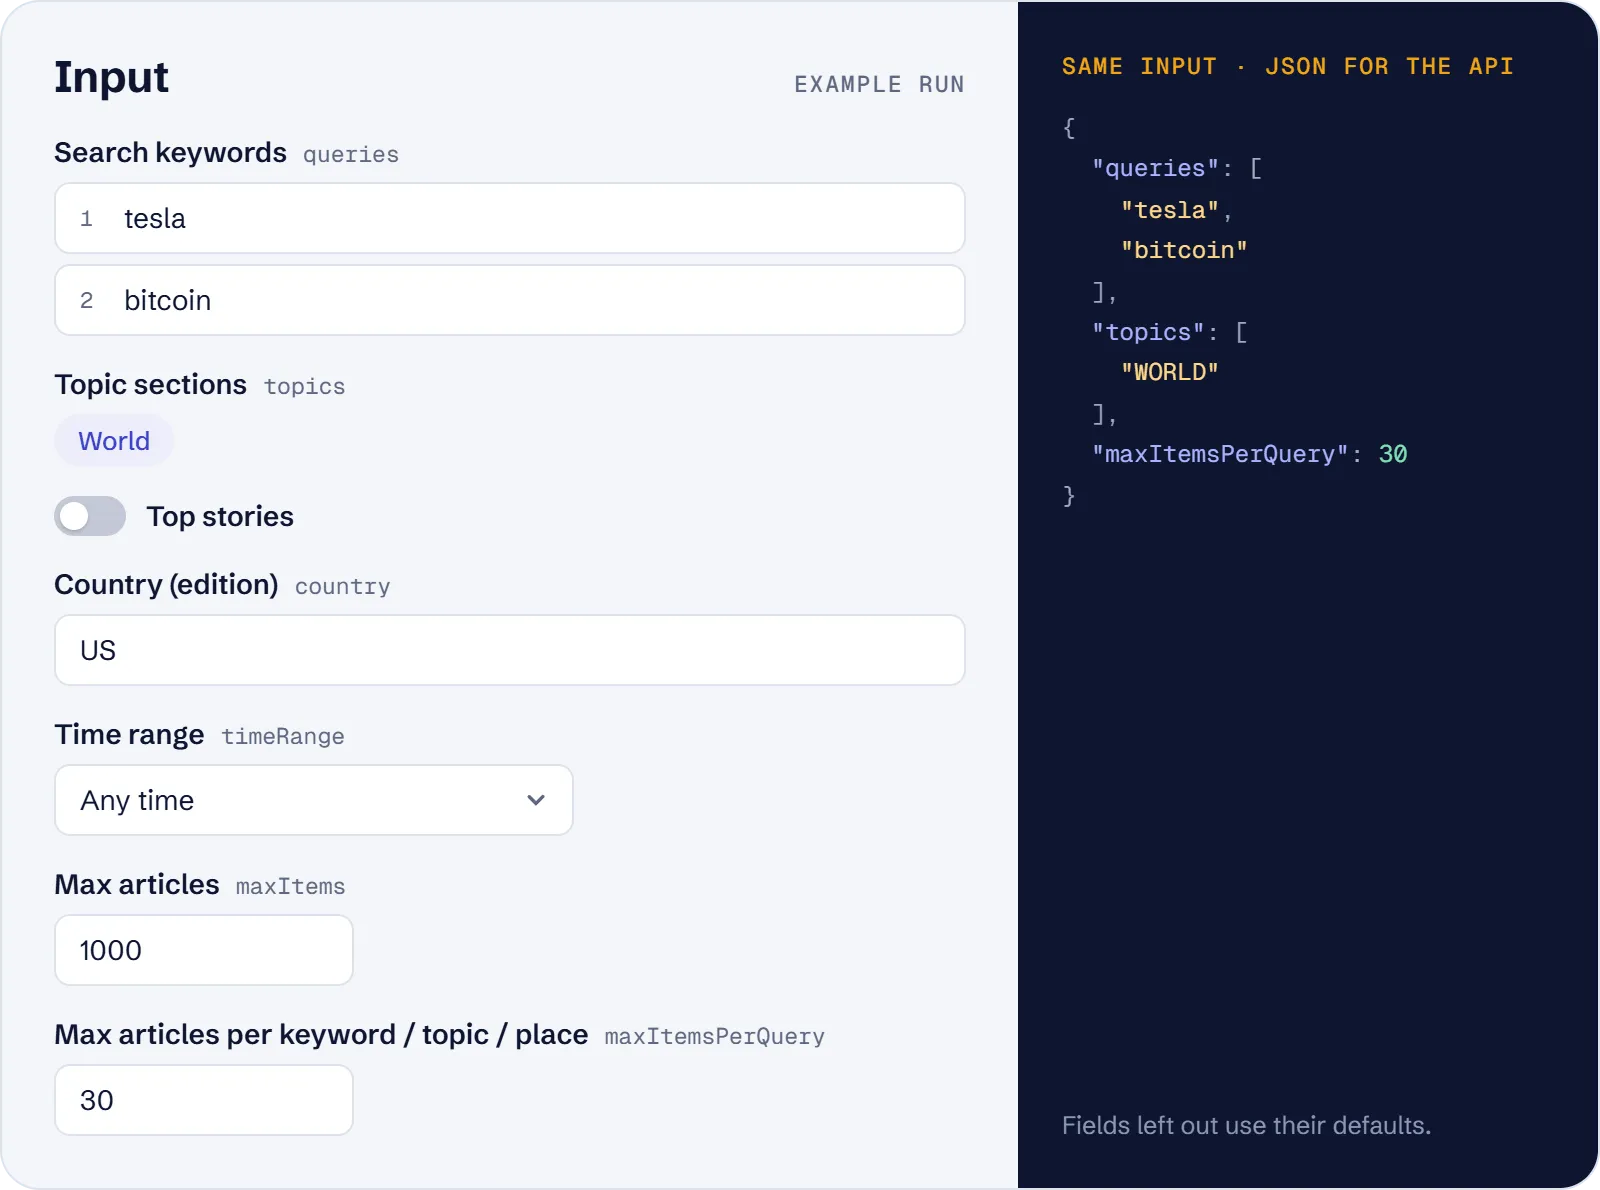
| Field | Meaning |
|---|---|
queries | Keywords, one per line; Google operators work |
topics | Topic sections: WORLD, NATION, BUSINESS, TECHNOLOGY, ENTERTAINMENT, SPORTS, SCIENCE, HEALTH |
topicIds | Google News topic page ids or URLs |
locations | Place names for local news, in the edition's country |
topStories | Also fetch the edition's top stories |
country, language | The Google News edition |
timeRange | any, 1h, 1d, 7d, 30d, 1y (not together with dates) |
dateFrom, dateTo | Day range, YYYY-MM-DD |
maxItems, maxItemsPerQuery | Limits for the run and per keyword/topic/place |
decodeUrls, fetchArticleDetails | Paid add-ons |
proxyConfiguration | Proxy; the default Apify datacenter proxy works |
Output
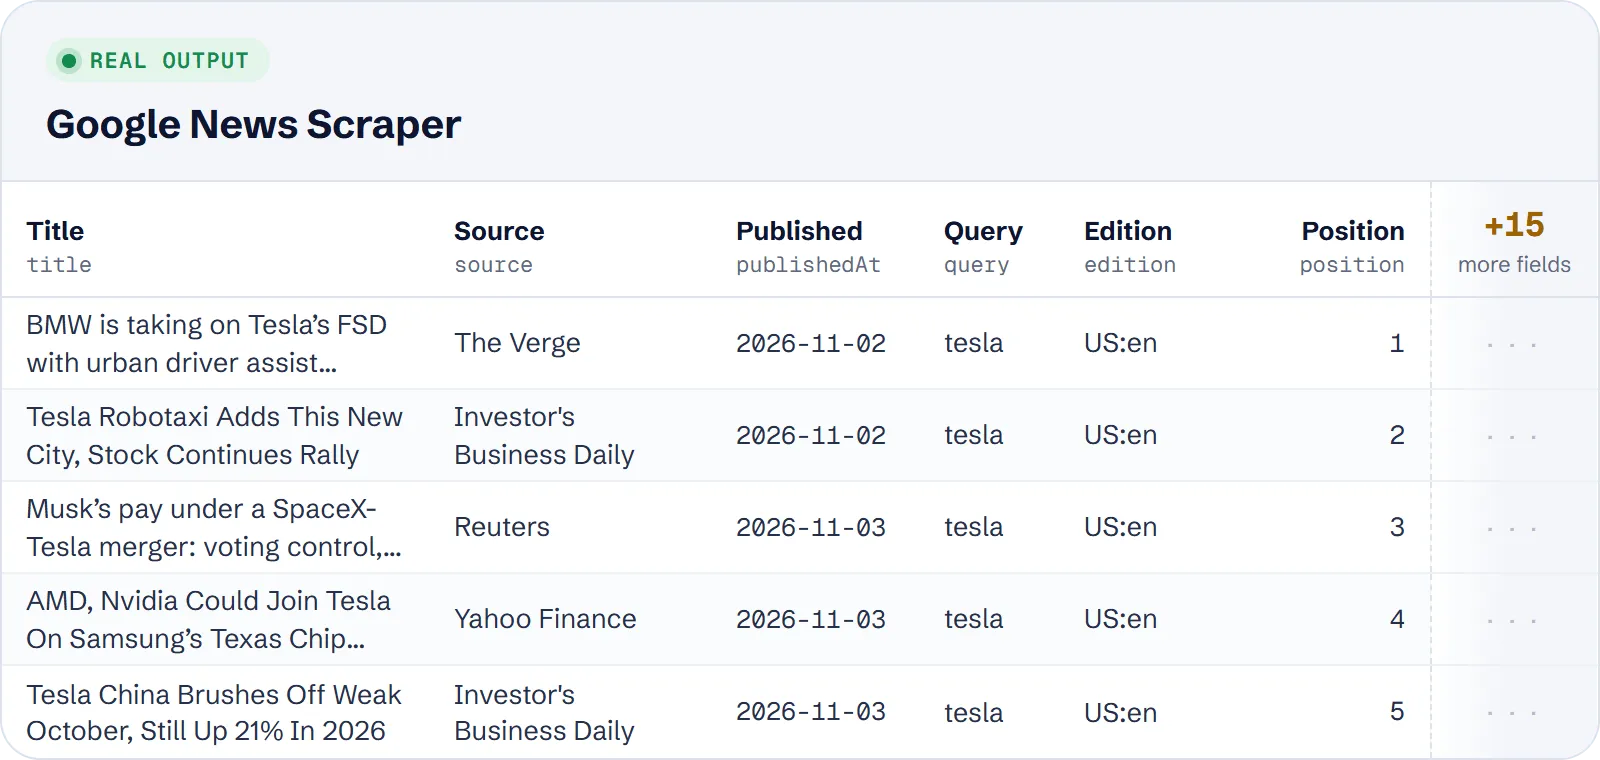
One row is one article in one feed. Fields: id, title, url, publishedAt, source, sourceUrl, position, relatedCount, relatedArticles (url, title, source), feedType (search, topic, topicId, location, topStories), query, topic, location, country, language, edition, publisherUrl, imageUrl, description, author, scrapedAt. Values that are not available are null; relatedArticles is [] when the article has no cluster. The add-on fields are null unless the add-on is on.
Real example (search for tesla, US:en):
Other rows in the same run have clusters, e.g. a Reuters article with relatedCount: 2 and two entries in relatedArticles.
Use cases
- Media and brand monitoring: track mentions of a company or product by keyword and country.
- PR and competitor tracking with
site:andsource:operators. - Market and trading research: headlines with publish time per day over a date range.
- Research datasets and news archives across languages and editions.
- Feeding AI agents or RAG pipelines with fresh headlines, optionally with publisher URL, description and author.
Limitations
- One keyword search returns up to about 100 articles; topic and top-stories feeds return roughly 34–70. Use Date from / Date to to get more for keywords. Topic feeds cannot be date-filtered by Google, so the time range filters them by publish time.
- Google News links in
urlredirect to the publisher; the real URL needs the Publisher URL add-on (slower, one Google page per article). - Only editions that Google offers work; an unsupported country is an input error, and a language must exist for the country (for example DE: de only).
- Places outside the edition's country or unknown to Google give no articles.
- Result content depends on what Google News shows at the time of the run.
FAQ
Do I need a login or API key? No.
Is it legal? The actor reads public Google News feeds and returns headlines, publishers, times and links. Google's terms describe the feed as meant for personal feed readers, so check them and the copyright of the publishers' content for your use case; the actor does not return full article texts. Do not use it to process personal data without a legal basis.
Why are there fewer than 100 articles for my keyword? Google returns what it has for that search and time window.
Can I get articles from several countries? Run once per edition (country + language); each row carries country, language and edition.
Also useful
- Google Trends Trending Now Scraper — find what is trending by country, with related news articles
- Google Trends Scraper — add search interest over time and by region for your news keywords
- SEC EDGAR Filings Search — pair company news with official filings: form type, date and links


