
Google Trends Scraper | Interest, Regions & Related Queries
Pricing
from $2.73 / 1,000 keyword reports
Google Trends Scraper | Interest, Regions & Related Queries
Returns Google Trends data for your search terms: a 0–100 timeline, interest per country, state, US metro or city, and top and rising related queries, with up to 5 terms on one scale. Flat rows for Sheets, BI or AI agents. Many terms per run, no login.
Pricing
from $2.73 / 1,000 keyword reports
Rating
0.0
(0)
Developer
Flowo
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Features
Share
Google Trends Scraper returns Google Trends data for your search terms as flat rows: interest over time (a 0–100 value for each time point), interest by region (country, state, US metro area or city, with latitude and longitude for cities) and related queries (top and rising, with a breakout flag). You can compare up to 5 terms on one scale, with no login or browser.
What does Google Trends Scraper do?
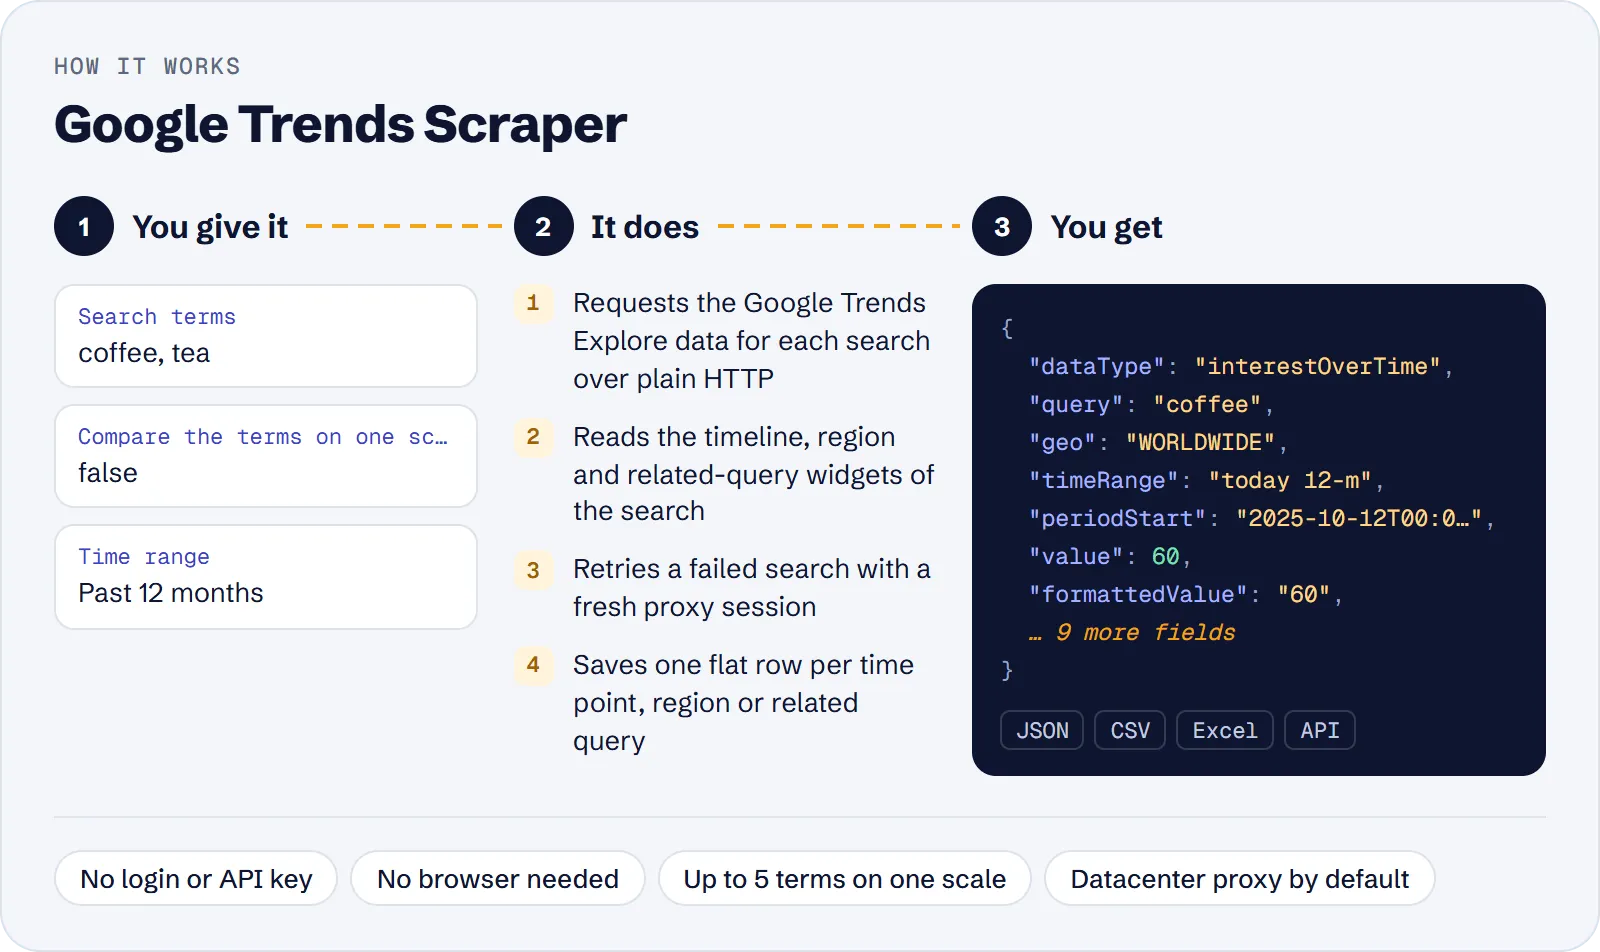
Google Trends Scraper gets Google Trends data for your search terms. You can look up each term on its own or compare up to 5 terms on one scale. For every search it returns three sections:
- Interest over time: a 0–100 score for each time point (minutes, hours, days, weeks or months, depending on the time range).
- Interest by region: a 0–100 score per country, state/region, US metro area or city. Cities come with latitude and longitude.
- Related queries: the top and rising searches for each term, including Google's "Breakout" label.
Each result is a flat row with ISO dates, so it opens directly in Google Sheets, Excel or a BI tool, or can be passed to an AI agent. The actor talks to Google Trends over plain HTTP. It doesn't need a browser or a Google account. It's made for SEO and content marketers, market researchers, analysts, journalists and automations.
How to scrape Google Trends data
- Open the actor in Apify Console.
- Enter your Search terms, one per line, e.g.
coffeeandtea. - To see which term is searched more, tick Compare the terms on one scale (1–5 terms; one term gets its own 0–100 scale).
- Pick a Country (empty = worldwide) and a Time range (past 12 months by default). Untick sections in Data to extract that you don't need.
- Optional: open More filters to set a state or region, a category, the Google search type (web, YouTube, images, news, shopping), the region level or custom dates. Or paste Google Trends links copied from your browser.
- Click Start. Download the dataset as JSON, CSV or Excel, or open the Overview and Interest over time tables.
Developers and AI agents can send the same JSON input through the Apify API, the Apify clients or the Apify MCP server.
How much does it cost to scrape Google Trends?
Price per event by Apify plan:
| Event | Free | Bronze | Silver | Gold and above |
|---|---|---|---|---|
| Keyword report | $3.00 per 1,000 | $2.73 per 1,000 | $2.73 per 1,000 | $2.73 per 1,000 |
A test run with the API example input below returned 326 rows in 11 s.
Pricing is pay-per-event with one event: a keyword report at $0.003 ($3.00 per 1,000 reports on the Free plan). A keyword report is one search term with data in one search, with every section you requested (timeline, regions, related queries). There is no start fee.
A keyword report is usually about 200 flat rows (119–393 in our test runs with all three sections). The rows themselves are free: you pay once per term, not per row. In a comparison (Compare ticked, or a Google Trends link with several terms) each term is its own report, so comparing 3 terms costs 3 reports = $0.009. No platform usage is billed on top.
Cost scenarios (Free plan):
| Scenario | Keyword reports | Cost |
|---|---|---|
coffee and tea, worldwide, all sections | 2 | $0.006 |
Compare coffee, tea and matcha | 3 | $0.009 |
| 100 search terms, all sections (or only related queries) | 100 | $0.30 |
| 1,000 search terms | 1,000 | $3.00 |
Fewer sections make a run faster and the dataset smaller, not cheaper.
What costs nothing:
- terms Google has no data for, and searches that fail;
- a run with no data at all, which still ends as succeeded;
- invalid input: the run stops before the first request with a message naming the field.
If one section of a report fails (for example related queries), the other sections are still saved, the report is charged once, and the log names the missing section. A report cut short by Max rows is also charged once. Higher Apify subscription plans may get a lower price per report; Console shows the price for your plan.
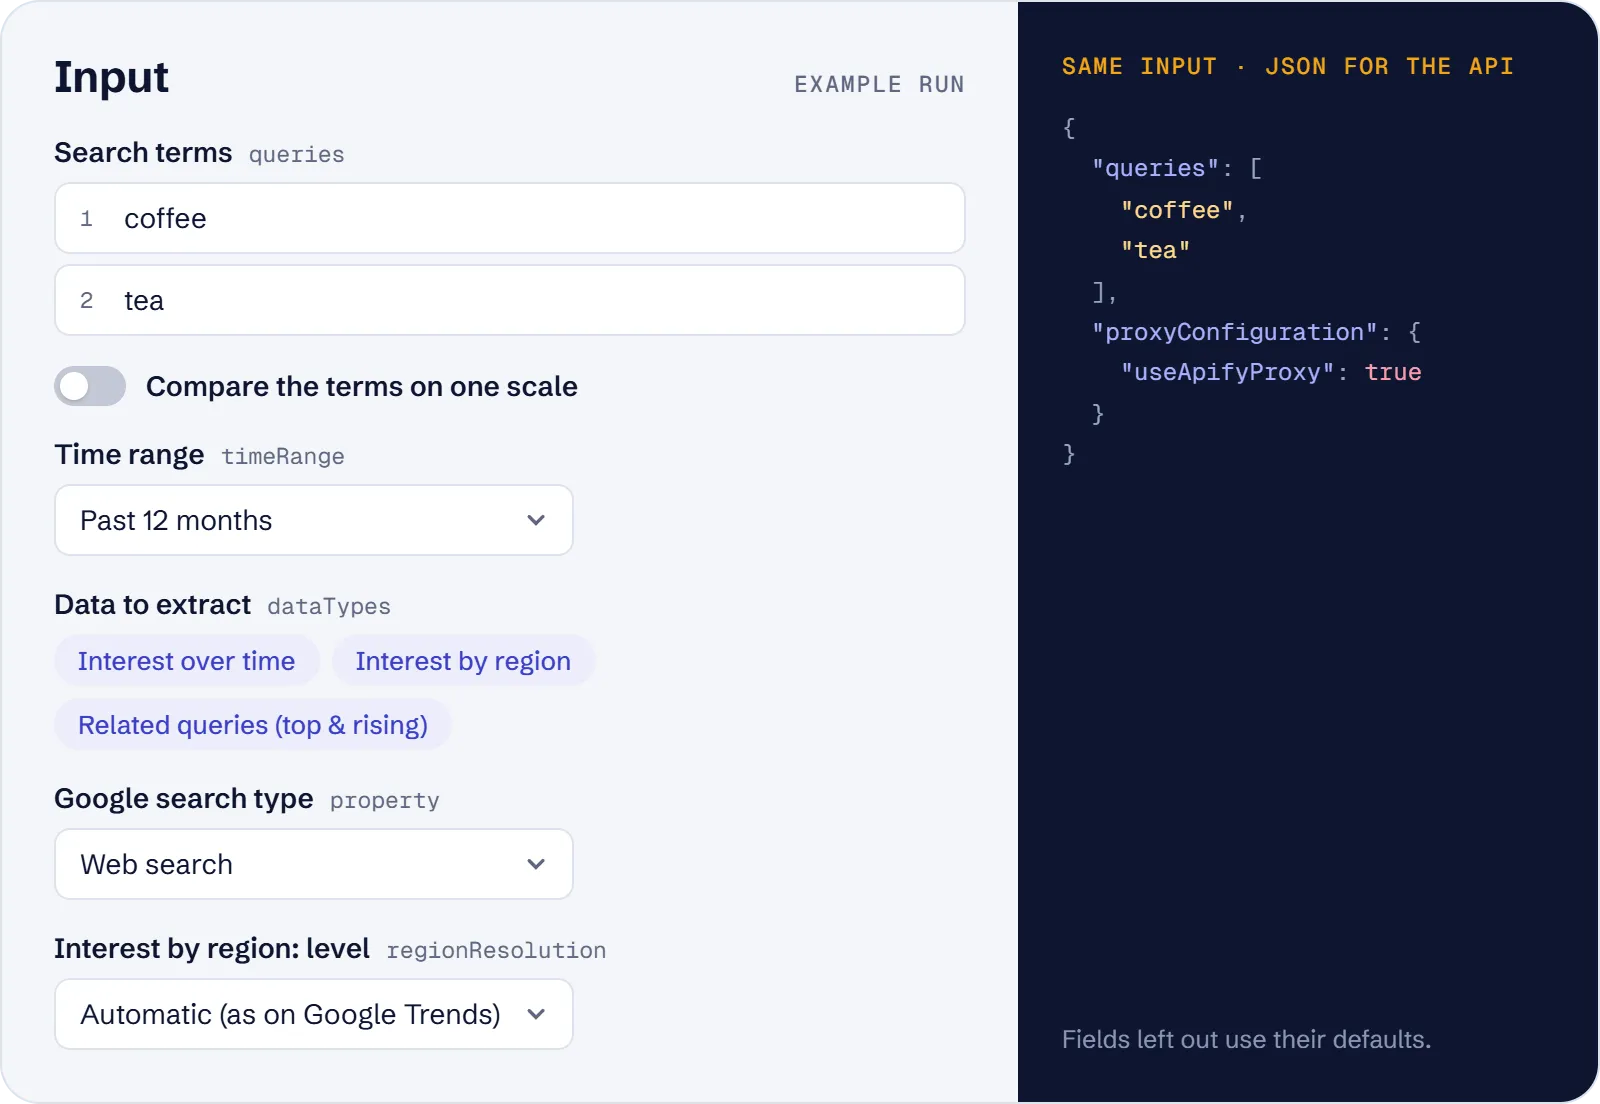
Input
| Field | What it does |
|---|---|
Search terms (queries) | One term per line, up to 100 characters each, no commas. Every term gets its own report. Duplicates are skipped. |
Compare the terms on one scale (compareQueries) | Off by default. When on, 1–5 terms are looked up together, as on the Trends Compare page, and share one 0–100 scale (one term is just a normal search). |
Country (country) | Empty = worldwide. Pick one of 20 markets from the list or type any country as a code (CH) or English name (Switzerland). |
Time range (timeRange) | Past hour, 4 hours, day, 7 days, 30 days, 90 days, 12 months (default), 5 years, 2004 – present, or custom dates. |
Data to extract (dataTypes) | interestOverTime, interestByRegion, relatedQueries. All three by default. |
State or region (region) | A region inside Country, by name (California) or code (CA, US-CA). |
Category (category) | A Google Trends category by name (Food & Drink, Programming) or ID (71). Empty = all categories. |
Google search type (property) | web (default), youtube, images, news or shopping. |
Interest by region: level (regionResolution) | auto (as on Google Trends, default), CITY (any location, with coordinates) or DMA (US metro areas, Country = United States only). |
Custom start / end date (startDate, endDate) | YYYY-MM-DD, used only with Time range = Custom dates. Data starts on 2004-01-01. |
Google Trends links (startUrls) | Explore page links. Each link is one search with its own terms (up to 5), location, time, category and search type. |
Max rows (maxItems) | Stop after this many rows in total. Empty = no limit. Rows are free; a report cut short by this limit is still charged once. |
Proxy (proxyConfiguration) | Apify Proxy, datacenter by default. Switch to RESIDENTIAL only if runs report blocking. |
Invalid combinations stop the run before any request, with a message that names the field and says how to fix it. Examples: an unknown country or category, a region without a country, US metro areas outside the United States, or more than 5 terms to compare.
Example input (compare three drinks in the US over the past 90 days):
What data can you extract from Google Trends?
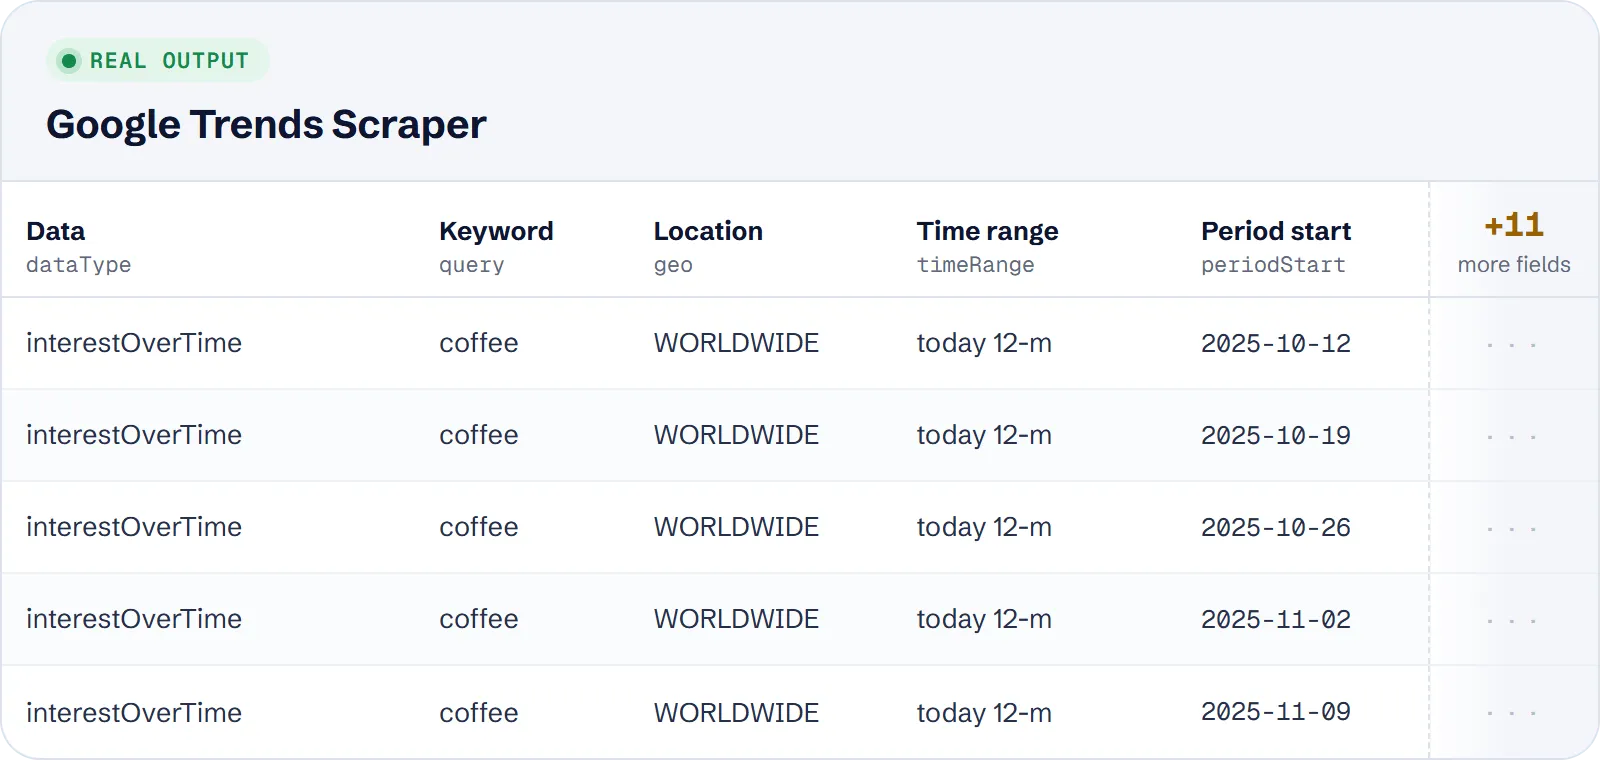
The actor saves one flat row per data point. The dataType field says which section a row comes from. Fields of other sections are null or absent on that row.
One keyword report (the unit you pay for) is all rows of one search term in one search, i.e. the rows with the same url and query: its interest-over-time points, its regions with data and its top and rising related queries, whichever sections you requested. The rows of a report are saved together. A term without data gives no report and no rows.
| Field | Rows | Description |
|---|---|---|
url | all | Google Trends Explore page of the search |
scrapedAt | all | When the row was extracted (ISO 8601) |
dataType | all | interestOverTime, interestByRegion or relatedQueries |
query | all | The search term the row is about |
searchTerms | all | All terms of the search, comma-separated (more than one = a comparison) |
geo | all | Geo code of the search (US, US-CA, US-CA-807) or WORLDWIDE |
timeRange | all | Google's time string, e.g. today 12-m or 2024-01-01 2024-12-31 |
categoryId, category | all | Category ID and name (0, All categories when not narrowed) |
property | all | web, youtube, images, news or shopping |
value | all | 0–100 interest or top-query score; growth in % for a rising query |
formattedValue | all | The value as Google shows it, e.g. "63", "+1,750%", "Breakout" |
periodStart, formattedTime | interest over time | Start of the time point (ISO 8601, UTC) and Google's label |
hasData | time points, regions | false when Google has too little data (value 0). Region rows are only saved with data, so they show true. |
isPartial | interest over time | true for the last, still incomplete time point |
regionResolution, geoCode, location | interest by region | Level (COUNTRY, REGION, DMA, CITY), region code (null for cities) and name |
latitude, longitude | interest by region, cities | City coordinates |
rankType, position | related queries | top or rising list and the 1-based rank |
relatedQuery, relatedQueryUrl, isBreakout | related queries | Query text, its Trends page, and the "Breakout" flag |
A real interest-over-time row from a test run (coffee, worldwide, past 12 months):
Use cases
- Seasonality in one market.
bitcoinwith Country = United States: weekly points for 12 months, every US state and 50 related queries (154 rows in our test). - Brand and product comparison. Compare
coffee,teaandmatchaon one scale over 90 days: daily points, countries and related queries per term. - Content ideas from rising queries. Keep only related queries, e.g.
electionin California over the past 7 days, to get the top and rising searches in a faster, smaller run (still one report per term). - City maps. Set the region level to Cities to get interest per city with latitude and longitude.
- Long-run series and saved charts.
kubernetessince 2004 in Computers & Electronics gives a monthly series. You can also paste links from the Trends site, for example a YouTube chart for the past day.
Limitations
- No related topics. Google sends an empty related-topics list to visitors who aren't signed in, so only related queries are returned.
- Relative values. Scores are 0–100 relative to the highest point of the search and based on Google's sampling. They are not search volumes, and repeated runs can differ by a few points.
- At most 5 terms per comparison, as in the Google Trends interface. Use several links for more comparisons.
- City data is sparse. Google often has city data only for popular terms. When it has none, the term gets no region rows and a warning, and its other sections are kept. Some small countries (e.g. Cayman Islands, Singapore) may have no regional data at all.
- Region levels. US metro areas (DMA) work only with Country = United States. Some countries (e.g. Ireland, Singapore) have no states or regions on Google Trends, so State or region must stay empty there.
- Non-web search types start in 2008. Earlier time points come back with
hasData: false. - Times are in UTC. Trending Now (daily trending searches) is not included.
- Rate limits. Google blocks single IPs quickly. The actor uses a fresh proxy session per search and retries failures. Without a proxy you get a captcha after a few dozen requests. If searches keep failing, switch to the
RESIDENTIALproxy group.
Tips and troubleshooting
- Fewer rows than expected? Google often has city data only for popular terms; otherwise the term gets no region rows and a warning, while its other sections are kept. Leave the region level on Automatic or use a more popular term.
- A run stops at the start? Invalid input is reported before any request with the field name: an unknown country or category, a region without a country, US metro areas outside the United States, a comma in a term, or more than 5 terms with Compare on.
- Comparing terms? Tick Compare, one term per line. With Compare off, every term is scaled to its own peak of 100.
- Using Google Trends links? Country, time range, category and search type then come from the link; Data to extract, region level and Max rows still apply.
- Searches fail or are blocked? Keep the default Apify Proxy; if runs report blocking, switch Proxy to the
RESIDENTIALgroup. - Need a smaller result? Untick sections in Data to extract or set Max rows. A report cut short by Max rows is still charged once.
API, MCP and integrations
Run the actor from your code with the same JSON input as in Console. Your API token is in Console → Settings → API & Integrations.
Python (pip install apify-client):
Node.js (npm install apify-client):
HTTP — one request runs the actor and returns the results (runs up to 5 minutes; longer ones: run asynchronously):
AI agents (MCP). Add the actor as a tool of the Apify MCP server. Claude Code:
Claude Desktop, Cursor or VS Code: {"mcpServers": {"apify": {"url": "https://mcp.apify.com?tools=genial_candlestand/google-trends-scraper"}}}. Then ask, for example:
- "Get Google Trends interest over time for bitcoin in the US over the past 12 months"
- "Compare coffee, tea and matcha on one scale in Google Trends for 90 days"
- "List top and rising related queries for election in California, past 7 days"
Integrations. Run it on a schedule with Apify Schedules and send the results to Google Sheets, Slack, Zapier, Make, n8n or your webhook — see Apify integrations.
FAQ
Is it legal to scrape Google Trends?
The actor collects only aggregated, public Google Trends statistics and no personal data. You are responsible for how you use the data and for following the laws and terms that apply to you. If in doubt, ask a lawyer.
Do I need a Google account or an API key?
No. No login, API key or browser is used.
How do I pick a country or category that isn't in the list?
Type it. Country takes any two-letter code or English name Google Trends knows. Category takes any of Google's 1,100+ category names or its numeric ID (the cat= number in a Trends link).
What's the difference between separate terms and "Compare"?
Separately, each term is scaled to its own peak of 100. With Compare on, all terms share one scale, so you can see which one is searched more.
How is it different from other Google Trends actors?
It returns flat, typed rows instead of nested arrays per term, so the data opens directly in Sheets or a BI tool. It reads Google Trends over plain HTTP without a browser, and a failed search is retried with a fresh proxy session. The price is $3.00 per 1,000 keyword reports with all rows included, and terms without data are free.
Can I use it from an AI agent?
Yes. The input is small and readable: country and category by name, time ranges like past90Days. Call it through the Apify API or MCP server.
Also useful
- Google Trends Trending Now Scraper — add today's trending searches by country: volume, growth and related news
- Google News Scraper — check news coverage behind a trend: articles by keyword and topic
- YouTube Comments Scraper — see what viewers say about a trending topic: comments and replies


