
Y Combinator Jobs Scraper: Work at a Startup & YC Jobs
Pricing
from $0.10 / 1,000 jobs
Y Combinator Jobs Scraper: Work at a Startup & YC Jobs
YC jobs scraper for Work at a Startup, Y Combinator's startup job board: every open job of every YC company, newest first, by keyword, company or link. Description, salary and equity parsed, role, posting age, remote, visa, batch and founders. Place, role, date filters. No login. Misses free.
Pricing
from $0.10 / 1,000 jobs
Rating
0.0
(0)
Developer
Hyperbach
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
5 hours ago
Last modified
Categories
Features
Share
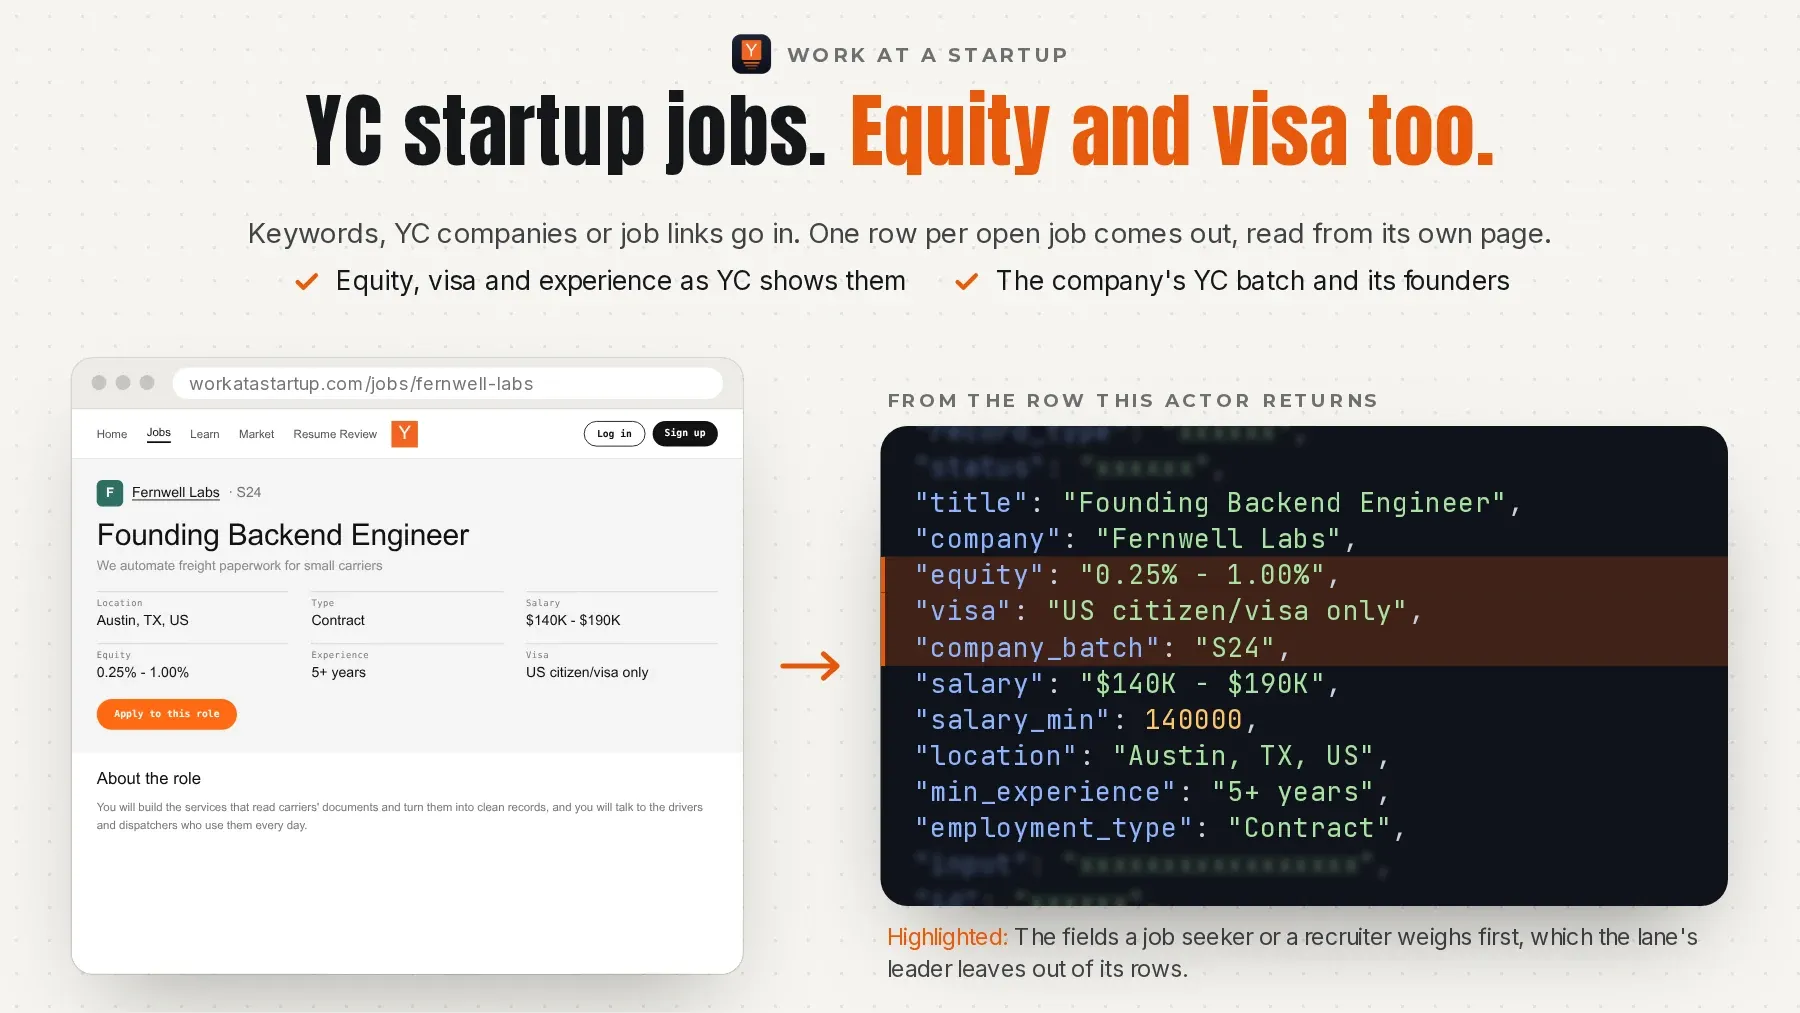
Y Combinator's Work at a Startup jobs as data, logged out. Give keywords, YC companies or job links, and get one row per open job: the full description and the interview process, the salary as shown and parsed (min, max, currency, period), equity, visa, experience, skills, the role and the posting age from YC's own pages, remote and the countries, the apply link, and the company with its YC batch, founders, team size, industry, year founded, LinkedIn and its other open jobs. Newest first over the whole board (every open job of every hiring YC company, about 6,300), with location, role, work arrangement, employment type, posted-within, salary, visa, experience, batch, industry and team-size filters. Every input ends with a free row that says what was found. No login, no cookies, no browser, proxies handled for you.
$0.10 per 1,000 job rows on the Free plan, $0.098 on Starter. A run start is $0.0154. The default input returns about 21 rows for about $0.0174. A closed or missing job, a company with no open job, a search with no match or a value that names nothing is a free row that says why: you never pay for an input that gave no job.
How it compares
- Faster than nomad-agent's Y Combinator Jobs Scraper, with more data: 20 jobs in 8.0 s, against 15 s; 68 fields per job, against 13. It is 12 times cheaper: $0.075 per 1,000 jobs, against our $0.87.
- Cheaper than parsebird's Y Combinator Jobs Scraper, with more data: $0.87 per 1,000 jobs, against $1.29; 68 fields per job, against 32.
Measured on 2026-11-12. Each line compares one job, run by both scrapers at the same time. Prices are per 1,000 jobs: Apify Actors at the Scale plan's prices.
Tested head-to-head on 2026-11-12
The job: the 20 newest software engineer jobs in the United States on Y Combinator's Work at a Startup board (the input schema's example, the leader's default job). Every Actor ran on it the same day from the same harness; every run's cost is at the Scale plan's prices: a rival's charged events at its price for that plan, this Actor's at its list price. Fields counts the filled fields of a typical row. Every actor got the same search; the rows here are read from each job's own page during the run, with the role, the posting age, equity, visa and the company's YC batch and founders. Re-measured monthly.
| Actor | Rows | First row | Run time | Cost | Fields | Failures |
|---|---|---|---|---|---|---|
| this Actor | 20 | 7.3 s | 8.0 s | $0.017 | 68 | none |
nomad-agent/ycombinator-was-scraper | 20 | 5.5 s | 15 s | $0.002 | 13 | none |
parsebird/yc-jobs-scraper | 20 | 7.8 s | 7.8 s | $0.026 | 32 | none |
Why this Y Combinator jobs scraper
- The whole board, not the first 30 cards. Work at a Startup's own job list shows 30 cards and its
?page=2repeats them. This Actor reads every open job of every hiring YC company (1,493 companies and 6,319 open jobs on 2026-11-12) through the YC directory and each company's page, then sorts newest first by the job id, the board's own posting order (553 of 553 dated postings in order). The lane leader stops at 200 rows a run. - Every row is the job's own page, read in the run. The description, the interview process, skills, salary, equity, visa and experience come from the job's page at the minute of the run, so a job closed since is never delivered: its page now shows the company's YC profile, and an input for it is a free
closedrow. - The fields the leader leaves out. The leader's rows carry no equity, visa, experience, skills, role, batch, founders or interview process; here the salary is also parsed to min, max, currency and period, the role and its sub-type and the posting age come from the company's ycombinator.com jobs page, and the company block carries the founders (name, title, LinkedIn), the batch, the stage, the year founded, LinkedIn, X and Crunchbase links and the company's other open jobs.
- The leader's input runs as it is.
queries,locations,locationTypes,employmentTypes,postedWithinandmaxItemsare this Actor's own names, with the same rule for a query: every word, whole words, any case. - No charge for nothing. A closed or missing job, a company with no open job, a search with no match and every input's summary row are free; a job is charged once a run however many inputs list it.
Who it's for
- Job seekers and career coaches — the newest openings at YC startups for a role and a place, with the salary, equity, visa terms and the interview process before applying.
- Recruiters and talent teams — which YC companies hire for a role now, how they pay, and who founded them, refreshed by the posting window.
- Investors and market researchers — the whole board's hiring by batch, industry, team size, role and place: a weekly read of every open job with its company's YC batch and stage.
Quick start
The 20 newest software engineer jobs in the United States
Every open job of two YC companies
Remote design jobs posted in the last 30 days
Jobs that sponsor a visa at Winter 2025 companies, paying 150K USD or more
Switching from nomad-agent/ycombinator-was-scraper?
Your input works as it is. Each name in the left column is read as this Actor's own field and the run log says so (read <theirs> as <ours>); a name marked not read is ignored with a note. A value in the other Actor's shape, an object list or its own date form, is read too.
| nomad-agent/ycombinator-was-scraper | this Actor | what to know |
|---|---|---|
queries | queries | The same name and rule: every word of a query, whole words, any case, in the title (and the description with searchIn = titleAndDescription). |
locations | locations | The same name: a city, region, country name or two-letter code; EU and Europe expand. |
locationTypes | locationTypes | The same name and values: remote, hybrid, onsite. |
employmentTypes | employmentTypes | The same name: Full-time, Contract, Internship (and Co-founder); the board has no Part-time job. |
postedWithin | postedWithin | The same name and form: 24h, 7d, 2w, 1m or any. |
maxItems | maxItems | The same name; 0 here means every match, not 200. |
dedupe | not read | Not read: no memory of earlier runs is kept for you; postedWithin reads the recent jobs only. |
schemaVersion | not read | Not read: the leader's own input-format marker; any value is ignored. |
What differs:
maxItems0 (or unset) reads every match here; the leader's 0 or anything above 200 means 200, and its default is 50.- The output columns are snake_case and more of them:
country_codesandlocationsas the leader'scountryCodesandlocations,employment_typefor itsemploymentTypeslist,work_arrangementfor itsworkType,salaryfor itssalary; the leader'spostedAthas no exact counterpart (Work at a Startup shows none):posted_agoandposted_at_approxare YC's own words and the day they point at. - Each input gets a free summary row (
record_type=target) beside its job rows; filter onrecord_type=jobfor the jobs alone. - There is no repeat-delivery memory: give
postedWithinto read only the recent jobs (thejob idis the posting order).
Output
One row per open job (and one free summary row for every search, company or job you give):
| field | meaning |
|---|---|
record_type | job on a job row (charged); target on an input's free summary row. |
status | ok, or why an input gave no job: no_results, closed, not_found, no_open_jobs, invalid_input, failed, not_read. |
input | The query, company or job link you gave that this row answers. |
id | The job's id on Work at a Startup (the posting order: a higher id is a newer job). The leader's id. |
url | The job's page on workatastartup.com. The leader's url. |
title | The job title as the company wrote it. |
company | The company's name. |
company_slug | The company's slug on Work at a Startup and ycombinator.com (artifact-2). |
location | The location as the company wrote it, parts joined by " / ". |
locations | The location's parts, each a place or a remote part. The leader's locations. |
country_codes | The two-letter countries the location names (its places and its remote part); a US state with no country is US. Empty when no part names a country. The leader's countryCodes. |
remote | True when a part of the location is remote. |
remote_countries | The countries a remote part names (Remote (US; CA) gives US, CA); empty for a plain Remote. |
work_arrangement | remote (every part remote), onsite, remote_or_onsite (both offered), or hybrid when the location or the description says hybrid. The leader's workType. |
work_arrangement_from | Which text set work_arrangement: location or description. |
employment_type | Full-time, Contract, Internship or Co-founder (the board's own types). The leader's employmentTypes. |
role | YC's role of the job (eng, design, product, science, sales, marketing, support, operations, recruiting, finance, legal), from the company's ycombinator.com jobs page. |
role_type | The role's sub-type as YC files it (Full stack, Backend, Electrical, …), where the company set one. |
role_label | The role's label as YC shows it (Engineering, Design, …). |
salary | The salary range as shown ($160K - $220K, €65K - €85K EUR, $2K - $3K / monthly). The leader's salary. |
salary_min | The range's low figure as a number (K and M expanded), in salary_currency and salary_period. |
salary_max | The range's high figure as a number. |
salary_currency | The salary's currency (USD, EUR, GBP, INR, CAD, …): the code the posting names, else its symbol's. |
salary_period | year, month, week or hour: the posting's label, else a year when the top figure is 30,000 or more; null when the posting states neither ("$130 - $180", "$2K - $5K": the source shows no period). |
equity | The equity range as shown (0.30% - 1.20%). |
equity_min_pct | The equity range's low end, in percent of the company. |
equity_max_pct | The equity range's high end, in percent. |
visa | The visa terms as the board states them: Will sponsor, US citizenship/visa not required, US citizen/visa only. |
min_experience | The experience asked, as shown (3+ years, Any (new grads ok)). |
min_experience_years | The years of experience asked as a number (0 for new grads). |
new_grads_ok | True when the job is open to new graduates. |
min_school_year | The school year asked, where YC shows one (Senior and above, Any). |
skills | The skills the job lists. |
posted_ago | How long ago the job was posted, in YC's own words ("6 days", "about 1 month"), from the company's ycombinator.com jobs page. |
posted_at_approx | The day posted_ago points at (UTC), from the middle of its range: an approximate date, as exact as YC's words. |
last_active_ago | How long ago the job's company was last active on the board, in YC's own words, where YC shows it. |
description | The full job description as plain text (a line a paragraph or list item). The leader's description. |
description_html | The full job description as the page's HTML. The leader's descriptionHtml. |
interview_process | The interview process as plain text, where the company wrote one. |
interview_process_html | The interview process as the page's HTML. |
application_questions | The application's own questions: each with its question, type, required and options. |
apply_url | The apply link (YC's account sign-in, then the application). |
yc_url | The job's page on ycombinator.com. |
ask_us | YC's "ask us about this job" flag of the posting. |
company_batch | The company's YC batch, short (W25). |
company_batch_name | The company's YC batch, long (Winter 2025), from the YC directory (search rows). |
company_one_liner | The company's one-line description. |
company_long_description | The company's long description as its YC page shows it (read with the posting's role and age). |
company_website | The company's website. |
company_team_size | The company's team size. |
company_industry | The company's industry path (B2B -> Engineering, Product and Design). |
company_industries | The company's industries. |
company_location | The company's own location. |
company_country | The company's country code, from its ycombinator.com page. |
company_logo | The company's logo. |
company_year_founded | The year the company was founded, from its ycombinator.com page. |
company_status | The company's YC status (Active, Acquired, …). |
company_stage | The company's stage in the YC directory (Early, Growth, …), on search rows. |
company_launched_at | The day the company launched on YC, from the directory (search rows). |
company_tags | The company's YC tags. |
company_top_company | True when the YC directory marks it a top company (search rows). |
company_nonprofit | True for a non-profit (search rows). |
company_yc_partner | The company's YC group partner, from the directory (search rows). |
company_regions | The company's regions in the YC directory (search rows). |
company_yc_id | The company's YC id. |
company_yc_url | The company's profile on ycombinator.com. |
company_hiring_description | The company's hiring pitch as plain text. |
company_tech_description | The company's tech-stack text as plain text, where it wrote one. |
company_linkedin | The company's LinkedIn page. |
company_twitter | The company's X (Twitter) page. |
company_facebook | The company's Facebook page. |
company_crunchbase | The company's Crunchbase page. |
company_founders | The founders as YC publishes them: each with name, title, bio, linkedin, twitter and past_companies (the founder's earlier roles as YC writes them, one text). |
company_open_jobs | How many open jobs the company lists on Work at a Startup. |
company_other_jobs | The company's other open jobs: each with its id and title. |
yc_page_status | served when the company's ycombinator.com jobs page was read (the role, the dates, the links), not_found or failed when not (those columns are null; the row stands). |
read_via | The connection the job page came through: datacenter or residential_us (ours, US), your_proxy. |
verdict | On an input's row: COMPLETE, CAPPED, TRUNCATED or PARTIAL (note says why). |
rows_delivered | On an input's row: the job rows it delivered. |
matches | On an input's row: the jobs that matched the list's fields (a search) or the company's open jobs. |
board_jobs | On a search's row: the open jobs on the whole board when it was read. |
note | Why an input's row has the status or the verdict it has, and what was left out. |
scraped_at | When this row was read (UTC). |
Example record:
Pricing
Pay for the jobs a run delivers, plus one run start; no platform usage is billed to you. The prices fall with your Apify plan.
| event | unit | Free | Starter | Scale | Business |
|---|---|---|---|---|---|
Job (job) | per 1,000 | $0.10 | $0.098 | $0.098 | $0.098 |
Run start (start) | per run | $0.0154 | $0.0154 | $0.0154 | $0.0154 |
A job is $0.10 per 1,000 on the Free plan ($0.0001 a job) and $0.098 on Starter, with everything it carries: the full description and the interview process, salary and equity as shown and parsed, visa, experience, skills, the role, the posting age, the places, and the company with its YC batch and founders. Each run that delivers a charged job also pays the run start, $0.0154 once (it pays for reading the YC directory and the board's company lists); a run that delivers none pays nothing at all. So the 20 newest jobs of a search cost $0.0174 on the Free plan and $0.01736 on Starter; 1,000 jobs $0.1154 and $0.1134; every input of a run shares one start. Free: every input's summary row, a closed or missing job, a company with no open job, a search with no match, a job a filter leaves out, a job another input of the run already delivered (one row, one charge), a value that names nothing, and an input left unread at maxItems, your charge limit or the time limit. A run that stops early (a timeout, an abort) is charged for the jobs it delivered.
Before the first request the log names the prices at your plan and the most the run can cost: maxItems over the whole run, one job a job link, maxItemsPerCompany a company, and never more than your charge limit. A search with no maxItems reads every job that matches, so the board decides the cost: on our runs the whole board held about 6,319 open jobs ($0.6473 on the Free plan) and "software engineer" matched 712 ($0.0866); set maxItems or a charge limit to bound it. Enterprise plans have their own rates — the Actor's Pricing tab shows the price for your plan.
Usage patterns
- What a search reads — Each query is one search over every open job of the board. The board is the YC directory's hiring companies (the batch, industry, team-size and top-company filters are applied there, so fewer companies are read) and each company's open jobs; it is shared between runs for 30 minutes, so most runs start from it at once, and a run that finds it older reads it again (about 30 seconds). The jobs that match the list's fields (the title words, the place, the arrangement, the type, the visa, the experience, the salary) are read newest first, one job page each;
searchIn=titleAndDescriptionmatches the description on the job's own page, androlesandpostedWithinare read off the company's ycombinator.com jobs page, one page a company.maxItemsstops the run; without it every match is read. - Companies and job links —
companiestakes a slug (artifact-2), a workatastartup.com or ycombinator.com company link, or the company's name (the YC directory finds its slug); every open job of the company is read, newest first.jobUrlstakes a job id, a workatastartup.com job link or a ycombinator.com job link. Companies and jobs are read as given: the search filters do not apply to them,maxItemsPerCompanydoes. Any list takes any link: a company link injobUrlsis a company, a job-list link inqueriesis a search with that role or place. - Places and the work arrangement — A location is the company's own text (
New York, NY, US / Remote (US)); the row splits it intolocations, reads the countries each part names (country_codes, a US state with no country is the United States) and the countries a remote part names (remote_countries). A country inlocationsmatches both; EU and Europe expand to their countries; a city matches the job's own words.work_arrangementis remote, onsite, remote_or_onsite, or hybrid when the location or the description says so (work_arrangement_from). The jobs are read from US connections: a connection in India sees fewer jobs (the board hides the US-only ones there). - What a row is —
record_type=job: one open job, charged once a run however many inputs list it.record_type=target: one free row per query, company or job, with itsstatus,verdict, the rows it delivered, the jobs that matched the list (matches), the board's open jobs (board_jobs) and anote. Filter onrecord_type=jobfor the jobs alone.
Input configuration
| field | type | default | what it does |
|---|---|---|---|
queries | array | [] | Keyword searches over every open job of YC's Work at a Startup board, newest first. A job matches when its title holds every word of the query, as whole words, any case (searchIn adds the description). Each query is its own search with its own summary row. * reads every open job. A workatastartup.com or ycombinator.com job-list link works here too (its role and place become the search's filters). |
companies | array | [] | Every open job of these companies: a slug (artifact-2), a workatastartup.com or ycombinator.com company link, or the company's name (the YC directory finds its slug). Read as given: the search filters do not apply, maxItemsPerCompany does. |
jobUrls | array | [] | Single jobs: a job id (76154), a workatastartup.com job link, or a ycombinator.com job link. A closed or missing job is a free row that says so. |
searchIn | title / titleAndDescription | "title" | Where a query's words must be: the title (the default: the whole list is matched at once), or the title or the description (each job's own page is read, newest first, with a read budget of 100 pages and then 15 a delivered job; the search row says how many jobs matched). |
locations | array | [] | City, region, country name or two-letter country code. A country matches the places a job names and the countries its remote part names (Remote (US; CA)); EU and Europe expand to their countries; a city or another place matches the job's own location words. Empty: every location. |
locationTypes | array | [] | remote (the job's location has a remote part), hybrid (the location or the description says hybrid), onsite (a place, not hybrid). A job matches when it offers any arrangement selected. Empty: every arrangement. |
employmentTypes | array | [] | The board's own types: Full-time, Contract, Internship, Co-founder (the board has no Part-time job; it is accepted for the leader's inputs and matches nothing). Empty: every type. |
roles | array | [] | The job's role as YC files it (read from the company's ycombinator.com jobs page, one page a company, newest first, with a read budget like searchIn's). Empty: every role. |
postedWithin | string | "any" | Only jobs posted within this time: 24h, 7d, 2w, 1m (30 days); any reads every age. The age is the source's own words ("6 days", "about 1 month"), so a window's edge is as exact as those words. |
minSalary | integer | 0 | Jobs whose salary range reaches this yearly figure in salaryCurrency (a monthly or hourly range counts as 12 months or 2,080 hours). A job with no salary, another currency or no stated period is kept unless onlyWithSalary is on. 0: no salary filter. |
salaryCurrency | USD / EUR / GBP / CAD / INR / AUD / SGD / CHF / JPY / BRL / MXN | "USD" | The currency of minSalary (no conversion: a job in another currency is not compared). |
onlyWithSalary | boolean | false | Leave out the jobs that show no salary (with minSalary: the jobs whose salary cannot be compared). |
visa | array | [] | The job's visa terms as the board states them. Empty: every job. |
maxExperienceYears | integer | Jobs that ask at most this many years (0 = jobs open to new grads). Jobs that state no experience are left out when this is set. Empty: no filter. | |
batches | array | [] | Companies of these YC batches: W25, S24, F24, X25 or Winter 2025. Read at the source: fewer companies are read. Empty: every batch. |
industries | array | [] | Companies in these YC directory industries (B2B, Fintech, Healthcare, Consumer, Engineering, Product and Design, …; any case). An unknown name is named in the run's notes with the directory's list. Empty: every industry. |
minTeamSize | integer | 0 | Companies with at least this many people (the directory's team size). 0: no floor. |
maxTeamSize | integer | 0 | Companies with at most this many people. 0: no ceiling. |
topCompaniesOnly | boolean | false | Only the companies the YC directory marks as top companies. |
maxItems | integer | 0 | The most charged jobs of the whole run; 0 = every match (the whole board is about 6,300 jobs). |
maxItemsPerCompany | integer | 0 | The most jobs of one company in the run (a search and a company input alike); 0 = no cap. |
feedback | string | A note to the people who maintain this Actor: what you needed and did not get. For example a missing field, a wrong or empty result, or the Actor you switch from or to, and why. The run does not read it: the rows and the charges stay the same. A person reads every note. |
Errors
A run does not fail because of your input. When an input cannot be used — a date that is not a date, an id in the wrong form, two settings that contradict each other — the run ends Succeeded, charges nothing, and says what to change:
- the status message starts with
INPUT REJECTED; - the dataset holds one row,
{"error": true, "code": "…", "message": "…"}, and no results; - the key-value store record
ERRORholds the same object.
From code, check error on the first row before reading results.
A search with no match, a closed or missing job, a company with no open job or a value that is not a search, a company or a job is not an error: it gets one free row with its status and the reason, and the run goes on with the others. A run that ends Failed is a fault on our side, never your input; it charges nothing, and we are alerted.
FAQ
Which status and verdict is which?
A job row is ok. An input's row: ok with a verdict (COMPLETE: every match read; CAPPED: maxItems or maxItemsPerCompany left matches out; TRUNCATED: a description, role or arrangement filter read 100 pages and then 15 a delivered job without enough matches, the note says how many matched (a description search then reads the older jobs whose title holds the words); PARTIAL: stopped early, the note says why), or free: no_results (no open job matches), closed (the job is closed: its page now shows the company's YC profile), not_found (no such job or company, on two connections), no_open_jobs (the company lists none, or it has no Work at a Startup page), invalid_input (a value that is not a search, a company or a job), failed (the source refused every connection tried; run it again later), not_read (maxItems, your charge limit or the time limit came first).
How fresh is it, and how exact is the posting date?
Every job row is read from the job's own page during the run. The board's list of companies and job ids is shared between runs for up to 30 minutes (on 2026-11-12 it gained 2 jobs between 12:03 and 12:08 UTC and none in the next 84 minutes): a job posted in the last 30 minutes can be missing from a search until the list is read again, and the search's row names the time the lists it used were read; a closed job is never in the rows. The posting date is YC's own words (posted_ago: "6 days", "about 1 month"), with posted_at_approx the day they point at: Work at a Startup shows no exact date.
Can it get the hiring manager's or the founders' e-mail?
No. The hiring manager is empty on every posting YC shows logged out, and no page carries an e-mail. The founders' names, titles, bios, LinkedIn and X links are on the row, as YC publishes them.
Does it need a YC account, cookies or an API key?
No. Everything is read from the public, logged-out pages of workatastartup.com and ycombinator.com and YC's public company directory: no login, no cookie of yours, no token. The connections are included in the price.
Do I need Apify Proxy or my own proxy?
No. The Actor uses its own connections, at no extra cost to you.
Integration
JavaScript
Python
CLI
REST
AI agents and MCP
Apify's MCP server offers this Actor as a tool to Claude, Cursor, VS Code and any other MCP client. Connect https://mcp.apify.com?tools=hyperbach/workatastartup-jobs-scraper and ask, for example: "Find the newest software engineer jobs at Y Combinator startups in the United States with salary, equity and the company's founders". The agent fills the input from the table above and reads the rows from the run's dataset. A field under the name another Actor gives it is read as this Actor's own: query, keywords, keyword, search as queries; company, companySlugs, companyUrls, companyNames as companies; jobUrl, jobIds, jobId, startUrls as jobUrls; location, country, countries, cities as locations (and more). An agent or a person can add feedback to any run and say what was needed and not delivered: a missing field, a wrong or empty result, the Actor switched from or to, and why. The run returns the same rows at the same price, and a person reads every note.
n8n, Make and Zapier
The Apify node in n8n, the Apify app in Make and the Apify integration in Zapier run this Actor on a schedule or from a trigger and read its dataset. A webhook on the run's end (Integrations on the Actor page) sends the rows on to your own endpoint. Nothing to install on our side.
Support
Disagree with a charge? Write to apify@hyperbach.com with the run ID. We will ask Apify to compensate you, and the charge comes back to your Apify account as platform credit.
Did it do the job? A short review on the Store, at any rating, helps the next buyer choose.
See also
- Upwork Jobs History — every Upwork job posting since November 2024 by period, category and skill, with the client's record as it stood on the day of posting.
- LinkedIn Jobs Scraper — LinkedIn job listings for keywords and a location, with the applicants count, the salary block and the company's facts.
- Greenhouse Jobs Scraper — the hiring of major tech companies from their own Greenhouse boards, kept as roles open and close.
- Remote Jobs Scraper — every remote job from seven boards and ATSs in one deduplicated feed, kept after the postings close.
- Arbeitsagentur Jobs Scraper — jobs of Germany's Federal Employment Agency (Jobsuche) by keyword, search link or job link: employer, place, working time, contract and the stated salary as numbers, with the description on request.
- Internshala Scraper — Internshala internships and fresher jobs in India by keyword, category, city or link, newest first: the stipend or salary as numbers, applicants, openings, the apply-by date, the exact post time, skills and perks.
This page is generated from the Actor's schemas and a live sample — it cannot describe a field the Actor does not have.


