

Product Hunt [Only $0.80💰] Scraper ·Launches, Reviews & Emails
Pricing
from $0.80 / 1,000 results
Product Hunt [Only $0.80💰] Scraper ·Launches, Reviews & Emails
[Only $0.80💰] Product Hunt scraper — leaderboards (daily–yearly), topics, collections, products & makers, any URL auto-classified. 50+ fields plus optional detailed reviews, comments & contact emails harvested per site. Pure HTTP, JSON/CSV.
Pricing
from $0.80 / 1,000 results
Rating
5.0
(1)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
125
Total users
20
Monthly active users
20 hours ago
Last modified
Categories
Share
Product Hunt Scraper — Launches, Reviews, Comments & Contact Emails
Turn any Product Hunt URL into a clean, structured dataset. Start from daily/weekly/monthly/yearly leaderboards, a date range, topics, categories, collections, individual products, or maker profiles — all auto-classified from one input.
Get 50+ fields per product including votes, rank, comments, and a media gallery — plus makers and the hunter with LinkedIn, optional detailed reviews, discussion threads + full comment bodies, and contact emails harvested from each product's own website. No Product Hunt API key. Pure HTTP, no browser.
Why Use This Scraper?
- ✅ Every Product Hunt entry point in one input — paste leaderboards, topics, categories, collections, products, and maker profiles together; each is auto-classified
- ✅ Date range (
startDate/endDate) andfeaturedOnlywithout walking the homepage unbounded - ✅ Rankings built in — vote counts, daily/weekly/monthly rank, comment counts, and the featured timestamp on every leaderboard-sourced row
- ✅ Makers + hunter on every product — name, headline, profile, follower count, LinkedIn and X. No API token
- ✅ Optional detailed reviews — full review text, five per-dimension ratings, and selected pros/cons per product
- ✅ Optional discussion threads + full comment bodies — no API token
- ✅ Contact emails harvested from each product's own website (mailto + plain-text, junk-filtered, deduped per site)
- ✅ Business fields the other scrapers skip — funding amount, employee band, YC flag, alternatives, review pro/con tags
- ✅ JSON or CSV output, ready for spreadsheets and CRMs
Coming from another Product Hunt scraper?
| You already get here | Often missing elsewhere |
|---|---|
Collections + /collections + /categories/{slug} + /search?q= | Search-only, or no category URL |
startDate / endDate + featuredOnly | Homepage walk with no date picker |
| Homepage walk-back across recent daily leaderboards | A single "today" snapshot |
| Reviews with 5 ratings, pos/neg text, selected pros/cons | Star + a text blob |
| Discussion threads (title, preview, pin, author) and comment bodies | Flat comments, or bodies behind a PH API key |
fundingAmount, employeeSize, wasInYCombinator | Explicitly not scraped |
alternatives[], proConTags[] | — |
| Company emails on by default, junk-filtered | Off by default, or billed as a separate event |
| Makers + hunter + founder LinkedIn, no API key | Token required, or LinkedIn omitted |
Overview
The Product Hunt Scraper is built for founders, marketers, VCs, and researchers who need Product Hunt data in a spreadsheet instead of a browser tab.
The output is primarily product-shaped rows. Even when you start from a leaderboard, topic, category, or collection URL, the resulting dataset is a stream of product rows (rowType: "product") — not separate leaderboard or collection rows. The exception is a direct maker profile URL (/@username), which emits a single maker row (rowType: "maker").
The parser reads Product Hunt's server-rendered Apollo cache (the same data the page UI uses) rather than scraping rendered HTML, so it stays resilient to PH's frequent visual redesigns. URLs are auto-classified by shape — you just paste them, you don't tag them.
Supported Inputs
URL types
| URL type | Pattern | Example |
|---|---|---|
| Homepage | producthunt.com/ | https://www.producthunt.com/ |
| Daily leaderboard | /leaderboard/daily/YYYY/M/D | https://www.producthunt.com/leaderboard/daily/2026/5/22 |
| Weekly leaderboard | /leaderboard/weekly/YYYY/WW | https://www.producthunt.com/leaderboard/weekly/2026/20 |
| Monthly leaderboard | /leaderboard/monthly/YYYY/M | https://www.producthunt.com/leaderboard/monthly/2026/5 |
| Yearly leaderboard | /leaderboard/yearly/YYYY | https://www.producthunt.com/leaderboard/yearly/2025 |
| Topic page | /topics/{slug} | https://www.producthunt.com/topics/artificial-intelligence |
| Category page | /categories/{slug} | https://www.producthunt.com/categories/ai-agents |
| Search | /search?q=… | https://www.producthunt.com/search?q=ai+agent |
| Collection | /collections/{slug} | https://www.producthunt.com/collections/best-ai-tools |
| Collections index | /collections | https://www.producthunt.com/collections |
| Product detail | /products/{slug} or /posts/{slug} | https://www.producthunt.com/products/bolt-new |
| Maker profile | /@{username} | https://www.producthunt.com/@ericsimons40 |
Homepage and listing URLs (leaderboards, topics, categories, collections) fan out to product rows and stop once maxItems is reached. The homepage walks recent daily leaderboards (newest first). A category URL uses the first server-rendered page (~15 products).
Copy-pasteable startUrls
startUrls accepts both plain strings ("https://…") and request objects ({ "url": "https://…" }) — mix freely.
Unsupported inputs
- ❌ Content behind a Product Hunt login (private/draft launches, account settings)
- ❌ Hosts outside
producthunt.com
Use Cases
| Audience | Use case |
|---|---|
| Founders & indie makers | Track competitor launches, benchmark votes/rank, study winning taglines, reviews, and media |
| Marketing & growth teams | Build outreach lists from new launches with contact emails attached |
| VCs & scouts | Source deals from daily/weekly leaderboards; filter by funding, YC alumni, traction, review sentiment |
| Sales / lead-gen | Turn leaderboards + collections into a ready-to-import prospect list |
| Researchers & analysts | Bulk-export launches, reviews, and discussions across topics and time periods |
| Agencies | Deliver client-ready Product Hunt datasets without writing a scraper |
How It Works
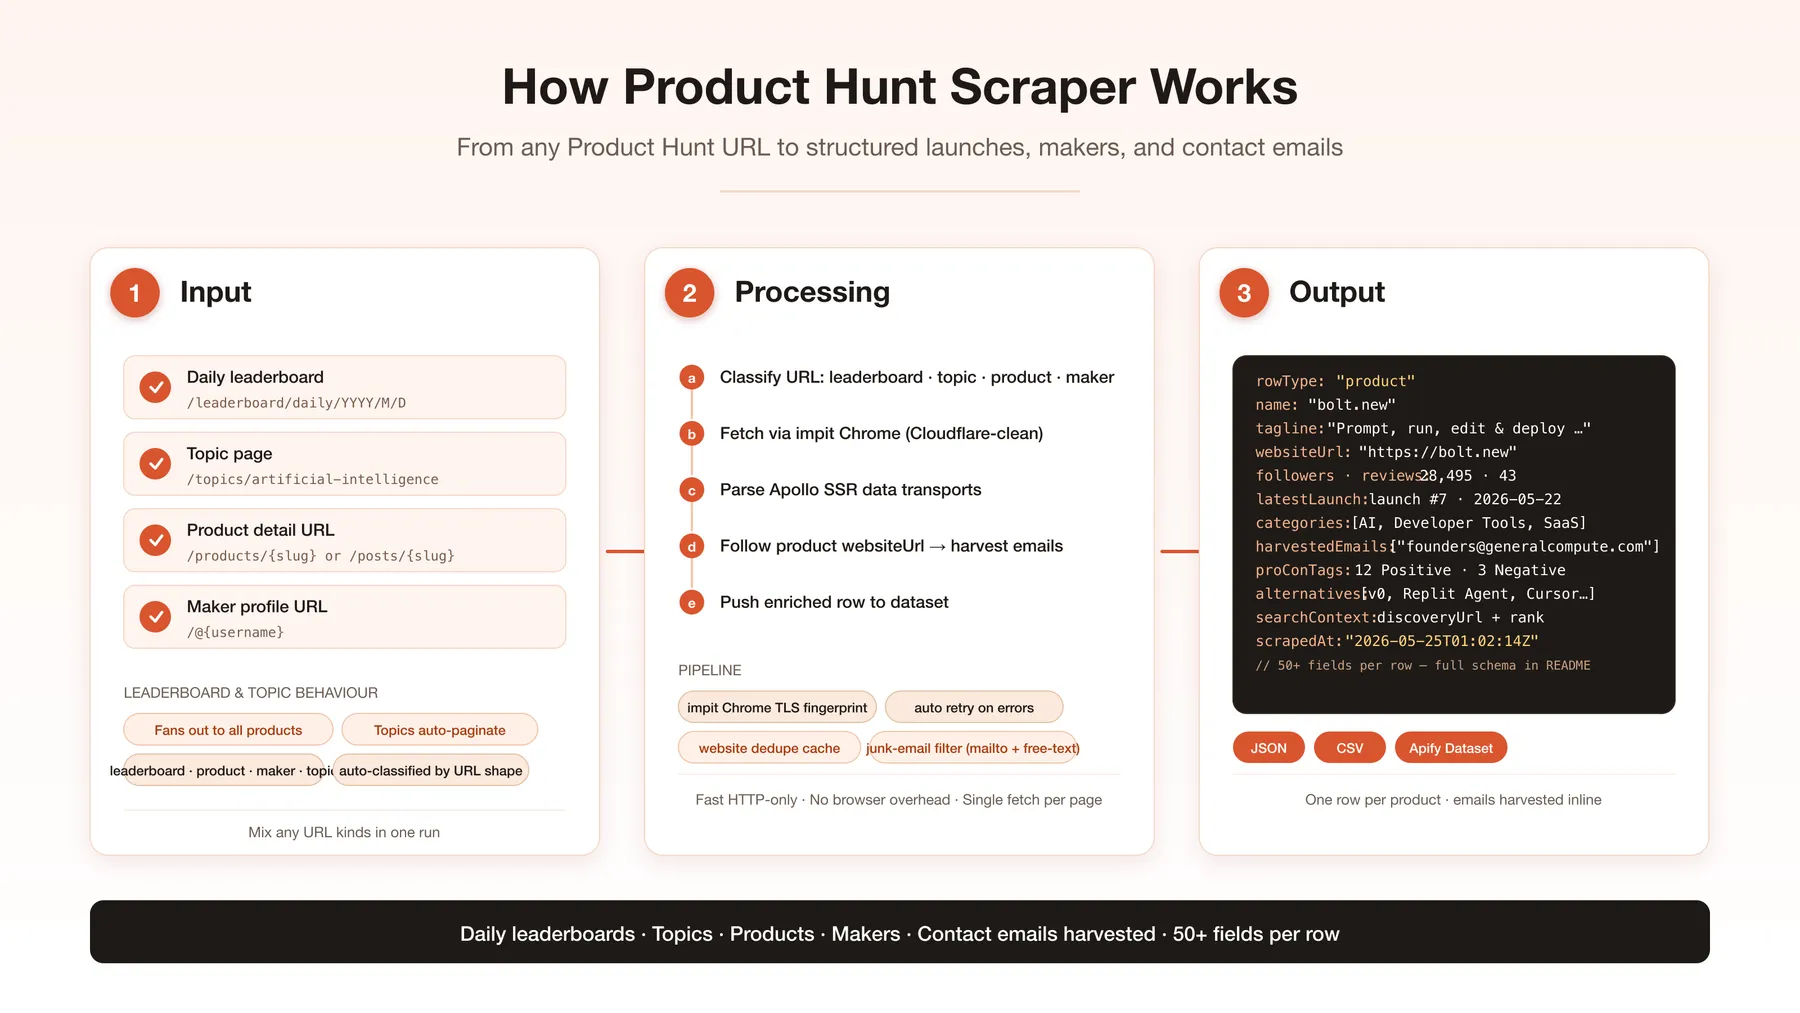
- Input — paste any mix of Product Hunt URLs (homepage, leaderboards, topics, categories, collections, products, makers) and optionally a date range
- Auto-classify & fan out — each URL is routed to the right handler; listing URLs expand to their products
- Fetch — pages are retrieved over HTTP with a real Chrome TLS fingerprint (passes Cloudflare without a browser)
- Parse & enrich — the Apollo cache is read for 50+ fields, makers, hunter, votes/rank, and the media gallery; maker profiles add LinkedIn; optionally add reviews, comment bodies, and contact emails from each product's site
- Output — one product row per launch (or one maker row per
/@username), as JSON or CSV
Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
startUrls | array<string | { url }> | no | Any mix of supported Product Hunt URLs. Auto-classified. Empty + no dates → today's daily leaderboard. |
startDate / endDate | YYYY-MM-DD | no | Inclusive daily-leaderboard range. One date alone = that day. Homepage + a range uses the range, not an unbounded walk-back. |
featuredOnly | boolean | no | Default false. Skip fan-out launches with no featuredAt. Pasted product/maker URLs and search hits are kept. |
searchQueries | string[] | no | Keyword searches, expanded to /search?q= (paginated, ~10/page). |
leanMode | boolean | no | Default false. Skip emails, reviews, comments, add-ons, and maker-profile fetches. |
scrapeAddons | boolean | no | Default false. Attach builtWith[] from /products/{slug}/addons. |
enrichMakerEmails | boolean | no | Default true. For each product, fetch its websiteUrl and harvest emails (junk-filtered, capped at 10/site, deduped per URL). Each unique email found is billed as a small add-on (see Store pricing). Disable for pure PH metadata (~30% faster). |
scrapeReviews | boolean | no | Default false. Attach detailed reviews per product (one extra request each). |
maxReviews | integer | no | Default 50. PH server-renders ~10, so higher values rarely add more. |
scrapeComments | boolean | no | Default false. Attach discussion threads and full comment bodies from the launch page (one extra request each). No token. |
maxComments | integer | no | Default 20. Cap on comment bodies per launch. |
apiToken | string (secret) | no | Unused for makers, hunter, LinkedIn, or comments. Leave blank. Fallback only if a launch page has no SSR makers/comments. |
maxItems | integer | no | Hard cap on total dataset rows. Default 2000. Free-tier runs are capped at 100. |
maxConcurrency | integer | no | Detail pages fetched in parallel. Default 8 (6–10 is the sweet spot). |
minConcurrency | integer | no | Minimum parallelism. Default 1. |
maxRequestRetries | integer | no | Per-URL retry budget. Soft-blocks/thin bodies auto-retried with a fresh session. Default 5. |
proxy | object | no | Defaults to Apify Proxy. Supply your own residential pool for geo-locked output or heavy runs. |
Common scenarios
1. A day's launches with contact emails
2. Launches with reviews and discussion threads
3. Full enrichment — emails + makers + hunter + comment bodies
4. A date range, featured launches only
Makers, hunter, LinkedIn, and comment bodies come from the pages themselves. No Product Hunt developer token.
Output Overview
Each dataset item is one of two shapes, set by rowType:
product— emitted for every product (from leaderboards, topics, collections, the homepage, or direct product URLs). Carries the full 50+ field schema, plusreviews[],discussionThreads[], andcomments[]when enabled.maker— emitted only for a direct/@usernameURL. Profile + the maker's launched products.
Notes on when fields are populated:
- Votes, rank, comments count,
featuredAtare present on rows discovered via a leaderboard/topic/category/collection. They'renullon a direct/products/{slug}URL (no ranking context). reviews[]appears only withscrapeReviews;discussionThreads[]andcomments[]only withscrapeComments.makersEnriched+hunter(including LinkedIn when the maker published one) are on every product row.harvestedEmailsrequiresenrichMakerEmailsand a site that exposes an email.
Output is nested JSON by default; the Apify Console "Export" tab flattens it to CSV.
Output Samples
Product row — leaderboard-discovered, with reviews + threads
Maker row — direct /@username
Key Output Fields
Identity & links
rowType,productId,slug,name,tagline,description,sourceUrl,canonicalUrlwebsiteUrl,githubUrl,iosUrl,androidUrl,twitterUrl,linkedinUrl,facebookUrl,instagramUrl
Ranking, engagement & media
votesCount,launchDayScore,dailyRank,weeklyRank,monthlyRank,commentsCount,featuredAtreviewsCount,reviewsRating,followersCountmedia[]—mediaType(image/video),imageUuid,width,height,videoId
Business, categories & sentiment
employeeSize,fundingAmount,wasInYCombinator,isTopProduct,isNoLongerOnlinecategories[],latestLaunch,firstPost,alternatives[],proConTags[],builtWith[](withscrapeAddons)
Reviews (with scrapeReviews)
reviews[].overallRating,.easeOfUseRating,.reliabilityRating,.valueForMoneyRating,.customizationRatingreviews[].overallExperience,.positiveFeedback,.negativeFeedback,.selectedPros,.selectedCons,.votesCount,.reviewer
Discussion & comments (with scrapeComments)
discussionThreads[].title,.descriptionPreview,.commentsCount,.isPinned,.authorcomments[].body,.votesCount,.url,.author
People
makersEnriched[]/hunter—name,username,headline,profileUrl,followersCount,linkedinUrl,twitterUrl,links[]- Maker rows also carry
followingCount,linkedinUrl,links[]
Enrichment (optional)
harvestedEmails[](withenrichMakerEmails)
Discovery context
searchContext.discoveryUrl,.resultPosition,.leaderboardDate,.topicSlug,.collectionSlug
FAQ
Which Product Hunt URLs are supported?
Homepage, daily/weekly/monthly/yearly leaderboards, a startDate/endDate range, topics, /categories/{slug} (first SSR page), /search?q= (or searchQueries), collections (and the /collections index), product detail (/products/{slug} or /posts/{slug}), and maker profiles (/@username). Mix any of them in startUrls.
Do I get product rows or leaderboard/collection rows?
Product rows. Leaderboards, topics, categories, collections, and the homepage all fan out to product rows (rowType: "product"). Only a direct /@username URL produces a maker row.
What do scrapeReviews and scrapeComments add?
scrapeReviews attaches a reviews[] array (full text, five ratings, pros/cons, reviewer). scrapeComments attaches discussionThreads[] and full comments[] bodies from the launch page. Each adds one HTTP request per product and is off by default.
Do I need a Product Hunt API token?
No. Makers, hunter, LinkedIn, reviews, and comment bodies are read from public Product Hunt pages. apiToken is an unused fallback — leave it blank.
How do I get makers and the hunter?
They are on every product row (makersEnriched[], hunter). LinkedIn is filled when the maker published one on their Product Hunt profile.
Can I search by keyword?
Yes. Paste https://www.producthunt.com/search?q=ai+agent or set searchQueries: ["ai agent"]. Results are in the page HTML (productSearch, ~10 per ?page=).
How do I scrape a date range?
Set startDate and endDate (YYYY-MM-DD). The actor expands them into daily leaderboards. One date alone scrapes that day. You can also paste other URLs in the same run. A homepage URL plus a range uses the range, not an unbounded walk-back.
What does featuredOnly do?
When true, listing fan-out (leaderboard / topic / category / collection) skips launches with an empty featuredAt. Product and maker URLs you paste yourself are always kept.
Why are votesCount / dailyRank sometimes null?
Those come from a leaderboard/topic/category/collection's ranking data. A direct /products/{slug} URL has no ranking context, so they're null. Reach a product via a leaderboard to get them.
Some products have harvestedEmails: [] — why?
Email harvesting is best-effort. A site may not publish an email, may load it via JavaScript, or may obfuscate it. Realistic harvest rate is roughly 30–50% of product sites.
Can I scrape private or login-gated content?
No. The actor only reads publicly available pages. Anything behind a Product Hunt login is out of scope.
What about rate limits?
The scraper runs cleanly at maxConcurrency=8; lower it or add a residential proxy if you see soft-blocks. Maker-profile fetches (for LinkedIn) are cached per username for the run.
Support
Found a bug, hit a soft-block we don't detect, or want another URL kind supported? Open an issue on the actor's Issues tab, or reach out via the memo23 profile on Apify.
Additional Services
Need a custom export shape, a new entry point, or scheduled monitoring? I build tailored scrapers and enrichment pipelines — get in touch via the memo23 profile.
Explore More Scrapers
If you track Product Hunt launches, founders, and prospects, these pair well:
- Y Combinator Scraper — companies + jobs from YC; cross-reference the
wasInYCombinatorflag - G2 Scraper — see how a launched SaaS ranks on G2 reviews
- Trustpilot Scraper — customer sentiment for products you discover
- LinkedIn Profiles Scraper — backfill founder profiles for makers
- PagesJaunes Leads Scraper — bulk B2B leads with emails
Full portfolio: apify.com/memo23.
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/producthunt-scraper).
Purpose: Turn any Product Hunt URL (leaderboards, date range, topics, categories, collections, products, maker profiles) into structured product rows read from PH's server-rendered Apollo cache, with optional reviews, discussion threads, and contact emails.
Minimal input:
Output: one row per product (rowType: "product") with slug, name, tagline, websiteUrl, votesCount, dailyRank, weeklyRank, monthlyRank, commentsCount, featuredAt, reviewsCount, reviewsRating, followersCount, wasInYCombinator, media[], categories[], harvestedEmails[], and (when enabled) reviews[], discussionThreads[], comments[], makersEnriched[], hunter, searchContext, scrapedAt. A direct /@username URL emits one maker row (rowType: "maker") with username, name, headline, productsCount, followersCount, products[].
Behaviors an agent should know:
- Always set
maxItems(default 2000): a topic page can fan out to hundreds of products; a single daily leaderboard yields ~17-30. Free-tier runs cap at 100. startUrlsare auto-classified; leaderboards/topics/categories/collections/homepage fan out to product rows,/products/{slug}emits one product,/@usernameemits one maker row.startDate/endDateexpand to daily leaderboards.featuredOnlydrops unfeatured listing rows; pasted product/maker URLs stay.scrapeReviewsandscrapeCommentsare off by default and each add one request per product.makersEnriched/hunter(with LinkedIn when published) are always populated from the page — noapiToken.votesCount/dailyRankare null on direct product URLs (no ranking context); reach a product via a leaderboard to populate them.- Pay-per-event billing — see the Pricing tab on the actor page. The optional email enrichment (
enrichEmails) is charged only per contact email found, never for misses.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Product Hunt or any of its parent companies or subsidiaries. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly available Product Hunt pages — no authenticated endpoints, private launches, or content behind the producthunt.com login wall. Users are responsible for ensuring their use complies with Product Hunt's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organization. Harvested contact emails and founder profile links are personal data — process them responsibly, honor opt-outs, and seek legal advice before outbound marketing.
SEO Keywords
product hunt scraper, scrape product hunt, producthunt scraper, product hunt api, product hunt.com scraper, Apify product hunt, product hunt leaderboard scraper, product hunt topic scraper, product hunt collections scraper, product hunt reviews scraper, product hunt comments scraper, maker profile scraper, product launch scraper, product hunt maker emails, founder contact scraper, saas launch tracker, b2b lead generation data, vc deal sourcing, ai product tracker, startup launch intelligence


